
cjwbw / demucs

Demucs Music Source Separation

replicate.com
Total runs: 184.6K
24-hour runs: 0
7-day runs: 0
30-day runs: 0
Github
Model's Last Updated: Juillet 02 2023

Introduction of demucs

Model Details of demucs

Readme

Demucs Music Source Separation

Demucs is a state-of-the-art music source separation model, currently capable of separating drums, bass, and vocals from the rest of the accompaniment. Demucs is based on a U-Net convolutional architecture inspired by [Wave-U-Net][waveunet]. The v4 version features [Hybrid Transformer Demucs][htdemucs], a hybrid spectrogram/waveform separation model using Transformers. It is based on [Hybrid Demucs][hybrid_paper] (also provided in this repo) with the innermost layers are replaced by a cross-domain Transformer Encoder. This Transformer uses self-attention within each domain, and cross-attention across domains. The model achieves a SDR of 9.00 dB on the MUSDB HQ test set. Moreover, when using sparse attention kernels to extend its receptive field and per source fine-tuning, we achieve state-of-the-art 9.20 dB of SDR.

Samples are available on our sample page . Checkout [our paper][htdemucs] for more information. It has been trained on the [MUSDB HQ][musdb] dataset + an extra training dataset of 800 songs. This model separates drums, bass and vocals and other stems for any song.

As Hybrid Transformer Demucs is brand new, it is not activated by default, you can activate it in the usual commands described hereafter with -n htdemucs_ft . The single, non fine-tuned model is provided as -n htdemucs , and the retrained baseline as -n hdemucs_mmi . The Sparse Hybrid Transformer model decribed in our paper is not provided as its requires custom CUDA code that is not ready for release yet. We are also releasing an experimental 6 sources model, that adds a guitar and piano source. Quick testing seems to show okay quality for guitar , but a lot of bleeding and artifacts for the piano source.

The list of pre-trained models is:
- htdemucs : first version of Hybrid Transformer Demucs. Trained on MusDB + 800 songs. Default model.
- htdemucs_ft : fine-tuned version of htdemucs , separation will take 4 times more time but might be a bit better. Same training set as htdemucs .
- htdemucs_6s : 6 sources version of htdemucs , with piano and guitar being added as sources. Note that the piano source is not working great at the moment.
- hdemucs_mmi : Hybrid Demucs v3, retrained on MusDB + 800 songs.
- mdx : trained only on MusDB HQ, winning model on track A at the [MDX][mdx] challenge.
- mdx_extra : trained with extra training data ( including MusDB test set ), ranked 2nd on the track B of the [MDX][mdx] challenge.
- mdx_q , mdx_extra_q : quantized version of the previous models. Smaller download and storage but quality can be slightly worse.
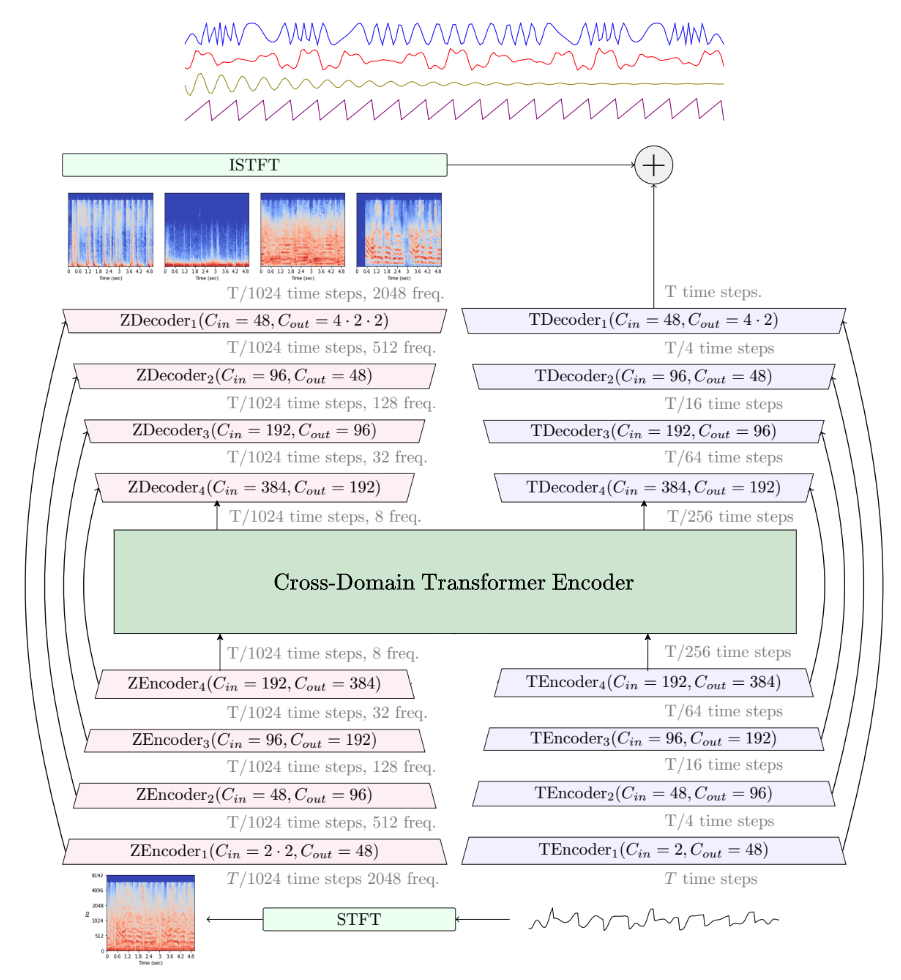
Schema representing the structure of Hybrid Transformer Demucs,
    with a dual U-Net structure, one branch for the temporal domain,
    and one branch for the spectral domain. There is a cross-domain Transformer between the Encoders and Decoders.

How to cite
@inproceedings{rouard2022hybrid,
  title={Hybrid Transformers for Music Source Separation},
  author={Rouard, Simon and Massa, Francisco and D{\'e}fossez, Alexandre},
  booktitle={ICASSP 23},
  year={2023}
}

@inproceedings{defossez2021hybrid,
  title={Hybrid Spectrogram and Waveform Source Separation},
  author={D{\'e}fossez, Alexandre},
  booktitle={Proceedings of the ISMIR 2021 Workshop on Music Source Separation},
  year={2021}
}
Pricing of demucs replicate.com

Run time and cost

This model costs approximately $0.044 to run on Replicate, or 22 runs per $1, but this varies depending on your inputs. It is also open source and you can run it on your own computer with Docker .

This model runs on Nvidia T4 GPU hardware . Predictions typically complete within 4 minutes. The predict time for this model varies significantly based on the inputs.

Runs of cjwbw demucs on replicate.com

184.6K
Total runs
0
24-hour runs
0
3-day runs
0
7-day runs
0
30-day runs

More Information About demucs replicate.com Model

demucs replicate.com

demucs replicate.com is an AI model on replicate.com that provides demucs's model effect (Demucs Music Source Separation), which can be used instantly with this cjwbw demucs model. replicate.com supports a free trial of the demucs model, and also provides paid use of the demucs. Support call demucs model through api, including Node.js, Python, http.

demucs replicate.com Url

https://replicate.com/cjwbw/demucs

cjwbw demucs online free

demucs replicate.com is an online trial and call api platform, which integrates demucs's modeling effects, including api services, and provides a free online trial of demucs, you can try demucs online for free by clicking the link below.

cjwbw demucs online free url in replicate.com:

https://replicate.com/cjwbw/demucs

demucs install

demucs is an open source model from GitHub that offers a free installation service, and any user can find demucs on GitHub to install. At the same time, replicate.com provides the effect of demucs install, users can directly use demucs installed effect in replicate.com for debugging and trial. It also supports api for free installation.

demucs install url in replicate.com:

https://replicate.com/cjwbw/demucs

demucs install url in github:

https://github.com/chenxwh/demucs

Url of demucs

Provider of demucs replicate.com

Other API from cjwbw

replicate

Remove images background

Total runs: 8.3M
Run Growth: 0
Growth Rate: 0.00%
Updated:Novembre 30 2022
replicate

openai/clip-vit-large-patch14 with Transformers

Total runs: 6.9M
Run Growth: 0
Growth Rate: 0.00%
Updated:Septembre 22 2022
replicate

ZoeDepth: Combining relative and metric depth

Total runs: 4.5M
Run Growth: 0
Growth Rate: 0.00%
Updated:Mars 05 2023
replicate

Anime-themed text-to-image stable diffusion model

Total runs: 4.0M
Run Growth: 0
Growth Rate: 0.00%
Updated:Mars 20 2024
replicate

high-quality, highly detailed anime style stable-diffusion with better VAE

Total runs: 3.5M
Run Growth: 0
Growth Rate: 0.00%
Updated:Janvier 15 2023
replicate

high-quality, highly detailed anime-style Stable Diffusion models

Total runs: 3.3M
Run Growth: 0
Growth Rate: 0.00%
Updated:Janvier 23 2023
replicate

Real-ESRGAN: Real-World Blind Super-Resolution

Total runs: 2.2M
Run Growth: 0
Growth Rate: 0.00%
Updated:Février 19 2023
replicate

powerful open-source visual language model

Total runs: 1.5M
Run Growth: 0
Growth Rate: 0.00%
Updated:Novembre 30 2023
replicate

Dream Shaper stable diffusion

Total runs: 1.3M
Run Growth: 0
Growth Rate: 0.00%
Updated:Mars 12 2023
replicate

Stable Diffusion on Danbooru images

Total runs: 1.1M
Run Growth: 0
Growth Rate: 0.00%
Updated:Octobre 10 2022
replicate

Colorization using a Generative Color Prior for Natural Images

Total runs: 564.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:Août 04 2022
replicate

Real-ESRGAN super-resolution model from ruDALL-E

Total runs: 483.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:Septembre 29 2022
replicate

Robust Monocular Depth Estimation

Total runs: 414.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:Février 15 2023
replicate

high-quality, highly detailed anime style stable-diffusion

Total runs: 353.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:Décembre 20 2022
replicate

sd-v2 with diffusers, test version!

Total runs: 280.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:Décembre 02 2022
replicate

a dreambooth model trained on a diverse set of analog photographs

Total runs: 234.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:Janvier 01 2023
replicate

Practicing Model Scaling for Photo-Realistic Image Restoration In the Wild. This version uses LLaVA-13b for captioning.

Total runs: 186.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:Février 24 2024
replicate

Advanced text-image comprehension and composition based on InternLM

Total runs: 164.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:Octobre 02 2023
replicate

Multi-stage text-to-video generation

Total runs: 143.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:Mars 24 2023
replicate

Blind Face Restoration with Vector-Quantized Dictionary and Parallel Decoder

Total runs: 140.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:Août 04 2022
replicate

Stylized Audio-Driven Single Image Talking Face Animation

Total runs: 127.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:Juin 01 2024
replicate

SeamlessM4T—Massively Multilingual & Multimodal Machine Translation

Total runs: 82.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:Septembre 14 2023
replicate

VideoCrafter2: Text-to-Video and Image-to-Video Generation and Editing

Total runs: 66.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:Janvier 31 2024
replicate

stable-diffusion with negative prompts, more scheduler

Total runs: 65.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:Octobre 08 2022
replicate

Background removal model developed by BRIA.AI, trained on a carefully selected dataset and is available as an open-source model for non-commercial use.

Total runs: 55.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:Février 07 2024
replicate

with large-v2 checkpoint

Total runs: 54.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:Décembre 16 2022
replicate

Unsupervised Night Image Enhancement

Total runs: 41.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:Août 14 2022
replicate

Text-to-Image Diffusion Models are Zero-Shot Video Generators

Total runs: 41.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:Avril 08 2023
replicate

stable-diffusion with v1-5 checkpoint

Total runs: 35.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:Octobre 26 2022
replicate

Tuning-Free Multi-Subject Image Generation with Localized Attention

Total runs: 34.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:Mai 19 2023
replicate

high-quality highly detailed anime stylized latent diffusion model

Total runs: 31.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:Février 21 2023
replicate

mixed stable diffusion model

Total runs: 30.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:Mars 05 2023
replicate

Portraits with stable-diffusion

Total runs: 24.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:Janvier 25 2023
replicate

VQ-Diffusion for Text-to-Image Synthesis

Total runs: 20.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:Août 10 2022
replicate

Practicing Model Scaling for Photo-Realistic Image Restoration In the Wild. This is the SUPIR-v0Q model and does NOT use LLaVA-13b.

Total runs: 19.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:Février 24 2024
replicate

Image Manipulatinon with Diffusion Autoencoders

Total runs: 17.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:Août 04 2022
replicate

Generating Conditional 3D Implicit Functions

Total runs: 15.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:Mai 20 2023
replicate

High-Quality Video Generation with Cascaded Latent Diffusion Models

Total runs: 13.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:Novembre 21 2023
replicate

Audio-Driven Synthesis of Photorealistic Portrait Animations

Total runs: 13.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:Avril 01 2024
replicate

stable-diffusion models for high quality and detailed anime images

Total runs: 13.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:Janvier 01 2023
replicate

Practicing Model Scaling for Photo-Realistic Image Restoration In the Wild. This is the SUPIR-v0F model and does NOT use LLaVA-13b.

Total runs: 13.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:Février 24 2024
replicate

Highly practical solution for robust monocular depth estimation by training on a combination of 1.5M labeled images and 62M+ unlabeled images

Total runs: 11.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:Janvier 24 2024
replicate

Zero-Shot Speech Editing and Text-to-Speech in the Wild

Total runs: 9.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:Mars 15 2025
replicate

Pose-Invariant Hairstyle Transfer

Total runs: 9.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:Août 21 2022
replicate

Point-E: A System for Generating 3D Point Clouds from Complex Prompts

Total runs: 8.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:Janvier 17 2023
replicate

A linear estimator on top of clip to predict the aesthetic quality of pictures

Total runs: 8.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:Novembre 18 2022
replicate

Decoding Micromotion in Low-dimensional Latent Spaces from StyleGAN

Total runs: 8.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:Août 04 2022
replicate

fine-tuned Stable Diffusion model trained on the game art from Elden Ring

Total runs: 6.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:Novembre 03 2022
replicate

Zero-shot Image-to-Image Translation

Total runs: 6.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:Février 12 2023
replicate

Weak-to-Strong Training of Diffusion Transformer for 4K Text-to-Image Generation

Total runs: 6.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:Avril 14 2024
replicate

Pix2Struct: Screenshot Parsing as Pretraining for Visual Language Understanding

Total runs: 6.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:Mars 29 2023
replicate

Van Gough on Stable Diffusion via Dreambooth

Total runs: 5.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:Novembre 08 2022
replicate

Finte-tuned Stable Diffusion on high quality 3D images with a futuristic Sci-Fi theme

Total runs: 5.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:Janvier 08 2023
replicate

face alignment using stylegan-encoding

Total runs: 4.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:Mai 27 2022
replicate

Clip-Guided Diffusion Model for Image Generation

Total runs: 4.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:Mars 12 2022
replicate

Efficient Pretraining of Text-to-Image Models

Total runs: 4.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:Septembre 16 2023
replicate

Separate Anything You Describe

Total runs: 4.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:Octobre 20 2023
replicate

Inpainting using Denoising Diffusion Probabilistic Models

Total runs: 4.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:Août 17 2022
replicate

Learning Adapters towards Controllable for Text-to-Image Diffusion Models

Total runs: 3.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:Février 18 2023
replicate

End-to-End Document Image Enhancement Transformer

Total runs: 3.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:Août 30 2022
replicate

dreambooth trained on a very diverse dataset ranging from photographs to paintings

Total runs: 3.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:Décembre 09 2022
replicate

Disco Diffusion style on Stable Diffusion via Dreambooth

Total runs: 3.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:Novembre 08 2022
replicate

Efficient Diffusion Model for Image Super-resolution by Residual Shifting

Total runs: 3.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:Août 02 2023
replicate

Real-Time High-Resolution Background Matting

Total runs: 2.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:Novembre 18 2022
replicate

Prompt-to-prompt image editing with cross-attention control

Total runs: 2.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:Octobre 30 2022
replicate

Training-free Controllable Text-to-Video Generation

Total runs: 2.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:Mai 28 2023
replicate

lightweight text-to-speech (TTS) model, trained on 10.5K hours of audio data

Total runs: 2.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:Avril 16 2024
replicate

A Visual Language Model for GUI Agents

Total runs: 2.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:Février 05 2024
replicate

herge_style on Stable Diffusion via Dreambooth

Total runs: 2.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:Novembre 08 2022
replicate

Controlling Vision-Language Models for Universal Image Restoration

Total runs: 2.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:Octobre 13 2023
replicate

Consistent Diffusion Features for Consistent Video Editing

Total runs: 2.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:Janvier 23 2024
replicate

Finetuned Stable-diffusion from Gerry Anderson Supermarionation

Total runs: 1.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:Mars 04 2023
replicate

text-to-image generation

Total runs: 1.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:Août 10 2022
replicate

Diffusion Models as Text Painters

Total runs: 1.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:Juin 04 2023
replicate

Open-source Distilled Stable Diffusion 100% speedup

Total runs: 1.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:Décembre 13 2023
replicate

Hyper-SD: Trajectory Segmented Consistency Model for Efficient Image Synthesis

Total runs: 1.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:Avril 27 2024
replicate

High-quality multilingual text-to-speech library

Total runs: 1.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:Mars 03 2024
replicate

Panoptic Scene Graph Generation

Total runs: 1.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:Août 13 2022
replicate

text-to-video generation model

Total runs: 1.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:Novembre 26 2023