
cjwbw / stable-diffusion-2-1-unclip

Stable Diffusion v2-1-unclip Model

replicate.com
Total runs: 2.3K
24-hour runs: 0
7-day runs: 0
30-day runs: 0
Model's Last Updated: March 25 2023

Introduction of stable-diffusion-2-1-unclip

Model Details of stable-diffusion-2-1-unclip

Readme

Stable unCLIP

unCLIP is the approach behind OpenAI’s DALL·E 2 , trained to invert CLIP image embeddings. We finetuned SD 2.1 to accept a CLIP ViT-L/14 image embedding in addition to the text encodings. This means that the model can be used to produce image variations, but can also be combined with a text-to-image embedding prior to yield a full text-to-image model at 768x768 resolution.

If you plan on building applications on top of the model that the general public may use, you are responsible for adding the guardrails to minimize or prevent misuse of the application, especially for use-cases highlighted in the sections below (Misuse, Malicious Use, and Out-of-Scope Use).
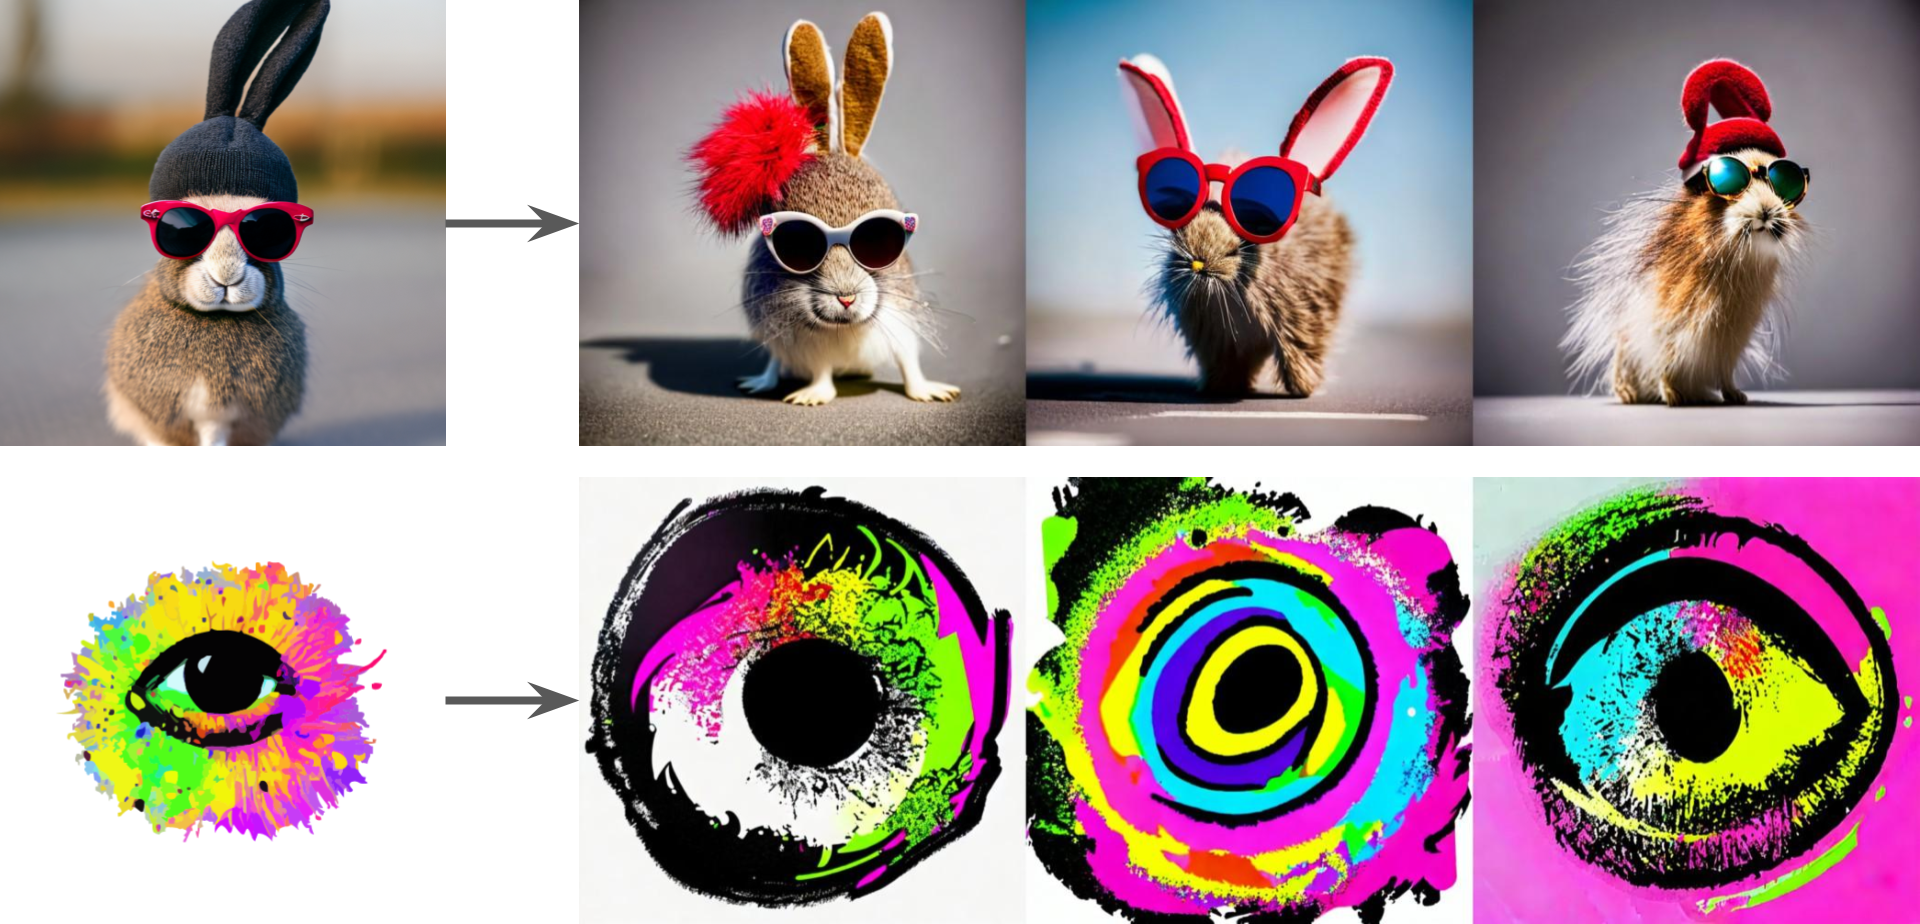
Example

Model Details
  • Developed by: Robin Rombach, Patrick Esser
  • Model type: Diffusion-based text-to-image generation model
  • Language(s): English
  • License: CreativeML Open RAIL++-M License
  • Model Description: This is a model that can be used to generate and modify images based on text prompts. It is a Latent Diffusion Model that uses a fixed, pretrained text encoder ( OpenCLIP-ViT/H ).
  • Resources for more information: GitHub Repository .
  • Cite as:

    @InProceedings{Rombach_2022_CVPR, author = {Rombach, Robin and Blattmann, Andreas and Lorenz, Dominik and Esser, Patrick and Ommer, Bj"orn}, title = {High-Resolution Image Synthesis With Latent Diffusion Models}, booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)}, month = {June}, year = {2022}, pages = {10684-10695} }

Uses
Direct Use

The model is intended for research purposes only. Possible research areas and tasks include

  • Safe deployment of models which have the potential to generate harmful content.
  • Probing and understanding the limitations and biases of generative models.
  • Generation of artworks and use in design and other artistic processes.
  • Applications in educational or creative tools.
  • Research on generative models.

Excluded uses are described below.

### Misuse, Malicious Use, and Out-of-Scope Use Note: This section is originally taken from the DALLE-MINI model card , was used for Stable Diffusion v1, but applies in the same way to Stable Diffusion v2 .

The model should not be used to intentionally create or disseminate images that create hostile or alienating environments for people. This includes generating images that people would foreseeably find disturbing, distressing, or offensive; or content that propagates historical or current stereotypes.

Out-of-Scope Use

The model was not trained to be factual or true representations of people or events, and therefore using the model to generate such content is out-of-scope for the abilities of this model.

Misuse and Malicious Use

Using the model to generate content that is cruel to individuals is a misuse of this model. This includes, but is not limited to:

  • Generating demeaning, dehumanizing, or otherwise harmful representations of people or their environments, cultures, religions, etc.
  • Intentionally promoting or propagating discriminatory content or harmful stereotypes.
  • Impersonating individuals without their consent.
  • Sexual content without consent of the people who might see it.
  • Mis- and disinformation
  • Representations of egregious violence and gore
  • Sharing of copyrighted or licensed material in violation of its terms of use.
  • Sharing content that is an alteration of copyrighted or licensed material in violation of its terms of use.
Limitations and Bias
Limitations
  • The model does not achieve perfect photorealism
  • The model cannot render legible text
  • The model does not perform well on more difficult tasks which involve compositionality, such as rendering an image corresponding to “A red cube on top of a blue sphere”
  • Faces and people in general may not be generated properly.
  • The model was trained mainly with English captions and will not work as well in other languages.
  • The autoencoding part of the model is lossy
  • The model was trained on a subset of the large-scale dataset LAION-5B , which contains adult, violent and sexual content. To partially mitigate this, we have filtered the dataset using LAION’s NFSW detector (see Training section).
Bias

While the capabilities of image generation models are impressive, they can also reinforce or exacerbate social biases. Stable Diffusion was primarily trained on subsets of LAION-2B(en) , which consists of images that are limited to English descriptions. Texts and images from communities and cultures that use other languages are likely to be insufficiently accounted for. This affects the overall output of the model, as white and western cultures are often set as the default. Further, the ability of the model to generate content with non-English prompts is significantly worse than with English-language prompts. Stable Diffusion v2 mirrors and exacerbates biases to such a degree that viewer discretion must be advised irrespective of the input or its intent.
Pricing of stable-diffusion-2-1-unclip replicate.com

Run time and cost

This model costs approximately $0.024 to run on Replicate, or 41 runs per $1, but this varies depending on your inputs. It is also open source and you can run it on your own computer with Docker .

This model runs on Nvidia A100 (80GB) GPU hardware . Predictions typically complete within 17 seconds. The predict time for this model varies significantly based on the inputs.

Runs of cjwbw stable-diffusion-2-1-unclip on replicate.com

2.3K
Total runs
0
24-hour runs
0
3-day runs
0
7-day runs
0
30-day runs

More Information About stable-diffusion-2-1-unclip replicate.com Model

stable-diffusion-2-1-unclip replicate.com

stable-diffusion-2-1-unclip replicate.com is an AI model on replicate.com that provides stable-diffusion-2-1-unclip's model effect (Stable Diffusion v2-1-unclip Model), which can be used instantly with this cjwbw stable-diffusion-2-1-unclip model. replicate.com supports a free trial of the stable-diffusion-2-1-unclip model, and also provides paid use of the stable-diffusion-2-1-unclip. Support call stable-diffusion-2-1-unclip model through api, including Node.js, Python, http.

stable-diffusion-2-1-unclip replicate.com Url

https://replicate.com/cjwbw/stable-diffusion-2-1-unclip

cjwbw stable-diffusion-2-1-unclip online free

stable-diffusion-2-1-unclip replicate.com is an online trial and call api platform, which integrates stable-diffusion-2-1-unclip's modeling effects, including api services, and provides a free online trial of stable-diffusion-2-1-unclip, you can try stable-diffusion-2-1-unclip online for free by clicking the link below.

cjwbw stable-diffusion-2-1-unclip online free url in replicate.com:

https://replicate.com/cjwbw/stable-diffusion-2-1-unclip

stable-diffusion-2-1-unclip install

stable-diffusion-2-1-unclip is an open source model from GitHub that offers a free installation service, and any user can find stable-diffusion-2-1-unclip on GitHub to install. At the same time, replicate.com provides the effect of stable-diffusion-2-1-unclip install, users can directly use stable-diffusion-2-1-unclip installed effect in replicate.com for debugging and trial. It also supports api for free installation.

stable-diffusion-2-1-unclip install url in replicate.com:

https://replicate.com/cjwbw/stable-diffusion-2-1-unclip

Url of stable-diffusion-2-1-unclip

stable-diffusion-2-1-unclip replicate.com Url

Provider of stable-diffusion-2-1-unclip replicate.com

cjwbw
ORGANIZATIONS

Other API from cjwbw

replicate

Remove images background

Total runs: 8.3M
Run Growth: 0
Growth Rate: 0.00%
Updated:November 30 2022
replicate

openai/clip-vit-large-patch14 with Transformers

Total runs: 6.9M
Run Growth: 0
Growth Rate: 0.00%
Updated:September 22 2022
replicate

ZoeDepth: Combining relative and metric depth

Total runs: 4.5M
Run Growth: 0
Growth Rate: 0.00%
Updated:March 05 2023
replicate

Anime-themed text-to-image stable diffusion model

Total runs: 4.0M
Run Growth: 0
Growth Rate: 0.00%
Updated:March 20 2024
replicate

high-quality, highly detailed anime style stable-diffusion with better VAE

Total runs: 3.5M
Run Growth: 0
Growth Rate: 0.00%
Updated:January 15 2023
replicate

high-quality, highly detailed anime-style Stable Diffusion models

Total runs: 3.3M
Run Growth: 0
Growth Rate: 0.00%
Updated:January 23 2023
replicate

Real-ESRGAN: Real-World Blind Super-Resolution

Total runs: 2.2M
Run Growth: 0
Growth Rate: 0.00%
Updated:February 19 2023
replicate

powerful open-source visual language model

Total runs: 1.5M
Run Growth: 0
Growth Rate: 0.00%
Updated:November 30 2023
replicate

Dream Shaper stable diffusion

Total runs: 1.3M
Run Growth: 0
Growth Rate: 0.00%
Updated:March 12 2023
replicate

Stable Diffusion on Danbooru images

Total runs: 1.1M
Run Growth: 0
Growth Rate: 0.00%
Updated:October 10 2022
replicate

Colorization using a Generative Color Prior for Natural Images

Total runs: 564.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 04 2022
replicate

Real-ESRGAN super-resolution model from ruDALL-E

Total runs: 483.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 29 2022
replicate

Robust Monocular Depth Estimation

Total runs: 414.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:February 15 2023
replicate

high-quality, highly detailed anime style stable-diffusion

Total runs: 353.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:December 20 2022
replicate

sd-v2 with diffusers, test version!

Total runs: 280.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:December 02 2022
replicate

a dreambooth model trained on a diverse set of analog photographs

Total runs: 234.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:January 01 2023
replicate

Practicing Model Scaling for Photo-Realistic Image Restoration In the Wild. This version uses LLaVA-13b for captioning.

Total runs: 186.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:February 24 2024
replicate

Demucs Music Source Separation

Total runs: 184.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:July 02 2023
replicate

Advanced text-image comprehension and composition based on InternLM

Total runs: 164.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 02 2023
replicate

Multi-stage text-to-video generation

Total runs: 143.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:March 24 2023
replicate

Blind Face Restoration with Vector-Quantized Dictionary and Parallel Decoder

Total runs: 140.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 04 2022
replicate

Stylized Audio-Driven Single Image Talking Face Animation

Total runs: 127.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 01 2024
replicate

SeamlessM4T—Massively Multilingual & Multimodal Machine Translation

Total runs: 82.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 14 2023
replicate

VideoCrafter2: Text-to-Video and Image-to-Video Generation and Editing

Total runs: 66.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:January 31 2024
replicate

stable-diffusion with negative prompts, more scheduler

Total runs: 65.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 08 2022
replicate

Background removal model developed by BRIA.AI, trained on a carefully selected dataset and is available as an open-source model for non-commercial use.

Total runs: 55.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:February 07 2024
replicate

with large-v2 checkpoint

Total runs: 54.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:December 16 2022
replicate

Unsupervised Night Image Enhancement

Total runs: 41.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 14 2022
replicate

Text-to-Image Diffusion Models are Zero-Shot Video Generators

Total runs: 41.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:April 08 2023
replicate

stable-diffusion with v1-5 checkpoint

Total runs: 35.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 26 2022
replicate

Tuning-Free Multi-Subject Image Generation with Localized Attention

Total runs: 34.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:May 19 2023
replicate

high-quality highly detailed anime stylized latent diffusion model

Total runs: 31.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:February 21 2023
replicate

mixed stable diffusion model

Total runs: 30.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:March 05 2023
replicate

Portraits with stable-diffusion

Total runs: 24.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:January 25 2023
replicate

VQ-Diffusion for Text-to-Image Synthesis

Total runs: 20.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 10 2022
replicate

Practicing Model Scaling for Photo-Realistic Image Restoration In the Wild. This is the SUPIR-v0Q model and does NOT use LLaVA-13b.

Total runs: 19.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:February 24 2024
replicate

Image Manipulatinon with Diffusion Autoencoders

Total runs: 17.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 04 2022
replicate

Generating Conditional 3D Implicit Functions

Total runs: 15.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:May 20 2023
replicate

High-Quality Video Generation with Cascaded Latent Diffusion Models

Total runs: 13.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 21 2023
replicate

Audio-Driven Synthesis of Photorealistic Portrait Animations

Total runs: 13.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:April 01 2024
replicate

stable-diffusion models for high quality and detailed anime images

Total runs: 13.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:January 01 2023
replicate

Practicing Model Scaling for Photo-Realistic Image Restoration In the Wild. This is the SUPIR-v0F model and does NOT use LLaVA-13b.

Total runs: 13.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:February 24 2024
replicate

Highly practical solution for robust monocular depth estimation by training on a combination of 1.5M labeled images and 62M+ unlabeled images

Total runs: 11.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:January 24 2024
replicate

Zero-Shot Speech Editing and Text-to-Speech in the Wild

Total runs: 9.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:March 15 2025
replicate

Pose-Invariant Hairstyle Transfer

Total runs: 9.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 21 2022
replicate

Point-E: A System for Generating 3D Point Clouds from Complex Prompts

Total runs: 8.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:January 17 2023
replicate

A linear estimator on top of clip to predict the aesthetic quality of pictures

Total runs: 8.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 18 2022
replicate

Decoding Micromotion in Low-dimensional Latent Spaces from StyleGAN

Total runs: 8.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 04 2022
replicate

fine-tuned Stable Diffusion model trained on the game art from Elden Ring

Total runs: 6.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 03 2022
replicate

Zero-shot Image-to-Image Translation

Total runs: 6.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:February 12 2023
replicate

Weak-to-Strong Training of Diffusion Transformer for 4K Text-to-Image Generation

Total runs: 6.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:April 14 2024
replicate

Pix2Struct: Screenshot Parsing as Pretraining for Visual Language Understanding

Total runs: 6.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:March 29 2023
replicate

Van Gough on Stable Diffusion via Dreambooth

Total runs: 5.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 08 2022
replicate

Finte-tuned Stable Diffusion on high quality 3D images with a futuristic Sci-Fi theme

Total runs: 5.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:January 08 2023
replicate

face alignment using stylegan-encoding

Total runs: 4.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:May 27 2022
replicate

Clip-Guided Diffusion Model for Image Generation

Total runs: 4.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:March 12 2022
replicate

Efficient Pretraining of Text-to-Image Models

Total runs: 4.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 16 2023
replicate

Separate Anything You Describe

Total runs: 4.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 20 2023
replicate

Inpainting using Denoising Diffusion Probabilistic Models

Total runs: 4.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 17 2022
replicate

Learning Adapters towards Controllable for Text-to-Image Diffusion Models

Total runs: 3.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:February 18 2023
replicate

End-to-End Document Image Enhancement Transformer

Total runs: 3.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 30 2022
replicate

dreambooth trained on a very diverse dataset ranging from photographs to paintings

Total runs: 3.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:December 09 2022
replicate

Disco Diffusion style on Stable Diffusion via Dreambooth

Total runs: 3.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 08 2022
replicate

Efficient Diffusion Model for Image Super-resolution by Residual Shifting

Total runs: 3.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 02 2023
replicate

Real-Time High-Resolution Background Matting

Total runs: 2.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 18 2022
replicate

Prompt-to-prompt image editing with cross-attention control

Total runs: 2.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 30 2022
replicate

Training-free Controllable Text-to-Video Generation

Total runs: 2.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:May 28 2023
replicate

lightweight text-to-speech (TTS) model, trained on 10.5K hours of audio data

Total runs: 2.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:April 16 2024
replicate

A Visual Language Model for GUI Agents

Total runs: 2.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:February 05 2024
replicate

herge_style on Stable Diffusion via Dreambooth

Total runs: 2.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 08 2022
replicate

Controlling Vision-Language Models for Universal Image Restoration

Total runs: 2.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 13 2023
replicate

Consistent Diffusion Features for Consistent Video Editing

Total runs: 2.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:January 23 2024
replicate

Finetuned Stable-diffusion from Gerry Anderson Supermarionation

Total runs: 1.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:March 04 2023
replicate

text-to-image generation

Total runs: 1.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 10 2022
replicate

Diffusion Models as Text Painters

Total runs: 1.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 04 2023
replicate

Open-source Distilled Stable Diffusion 100% speedup

Total runs: 1.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:December 13 2023
replicate

Hyper-SD: Trajectory Segmented Consistency Model for Efficient Image Synthesis

Total runs: 1.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:April 27 2024
replicate

High-quality multilingual text-to-speech library

Total runs: 1.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:March 03 2024
replicate

Panoptic Scene Graph Generation

Total runs: 1.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 13 2022
replicate

text-to-video generation model

Total runs: 1.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 26 2023