




Sponsored by
APIMart
amazon / GDN-primed-HQwen3-8B-Instruct
Model's Last Updated: April 03 2026
text-generation
Introduction of GDN-primed-HQwen3-8B-Instruct
Model Details of GDN-primed-HQwen3-8B-Instruct
GDN-primed-HQwen3-8B-Instruct
GDN-primed-HQwen3-8B-Instruct is a Hybrid language model consisting of 50% Attention layers and 50% Gated DeltaNet (GDN) layers, primed from Qwen3-8B using the Hybrid Model Factory Priming pipeline. The model is instruction-tuned and supports context lengths up to 128K tokens.
GDN is a State-Space Model layer with constant memory and linear compute cost in the sequence length.
By combining Attention with GDN, our Hybrid model achieves up to 2× faster inference at long contexts while closely matching the base Transformer's quality .
Links
Why Hybrid?
Each Primed Hybrid model is initialized from a base Transformer by converting a portion of its Attention layers into State-Space Model (SSM) layers that maintain a fixed-size recurrent state instead of a growing KV cache. At a 50% Hybrid ratio, roughly half the KV cache (which grows linearly with sequence length) is replaced with fixed-size SSM state. The practical benefits:
- Higher throughput at long contexts — less memory on KV cache means more memory for batching
- More concurrent sequences — ~2× as many concurrent sequences before hitting memory limits
- Growing advantage with context length — at long contexts, Attention dominates the forward pass while SSM layers remain negligible in cost. Since the Hybrid model makes roughly half as many Attention calls as the base Transformer, the throughput advantage grows with context length
Increasing hybridization ratio, replacing more Attention layers with SSM layers, further reduces memory and increases throughput, typically at the expense of performance.
Model Overview
- Type : Causal Language Model (Hybrid Attention + SSM)
- Base Model : Qwen3-8B
- Hybrid Layer Type : Gated DeltaNet (GDN)
- Hybrid Ratio : 50% (18 Attention + 18 GDN layers)
- Parameters : ~8B
- Context Length : 128K natively
- Precision : bfloat16
- License : Apache 2.0
Note, this is an Instruct-tuned model and is not a thinking model, that is, it does not natively produce chain-of-thought thinking tokens in its generation trace.
Benchmark Results
Below we report benchmark performance for all our instruct-tuned Primed models. All Hybrid models use a 50% Hybrid ratio and are Primed from Qwen3-8B.
We consider two baselines:
- Qwen3-8B (non-thinking, from HF) : The original Qwen model evaluated in non-thinking mode, which is the intended mode for an Instruct model. This serves as the base Transformer from which we start the Priming procedure.
- Qwen3-8B (Long) : The Qwen model fine-tuned on our priming data, extending its native context length from 32K to 128K. All Primed Hybrid models use the same training hyperparameters and data as this baseline, making it a fair comparison for differing architectures.
On both long- and short-context benchmarks, our Primed Hybrid models closely match the performance of the Transformer model while having considerably lower deployment costs , showcasing the efficacy of the Priming process.
Long-Context Benchmarks
Evaluated on HELMET , MRCR , and BABILong across context lengths from 8K to 128K, using a weighted average with geometrically increasing weights for longer contexts.
The plot below shows performance averaged over context lengths from 8K to 128K.
For the Qwen3-8B (non-thinking, from HF) model, we used YaRN to evaluate on long-context tasks as directed in the model card
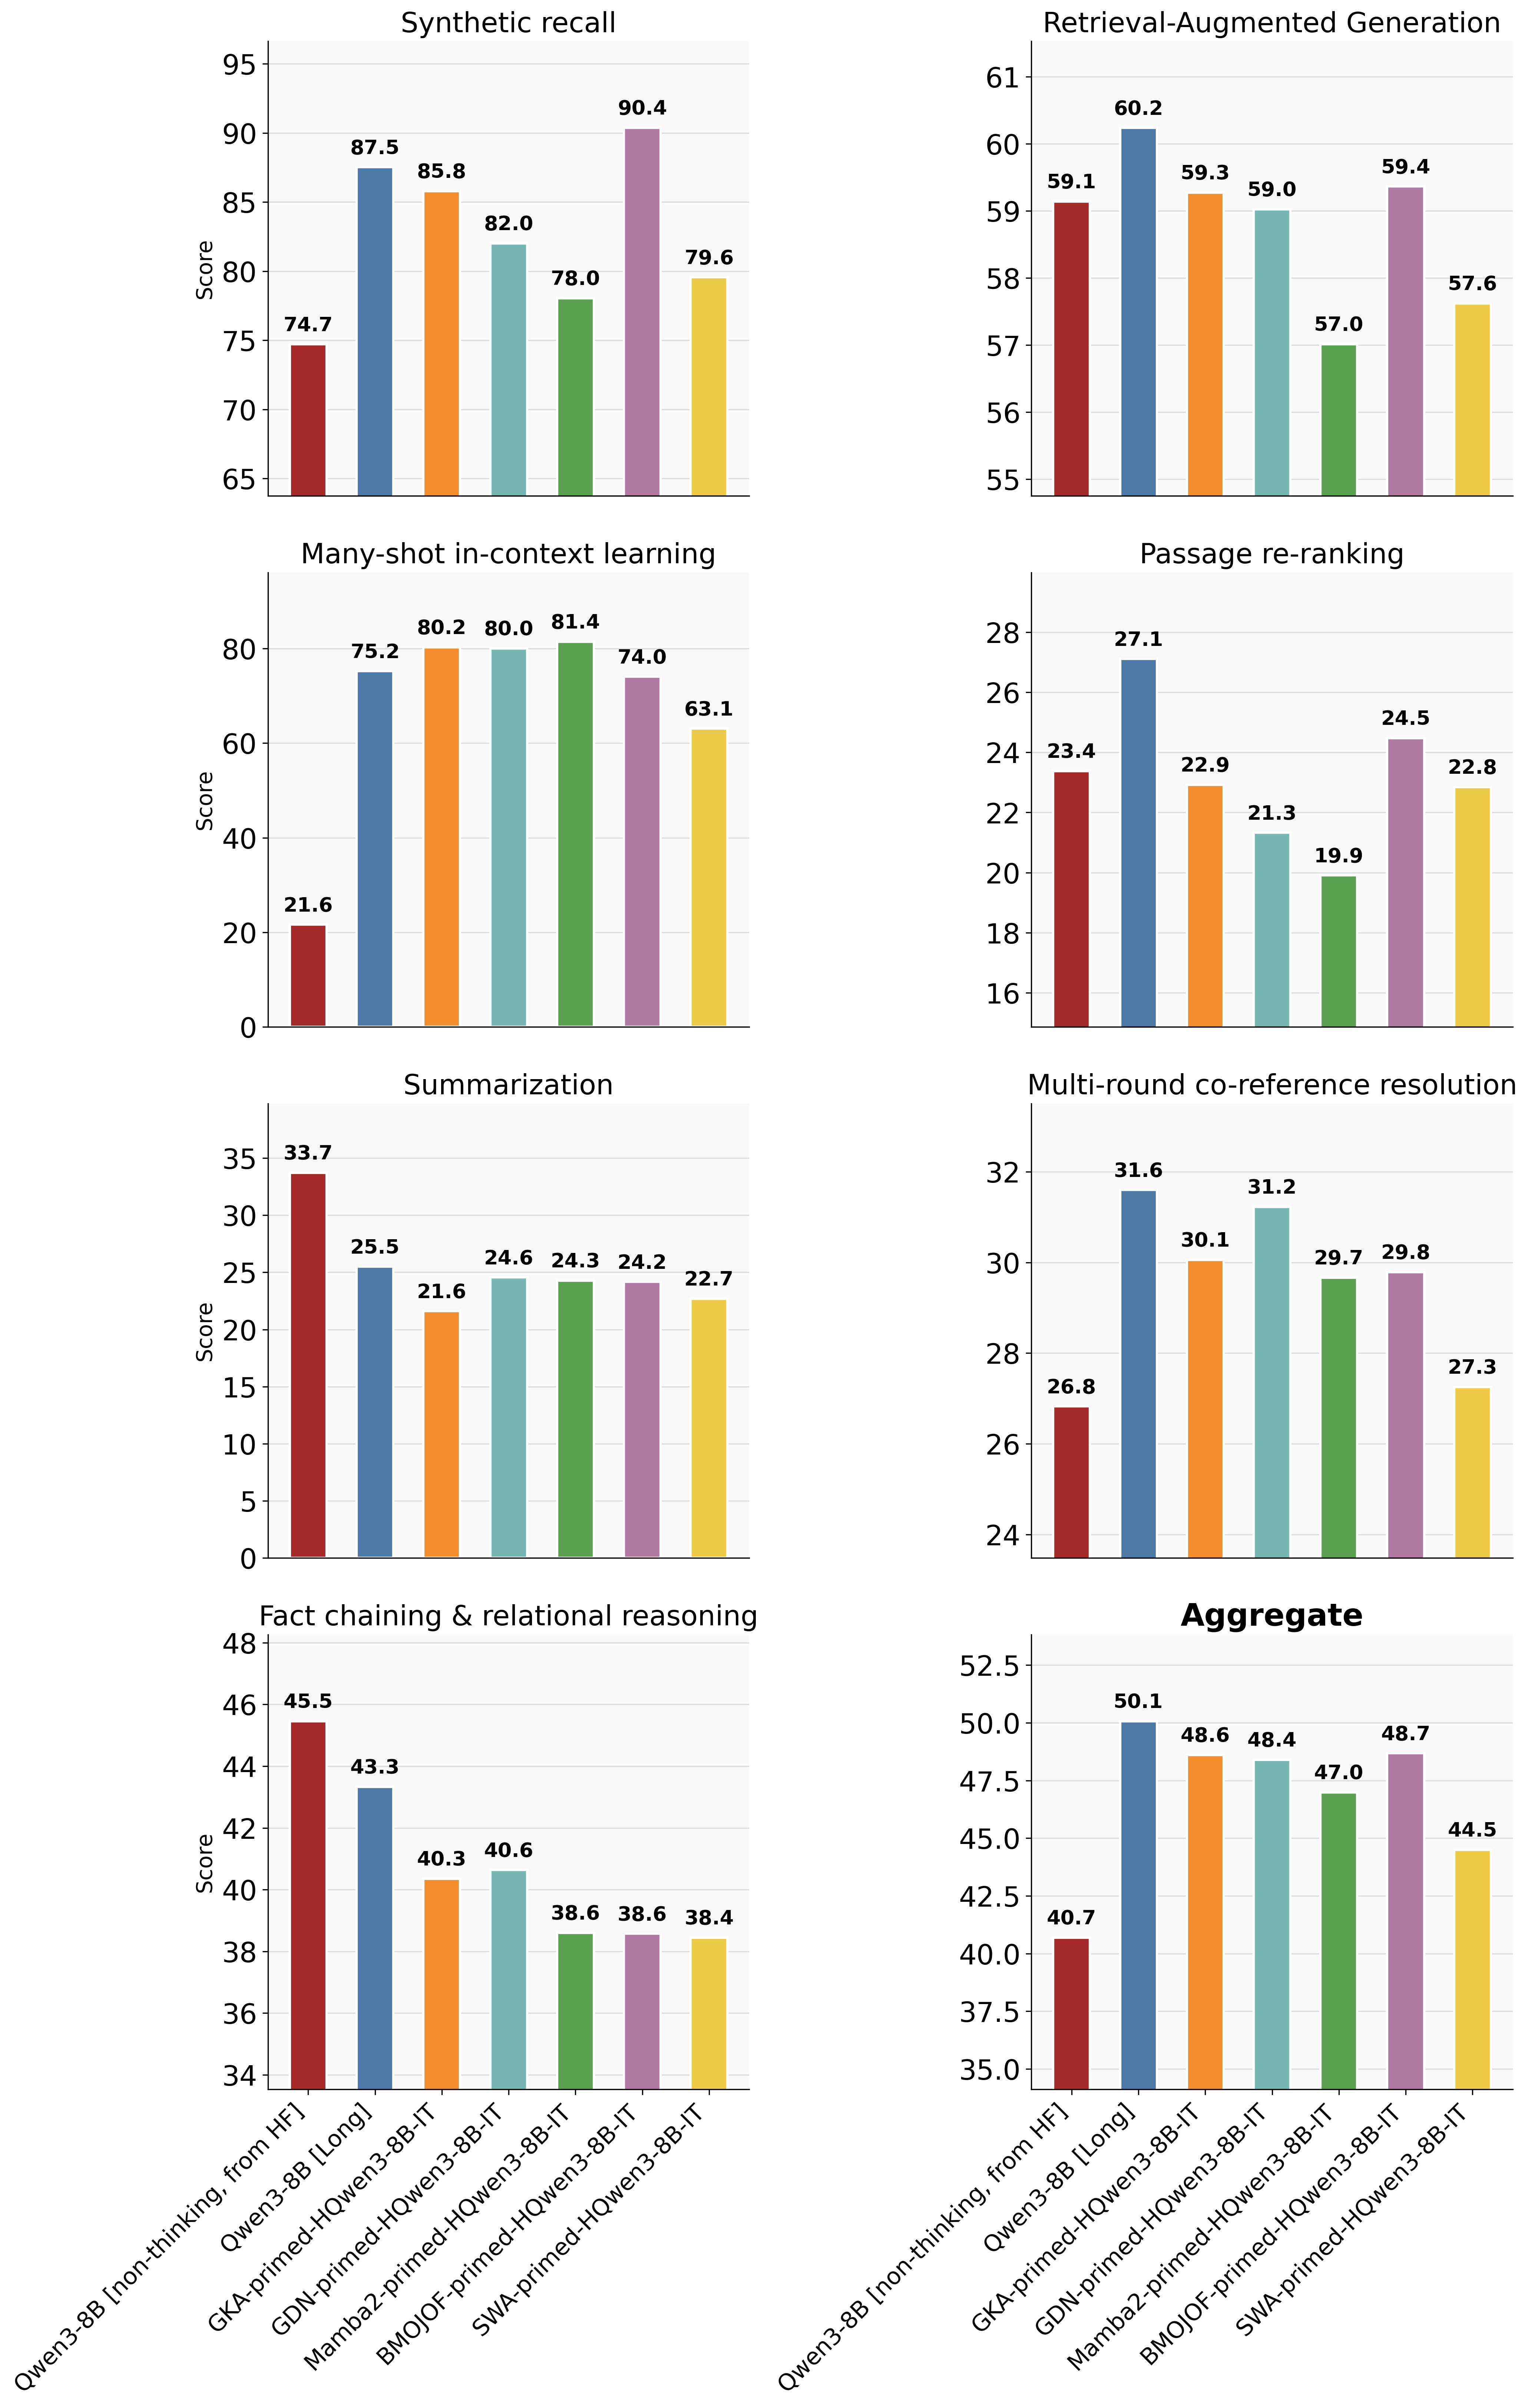
How close are the Hybrid models to the Transformer baseline on long context tasks? Primed GKA and GDN Hybrids are within ~1.5 points of Qwen3-8B (Long) on average, while being 1.5–2× faster at inference . Primed B'MOJO-F matches GKA/GDN in quality but is slower due to unfused SSM+SWA kernels ( details ). Primed Mamba2 lags further behind (approx. 3 point gap), consistent with GKA and GDN's higher expressivity.
Why SSM layers over Sliding Window Attention (SWA)? All Hybrid SSM models outperform the Hybrid SWA model (50% Attention + 50% SWA, window size 512). Even though SWA uses ~2× the effective state size of GKA at BF16, SSM layers retain information from the remote past, while SWA forgets everything beyond its window.
Short-Context NLP Benchmarks
Evaluations on Tulu3-dev from OLMES . All tasks are over a short-context length (≤ 8K). Each category in the table below averages the following Tulu3-dev subtasks:
- Math: GSM8K, MATH.
- Knowledge: MMLU, PopQA, TruthfulQA.
- Coding: HumanEval, HumanEval+.
- Reasoning: BigBenchHard.
- Instruction Following: IFEval.
| Model | Math | Knowledge | Coding | Reasoning | Instruction Following | Average |
|---|---|---|---|---|---|---|
| Qwen3-8B [non-thinking, from HF] | 81.36 | 49.33 | 91.77 | 74.31 | 85.59 | 76.47 |
| Qwen3-8B [Long] | 64.56 | 49.75 | 91 | 76.27 | 74.49 | 71.21 |
| GKA-primed-HQwen3-8B-Instruct | 64.15 | 47.90 | 90.46 | 72.60 | 70.98 | 69.22 |
| GDN-primed-HQwen3-8B-Instruct | 59.54 | 48.41 | 91.18 | 72.97 | 73.57 | 69.13 |
| Mamba2-primed-HQwen3-8B-Instruct | 57.77 | 46.91 | 89.56 | 70.99 | 74.86 | 68.02 |
| BMOJOF-primed-HQwen3-8B-Instruct | 65.69 | 48.63 | 90.02 | 76.42 | 75.60 | 71.27 |
How close are the Hybrid models to the Transformer baseline on short context tasks? All Primed Hybrid models are within ~3 points of Qwen3-8B (Long), using <0.5% of the base Transformer's pre-training token budget . Note, B'MOJO-F fully matches the Transformer baseline but is slower to deploy (see above ).
Which SSM layer type performs best? Among the non B'MOJO-F Hybrids, GKA ranks first (~2 point gap with Qwen3-8B [Long]), followed by GDN, then Mamba2. This ranking correlates with the expressiveness order of their respective SSM layers.
For applications to complex reasoning and coding problems check out our Primed Hybrid Reasoning models .
About Gated DeltaNet (GDN)
Gated DeltaNet is a State-Space Model layer with diagonal + low-rank transition dynamics. It extends Mamba2 with the Delta Update rule, improving expressiveness through gated state transitions while retaining Mamba2's efficiency.
For more details, see the GDN paper .
Architecture Details
| Component | Details |
|---|---|
| Number of Layers | 36 (18 Attention + 18 GDN) |
| Hidden Dimension | 4096 |
| Attention Heads | 32 (Q) / 8 (KV) |
| Head Dimension | 128 |
| Intermediate Dimension (FFN) | 12288 |
| Vocabulary Size | 151,936 |
| Position Encoding | RoPE (θ = 5,000,000) |
| Layer Layout | GDN layer indices were selected with our selective hybridization procedure |
Inference Efficiency
Sustained decode throughput (tokens/s) on 8× H200 GPUs (TP=8), measured during pure decode with a saturated KV cache. Benchmarked with random data (no prefix-caching benefits). See the full Inference guide for methodology and additional models.
| Model | 16K | 32K | 64K | 128K |
|---|---|---|---|---|
| GDN-primed-HQwen3-8B-Instruct | 17,479 (1.95×) | 10,080 (1.95×) | 5,521 (2.01×) | 2,863 (2.33×) |
GKA-primed-HQwen3-8B (
num_iter=30
, default)
|
15,892 (1.78×) | 9,159 (1.77×) | 5,173 (1.89×) | 2,736 (2.23×) |
| Mamba2-primed-HQwen3-8B | 16,844 (1.88×) | 9,966 (1.93×) | 5,460 (1.99×) | 2,825 (2.30×) |
| BMOJOF-primed-HQwen3-8B | 7,854 (0.88×) | 5,597 (1.08×) | 3,573 (1.30×) | 2,153 (1.75×) |
| Qwen3-8B (Long) | 8,951 | 5,174 | 2,740 | 1,227 |
Mean TTFT at the Transformer's saturated batch size (Hybrid model has memory to spare):
| Model | 16K | 32K | 64K | 128K |
|---|---|---|---|---|
| GDN-primed-HQwen3-8B-Instruct | 27,805 ms (1.00×) | 30,975 ms (0.95×) | 36,151 ms (0.85×) | 46,389 ms (0.74×) |
GKA-primed-HQwen3-8B (
num_iter=30
, default)
|
35,013 ms (1.26×) | 38,502 ms (1.18×) | 44,893 ms (1.06×) | 53,606 ms (0.85×) |
| Mamba2-primed-HQwen3-8B | 28,668 ms (1.03×) | 31,405 ms (0.96×) | 36,666 ms (0.86×) | 46,618 ms (0.74×) |
| BMOJOF-primed-HQwen3-8B | 44,763 ms (1.61×) | 47,600 ms (1.46×) | 52,272 ms (1.23×) | 61,702 ms (0.98×) |
| Qwen3-8B (Long) | 27,736 ms | 32,661 ms | 42,462 ms | 62,922 ms |
The decode throughput advantage grows with context length — from 1.95× at 16K to 2.33× at 128K — thanks to GDN layers maintaining a fixed-size recurrent state instead of a growing KV cache. TTFT crosses over at 32K and reaches 0.74× (26% faster) at 128K.
Usage
With vLLM (recommended)
Install the Hybrid Model Factory vLLM plugin in your local environment, then serve:
vllm serve amazon/GDN-primed-HQwen3-8B-Instruct \
  --enable-prefix-caching \
  --mamba-cache-mode align \
  --mamba-cache-dtype float32 \
  --mamba-ssm-cache-dtype float32
Query the server:
curl http://localhost:8000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "amazon/GDN-primed-HQwen3-8B-Instruct",
    "messages": [
      {"role": "system", "content": "You are a helpful assistant."},
      {"role": "user", "content": "What is Linear Attention in the context of LLMs?"}
    ]
  }'
The
--mamba-cache-dtype float32and--mamba-ssm-cache-dtype float32flags are important for accurate long-context generation. See the Inference guide for details on all recommended flags.
With Hugging Face Transformers
See the Inference guide for details on when we recommend the Hugging Face Transformers implementation as opposed to the highly optimized vLLM one.
from transformers import AutoModelForCausalLM, AutoTokenizer
import hmf.model.hybrid_zoo.models.model_register  # Register Hybrid models

model = AutoModelForCausalLM.from_pretrained(
    "amazon/GDN-primed-HQwen3-8B-Instruct", trust_remote_code=True
).to("cuda")
tokenizer = AutoTokenizer.from_pretrained("amazon/GDN-primed-HQwen3-8B-Instruct")

messages = [{"role": "user", "content": "What is linear attention in the context of LLMs?"}]
prompt = tokenizer.apply_chat_template(
    messages, tokenize=False, add_generation_prompt=True
)
inputs = tokenizer(prompt, return_tensors="pt").to("cuda")
outputs = model.generate(**inputs, max_new_tokens=256)
print(tokenizer.decode(outputs[0], skip_special_tokens=True))
Training-Free Context Extension
This model supports training-free context extension 2-4× its native context via an extension to Hybrid models of PICASO cache composition . See the State Composition guide for usage. Note, this is currently supported in Hugging Face Transformers only.
Training data
These models were produced through the multi-stage Priming pipeline from Hybrid Model Factory . Training data spans web documents, mathematics, long-context documents, and instruction-following and reasoning examples — each targeting a different capability axis. This diversity is critical: it allows the Priming procedure to convert a base Transformer into a more memory- and compute-efficient Hybrid architecture at nearly the same level of performance, using <0.5% of the base Transformer model's pre-training token budget.
Responsible AI Considerations
At Amazon, we are committed to developing AI responsibly and take a people-centric approach that prioritizes education, science, and our customers, to integrate responsible AI across the end-to-end AI lifecycle. We believe the use of AI must respect the rule of law and human rights, and we encourage the safe and responsible development of AI. When downloaded or used in accordance with AWS Responsible AI Policy , developers should work with their internal model team to ensure this model meets requirements for the relevant industry and use case and addresses unforeseen product misuse. Please report model quality, risk, security vulnerabilities or Amazon AI Concerns here .
Citation
@software{hybrid_model_factory,
  title = {Hybrid Model Factory},
  year = {2026},
  url = {https://github.com/awslabs/hybrid-model-factory}
}

@misc{yang2025gateddeltanetworksimproving,
      title={Gated Delta Networks: Improving Mamba2 with Delta Rule},
      author={Songlin Yang and Jan Kautz and Ali Hatamizadeh},
      year={2025},
      eprint={2412.06464},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2412.06464},
}
License
This model is licensed under the Apache 2.0 License .
Runs of amazon GDN-primed-HQwen3-8B-Instruct on huggingface.co
274
Total runs
0
24-hour runs
9
3-day runs
21
7-day runs
102
30-day runs
More Information About GDN-primed-HQwen3-8B-Instruct huggingface.co Model
Url of GDN-primed-HQwen3-8B-Instruct
GDN-primed-HQwen3-8B-Instruct huggingface.co Url
Provider of GDN-primed-HQwen3-8B-Instruct huggingface.co
Other API from amazon
Total runs:
9.1M
Run Growth:
6.5M
Growth Rate:
70.96%
Total runs:
1.2M
Run Growth:
-274.8K
Growth Rate:
-23.12%
Total runs:
1.0M
Run Growth:
-593.5K
Growth Rate:
-59.58%
Total runs:
921.8K
Run Growth:
-61.9K
Growth Rate:
-7.07%
Total runs:
636.4K
Run Growth:
-777.6K
Growth Rate:
-123.56%
Total runs:
466.3K
Run Growth:
-1.0M
Growth Rate:
-224.21%
Total runs:
165.8K
Run Growth:
7.6K
Growth Rate:
4.25%
Total runs:
96.4K
Run Growth:
-30.6K
Growth Rate:
-32.02%
Total runs:
36.6K
Run Growth:
-23.7K
Growth Rate:
-65.07%
Total runs:
5.4K
Run Growth:
1.1K
Growth Rate:
19.34%
Total runs:
3.8K
Run Growth:
0
Growth Rate:
0.00%
Total runs:
1.0K
Run Growth:
-12.7K
Growth Rate:
-1200.95%
Total runs:
524
Run Growth:
95
Growth Rate:
18.41%
Total runs:
372
Run Growth:
-664
Growth Rate:
-185.99%
Total runs:
173
Run Growth:
15
Growth Rate:
8.67%
Total runs:
148
Run Growth:
-126
Growth Rate:
-85.14%
Total runs:
145
Run Growth:
-6.8K
Growth Rate:
-4596.62%
Total runs:
137
Run Growth:
126
Growth Rate:
90.65%
Total runs:
129
Run Growth:
-131
Growth Rate:
-103.97%
Total runs:
121
Run Growth:
58
Growth Rate:
48.74%
Total runs:
107
Run Growth:
-184
Growth Rate:
-171.96%
Total runs:
67
Run Growth:
-72
Growth Rate:
-114.29%
Total runs:
51
Run Growth:
-45
Growth Rate:
-88.24%
Total runs:
46
Run Growth:
-5
Growth Rate:
-11.36%
Total runs:
33
Run Growth:
5
Growth Rate:
15.15%
Total runs:
29
Run Growth:
7
Growth Rate:
24.14%
Total runs:
17
Run Growth:
3
Growth Rate:
16.67%
Total runs:
15
Run Growth:
5
Growth Rate:
29.41%
Total runs:
13
Run Growth:
4
Growth Rate:
26.67%
Total runs:
13
Run Growth:
4
Growth Rate:
26.67%