



Sponsored by
ThumbnailCreator.com
anthonym21 / qwen3-0.6b-rlcd-decision
Model's Last Updated: September 19 2026
text-classification
Introduction of qwen3-0.6b-rlcd-decision
Model Details of qwen3-0.6b-rlcd-decision
Qwen3-0.6B RLCD decision model
A decision-only model: it reads one state and a list of typed questions, runs one forward pass, and returns a probability distribution over the options each question declares. It does not generate text. It is Qwen3-0.6B-Base after a short supervised warmup and 500 steps of reinforcement learning for calibrated decisions (RLCD), a REINFORCE loop under bandit feedback whose reward is the outcome minus the probability the model put on the option it chose. On the held-out test split it is as calibrated as the warmup it started from (ECE 0.021) and six accuracy points better (0.807 against 0.746); the same loop with a plain outcome reward ends at ECE 0.216 or worse.
Code, training, evaluation and the loader live at
github.com/anthony-maio/eve-rlcd
. This repository is the export of
runs/q-rlcd
from that project, and it needs the
rlcd
package from that repository to load; it is not a stock
transformers
checkpoint with a language-model head.
What is in the repository
The export format is
rlcd-decision-only-v1
, described by
decision.json
:
-
model.safetensors(2384.2 MB): the transformer body in fp32, every weight except the language-model head. The input embedding stays because the body needs it. -
decision_head.safetensors(0.1 MB): the 26 rows of the output head for the letter tokensA..Z(token ids 362, 425, 356, 422, 468, 434, 479, 472, 358, 619, 730, 444, 386, 451, 506, 393, 1207, 431, 328, 350, 547, 647, 467, 1599, 809, 1863), 26 x 1024 in fp32. -
decision.json: the letters and their ids, the prompt template, the primitive and confidence definitions, the training summary frommeta.json, the base model id,prepend_bos: false,pad_id: 151643,tied_embeddings: true, and the sha256 of both weight files. -
The tokenizer (
tokenizer.json,vocab.json,merges.txt,tokenizer_config.json,special_tokens_map.json,added_tokens.json,chat_template.jinja) andconfig.json.
The loader verifies both hashes before anything runs, checks every tensor, checks that the tokenizer still gives the recorded letter ids, and refuses a directory that carries an output head.
The prompt is fixed by
decision.json
and rendered by the loader:
User: Context:
<state>

Question: <question>
Options:
A) <option>
B) <option>
Answer with the letter only.
Assistant: The answer is
The readout is the softmax over the 26 letter rows at the last prompt token, masked at and beyond the option count. The state is left-truncated to
max_state_tokens
(default 1536) so the header always survives; a question is left-truncated from its text only, never from its options block, until its suffix fits
max_question_tokens
(default 448). The model was trained and evaluated on prompts of at most 512 tokens, and its calibration beyond about 500 is unmeasured.
The three primitives
git clone https://github.com/anthony-maio/eve-rlcd && cd eve-rlcd && uv sync
hf download anthonym21/qwen3-0.6b-rlcd-decision --local-dir qwen3-rlcd-decision
Run the examples from the repository root with
uv run python
.
Decider.load
takes a local directory.
ask
prefills the state once and runs every question suffix in one batched forward over the shared key/value cache, so each question sees the state and nothing else, and the answers equal those of a full-prompt pass to about 1e-6 in fp32 (the default;
fast=True
runs the body under bf16 autocast).
Choice: 2 to 26 unordered options. The answer holds
value
(the most probable option),
probs
(option to probability),
confidence
(the largest probability) and
entropy_confidence
(
1 - H(p) / ln K
).
from rlcd.decide import ChoiceQ, Decider

d = Decider.load("qwen3-rlcd-decision")
state = ("Ticket #4242 from an enterprise, tier 1 customer. Report: API latency spiked to 4 seconds; "
         "load balancer returning 502s. Note: all customers affected.")
[a] = d.ask(state, [ChoiceQ("Which department should handle this ticket?",
                            ["BILLING", "INFRASTRUCTURE", "SECURITY", "PRODUCT_SUPPORT"])])
# a["value"] == "INFRASTRUCTURE", a["confidence"] == 0.869700795598093
# a["probs"] == {"BILLING": 0.0598..., "INFRASTRUCTURE": 0.8697..., "SECURITY": 0.0448..., "PRODUCT_SUPPORT": 0.0257...}
Score: 2 to 26 ordered levels, listed low to high. The answer holds the choice fields plus
score
, the probability-weighted mean level index divided by
K - 1
, so 0 is the lowest level and 1 the highest.
from rlcd.decide import ScoreQ

[a] = d.ask(state, [ScoreQ("What is the priority of this ticket?", ["P3_LOW", "P2_NORMAL", "P1_HIGH", "P0_CRITICAL"])])
# a["value"] == "P0_CRITICAL", a["confidence"] == 0.9925466990992174, a["score"] == 0.9950223041045235
Noul: a yes/no question, rendered verbatim with the options
true
and
false
, exactly as the noul rows of the training data were rendered. The answer holds
p_true
and
confidence = max(p_true, 1 - p_true)
. Phrase it as a question; a bare proposition is a prompt the model was not trained on.
from rlcd.decide import NoulQ

[a] = d.ask(state, [NoulQ("Should an on-call engineer be paged immediately?")])
# a["p_true"] == 0.8894891738891602
The three questions above asked together take 66.1 ms on an RTX 4080. Eight 4-option questions on an 800-token state take 105.3 ms through
ask
against 440.9 ms one prompt at a time; sixty-four take 472.2 ms against 3679.1 ms. The equivalence proof and the full latency tables are in the repository's
docs/inference.md
.
How it was trained
Two stages from
Qwen/Qwen3-0.6B-Base
, full fine-tune, fp32 master weights with bf16 autocast, gradient checkpointing on, AdamW with betas 0.9 and 0.95 and weight decay 0.1, cosine schedule to a floor of 0.1 x peak after a linear warmup of 5 percent of the steps, prompts truncated to 512 tokens.
Warmup: supervised training on rows 0..6399 of the training file (6,400 labeled rows), 1 epoch, 64 prompts per step (micro-batch 4 x 16 accumulation), 100 steps, peak lr 2e-5. Its job is to teach the letter format; it reaches 0.746 test accuracy.
RLCD: from the warmup, rows 32000..63999 (32,000 rows, disjoint from the warmup rows), 2 epochs, 128 prompts per step (micro-batch 4 x 32 accumulation), 500 steps, peak lr 2e-5, seed 0, 4 sampled actions per prompt with a leave-one-out baseline over the group, no KL term (
kl 0.0
), no entropy bonus, evaluated every 50 steps on a 2,000-row stride sample of the validation split, checkpoint every 100 steps. Each step is one forward and one backward: the action is a single sampled letter, the environment returns 1 if it was the correct option and 0 otherwise, and the label itself is never shown. The reward is
r = c - p_a
; REINFORCE with it is an unbiased estimator of half the gradient of the Brier score of the full distribution, so its fixed point is a calibrated policy, and the identity is checked numerically in the repository's tests. The final checkpoint is what is exported; no checkpoint selection was done.
Hardware: one RTX 4080 (16 GB) under Windows 11, torch 2.11.0+cu128, transformers 4.57.6 (the published runs were produced under transformers 4.57.6; the repository now pins transformers 5.x, currently resolving to 5.17.0, under which the exported checkpoint reproduces the numbers below within the 0.002 bf16 rounding floor). Wall clock 493.8 s for the warmup and 4233.6 s for the RL run, peak VRAM 11,413 MB.
Training data: Bitext customer support intents, Banking77 (each row a sampled subset of 4 to 26 intents that always contains the truth), AG News, MultiNLI (premise as state, hypothesis as question), SST-5 and Yelp reviews as ordered scores, BoolQ as yes/no, and synthetic multi-field triage tickets (department, priority, escalate) generated from templates with deliberate ambiguity. A "None of the above" option is injected in a fraction of rows, sometimes as the correct answer with the truth removed, so the model has an abstain route. The build is
python -m rlcd.data build --out data --per-source 8000 --seed 0
; the exact files used are attached to the GitHub release
data-v1
.
Results
Every number is on the held-out 8,000-row test split at temperature 1, from the repository's
docs/results.md
. Cells with three values are mean [min, max] across the runs of the arm: one local RTX 4080 run at seed 0 (the one exported here) and two Colab A100 runs at seeds 1 and 2. Lower is better for ECE, Brier loss and NOTA false alarm.
| arm | n runs (hardware) | accuracy | ECE (15 bins) | Brier loss | mean confidence | NOTA recall | NOTA false alarm |
|---|---|---|---|---|---|---|---|
| warmup (100-step SFT on 6,400 rows) | 2 (local, colab) | 0.748 [0.746, 0.750] | 0.022 [0.019, 0.026] | 0.339 [0.339, 0.340] | 0.763 [0.755, 0.770] | 0.531 [0.501, 0.561] | 0.072 [0.061, 0.083] |
| supervised continuation (500 more SFT steps, same 6,400 rows) | 1 (colab) | 0.778 | 0.192 | 0.407 | 0.969 | 0.739 | 0.099 |
| RLCD (this model is the local run) | 3 (local, colab, colab) | 0.808 [0.806, 0.811] | 0.023 [0.020, 0.029] | 0.267 [0.264, 0.269] | 0.830 [0.824, 0.839] | 0.793 [0.779, 0.806] | 0.075 [0.067, 0.091] |
| RLVR, shared settings (lr 2e-5, stopped) | 1 (local) | 0.576 | 0.415 | 0.835 | 0.991 | 0.599 | 0.406 |
| RLVR, low lr (4e-6) | 3 (local, colab, colab) | 0.778 [0.775, 0.780] | 0.213 [0.209, 0.216] | 0.432 [0.424, 0.439] | 0.991 [0.989, 0.993] | 0.715 [0.709, 0.721] | 0.090 [0.085, 0.098] |
| oracle (labels revealed, same RL rows) | 3 (local, colab, colab) | 0.819 [0.817, 0.822] | 0.059 [0.046, 0.072] | 0.256 [0.253, 0.258] | 0.878 [0.868, 0.890] | 0.830 [0.807, 0.849] | 0.076 [0.067, 0.088] |
| 32k-label SFT reference (500 steps on rows 0..31999) | 1 (local) | 0.817 | 0.014 | 0.251 | 0.829 | 0.843 | 0.089 |
The exported checkpoint on its own, with 95 percent bootstrap intervals over the test rows: accuracy 0.807 [0.798, 0.816], Brier loss 0.268 [0.258, 0.279], ECE 0.021 [0.017, 0.030], mean confidence 0.828. Paired against the warmup it started from on the same rows: accuracy +0.062 [+0.053, +0.072], Brier -0.071 [-0.079, -0.061], ECE -0.005 [-0.014, +0.003]. Paired against RLVR at the low learning rate: accuracy +0.032 [+0.024, +0.040], ECE -0.195 [-0.202, -0.184]. Paired against the oracle: accuracy -0.014 [-0.021, -0.007], ECE -0.025 [-0.031, -0.017].
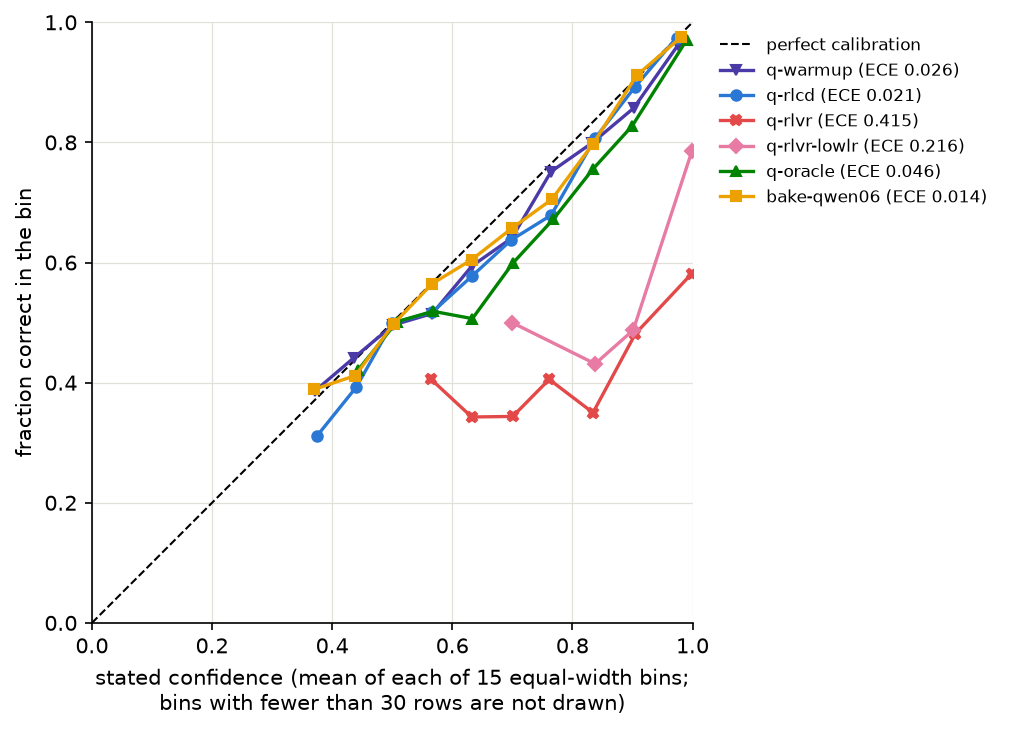
The comparison arms. All start from the same warmup and run the same loop on the same 32,000 rows unless noted. RLVR is the same REINFORCE update with the reward
r = c
(the outcome alone); at the shared learning rate it collapses inside 50 steps and the built-in stop rule ends it at step 150, and at a fifth of the rate (4e-6) it keeps its accuracy but says 0.991 on average. The oracle sees the label on every row and minimizes its negative log-likelihood, the ceiling bandit feedback should approach; it is about one accuracy point ahead and worse calibrated, because two supervised epochs over the same labels make it overconfident. The supervised continuation trains the warmup for 500 more steps on its own 6,400 labels and lands where RLVR low lr does, so the gain is not just more optimizer steps. The 32k-label SFT reference is one supervised pass over rows 0..31999 from the base model; it is the cheapest thing to do if you have the labels, and RLCD with a fifth of the labels plus bandit feedback lands just behind it (accuracy -0.009 [-0.017, -0.002], Brier +0.017 [+0.011, +0.024], ECE +0.007 [-0.002, +0.014]).
Known-posterior probe
The synthetic triage generator fixes the true posterior of its tickets, so calibration can be checked against a known answer rather than against frequencies in bins. 3,000 fresh tickets (seed 12345, 2 questions dropped for overlap with training contexts) ask the department question with one cued department (posterior 1.0 on it) or two equally cued departments (0.5 each), and the escalate question, whose answer follows the priority with probability 0.90. A calibrated model should say about 1.0, about 0.5, and about 0.90.
| arm | n runs | one cue: mean max p (ideal 1.0) | two cues: mean max p (ideal 0.5) | two cues: mass on the cued pair (ideal 1.0) | escalate: accuracy (ideal 0.90) | escalate: mean confidence (ideal 0.90) |
|---|---|---|---|---|---|---|
| warmup (100-step SFT on 6,400 rows) | 2 | 0.984 [0.983, 0.985] | 0.798 [0.782, 0.813] | 0.982 [0.979, 0.986] | 0.897 [0.897, 0.897] | 0.821 [0.808, 0.834] |
| supervised continuation (500 more SFT steps, same 6,400 rows) | 1 | 0.998 | 0.915 | 1.000 | 0.852 | 0.940 |
| RLCD | 3 | 0.973 [0.966, 0.980] | 0.593 [0.546, 0.628] | 0.915 [0.897, 0.924] | 0.897 [0.897, 0.897] | 0.932 [0.913, 0.944] |
| RLVR, shared settings (lr 2e-5, stopped) | 1 | 0.998 | 0.996 | 0.739 | 0.875 | 1.000 |
| RLVR, low lr (4e-6) | 3 | 0.999 [0.998, 1.000] | 0.990 [0.989, 0.992] | 0.998 [0.993, 1.000] | 0.897 [0.897, 0.897] | 1.000 [1.000, 1.000] |
| oracle (labels revealed, same RL rows) | 3 | 1.000 [1.000, 1.000] | 0.630 [0.618, 0.637] | 0.998 [0.997, 0.999] | 0.897 [0.897, 0.897] | 0.880 [0.828, 0.907] |
| 32k-label SFT reference (500 steps on rows 0..31999) | 1 | 0.995 | 0.598 | 0.997 | 0.897 | 0.935 |
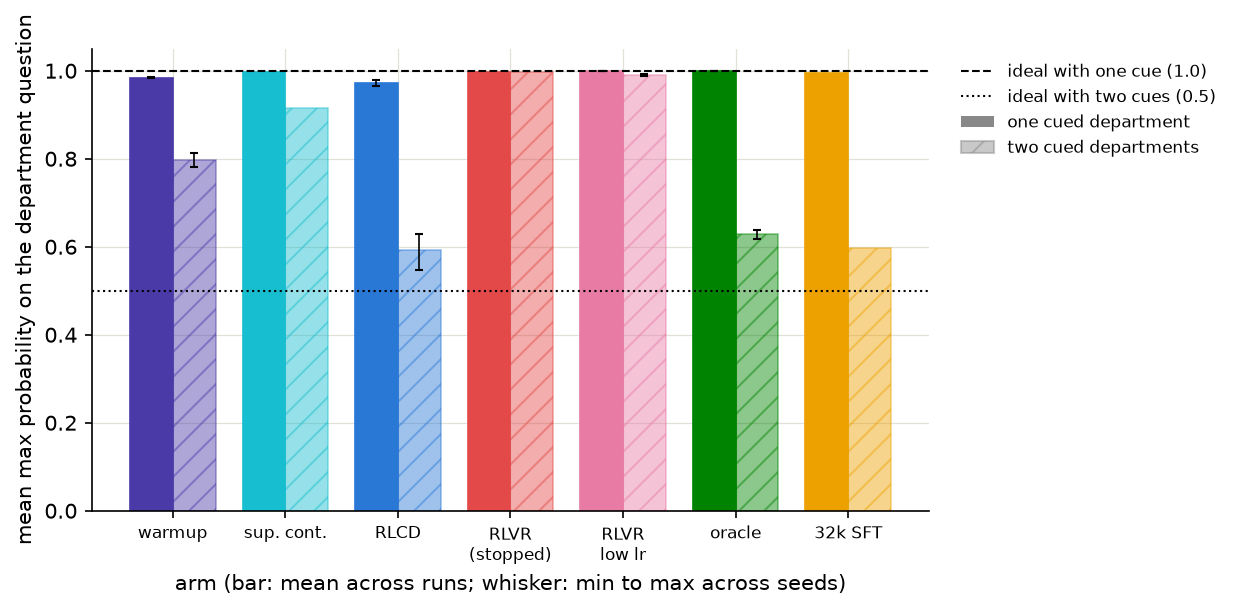
RLCD moved the ambiguous case from 0.798 toward 0.5 with bandit feedback only, where both RLVR arms say 0.99 and the supervised continuation moves the wrong way. Part of RLCD's lower max p is mass that leaked to the uncued departments (0.915 on the cued pair against 0.998 for the oracle), so it is not entirely a fairer split between the cued two, and on the escalate question it sits a little above the posterior (0.932 against 0.90).
Limitations
- Calibration was held, not improved. RLCD ended within about 0.01 ECE of its warmup on every seed, and its validation ECE rose to 0.064 (local), 0.067 and 0.123 (Colab seeds) mid-training before ending low. The final checkpoint is reported; do not take its ECE as a guarantee at every step.
- Seeds vary more than the sampling. The local run and the two Colab runs differ in warmup checkpoint, GPU, micro-batch shape and gradient checkpointing as well as seed; the seed spread includes hardware variation. bf16 training is not bit-reproducible: two shared-settings RLVR attempts with the same seed took different trajectories.
- The shared-settings RLVR arm is one stopped run. The three-seed RLVR comparison is the low-lr arm, at 4e-6 against RLCD's 2e-5; RLCD at 4e-6 was not run, and no KL term, entropy bonus or temperature was tried to keep RLVR calibrated, so the contrast is between these two recipes at these settings.
- Plug-in ECE is biased upward and its bootstrap interval inherits the bias; the paired differences, which resample the same rows for both runs, are the ones to read. They cover test-row sampling, not training noise.
- Everything is in-distribution: public classification datasets plus synthetic triage, prompts of at most 512 tokens. Calibration on real tickets, on other domains, or on longer prompts is unmeasured. No out-of-distribution evaluation was run.
-
A
NoulQmust be a yes/no question. Cardinality is capped at 26 options, one letter each. -
Tied embedding. From
decision.json: "Qwen3-0.6B ties its output head to the input embedding, so the vocabulary projection is recoverable from the embedding; the export removes the generation path from the API, it does not make generation physically impossible." - Tokenizer warning. Loading the tokenizer under transformers 4.57 printed "The tokenizer you are loading ... with an incorrect regex pattern ... fix_mistral_regex". The warning was spurious for this tokenizer (it is not a Mistral tokenizer) and transformers 5 no longer prints it; the encodings are the same under both versions and are the ones the model was trained on, checked against the Hub tokenizer on 3,494 real prompts.
Intended use and out-of-scope use
This is a research toy: a demonstration that a proper-scoring-rule reward under bandit feedback keeps a small decision model calibrated where an outcome-only reward does not, trained on public classification data and synthetic tickets. Use it to study calibration, to try the decision API, or as a starting point for your own RLCD run. Do not use it for consequential decisions about people, money, safety or security, and do not read its probabilities as calibrated on any input that does not resemble its training data; the evidence above covers only that data.
Reproduce
The commands for the data build, the warmup, the four arms, the evaluation, the paired comparisons and the export are in the README of github.com/anthony-maio/eve-rlcd ; the Colab notebook there runs the seed jobs on an A100.
Credits
The idea came from TypeSafe's Jev announcement, which I wrote about in Jev: The Language Model That Won't Talk (2026-09-16); TypeSafe has published no method and nothing here claims to reproduce theirs. The reward follows the line of "Rewarding Doubt" (Stangel et al., 2025), RL with a proper-scoring-rule reward on stated confidence. Temperature scaling, reported in the repository for reference only, is Guo et al., "On Calibration of Modern Neural Networks" (2017). The inference pattern of scoring declared options at one position over a shared prefill comes from harshatheg/Qwen-2.5-1B-RLCD . The base model is Qwen/Qwen3-0.6B-Base (Apache-2.0), which these weights inherit.
Citation
@misc{maio2026everlcd,
  author = {Maio, Anthony},
  title = {eve-rlcd: reinforcement learning for calibrated decisions on a small decision model},
  year = {2026},
  howpublished = {\url{https://github.com/anthony-maio/eve-rlcd}}
}
Runs of anthonym21 qwen3-0.6b-rlcd-decision on huggingface.co
1.2K
Total runs
4
24-hour runs
4
3-day runs
4
7-day runs
1.1K
30-day runs
More Information About qwen3-0.6b-rlcd-decision huggingface.co Model
Url of qwen3-0.6b-rlcd-decision
qwen3-0.6b-rlcd-decision huggingface.co Url
Provider of qwen3-0.6b-rlcd-decision huggingface.co
Other API from anthonym21
Total runs:
124
Run Growth:
71
Growth Rate:
57.72%
Total runs:
90
Run Growth:
38
Growth Rate:
42.22%
Total runs:
48
Run Growth:
17
Growth Rate:
32.69%
Total runs:
48
Run Growth:
34
Growth Rate:
66.67%
Total runs:
43
Run Growth:
16
Growth Rate:
37.21%
Total runs:
38
Run Growth:
-20
Growth Rate:
-52.63%
Total runs:
36
Run Growth:
19
Growth Rate:
55.88%
Total runs:
36
Run Growth:
-12
Growth Rate:
-34.29%
Total runs:
32
Run Growth:
18
Growth Rate:
56.25%
Total runs:
29
Run Growth:
-6
Growth Rate:
-18.75%
Total runs:
28
Run Growth:
10
Growth Rate:
35.71%
Total runs:
25
Run Growth:
-2
Growth Rate:
-8.00%
Total runs:
24
Run Growth:
13
Growth Rate:
54.17%
Total runs:
23
Run Growth:
6
Growth Rate:
26.09%
Total runs:
21
Run Growth:
-9
Growth Rate:
-39.13%
Total runs:
18
Run Growth:
11
Growth Rate:
61.11%
Total runs:
16
Run Growth:
-9
Growth Rate:
-60.00%
Total runs:
16
Run Growth:
11
Growth Rate:
68.75%
Total runs:
14
Run Growth:
11
Growth Rate:
73.33%
Total runs:
12
Run Growth:
6
Growth Rate:
54.55%
Total runs:
9
Run Growth:
2
Growth Rate:
22.22%
Total runs:
7
Run Growth:
5
Growth Rate:
71.43%
Total runs:
6
Run Growth:
2
Growth Rate:
33.33%
Total runs:
6
Run Growth:
0
Growth Rate:
0.00%
Total runs:
6
Run Growth:
-20
Growth Rate:
-285.71%
Total runs:
4
Run Growth:
2
Growth Rate:
40.00%
Total runs:
3
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%