
Total runs:
6.2K
Run Growth:
1.1K
Growth Rate:
17.30%
Latent Diffusion
Paper : High-Resolution Image Synthesis with Latent Diffusion Models
Abstract :
By decomposing the image formation process into a sequential application of denoising autoencoders, diffusion models (DMs) achieve state-of-the-art synthesis results on image data and beyond. Additionally, their formulation allows for a guiding mechanism to control the image generation process without retraining. However, since these models typically operate directly in pixel space, optimization of powerful DMs often consumes hundreds of GPU days and inference is expensive due to sequential evaluations. To enable DM training on limited computational resources while retaining their quality and flexibility, we apply them in the latent space of powerful pretrained autoencoders. In contrast to previous work, training diffusion models on such a representation allows for the first time to reach a near-optimal point between complexity reduction and detail preservation, greatly boosting visual fidelity. By introducing cross-attention layers into the model architecture, we turn diffusion models into powerful and flexible generators for general conditioning inputs such as text or bounding boxes and high-resolution synthesis becomes possible in a convolutional manner. Our latent diffusion models (LDMs) achieve a new state of the art for image inpainting and highly competitive performance on various tasks, including unconditional image generation, semantic scene synthesis, and super-resolution, while significantly reducing computational requirements compared to pixel-based DMs. Code is available at this https URL.
from diffusers import DiffusionPipeline

ldm = DiffusionPipeline.from_pretrained("fusing/latent-diffusion-text2im-large")

generator = torch.manual_seed(42)

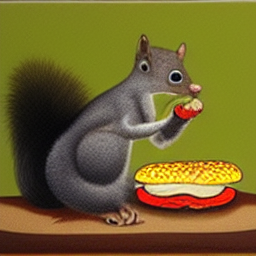
prompt = "A painting of a squirrel eating a burger"
image = ldm([prompt], generator=generator, eta=0.3, guidance_scale=6.0, num_inference_steps=50)

image_processed = image.cpu().permute(0, 2, 3, 1)
image_processed = image_processed  * 255.
image_processed = image_processed.numpy().astype(np.uint8)
image_pil = PIL.Image.fromarray(image_processed[0])

# save image
image_pil.save("test.png")
2."A painting of a squirrel eating a burger"