



Total runs:
34.1K
Run Growth:
27.4K
Growth Rate:
80.45%
bekko-embedding-v1-a8m is an ultra-compact multilingual text embedding model. It has just 8M active parameters — light enough to run comfortably even on low-spec CPUs — yet its retrieval quality is comparable to models with 3–10x more active parameters.
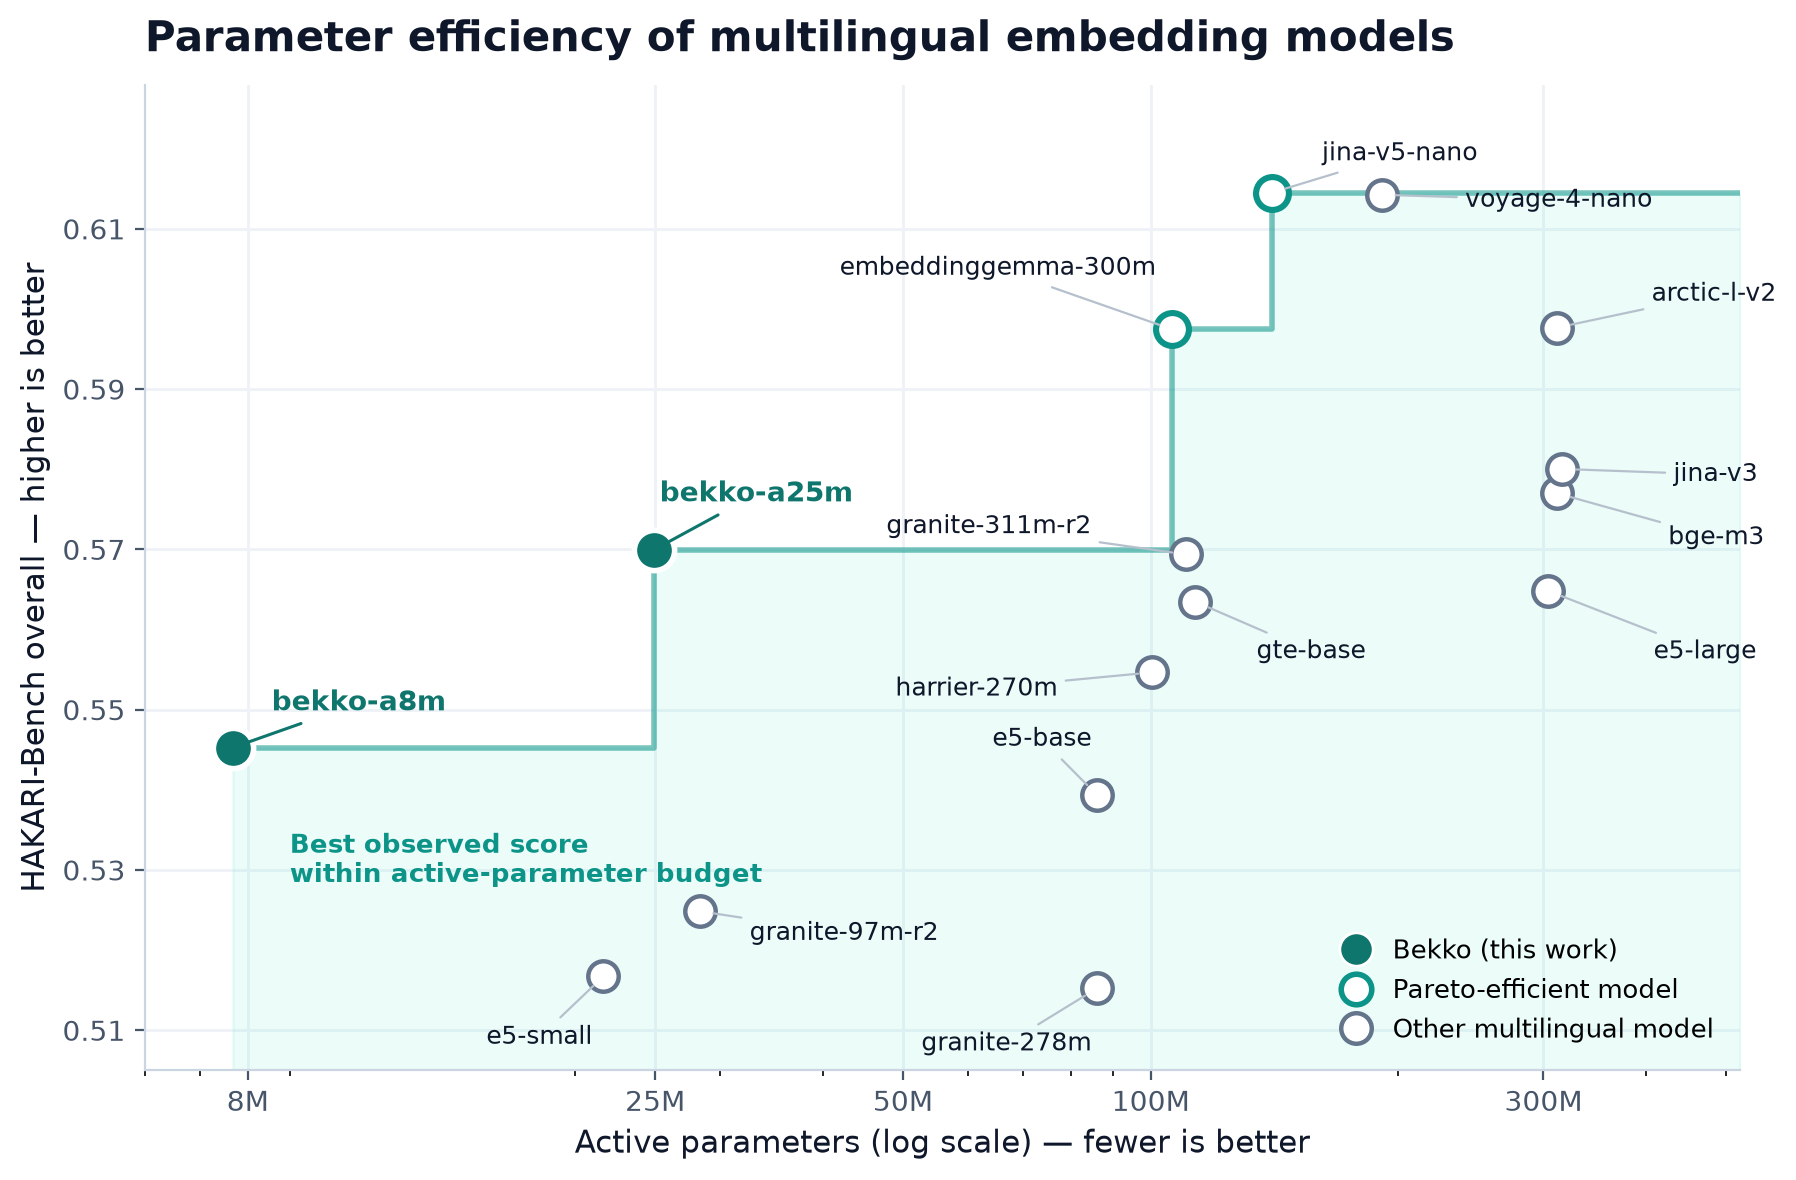
For higher retrieval quality, see the larger bekko-embedding-v1-a25m (25M active parameters).
You can also try bekko right in your browser: the bekko-embedding-web demo runs the model fully client-side with Transformers.js — no server involved.
🚧 WIP — we're writing the technical paper.
| a8m (this model) | a25m | |
|---|---|---|
| Active parameters | 7.7M | 24.9M |
| HAKARI-Bench overall | 0.545 | 0.570 |
| MMTEB Retrieval | 56.2 | 57.5 |
| CPU docs/s (Ryzen 9 7950X, OpenVINO) | 364 | 134 |
| CPU docs/s (Raspberry Pi 5, OpenVINO) | 33 | 10.5 |
| GPU docs/s (RTX 5090, Flash Attention 2) | 5,561 | 4,006 |
Rule of thumb: a8m is the speed pick — the fastest model we measured on every device. If you can spare about 2.7x CPU throughput, a25m buys a solid quality bump.
We recommend Sentence Transformers 5.0+ and Transformers 5.12+:
pip install -U "sentence-transformers>=5.0" "transformers>=5.12"
Queries and documents go through the same
encode()
call — no prefixes or task instructions needed. Pass
normalize_embeddings=True
when you plan to search with cosine similarity or dot product.
from sentence_transformers import SentenceTransformer, util

model = SentenceTransformer(
    "hotchpotch/bekko-embedding-v1-a8m",
    # Optional: pin the attention backend to SDPA for identical behavior
    # across CPU, CUDA, and Apple Silicon.
    # model_kwargs={"attn_implementation": "sdpa"},
)

query = "What are the characteristics of sushi?"
docs = [
    "A warm noodle soup served in broth with sliced toppings.",
    "天ぷらは魚や野菜に衣をつけて揚げた料理です。",  # "Tempura is battered, deep-fried fish and vegetables."
    "Une fine crepe garnie de sucre, de beurre ou de fruits.",
    "A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",
]

query_emb = model.encode(query, normalize_embeddings=True)
doc_emb = model.encode(docs, normalize_embeddings=True)
scores = util.cos_sim(query_emb, doc_emb)[0]

print(scores)
print("best doc:", docs[int(scores.argmax())])
Output (exact scores vary slightly by backend):
tensor([0.3085, 0.2716, 0.2750, 0.4738])
best doc: A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.
Queries and documents don't need to share a language. Continuing with the same
model
, a Japanese query finds the right English document in a mixed English / Spanish corpus:
corpus = [
    "Sushi is a Japanese dish of vinegared rice topped with seafood.",
    "The Eiffel Tower is a wrought-iron lattice tower in Paris, France.",
    "Mount Fuji is the highest mountain in Japan, at 3,776 meters.",
    "Python is a programming language known for its readability.",
    "La Sagrada Família es una basílica de Barcelona diseñada por Antoni Gaudí.",
]
corpus_emb = model.encode(corpus, normalize_embeddings=True)

for query in [
    "日本で一番高い山は?",  # "What is the highest mountain in Japan?"
    "Who designed the famous basilica in Barcelona?",
]:
    query_emb = model.encode(query, normalize_embeddings=True)
    hits = util.semantic_search(query_emb, corpus_emb, top_k=2)[0]
    print(query)
    for hit in hits:
        print(f"  {hit['score']:.3f}  {corpus[hit['corpus_id']]}")
日本で一番高い山は?
  0.609  Mount Fuji is the highest mountain in Japan, at 3,776 meters.
  0.219  Sushi is a Japanese dish of vinegared rice topped with seafood.
Who designed the famous basilica in Barcelona?
  0.489  La Sagrada Família es una basílica de Barcelona diseñada por Antoni Gaudí.
  0.152  The Eiffel Tower is a wrought-iron lattice tower in Paris, France.
That's everything you need for basic use. For more speed — OpenVINO on CPU, Flash Attention on GPU, browser inference, smaller embeddings — see Optimized Inference below.
In the chart above, up and to the left is better: more retrieval quality from fewer active parameters. The step line shows the best observed score within each active-parameter budget, and outlined markers identify Pareto-efficient models. Both bekko models sit in that upper-left region, scoring at or above many models several times their size — which is the whole point of the project.
On the 131-task MMTEB Multilingual v2 suite, a8m scores 56.2 Retrieval and 56.7 Mean(Task) with 7.7M active parameters — a higher Retrieval score than multilingual-e5-small (50.9), multilingual-e5-large (53.7), and BGE-M3 (54.6), all models with 3–40x more active parameters.
Scores are ×100. Retrieval is task-macro nDCG@10, and Mean is the mean across all 131 tasks. Competitor values use the official 2026-06-28 snapshot. Bekko was evaluated over the same task set and aggregation rules.
| Model | Active Params | Dims | Mean | Retrieval | Reranking | BitextMining | STS |
|---|---|---|---|---|---|---|---|
| bekko-embedding-v1-a8m | 7.7M | 384 | 56.7 | 56.2 | 60.6 | 73.1 | 71.6 |
| multilingual-e5-small | 21.6M | 384 | 56.4 | 50.9 | 60.4 | 69.4 | 71.7 |
| bekko-embedding-v1-a25m | 24.9M | 384 | 58.3 | 57.5 | 61.6 | 75.4 | 73.4 |
| granite-embedding-97m-multilingual-r2 | 28.3M | 384 | 51.9 | 60.3 | 59.4 | 44.2 | 65.6 |
| harrier-oss-v1-270m | 100.3M | 640 | 66.6 | 66.4 | 61.9 | 81.5 | 75.4 |
| embeddinggemma-300m | 106.3M | 768 | 61.2 | 62.5 | 63.3 | 64.4 | 74.7 |
| granite-embedding-311m-multilingual-r2 | 110.3M | 768 | 56.0 | 65.2 | 62.0 | 57.9 | 69.0 |
| gte-multilingual-base | 113.3M | 768 | 58.3 | 57.2 | 60.7 | 71.8 | 72.9 |
| multilingual-e5-large | 303.9M | 1024 | 58.6 | 53.7 | 62.9 | 73.8 | 73.3 |
| snowflake-arctic-embed-l-v2.0 | 311.8M | 1024 | 57.0 | 58.4 | 63.7 | 64.1 | 70.1 |
| BGE-M3 | 311.8M | 1024 | 59.6 | 54.6 | 62.8 | 79.1 | 74.1 |
Scores are ×100. a25m is stronger than a8m on 13 of 18 tasks and on the mean. Its main regression is WinoGrande.
| Task | a8m | a25m | mE5-s | G97 | GTE | BGE-M3 |
|---|---|---|---|---|---|---|
| Mean | 56.23 | 57.45 | 50.91 | 60.32 | 57.16 | 54.59 |
| StackOverflowQA | 74.94 | 77.35 | 81.94 | 81.99 | 87.08 | 80.60 |
| TwitterHjerne | 56.56 | 63.59 | 58.18 | 56.71 | 68.92 | 37.82 |
| AILAStatutes | 34.13 | 36.23 | 19.01 | 28.95 | 33.57 | 29.04 |
| ArguAna | 55.57 | 57.69 | 39.09 | 53.09 | 58.28 | 54.04 |
| Hagrid | 98.69 | 98.62 | 98.55 | 98.69 | 98.55 | 98.77 |
| LegalBench Lobbying | 92.01 | 91.40 | 89.47 | 91.36 | 90.55 | 90.34 |
| LEMBPasskey | 85.00 | 85.00 | 38.25 | 82.75 | 55.50 | 59.00 |
| SCIDOCS | 19.43 | 20.11 | 13.90 | 20.36 | 18.26 | 16.31 |
| SpartQA | 11.95 | 9.18 | 5.43 | 67.34 | 5.29 | 7.49 |
| TempReason L1 | 1.06 | 1.40 | 0.80 | 5.15 | 1.08 | 0.99 |
| TRECCOVID | 53.19 | 56.46 | 72.29 | 66.27 | 57.67 | 54.72 |
| WinoGrande | 59.24 | 44.21 | 37.46 | 56.61 | 42.21 | 41.72 |
| Belebele | 69.72 | 74.56 | 66.29 | 52.86 | 89.20 | 78.16 |
| MLQA | 67.50 | 71.06 | 63.85 | 60.54 | 72.19 | 74.81 |
| StatCan Dialogue | 21.73 | 25.96 | 10.33 | 53.65 | 21.74 | 21.86 |
| Wikipedia Multi. | 86.01 | 87.89 | 88.66 | 83.24 | 84.00 | 89.87 |
| COVID | 72.01 | 73.69 | 72.82 | 70.10 | 80.61 | 77.51 |
| MIRACL HN | 53.50 | 59.77 | 60.09 | 56.09 | 64.17 | 69.59 |
Abbreviations: mE5-s = multilingual-e5-small, G97 = Granite Embedding 97M Multilingual R2, GTE = gte-multilingual-base, MIRACL HN = MIRACL Retrieval Hard Negatives.
The following retrieval scores use multilingual Nano benchmarks measured with HAKARI-Bench . Higher is better.
What each column means:
| Model | Active Params | Overall | MNanoBEIR | NanoMMTEB-v2 | NanoRTEB | NanoLongEmbed | NanoCoIR |
|---|---|---|---|---|---|---|---|
| bekko-embedding-v1-a8m | 7.7M | 0.545 | 0.527 | 0.503 | 0.550 | 0.682 | 0.747 |
| bekko-embedding-v1-a25m | 24.9M | 0.570 | 0.549 | 0.494 | 0.594 | 0.706 | 0.786 |
| multilingual-e5-small | 21.6M | 0.517 | 0.512 | 0.445 | 0.471 | 0.501 | 0.692 |
| granite-97m-multilingual-r2 | 28.3M | 0.525 | 0.505 | 0.531 | 0.567 | 0.659 | 0.780 |
| harrier-oss-v1-270m | 100.3M | 0.555 | 0.523 | 0.522 | 0.550 | 0.617 | 0.789 |
| granite-311m-multilingual-r2 | 110.3M | 0.569 | 0.543 | 0.577 | 0.606 | 0.695 | 0.814 |
| gte-multilingual-base | 113.3M | 0.563 | 0.527 | 0.486 | 0.558 | 0.669 | 0.753 |
| multilingual-e5-large | 303.9M | 0.565 | 0.560 | 0.484 | 0.556 | 0.505 | 0.747 |
| bge-m3 | 311.8M | 0.577 | 0.557 | 0.485 | 0.536 | 0.653 | 0.692 |
Scores are nDCG@10. a25m scores higher than a8m on 14 of 18 tasks. Its slightly lower simple mean is mainly due to LEMBPasskey.
| Task | a8m | a25m | mE5-s | G97 | GTE | BGE-M3 |
|---|---|---|---|---|---|---|
| Mean | 0.503 | 0.494 | 0.445 | 0.531 | 0.486 | 0.485 |
| AILAStatutes | 0.338 | 0.368 | 0.195 | 0.291 | 0.336 | 0.292 |
| ArguAna | 0.393 | 0.396 | 0.265 | 0.359 | 0.396 | 0.381 |
| Belebele | 0.098 | 0.097 | 0.112 | 0.119 | 0.108 | 0.151 |
| COVID | 0.683 | 0.726 | 0.708 | 0.680 | 0.787 | 0.746 |
| Hagrid | 0.988 | 0.989 | 0.988 | 0.989 | 0.989 | 0.991 |
| LegalBench Lobbying | 0.918 | 0.918 | 0.895 | 0.921 | 0.903 | 0.909 |
| LEMBPasskey | 0.876 | 0.552 | 0.380 | 0.702 | 0.417 | 0.491 |
| MIRACL | 0.743 | 0.785 | 0.791 | 0.779 | 0.820 | 0.836 |
| MLQA | 0.139 | 0.172 | 0.089 | 0.129 | 0.144 | 0.159 |
| SCIDOCS | 0.255 | 0.266 | 0.195 | 0.273 | 0.256 | 0.216 |
| SpartQA | 0.143 | 0.102 | 0.069 | 0.656 | 0.049 | 0.074 |
| StackOverflowQA | 0.823 | 0.839 | 0.880 | 0.891 | 0.919 | 0.871 |
| StatCan Dialogue | 0.112 | 0.149 | 0.074 | 0.187 | 0.122 | 0.137 |
| TempReason L1 | 0.013 | 0.023 | 0.019 | 0.121 | 0.013 | 0.009 |
| TRECCOVID | 0.397 | 0.407 | 0.401 | 0.394 | 0.402 | 0.366 |
| TwitterHjerne | 0.564 | 0.634 | 0.584 | 0.571 | 0.698 | 0.717 |
| Wikipedia Multi. | 0.954 | 0.972 | 0.995 | 0.941 | 0.966 | 0.978 |
| WinoGrande | 0.607 | 0.490 | 0.377 | 0.564 | 0.430 | 0.398 |
Model abbreviations match the Full MMTEB Retrieval table above.
| Item | Value |
|---|---|
| Model type | Sentence Transformer dense embedding model |
| Architecture | mmBERT (ModernBERT-style) encoder, 4 layers, hidden size 384 |
| Base model | hotchpotch/bekko-embedding-v1-a8m-pt |
| Backbone | hotchpotch/mmBERT-L4H384-pruned , pruned from mmBERT-small |
| Active parameters | 7,671,168 |
| Total parameters | 105,975,168 |
| Embedding dimension | 384 |
| Supported truncate dimensions | 256, 128, 64 |
| Max sequence length | 8192 tokens |
| Pooling | Mean pooling |
| Similarity | Cosine similarity |
The "a8m" in the name counts active parameters: the attention and feed-forward weights that run on every token, which is where nearly all of a transformer encoder's inference cost lives. The token embedding table dominates the total parameter count, but at inference it's only a lookup.
That's why a model can be large on disk and still fast. bekko-embedding-v1-a8m totals ~106M parameters, but the bulk of that is the multilingual embedding table — only 8M parameters do real work per token, so latency behaves like an 8M model. The default OpenVINO / ONNX artifacts also store that static table as row-wise
int8
, cutting the main artifact from ~404 MiB
fp32
to about 124 MiB.
a8m was the fastest model we measured in every environment — x86 CPU, Raspberry Pi 5, Apple Silicon, and NVIDIA GPU. On a Ryzen 9 7950X with OpenVINO it encodes 364 docs/s (1.6x multilingual-e5-small, 17x multilingual-e5-large), and 5,561 docs/s on an RTX 5090 with Flash Attention 2.
Document throughput uses Natural Questions text, batch size 64 and max length 512 for CPU/MPS. CUDA uses NQ 100k,
fp16
, and Flash Attention 2. All throughput values in the table are docs/s.
| Model | AP | x86 | Pi 5 | M4 | RTX |
|---|---|---|---|---|---|
| bekko-a8m | 7.7M | 364 | 33 | 592 | 5,561 |
| mE5-small | 21.6M | 226 | 19 | 370 | 3,746 |
| bekko-a25m | 24.9M | 134 | 10.5 | 351 | 4,006 |
| granite-97m-r2 | 28.3M | 125 | 10.0 | 286 | 3,917 |
| EmbGemma-300m | 106.3M | — | — | 97 | 1,678 |
| granite-311m-r2 | 110.3M | 38 | 2.9 | 106 | 2,159 |
| mE5-large | 303.9M | 21 | 1.5 | 67 | 1,318 |
| BGE-M3 | 311.8M | — | — | 78 | 1,324 |
Abbreviations: mE5 = multilingual-e5, granite-97m/311m-r2 = Granite Embedding Multilingual R2, EmbGemma = EmbeddingGemma. x86 = Ryzen 9 7950X + OpenVINO, Pi 5 = Raspberry Pi 5 + OpenVINO, M4 = Apple M4 Max + MPS, RTX = RTX 5090 + CUDA/Flash Attention 2. AP means active parameters.
Throughput depends on input lengths, batch size, runtime, and hardware. OpenVINO is recommended for CPU, MPS for Apple Silicon, and Flash Attention 2 for supported NVIDIA GPUs.
The short version: on CPU, use the OpenVINO backend — it gave us 2.82x PyTorch throughput on x86 and 1.69x on a Raspberry Pi 5. In the browser, or wherever you need ONNX Runtime, use the default ONNX artifact. Both compress only the static token embedding table (~404 MiB
fp32
down to about 124 MiB) and stayed within cosine similarity 0.9994 of PyTorch in release verification. The transformer-weight
qint8
/
quint8
files are separate experiments, not defaults.
SDPA works everywhere and is the safe default. If your GPU supports Flash Attention 2, it's worth enabling: on our RTX 5090 it was about 18% faster than SDPA for a8m (24% for a25m).
import torch
from sentence_transformers import SentenceTransformer, util

model = SentenceTransformer(
    "hotchpotch/bekko-embedding-v1-a8m",
    device="cuda",
    model_kwargs={
        "attn_implementation": "flash_attention_2",
        "dtype": torch.float16,
    },
)

query = "What are the characteristics of sushi?"
docs = [
    "A warm noodle soup served in broth with sliced toppings.",
    "天ぷらは魚や野菜に衣をつけて揚げた料理です。",  # "Tempura is battered, deep-fried fish and vegetables."
    "Une fine crepe garnie de sucre, de beurre ou de fruits.",
    "A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",
]

scores = util.cos_sim(
    model.encode(query, normalize_embeddings=True),
    model.encode(docs, normalize_embeddings=True),
)[0]
print(scores)
If Flash Attention 2 is unavailable, use
model_kwargs={"attn_implementation": "sdpa"}
.
from sentence_transformers import SentenceTransformer, util

model = SentenceTransformer(
    "hotchpotch/bekko-embedding-v1-a8m",
    device="mps",
    model_kwargs={"attn_implementation": "sdpa"},
)

query = "What are the characteristics of sushi?"
docs = [
    "A warm noodle soup served in broth with sliced toppings.",
    "天ぷらは魚や野菜に衣をつけて揚げた料理です。",  # "Tempura is battered, deep-fried fish and vegetables."
    "Une fine crepe garnie de sucre, de beurre ou de fruits.",
    "A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",
]

scores = util.cos_sim(
    model.encode(query, normalize_embeddings=True),
    model.encode(docs, normalize_embeddings=True),
)[0]
print(scores)
The default IR (
openvino/openvino_model.xml
+
.bin
) runs on Intel, AMD, and Arm CPUs, Raspberry Pi included. Only the static token embedding table is stored as
int8
— the transformer layers stay
fp32
, so quality is essentially unchanged (cosine similarity ≥ 0.9994 to PyTorch in our release checks).
# As of 2026-07-28, Transformers 4.x must be specified so that pip resolves
# a compatible OpenVINO dependency stack.
pip install -U \
  "sentence-transformers[openvino]>=5.0" \
  "transformers>=4.57,<5"
from sentence_transformers import SentenceTransformer, util

model = SentenceTransformer(
    "hotchpotch/bekko-embedding-v1-a8m",
    backend="openvino",
    device="cpu",
    model_kwargs={"file_name": "openvino/openvino_model.xml", "device": "CPU"},
)

query = "What are the characteristics of sushi?"
docs = [
    "A warm noodle soup served in broth with sliced toppings.",
    "天ぷらは魚や野菜に衣をつけて揚げた料理です。",  # "Tempura is battered, deep-fried fish and vegetables."
    "Une fine crepe garnie de sucre, de beurre ou de fruits.",
    "A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",
]

scores = util.cos_sim(
    model.encode(query, normalize_embeddings=True),
    model.encode(docs, normalize_embeddings=True),
)[0]
print(scores)
The default ONNX artifact (
onnx/model.onnx
) keeps the tokenizer and full vocabulary unchanged and stores only the static token embedding table as
int8
. Use it with Transformers.js in the browser, or with ONNX Runtime. If plain CPU throughput is what you're after, OpenVINO above is faster. For a complete client-side example, see the
bekko-embedding-web
Space.
npm install @huggingface/transformers
import { pipeline } from "@huggingface/transformers";

// Browser: use WebGPU when available, otherwise fall back to WASM.
// Node.js: replace this line with `const device = "cpu";`.
const device = navigator.gpu ? "webgpu" : "wasm";

const extractor = await pipeline(
  "feature-extraction",
  "hotchpotch/bekko-embedding-v1-a8m",
  {
    device,
    // Transformers.js maps dtype="fp32" to onnx/model.onnx.
    // In this repo, that file is the compact static-embedding-int8 ONNX model.
    dtype: "fp32",
  },
);

const queryEmbedding = await extractor("What are the characteristics of sushi?", {
  pooling: "mean",
  normalize: true,
});

const documentEmbedding = await extractor(
  "A Japanese dish made with vinegared rice and seafood.",
  { pooling: "mean", normalize: true },
);

console.log(queryEmbedding.tolist()[0].slice(0, 8));
console.log(documentEmbedding.tolist()[0].slice(0, 8));
console.log(queryEmbedding.dims); // [1, 384]
pip install -U "sentence-transformers[onnx]>=5.0"
from sentence_transformers import SentenceTransformer, util

model = SentenceTransformer(
    "hotchpotch/bekko-embedding-v1-a8m",
    backend="onnx",
    device="cpu",
    model_kwargs={"file_name": "onnx/model.onnx", "provider": "CPUExecutionProvider"},
)

query = "What are the characteristics of sushi?"
docs = [
    "A warm noodle soup served in broth with sliced toppings.",
    "天ぷらは魚や野菜に衣をつけて揚げた料理です。",  # "Tempura is battered, deep-fried fish and vegetables."
    "Une fine crepe garnie de sucre, de beurre ou de fruits.",
    "A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",
]
print(util.cos_sim(model.encode(query, normalize_embeddings=True), model.encode(docs, normalize_embeddings=True))[0])
These models are trained with Matryoshka representation learning, so you can shrink the 384-dim embeddings to 256, 128, or 64 dimensions by passing
truncate_dim
. Smaller dimensions reduce index size and speed up similarity search, at a small cost in retrieval quality (see
Truncation and Quantization
).
from sentence_transformers import SentenceTransformer, util

# Full embedding is 384-dim; 256 / 128 / 64 are supported.
model = SentenceTransformer(
    "hotchpotch/bekko-embedding-v1-a8m",
    truncate_dim=256,
    model_kwargs={"attn_implementation": "sdpa"},
)

query = "What are the characteristics of sushi?"
docs = [
    "A warm noodle soup served in broth with sliced toppings.",
    "天ぷらは魚や野菜に衣をつけて揚げた料理です。",  # "Tempura is battered, deep-fried fish and vegetables."
    "Une fine crepe garnie de sucre, de beurre ou de fruits.",
    "A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",
]
emb = model.encode(query, normalize_embeddings=True)
print("embedding dim:", emb.shape[-1])
print(util.cos_sim(emb, model.encode(docs, normalize_embeddings=True))[0])
Not the same as the default artifact above — this one quantizes the transformer weights too. We keep it for experimentation only: on models this small,
qint8
tends to hurt retrieval quality without reliably improving latency.
from sentence_transformers import SentenceTransformer, util

model = SentenceTransformer(
    "hotchpotch/bekko-embedding-v1-a8m",
    backend="openvino",
    device="cpu",
    model_kwargs={"file_name": "openvino/openvino_model_qint8_not_recommended.xml", "device": "CPU"},
)

query = "What are the characteristics of sushi?"
docs = [
    "A warm noodle soup served in broth with sliced toppings.",
    "天ぷらは魚や野菜に衣をつけて揚げた料理です。",  # "Tempura is battered, deep-fried fish and vegetables."
    "Une fine crepe garnie de sucre, de beurre ou de fruits.",
    "A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",
]
print(util.cos_sim(model.encode(query, normalize_embeddings=True), model.encode(docs, normalize_embeddings=True))[0])
Same caveat as OpenVINO
qint8
: these files quantize the transformer weights and are platform-specific experiments. On models this small they can noticeably degrade retrieval quality, so measure on your target hardware before adopting them.
pip install -U "sentence-transformers[onnx]>=5.0"
from sentence_transformers import SentenceTransformer, util

model = SentenceTransformer(
    "hotchpotch/bekko-embedding-v1-a8m",
    backend="onnx",
    device="cpu",
    model_kwargs={
        "file_name": "onnx/model_qint8_avx512_not_recommended.onnx",
        "provider": "CPUExecutionProvider",
    },
)

query = "What are the characteristics of sushi?"
docs = [
    "A warm noodle soup served in broth with sliced toppings.",
    "天ぷらは魚や野菜に衣をつけて揚げた料理です。",  # "Tempura is battered, deep-fried fish and vegetables."
    "Une fine crepe garnie de sucre, de beurre ou de fruits.",
    "A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",
]
print(util.cos_sim(model.encode(query, normalize_embeddings=True), model.encode(docs, normalize_embeddings=True))[0])
Beyond the Sentence Transformers backends above, you can also serve or run the model with:
Text Embeddings Inference (TEI) is Hugging Face's Rust-based serving stack, with official Docker images, dynamic batching, and Prometheus metrics built in.
Before deploying, confirm your TEI version supports this model's encoder architecture, and pick the image tag that matches your target — a CPU image, or a GPU image for your specific architecture. See the TEI image list for current tags.
model=hotchpotch/bekko-embedding-v1-a8m
volume=$PWD/tei-data
# Replace <tag> with the current TEI image for your hardware (CPU, or your GPU arch).
# Add `--gpus all` when using a GPU image.
docker run -p 8080:80 -v "$volume:/data" --pull always \
  ghcr.io/huggingface/text-embeddings-inference:<tag> \
  --model-id "$model"
import requests
import numpy as np

query = "What are the characteristics of sushi?"
docs = [
    "A warm noodle soup served in broth with sliced toppings.",
    "天ぷらは魚や野菜に衣をつけて揚げた料理です。",  # "Tempura is battered, deep-fried fish and vegetables."
    "Une fine crepe garnie de sucre, de beurre ou de fruits.",
    "A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",
]

q = np.array(requests.post("http://127.0.0.1:8080/embed", json={"inputs": [query]}).json()[0])
d = np.array(requests.post("http://127.0.0.1:8080/embed", json={"inputs": docs}).json())
q = q / np.linalg.norm(q)
d = d / np.linalg.norm(d, axis=1, keepdims=True)
print(d @ q)
Apply mean pooling with pure Transformers.
import torch
import torch.nn.functional as F
from transformers import AutoModel, AutoTokenizer

model_id = "hotchpotch/bekko-embedding-v1-a8m"
tokenizer = AutoTokenizer.from_pretrained(model_id)
model = AutoModel.from_pretrained(model_id, attn_implementation="sdpa").eval()

def embed(texts):
    batch = tokenizer(texts, padding=True, truncation=True, return_tensors="pt")
    with torch.no_grad():
        out = model(**batch).last_hidden_state
    mask = batch["attention_mask"].unsqueeze(-1)
    pooled = (out * mask).sum(dim=1) / mask.sum(dim=1).clamp(min=1)
    return F.normalize(pooled, p=2, dim=1)

query = "What are the characteristics of sushi?"
docs = [
    "A warm noodle soup served in broth with sliced toppings.",
    "天ぷらは魚や野菜に衣をつけて揚げた料理です。",  # "Tempura is battered, deep-fried fish and vegetables."
    "Une fine crepe garnie de sucre, de beurre ou de fruits.",
    "A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",
]

scores = embed(docs) @ embed([query]).T
print(scores.squeeze(-1))
How much quality do you trade for a smaller index? For
bekko-embedding-v1-a8m
: very little at 256 dimensions (-1.8%), progressively more below that. If you quantize the output vectors to
int8
or binary, add a rescoring step — it recovers nearly all of the loss.
| Setting | Dim | Encoding | Rescore | HAKARI overall | Delta vs 384-dim float | Recommended use |
|---|---|---|---|---|---|---|
| Full quality | 384 | float | No | 0.545 | - | Default choice |
| Smaller index | 256 | float | No | 0.536 | -1.76% | Good size/quality tradeoff |
| Compact index | 128 | float | No | 0.507 | -7.05% | Memory-constrained indexes |
| Very compact index | 64 | float | No | 0.450 | -17.51% | Not for quality-sensitive retrieval |
| INT8 search | 384 | int8 | No | 0.515 | -5.48% | Benchmark before using |
| INT8 search + rescore | 384 | int8 | Yes | 0.545 | -0.04% | Best quantized option |
| Binary search | 384 | binary | No | 0.475 | -12.93% | Not recommended by default |
| Binary search + rescore | 384 | binary | Yes | 0.543 | -0.44% | Strong compression when rescoring is available |
query:
or
passage:
?
— No. bekko is trained without prefixes, so you encode raw text for both queries and documents. If you come from the multilingual-e5 family, just drop the prefixes.
openvino/openvino_model.xml
. Browser / ONNX Runtime:
onnx/model.onnx
. Files named
_not_default
/
_not_recommended
are comparison artifacts, not deployment choices.
truncate_dim=256
(or 128 / 64). See
Truncation and Quantization
for the quality cost.
qint8
artifacts are experimental and can lose retrieval quality or behave differently across CPU architectures. The default ONNX/OpenVINO artifacts only compress the static token embedding table and are the recommended deployment files.
bekko (/ˈbek.koː/) is a coined name that joins two pieces of Japanese tradition:
The name pairs the protective spirit of the red ox with the quiet beauty of this classic amber tone.
The technical paper is in preparation. A BibTeX entry will be added here once it's published.
Both datasets built for training bekko-embedding are public:
MIT License.
Yuichi Tateno @hotchpotch