



Sponsored by
APIMart
Linaqruf / animagine-xl
Model's Last Updated: August 21 2023
text-to-image
Introduction of animagine-xl
Model Details of animagine-xl
Animagine XL
|
|
Overview
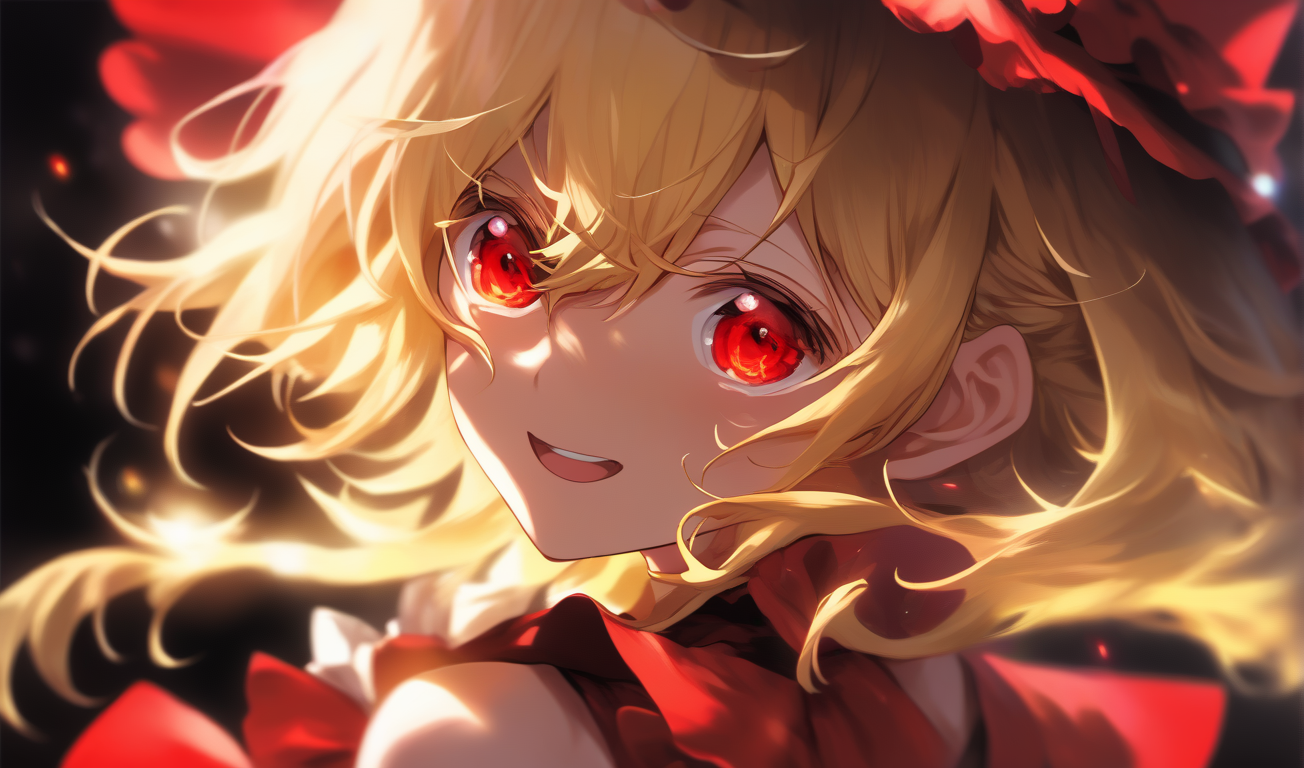
Animagine XL
is a high-resolution, latent text-to-image diffusion model. The model has been fine-tuned using a learning rate of
4e-7
over 27000 global steps with a batch size of 16 on a curated dataset of superior-quality anime-style images. This model is derived from Stable Diffusion XL 1.0.
-
Use it with the
Stable Diffusion Webui -
Use it with 🧨
diffusers -
Use it with the
ComfyUI(recommended)
Like other anime-style Stable Diffusion models, it also supports Danbooru tags to generate images.
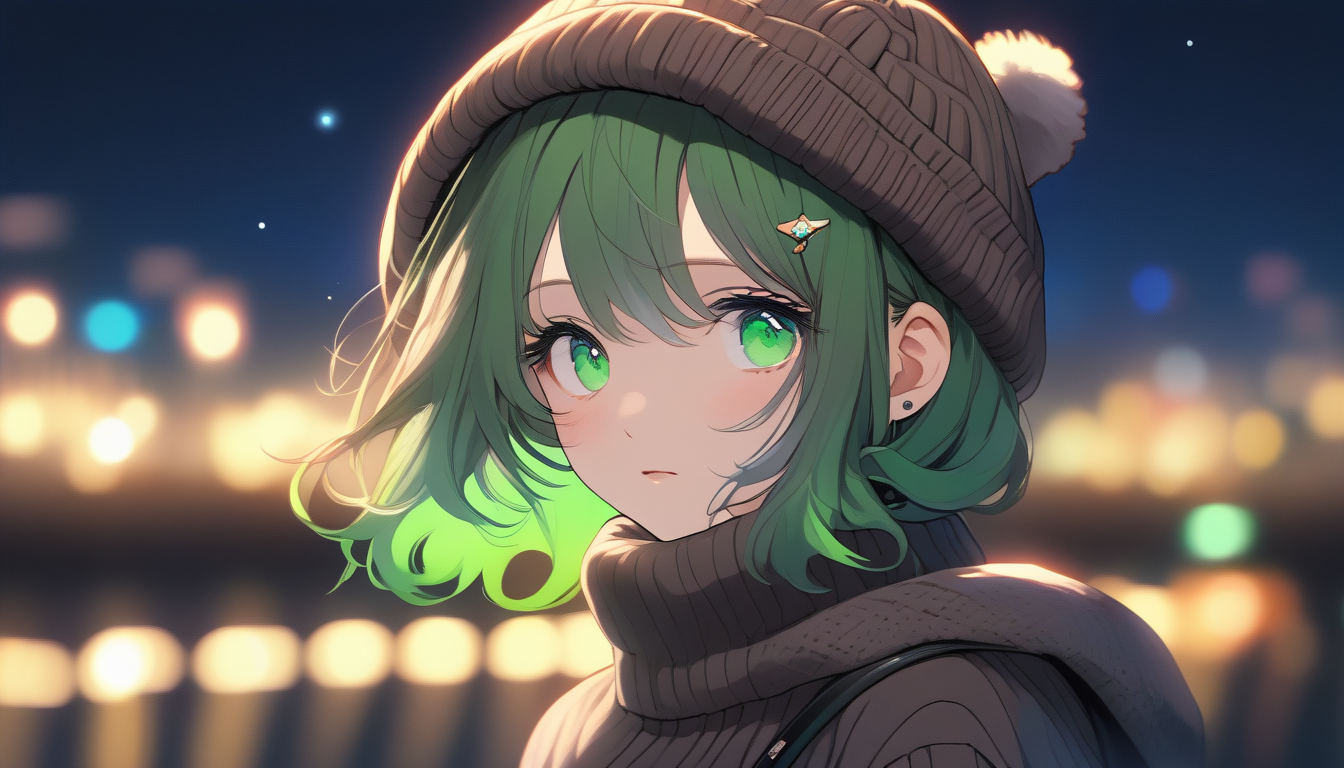
e.g. face focus, cute, masterpiece, best quality, 1girl, green hair, sweater, looking at viewer, upper body, beanie, outdoors, night, turtleneck
Features
- High-Resolution Images: The model trained with 1024x1024 resolution. The model is trained using NovelAI Aspect Ratio Bucketing Tool so that it can be trained at non-square resolutions.
- Anime-styled Generation: Based on given text prompts, the model can create high quality anime-styled images.
- Fine-Tuned Diffusion Process: The model utilizes a fine-tuned diffusion process to ensure high quality and unique image output.
Model Details
- Developed by: Linaqruf
- Model type: Diffusion-based text-to-image generative model
- Model Description: This is a model that can be used to generate and modify high quality anime-themed images based on text prompts.
- License: CreativeML Open RAIL++-M License
- Finetuned from model: Stable Diffusion XL 1.0
How to Use:
-
Download
Animagine XLhere , the model is in.safetensorsformat. - You need to use Danbooru-style tag as prompt instead of natural language, otherwise you will get realistic result instead of anime
- You can use any generic negative prompt or use the following suggested negative prompt to guide the model towards high aesthetic generationse:
lowres, bad anatomy, bad hands, text, error, missing fingers, extra digit, fewer digits, cropped, worst quality, low quality, normal quality, jpeg artifacts, signature, watermark, username, blurry
- And, the following should also be prepended to prompts to get high aesthetic results:
masterpiece, best quality
- Use this cheat sheet to find the best resolution:
768 x 1344: Vertical (9:16)
915 x 1144: Portrait (4:5)
1024 x 1024: Square (1:1)
1182 x 886: Photo (4:3)
1254 x 836: Landscape (3:2)
1365 x 768: Widescreen (16:9)
1564 x 670: Cinematic (21:9)
Gradio & Colab
We also support a
Gradio
Web UI and Colab with Diffusers to run
Animagine XL
:

🧨 Diffusers
Make sure to upgrade diffusers to >= 0.18.2:
pip install diffusers --upgrade
In addition make sure to install
transformers
,
safetensors
,
accelerate
as well as the invisible watermark:
pip install invisible_watermark transformers accelerate safetensors
Running the pipeline (if you don't swap the scheduler it will run with the default EulerDiscreteScheduler in this example we are swapping it to EulerAncestralDiscreteScheduler :
import torch
from torch import autocast
from diffusers import StableDiffusionXLPipeline, EulerAncestralDiscreteScheduler

model = "Linaqruf/animagine-xl"

pipe = StableDiffusionXLPipeline.from_pretrained(
    model,
    torch_dtype=torch.float16,
    use_safetensors=True,
    variant="fp16"
    )

pipe.scheduler = EulerAncestralDiscreteScheduler.from_config(pipe.scheduler.config)
pipe.to('cuda')

prompt = "face focus, cute, masterpiece, best quality, 1girl, green hair, sweater, looking at viewer, upper body, beanie, outdoors, night, turtleneck"
negative_prompt = "lowres, bad anatomy, bad hands, text, error, missing fingers, extra digit, fewer digits, cropped, worst quality, low quality, normal quality, jpeg artifacts, signature, watermark, username, blurry"

image = pipe(
    prompt,
    negative_prompt=negative_prompt,
    width=1024,
    height=1024,
    guidance_scale=12,
    target_size=(1024,1024),
    original_size=(4096,4096),
    num_inference_steps=50
    ).images[0]

image.save("anime_girl.png")
Limitation
This model inherit Stable Diffusion XL 1.0 limitation
Runs of Linaqruf animagine-xl on huggingface.co
981
Total runs
22
24-hour runs
34
3-day runs
13
7-day runs
451
30-day runs
More Information About animagine-xl huggingface.co Model
Url of animagine-xl
animagine-xl huggingface.co Url
Provider of animagine-xl huggingface.co
Other API from Linaqruf
Total runs:
4.8K
Run Growth:
120
Growth Rate:
2.48%
Total runs:
4.4K
Run Growth:
-136
Growth Rate:
-3.18%
Total runs:
1.4K
Run Growth:
-274
Growth Rate:
-19.24%
Total runs:
730
Run Growth:
240
Growth Rate:
32.88%
Total runs:
315
Run Growth:
-58
Growth Rate:
-18.41%
Total runs:
257
Run Growth:
0
Growth Rate:
0.00%
Total runs:
217
Run Growth:
22
Growth Rate:
10.14%
Total runs:
177
Run Growth:
81
Growth Rate:
45.76%
Total runs:
87
Run Growth:
-54
Growth Rate:
-62.07%
Total runs:
44
Run Growth:
-45
Growth Rate:
-102.27%
Total runs:
10
Run Growth:
4
Growth Rate:
40.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%