
lucataco / ai-toolkit

Ostris AI-Toolkit for Flux LoRA Training (DEPRECATED. Please use: ostris/flux-dev-lora-trainer)

replicate.com
Total runs: 55.5K
24-hour runs: 0
7-day runs: 0
30-day runs: 0
Github
Model's Last Updated: August 18 2024

Introduction of ai-toolkit

Model Details of ai-toolkit

Readme

About

An MVP Cog implementation of ostris/ai-toolkit

(Training currently only works with FLUX.1-dev)

How to use

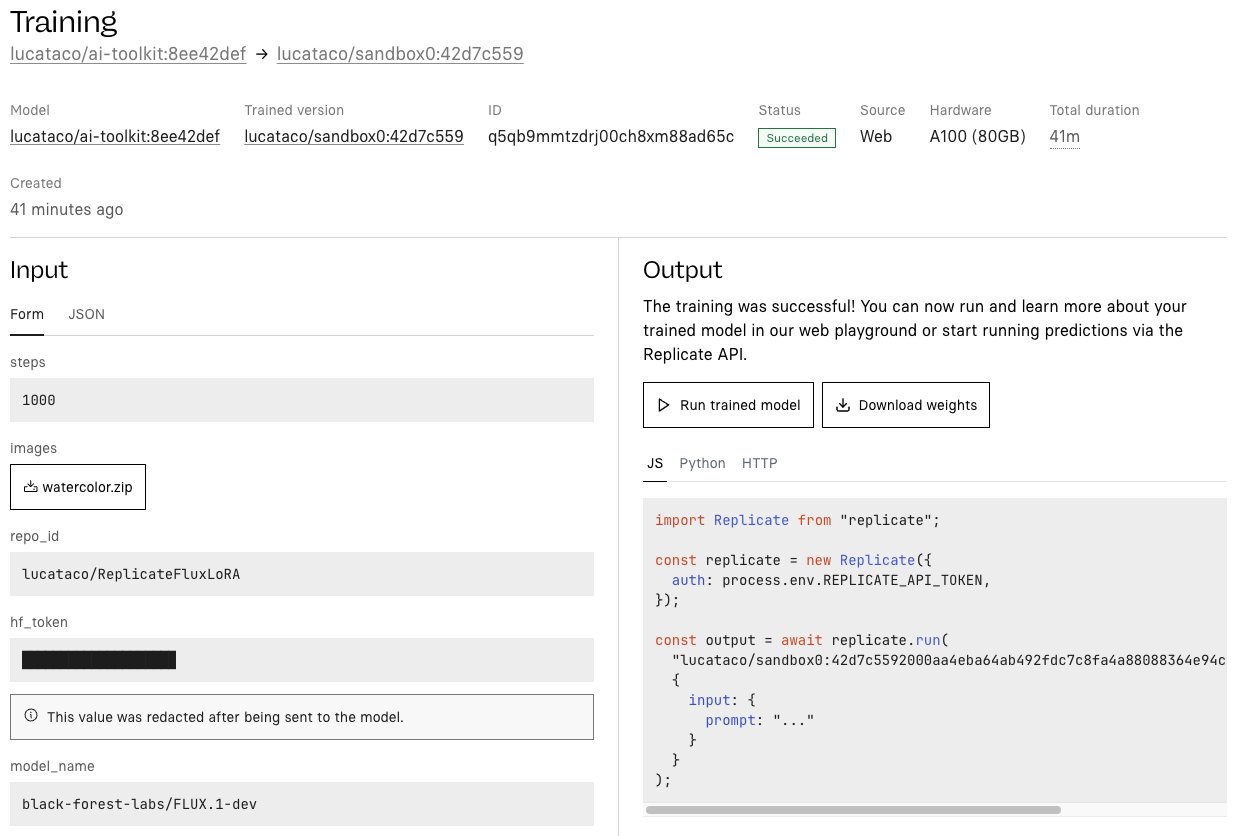
In the TRAIN tab (between README and VERSIONS) you’ll see the parameters that you can select to train a LoRA

For destination select/create an empty Replicate model location to store your LoRAs. (Ex: lucataco/flux-loras)

For images upload your zip/tar file of images for training. File names must be their captions, ex: a_bird_in_the_style_of_TOK.png, etc

For model_name use “black-forest-labs/FLUX.1-dev”

For hf_token use your Huggingface token to access the Flux-Dev weights for training. Make sure the Access Token has the right permissions: “Read access to public gated repos you can access”

For steps select a value from 500-4000

The other steps are optional

Example Training run:

Below is an example training run to create a style LoRA, trained on 16 watercolor images for 1000 steps: training run
How to test your LoRA

Once you have an Output.zip file you can download and extract the safetensors file, and upload it to a huggingface space (ex: lucataco/flux-dev-lora ). If you added a model name for the Train parameter repo_id at the bottom, then this should be done for you automatically

With your LoRA in a huggingface model under your repo_id ( lucataco/flux-dev-lora ) go to the LoRA Explorer model and try it out. In this example, I trained a watercolor style LoRA, so to activate the LoRA I would use the prompt: “a boat in the style of TOK”

License

All Flux-Dev LoRAs have the same license as the original base mode for FLUX.1-dev

If you choose the option to auto-upload your trained LoRA to Huggingface, this License will be added for you
Pricing of ai-toolkit replicate.com

Run time and cost

This model runs on Nvidia A100 (80GB) GPU hardware . We don't yet have enough runs of this model to provide performance information.

Runs of lucataco ai-toolkit on replicate.com

55.5K
Total runs
0
24-hour runs
0
3-day runs
0
7-day runs
0
30-day runs

More Information About ai-toolkit replicate.com Model

ai-toolkit replicate.com

ai-toolkit replicate.com is an AI model on replicate.com that provides ai-toolkit's model effect (Ostris AI-Toolkit for Flux LoRA Training (DEPRECATED. Please use: ostris/flux-dev-lora-trainer)), which can be used instantly with this lucataco ai-toolkit model. replicate.com supports a free trial of the ai-toolkit model, and also provides paid use of the ai-toolkit. Support call ai-toolkit model through api, including Node.js, Python, http.

lucataco ai-toolkit online free

ai-toolkit replicate.com is an online trial and call api platform, which integrates ai-toolkit's modeling effects, including api services, and provides a free online trial of ai-toolkit, you can try ai-toolkit online for free by clicking the link below.

lucataco ai-toolkit online free url in replicate.com:

https://replicate.com/lucataco/ai-toolkit

ai-toolkit install

ai-toolkit is an open source model from GitHub that offers a free installation service, and any user can find ai-toolkit on GitHub to install. At the same time, replicate.com provides the effect of ai-toolkit install, users can directly use ai-toolkit installed effect in replicate.com for debugging and trial. It also supports api for free installation.

ai-toolkit install url in replicate.com:

https://replicate.com/lucataco/ai-toolkit

ai-toolkit install url in github:

https://github.com/lucataco/cog-ai-toolkit

Url of ai-toolkit

Provider of ai-toolkit replicate.com

Other API from lucataco

replicate

Remove background from an image

Total runs: 6.1M
Run Growth: 0
Growth Rate: 0.00%
Updated:September 15 2023
replicate

Falcons.ai Fine-Tuned Vision Transformer (ViT) for NSFW Image Classification

Total runs: 4.5M
Run Growth: 0
Growth Rate: 0.00%
Updated:November 21 2023
replicate

Implementation of Realistic Vision v5.1 with VAE

Total runs: 4.1M
Run Growth: 0
Growth Rate: 0.00%
Updated:August 15 2023
replicate

FLUX.1-Dev LoRA Explorer (DEPRECATED Please use: black-forest-labs/flux-dev-lora)

Total runs: 3.3M
Run Growth: 0
Growth Rate: 0.00%
Updated:Oktober 06 2024
replicate

SDXL ControlNet - Canny

Total runs: 2.4M
Run Growth: 0
Growth Rate: 0.00%
Updated:Oktober 04 2023
replicate

SDXL Inpainting by the HF Diffusers team

Total runs: 2.1M
Run Growth: 0
Growth Rate: 0.00%
Updated:März 06 2024
replicate

Robust face restoration algorithm for old photos/AI-generated faces

Total runs: 1.7M
Run Growth: 0
Growth Rate: 0.00%
Updated:September 06 2023
replicate

Turn any image into a video

Total runs: 1.3M
Run Growth: 0
Growth Rate: 0.00%
Updated:September 03 2023
replicate

Segmind Stable Diffusion Model (SSD-1B) is a distilled 50% smaller version of SDXL, offering a 60% speedup while maintaining high-quality text-to-image generation capabilities

Total runs: 994.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 09 2023
replicate

Hyper FLUX 8-step by ByteDance

Total runs: 926.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 28 2024
replicate

FLUX.1-Schnell LoRA Explorer

Total runs: 924.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 07 2024
replicate

CLIP Interrogator for SDXL optimizes text prompts to match a given image

Total runs: 846.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:Mai 17 2024
replicate

Coqui XTTS-v2: Multilingual Text To Speech Voice Cloning

Total runs: 835.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 28 2023
replicate

A multimodal LLM-based AI assistant, which is trained with alignment techniques. Qwen-VL-Chat supports more flexible interaction, such as multi-round question answering, and creative capabilities.

Total runs: 799.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:Oktober 15 2023
replicate

😊 Hotshot-XL is an AI text-to-GIF model trained to work alongside Stable Diffusion XL

Total runs: 576.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:Oktober 23 2023
replicate

SDXL v1.0 - A text-to-image generative AI model that creates beautiful images

Total runs: 478.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 02 2023
replicate

snowflake-arctic-embed is a suite of text embedding models that focuses on creating high-quality retrieval models optimized for performance

Total runs: 397.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:April 20 2024
replicate

Latent Consistency Model (LCM): SDXL, distills the original model into a version that requires fewer steps (4 to 8 instead of the original 25 to 50)

Total runs: 395.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 13 2023
replicate

Monster Labs QrCode ControlNet on top of SD Realistic Vision v5.1

Total runs: 390.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 24 2023
replicate

moondream2 is a small vision language model designed to run efficiently on edge devices

Total runs: 370.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:Juli 29 2024
replicate

RealvisXL-v2.0 with LCM LoRA - requires fewer steps (4 to 8 instead of the original 40 to 50)

Total runs: 292.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 16 2023
replicate

Implementation of SDXL RealVisXL_V2.0

Total runs: 284.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 09 2023
replicate

Animate Your Personalized Text-to-Image Diffusion Models

Total runs: 281.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 25 2023
replicate

Practical face restoration algorithm for *old photos* or *AI-generated faces* (for larger images)

Total runs: 263.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 03 2023
replicate

DreamShaper is a general purpose SD model that aims at doing everything well, photos, art, anime, manga. It's designed to match Midjourney and DALL-E.

Total runs: 200.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:Dezember 20 2023
replicate

Real-ESRGAN Video Upscaler

Total runs: 191.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 25 2023
replicate

A unique fusion that showcases exceptional prompt adherence and semantic understanding, it seems to be a step above base SDXL and a step closer to DALLE-3 in terms of prompt comprehension

Total runs: 125.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:Dezember 27 2023
replicate

CLIP Interrogator (for faster inference)

Total runs: 122.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 12 2023
replicate

dreamshaper-xl-lightning is a Stable Diffusion model that has been fine-tuned on SDXL

Total runs: 114.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:Februar 27 2024
replicate

AI-driven audio enhancement for your audio files, powered by Resemble AI

Total runs: 88.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:Dezember 15 2023
replicate

Phi-3-Mini-4K-Instruct is a 3.8B parameters, lightweight, state-of-the-art open model trained with the Phi-3 datasets

Total runs: 81.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:Juli 03 2024
replicate

SDXL_Niji_Special Edition

Total runs: 71.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 14 2023
replicate

Florence-2: Advancing a Unified Representation for a Variety of Vision Tasks

Total runs: 70.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:Juni 26 2024
replicate

PixArt-Alpha 1024px is a transformer-based text-to-image diffusion system trained on text embeddings from T5

Total runs: 64.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:Dezember 04 2023
replicate

MagicAnimate: Temporally Consistent Human Image Animation using Diffusion Model

Total runs: 55.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:Dezember 05 2023
replicate

Dreamshaper-7 img2img with LCM LoRA for faster inference

Total runs: 55.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 17 2023
replicate

Florence-2: Advancing a Unified Representation for a Variety of Vision Tasks

Total runs: 46.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:Juni 26 2024
replicate

Implementation of SDXL RealVisXL_V1.0

Total runs: 44.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 13 2023
replicate

SDXL Image Blending

Total runs: 42.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:Dezember 12 2023
replicate

(Academic and Non-commercial use only) Pixel-Aware Stable Diffusion for Realistic Image Super-resolution and Personalized Stylization

Total runs: 40.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:Januar 08 2024
replicate

BakLLaVA-1 is a Mistral 7B base augmented with the LLaVA 1.5 architecture

Total runs: 39.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:Oktober 24 2023
replicate

lmsys/vicuna-13b-v1.3

Total runs: 38.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:Juni 30 2023
replicate

Mistral-7B-v0.1 fine tuned for chat with the Dolphin dataset (an open-source implementation of Microsoft's Orca)

Total runs: 35.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:Oktober 31 2023
replicate

Real-ESRGAN with optional face correction and adjustable upscale (for larger images)

Total runs: 34.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:Juli 17 2023
replicate

Latest model in the Qwen family for chatting with video and image models

Total runs: 34.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:Dezember 21 2024
replicate

Gemma2 2b by Google

Total runs: 33.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 01 2024
replicate

The image prompt adapter is designed to enable a pretrained text-to-image diffusion model to generate SDXL images with an image prompt

Total runs: 31.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 12 2023
replicate

(Research only) IP-Adapter-FaceID can generate various style images conditioned on a face with only text prompts

Total runs: 29.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:Dezember 21 2023
replicate

lmsys/vicuna-7b-v1.3

Total runs: 28.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:Juni 30 2023
replicate

Meta's Llama 2 7b Chat - GPTQ

Total runs: 20.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:Juli 24 2023
replicate

Segment Anything 2 (SAM2) by Meta - Automatic mask generation

Total runs: 19.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:Juli 31 2024
replicate

Stylized Audio-Driven Single Image Talking Face Animation

Total runs: 18.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:Oktober 08 2023
replicate

sdxs-512-0.9 can generate high-resolution images in real-time based on prompt texts, trained using score distillation and feature matching

Total runs: 18.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:März 28 2024
replicate

Meta's Llama 2 13b Chat - GPTQ

Total runs: 18.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:Juli 25 2023
replicate

WizardCoder: Empowering Code Large Language Models with Evol-Instruct

Total runs: 17.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:Januar 24 2024
replicate

ThinkDiffusionXL is a go-to model capable of amazing photorealism that's also versatile enough to generate high-quality images across a variety of styles and subjects without needing to be a prompting genius

Total runs: 15.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 07 2023
replicate

This is wizard-vicuna-13b trained with a subset of the dataset - responses that contained alignment / moralizing were removed

Total runs: 15.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:April 26 2024
replicate

Hyper FLUX 16-step by ByteDance

Total runs: 15.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 28 2024
replicate

Mistral-7B-v0.1 fine tuned for chat with the Dolphin dataset (an open-source implementation of Microsoft's Orca)

Total runs: 13.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:Oktober 31 2023
replicate

Image-to-video - SEINE: Short-to-Long Video Diffusion Model for Generative Transition and Prediction

Total runs: 12.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 23 2023
replicate

Auto fuse a user's face onto the template image, with a similar appearance to the user

Total runs: 11.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 16 2023
replicate

Segments an audio recording based on who is speaking (on A100)

Total runs: 11.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:Juli 22 2023
replicate

(Research only) Moondream1 is a vision language model that performs on par with models twice its size

Total runs: 11.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:Januar 25 2024
replicate

InterpAny-Clearer: Clearer anytime frame interpolation & Manipulated interpolation

Total runs: 11.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 30 2023
replicate

Image to Image enhancer using DemoFusion

Total runs: 10.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:Dezember 09 2023
replicate

Open diffusion model for high-quality video generation

Total runs: 10.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:Oktober 19 2023
replicate

Orpheus 3B - high quality, emotive Text to Speech

Total runs: 10.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:März 21 2025
replicate

DemoFusion: Democratising High-Resolution Image Generation With No 💰

Total runs: 9.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:Dezember 04 2023
replicate

Implementation of SDXL RealVisXL_V2.0 img2img

Total runs: 8.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 07 2023
replicate

Phi-3-Mini-128K-Instruct is a 3.8 billion-parameter, lightweight, state-of-the-art open model trained using the Phi-3 datasets

Total runs: 8.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:April 26 2024
replicate

In-Context LoRA with Image-to-Image and Inpainting to apply your logo to anything

Total runs: 6.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:Februar 26 2025
replicate

Cog wrapper for Ollama llama3:70b

Total runs: 6.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:Juli 09 2024
replicate

360 Panorama SDXL image with inpainted wrapping seam

Total runs: 6.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 10 2023
replicate

Convert your videos to DensePose and use it with MagicAnimate

Total runs: 5.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:Dezember 06 2023
replicate

Projection module trained to add vision capabilties to Llama 3 using SigLIP

Total runs: 5.5K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 05 2024
replicate

Fuyu-8B is a multi-modal text and image transformer trained by Adept AI

Total runs: 4.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:Oktober 20 2023
replicate

Qwen1.5 is the beta version of Qwen2, a transformer-based decoder-only language model pretrained on a large amount of data

Total runs: 4.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:Februar 07 2024
replicate

Controlnet v1.1 - Tile Version

Total runs: 4.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 27 2023
replicate

A combination of ip_adapter SDv1.5 and mediapipe-face to inpaint a face

Total runs: 3.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 15 2023
replicate

SDXL using DeepCache

Total runs: 3.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:Januar 08 2024
replicate

Segmind Stable Diffusion Model (SSD-1B) img2img

Total runs: 3.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 03 2023
replicate

Phi-2 by Microsoft

Total runs: 3.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:Januar 31 2024
replicate

Playground v2 is a diffusion-based text-to-image generative model trained from scratch. Try out all 3 models here

Total runs: 3.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:Dezember 08 2023
replicate

nomic-embed-text-v1 is 8192 context length text encoder that surpasses OpenAI text-embedding-ada-002 and text-embedding-3-small performance on short and long context tasks

Total runs: 3.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:Februar 13 2024