



Sponsored by
iMean AI Trip Planner
m-a-p / OpenCodeInterpreter-CL-13B
Model's Last Updated: March 03 2024
text-generation
Introduction of OpenCodeInterpreter-CL-13B
Model Details of OpenCodeInterpreter-CL-13B
OpenCodeInterpreter: Integrating Code Generation with Execution and Refinement
Introduction
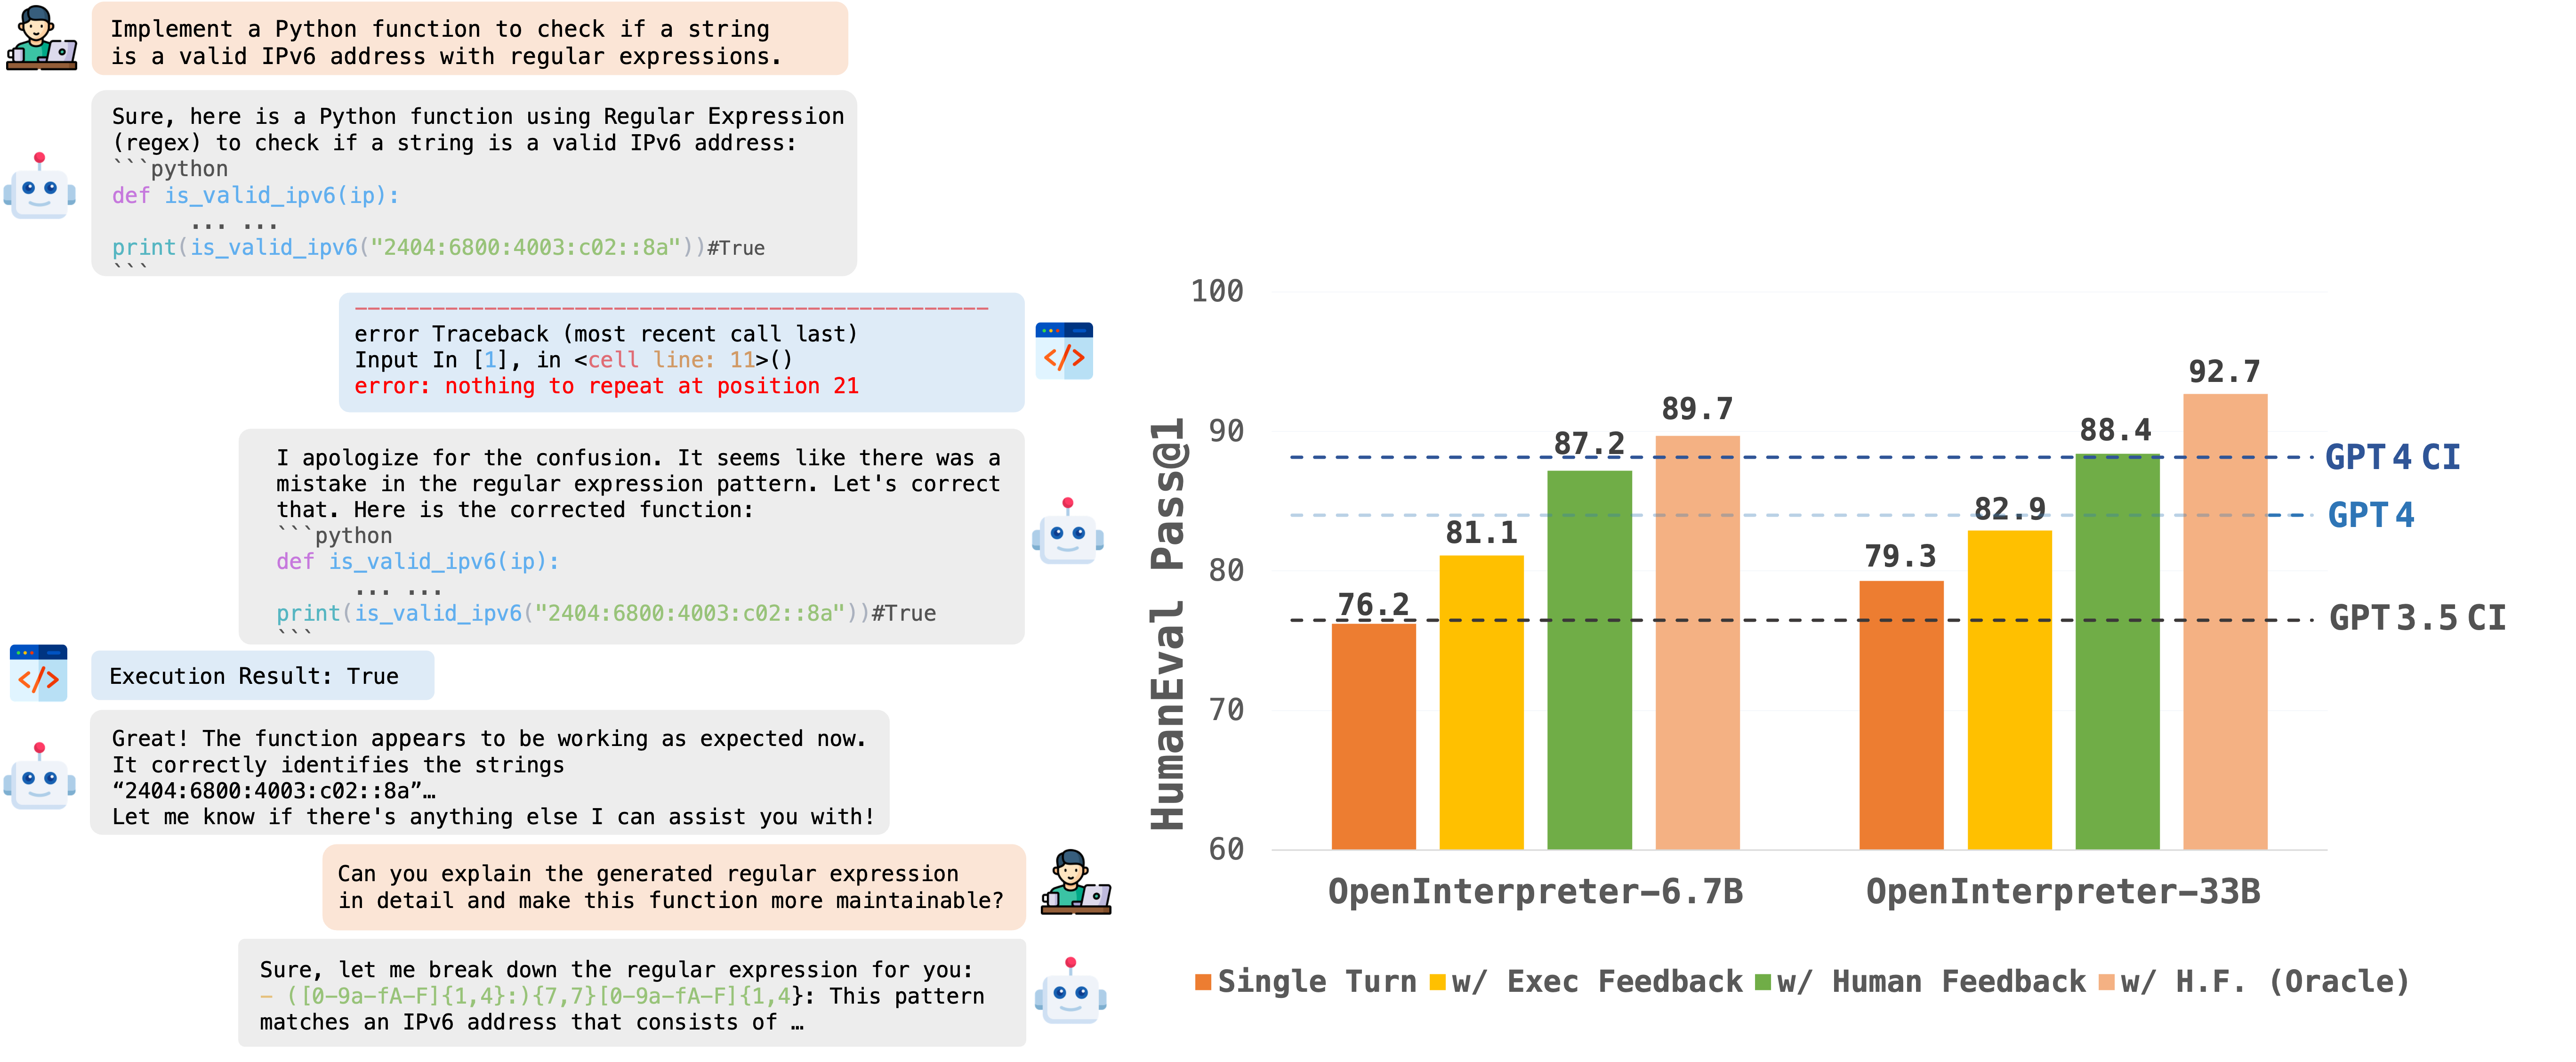
OpenCodeInterpreter is a family of open-source code generation systems designed to bridge the gap between large language models and advanced proprietary systems like the GPT-4 Code Interpreter. It significantly advances code generation capabilities by integrating execution and iterative refinement functionalities.
For further information and related work, refer to our paper: "OpenCodeInterpreter: A System for Enhanced Code Generation and Execution" available on arXiv.
Model Information
This model is based on CodeLlama-13b-Python-hf .
Benchmark Scores
The OpenCodeInterpreter Models series exemplifies the evolution of coding model performance, particularly highlighting the significant enhancements brought about by the integration of execution feedback. In an effort to quantify these improvements, we present a detailed comparison across two critical benchmarks: HumanEval and MBPP. This comparison not only showcases the individual performance metrics on each benchmark but also provides an aggregated view of the overall performance enhancement. The subsequent table succinctly encapsulates the performance data, offering a clear perspective on how execution feedback contributes to elevating the models' capabilities in code interpretation and execution tasks.
| Benchmark | HumanEval (+) | MBPP (+) | Average (+) |
|---|---|---|---|
| OpenCodeInterpreter-DS-1.3B | 65.2 (61.0) | 63.4 (52.4) | 64.3 (56.7) |
| + Execution Feedback | 65.2 (62.2) | 65.2 (55.6) | 65.2 (58.9) |
| OpenCodeInterpreter-DS-6.7B | 76.2 (72.0) | 73.9 (63.7) | 75.1 (67.9) |
| + Execution Feedback | 81.1 (78.7) | 82.7 (72.4) | 81.9 (75.6) |
| + Synth. Human Feedback | 87.2 (86.6) | 86.2 (74.2) | 86.7 (80.4) |
| + Synth. Human Feedback (Oracle) | 89.7 (86.6) | 87.2 (75.2) | 88.5 (80.9) |
| OpenCodeInterpreter-DS-33B | 79.3 (74.3) | 78.7 (66.4) | 79.0 (70.4) |
| + Execution Feedback | 82.9 (80.5) | 83.5 (72.2) | 83.2 (76.4) |
| + Synth. Human Feedback | 88.4 (86.0) | 87.5 (75.9) | 88.0 (81.0) |
| + Synth. Human Feedback (Oracle) | 92.7 (89.7) | 90.5 (79.5) | 91.6 (84.6) |
| OpenCodeInterpreter-CL-7B | 72.6 (67.7) | 66.4 (55.4) | 69.5 (61.6) |
| + Execution Feedback | 75.6 (70.1) | 69.9 (60.7) | 72.8 (65.4) |
| OpenCodeInterpreter-CL-13B | 77.4 (73.8) | 70.7 (59.2) | 74.1 (66.5) |
| + Execution Feedback | 81.1 (76.8) | 78.2 (67.2) | 79.7 (72.0) |
| OpenCodeInterpreter-CL-34B | 78.0 (72.6) | 73.4 (61.4) | 75.7 (67.0) |
| + Execution Feedback | 81.7 (78.7) | 80.2 (67.9) | 81.0 (73.3) |
| OpenCodeInterpreter-CL-70B | 76.2 (70.7) | 73.0 (61.9) | 74.6 (66.3) |
| + Execution Feedback | 79.9 (77.4) | 81.5 (69.9) | 80.7 (73.7) |
| OpenCodeInterpreter-GM-7B | 56.1 (50.0) | 39.8 (34.6) | 48.0 (42.3) |
| + Execution Feedback | 64.0 (54.3) | 48.6 (40.9) | 56.3 (47.6) |
| OpenCodeInterpreter-SC2-3B | 65.2 (57.9) | 62.7 (52.9) | 64.0 (55.4) |
| + Execution Feedback | 67.1 (60.4) | 63.4 (54.9) | 65.3 (57.7) |
| OpenCodeInterpreter-SC2-7B | 73.8 (68.9) | 61.7 (51.1) | 67.8 (60.0) |
| + Execution Feedback | 75.6 (69.5) | 66.9 (55.4) | 71.3 (62.5) |
| OpenCodeInterpreter-SC2-15B | 75.6 (69.5) | 71.2 (61.2) | 73.4 (65.4) |
| + Execution Feedback | 77.4 (72.0) | 74.2 (63.4) | 75.8 (67.7) |
Note: The "(+)" notation represents scores from extended versions of the HumanEval and MBPP benchmarks. To ensure a fair comparison, the results shown for adding execution feedback are based on outcomes after just one iteration of feedback, without unrestricted iterations. This approach highlights the immediate impact of execution feedback on performance improvements across benchmarks.
Model Usage
Inference
import torch
from transformers import AutoTokenizer, AutoModelForCausalLM
model_path="m-a-p/OpenCodeInterpreter-CL-13B"

tokenizer = AutoTokenizer.from_pretrained(model_path)
model = AutoModelForCausalLM.from_pretrained(
    model_path,
    torch_dtype=torch.bfloat16,
    device_map="auto",
)
model.eval()

prompt = "Write a function to find the shared elements from the given two lists."
inputs = tokenizer.apply_chat_template(
        [{'role': 'user', 'content': prompt }],
        return_tensors="pt"
    ).to(model.device)
outputs = model.generate(
    inputs,
    max_new_tokens=1024,
    do_sample=False,
    pad_token_id=tokenizer.eos_token_id,
    eos_token_id=tokenizer.eos_token_id,
)
print(tokenizer.decode(outputs[0][len(inputs[0]):], skip_special_tokens=True))
Contact
If you have any inquiries, please feel free to raise an issue or reach out to us via email at: [email protected] , [email protected] . We're here to assist you!"
Runs of m-a-p OpenCodeInterpreter-CL-13B on huggingface.co
112
Total runs
0
24-hour runs
36
3-day runs
90
7-day runs
95
30-day runs
More Information About OpenCodeInterpreter-CL-13B huggingface.co Model
Url of OpenCodeInterpreter-CL-13B
OpenCodeInterpreter-CL-13B huggingface.co Url
Provider of OpenCodeInterpreter-CL-13B huggingface.co
Other API from m-a-p
Total runs:
9.1K
Run Growth:
3.3K
Growth Rate:
35.97%
Total runs:
5.2K
Run Growth:
5.2K
Growth Rate:
99.01%
Total runs:
3.6K
Run Growth:
2.8K
Growth Rate:
76.20%
Total runs:
2.4K
Run Growth:
1.7K
Growth Rate:
72.98%
Total runs:
1.1K
Run Growth:
-270
Growth Rate:
-24.15%
Total runs:
899
Run Growth:
314
Growth Rate:
34.93%
Total runs:
887
Run Growth:
176
Growth Rate:
19.84%
Total runs:
878
Run Growth:
693
Growth Rate:
78.93%
Total runs:
847
Run Growth:
312
Growth Rate:
36.84%
Total runs:
720
Run Growth:
-879
Growth Rate:
-122.08%
Total runs:
611
Run Growth:
436
Growth Rate:
71.36%
Total runs:
411
Run Growth:
-47
Growth Rate:
-11.44%
Total runs:
404
Run Growth:
387
Growth Rate:
95.79%
Total runs:
312
Run Growth:
260
Growth Rate:
83.60%
Total runs:
266
Run Growth:
195
Growth Rate:
77.38%
Total runs:
247
Run Growth:
70
Growth Rate:
28.34%
Total runs:
237
Run Growth:
210
Growth Rate:
88.61%
Total runs:
226
Run Growth:
197
Growth Rate:
87.56%
Total runs:
190
Run Growth:
-30
Growth Rate:
-16.04%
Total runs:
153
Run Growth:
42
Growth Rate:
27.81%
Total runs:
132
Run Growth:
44
Growth Rate:
34.11%
Total runs:
112
Run Growth:
60
Growth Rate:
55.05%
Total runs:
89
Run Growth:
25
Growth Rate:
28.09%
Total runs:
70
Run Growth:
49
Growth Rate:
71.01%
Total runs:
68
Run Growth:
51
Growth Rate:
83.61%
Total runs:
47
Run Growth:
28
Growth Rate:
58.33%
Total runs:
41
Run Growth:
16
Growth Rate:
37.21%
Total runs:
41
Run Growth:
21
Growth Rate:
47.73%
Total runs:
38
Run Growth:
-35
Growth Rate:
-92.11%
Total runs:
38
Run Growth:
27
Growth Rate:
69.23%
Total runs:
37
Run Growth:
14
Growth Rate:
46.67%
Total runs:
36
Run Growth:
25
Growth Rate:
69.44%
Total runs:
33
Run Growth:
19
Growth Rate:
57.58%
Total runs:
32
Run Growth:
19
Growth Rate:
59.38%
Total runs:
30
Run Growth:
-41
Growth Rate:
-178.26%
Total runs:
30
Run Growth:
7
Growth Rate:
30.43%
Total runs:
30
Run Growth:
9
Growth Rate:
39.13%
Total runs:
29
Run Growth:
9
Growth Rate:
40.91%
Total runs:
29
Run Growth:
16
Growth Rate:
55.17%
Total runs:
28
Run Growth:
7
Growth Rate:
31.82%
Total runs:
28
Run Growth:
9
Growth Rate:
47.37%
Total runs:
28
Run Growth:
0
Growth Rate:
0.00%
Total runs:
28
Run Growth:
5
Growth Rate:
23.81%
Total runs:
27
Run Growth:
8
Growth Rate:
29.63%
Total runs:
27
Run Growth:
-2
Growth Rate:
-7.41%
Total runs:
26
Run Growth:
15
Growth Rate:
57.69%
Total runs:
26
Run Growth:
10
Growth Rate:
43.48%
Total runs:
26
Run Growth:
5
Growth Rate:
21.74%
Total runs:
26
Run Growth:
5
Growth Rate:
19.23%
Total runs:
26
Run Growth:
7
Growth Rate:
30.43%
Total runs:
25
Run Growth:
8
Growth Rate:
38.10%
Total runs:
25
Run Growth:
12
Growth Rate:
48.00%
Total runs:
25
Run Growth:
1
Growth Rate:
4.00%
Total runs:
24
Run Growth:
11
Growth Rate:
47.83%
Total runs:
24
Run Growth:
5
Growth Rate:
29.41%
Total runs:
24
Run Growth:
-17
Growth Rate:
-80.95%
Total runs:
23
Run Growth:
5
Growth Rate:
23.81%
Total runs:
23
Run Growth:
8
Growth Rate:
34.78%
Total runs:
23
Run Growth:
9
Growth Rate:
39.13%
Total runs:
22
Run Growth:
4
Growth Rate:
21.05%
Total runs:
22
Run Growth:
10
Growth Rate:
45.45%
Total runs:
22
Run Growth:
11
Growth Rate:
50.00%
Total runs:
21
Run Growth:
10
Growth Rate:
47.62%
Total runs:
21
Run Growth:
7
Growth Rate:
33.33%
Total runs:
21
Run Growth:
2
Growth Rate:
9.52%
Total runs:
21
Run Growth:
9
Growth Rate:
42.86%
Total runs:
20
Run Growth:
0
Growth Rate:
0.00%
Total runs:
20
Run Growth:
5
Growth Rate:
25.00%
Total runs:
20
Run Growth:
-3
Growth Rate:
-15.00%
Total runs:
19
Run Growth:
10
Growth Rate:
52.63%
Total runs:
19
Run Growth:
10
Growth Rate:
52.63%
Total runs:
19
Run Growth:
8
Growth Rate:
42.11%
Total runs:
19
Run Growth:
10
Growth Rate:
52.63%
Total runs:
19
Run Growth:
3
Growth Rate:
15.79%