



Total runs:
869.1K
Run Growth:
622.1K
Growth Rate:
74.64%

An MLX build of the official GLM-5.3 — 2 / 3 / 4 / 6-bit OrcaSAQ quant for Apple Silicon & the MLX CUDA backend


One Gateway. Every Model.
— Route Smarter · Ship Safer · Spend Less.
GLM-5.3 on OrcaRouter →
Website · Model Catalog · Model API · GitHub · OrcaCode Review · Discord · X
An MLX build of the official
zai-org/GLM-5.3— Z.AI's 753B-total / ~39B-active MoE flagship for frontier coding and long-horizon agentic engineering, built on theglm_moe_dsaarchitecture (MLA + DeepSeek-style sparse attention with a shared indexer , 1M context) — quantized to MLX for Apple Silicon and the MLX CUDA backend. Four precisions ( 2 / 3 / 4 / 6-bit ) ship as subfolders with the 4-bit build mirrored at the repo root , produced with OrcaSAQ (Sensitivity-Aware Quantization) : calibration-free and architecture-aware, giving sensitive tensors more bits (shared experts+2,down_proj+1) while attention stays at 8-bit and the DSA indexer stays in BF16 in every build. Browse all models in the OrcaRouter Model Catalog ; deployed as API here . Put this model to work reviewing your pull requests with OrcaCode Review .
| Folder | Expert base bits | Group size | Size | Min RAM | Quality vs FP8 |
|---|---|---|---|---|---|
6-bit/
|
6 | 64 | 671 GB (625 GiB) | ~700 GB | Near-lossless — best quality |
4-bit/
|
4 | 64 | 459 GB (427 GiB) | ~480 GB | Very good — recommended default |
3-bit/
|
3 | 64 | 368 GB (343 GiB) | ~390 GB | Good — aggressive but usable |
2-bit/
|
2 | 32 | 322 GB (300 GiB) | ~340 GB | Aggressive — best-effort |
The
repository root is a mirror of
4-bit/
, so
orcarouter/GLM-5.3-MLX
resolves to the recommended default with no subfolder needed.
Quantized from the official FP8 release (756 GB, block-wise
e4m3128×128, dynamic activation scheme). Bit-widths above are the expert base precision; the OrcaSAQ policy below raises sensitive tensors above the base. Group size is 64 everywhere except the2-bitrouted experts, which use 32 — at two bits the finer grid is what keeps the build usable (see the fidelity table).
Hardware reality check.
This is a 753B model; even the smallest build is 322 GB. On a
512 GB M3 Ultra Mac Studio
,
2-bit
and
3-bit
leave comfortable KV headroom and
4-bit
fits but runs tight — raise the wired-memory limit and keep the context bounded.
6-bit
does not fit any single Apple Silicon machine today: run it across two 512 GB boxes with
mlx.distributed
, or on a CUDA host (8×H200 = 1128 GB) via the MLX CUDA backend. If the hardware isn't there, the
hosted API
needs no local memory at all.
No 8-bit build was produced:
6-bit
already lands at cosine ≥ 0.9997 against FP8, and 8-bit expert weights would exceed the FP8 source in size.
OrcaSAQ is a calibration-free, architecture-aware mixed-precision quantization method designed to preserve model quality while aggressively reducing memory footprint.
Instead of running expensive calibration datasets or per-layer sensitivity searches, OrcaSAQ uses architectural and tensor-role priors to determine which weights are most sensitive to quantization. Critical components receive higher precision, while more quantization-tolerant tensors remain at the target base precision.
For MoE architectures, for example, OrcaSAQ can preserve shared experts at
base +2 bits
,
down_proj
at
base +1 bit
, keep
gate_proj
and
up_proj
at the base precision, and retain sensitive non-quantized components at their source dtype.
The result is a fast, deterministic, zero-calibration quantization pipeline that can be applied to new architectures without costly dataset-driven optimization.
Architecture-aware. Calibration-free. Quality-preserving.
Two properties of this checkpoint drive the whole recipe:
Everything that was
not
FP8 in the base release — the indexer, router
gate
weights, the FP32
e_score_correction_bias
, every norm,
embed_tokens
and
lm_head
— is carried through at its
original dtype
, never a lossy cast.
| Component | Tensors | Params | 2-bit | 3-bit | 4-bit | 6-bit | Policy |
|---|---|---|---|---|---|---|---|
Expert
gate_proj
/
up_proj
|
38,400 | 483.2B |
2
gs32
|
3 | 4 | 6 | base |
Expert
down_proj
|
19,200 | 241.6B |
3
gs32
|
4 | 5 | 8 | base +1 |
Shared expert
gate
/
up
/
down
|
225 | 2.83B | 4 | 5 | 6 | 8 | base +2 |
MLA
q_a
/
q_b
/
kv_a_with_mqa
/
kv_b
/
o_proj
|
390 | 12.87B | 8 | 8 | 8 | 8 | pinned 8-bit |
Dense-MLP
gate
/
up
/
down
(layers 0–2)
|
9 | 0.68B | 6 | 6 | 6 | 6 | pinned 6-bit |
DSA indexer
wk
/
wq_b
/
weights_proj
|
63 | 0.19B | BF16 | BF16 | BF16 | BF16 | never quantized |
Router
gate.weight
|
75 | 0.12B | BF16 | BF16 | BF16 | BF16 | never quantized |
Router
e_score_correction_bias
|
75 | — | FP32 | FP32 | FP32 | FP32 | never quantized |
Norms (incl. indexer
k_norm
),
embed_tokens
,
lm_head
|
357 | 1.90B | BF16 | BF16 | BF16 | BF16 | never quantized |
58,224 tensors are quantized
in total (97.5 % of all parameters live in the routed experts). Bits are rounded to the nearest MLX-supported width (
{2,3,4,5,6,8}
), and group size must divide the tensor's last dim —
gs64
on attention is mandatory because
qk_nope_head_dim
is 192 and
gs128
breaks mlx-lm's
kv_b → embed_q
re-quantization.
Effective width on the experts, including the FP16 scales and biases MLX stores per group:
| Build | Expert effective bpw | Experts as share of build |
|---|---|---|
2-bit
|
3.33 | 93.7 % |
3-bit
|
3.83 | 94.4 % |
4-bit
|
4.83 | 95.4 % |
6-bit
|
7.17 | 96.8 % |
The assignment is recorded in
config.json
→
quantization
(and mirrored to
quantization_config
) as
per-module
{group_size, bits}
overrides keyed by MLX module path
— e.g.
model.layers.3.mlp.switch_mlp.down_proj
. MLX fuses a layer's 256 routed experts into one
switch_mlp
, so
699 entries
cover all 58,224 tensors. This is what the loader reads at load time and it is
required
: the top-level
bits
/
group_size
alone would mis-shape every raised-precision tensor. A full per-tensor record is also shipped as
quantization_map.json
.
The
MTP (multi-token prediction) layer — layer 78 — is dropped
, and
num_nextn_predict_layers
is set to
0
. 791 tensors (~9.95B params) are removed; MLX runtimes drop it at load anyway.
All three tables compare each build against the full
FP8
reference (dequantized to BF16 and run
through the identical
glm_moe_dsa
forward, so the only variable is the quantization). Sizes are
decimal GB, matching the file sizes in this repo.
Perplexity
Measured against the
FP8 reference
on wikitext-2 test, 4 chunks × 1024 tokens
(4,092 predicted tokens). Both sides run the identical
glm_moe_dsa
forward on the
same FP8 kernels — each build's actual dequantized bytes are injected back into the
transformers model — so quantization is the only variable.
| Build | Size | PPL | ΔPPL |
|---|---|---|---|
| FP8 (ref) | 756 GB | 1.6666 | — |
| 6-bit | 671 GB | 1.6642 | −0.14 % |
| 4-bit | 459 GB | 1.7015 | +2.10 % |
| 3-bit | 368 GB | 1.8249 | +9.50 % |
| 2-bit | 322 GB | 2.6385 | +58.3 % |
6-bit
lands within noise of the FP8 reference — read it as indistinguishable.
KL divergence & Top-1 token agreement
KLD is
KL(ref ‖ quant)
per token against the FP8 reference distribution, Top-1 is how
often the build's argmax matches the reference's. Lower KLD and higher Top-1 = closer to
the original. Same corpus and token budget as the PPL table.
| Build | Size | Mean KLD | KLD p95 | Top-1 agreement |
|---|---|---|---|---|
| FP8 (ref) | 756 GB | — | — | 100 % |
| 6-bit | 671 GB | 0.0295 | 0.1629 | 96.39 % |
| 4-bit | 459 GB | 0.0574 | 0.3049 | 95.46 % |
| 3-bit | 368 GB | 0.1668 | 0.9764 | 90.43 % |
| 2-bit | 322 GB | 0.5272 | 2.7405 | 80.18 % |
All three measurements — weight fidelity, perplexity, and KLD/Top-1 — agree on the
ordering:
6-bit
is effectively lossless,
4-bit
costs about
2 % perplexity for 43 %
less memory
and is the recommended default, and
3-bit
holds up well at 40 % under
FP8.
2-bit
is the memory-first option — reach for it when the hardware cannot hold
anything larger.
Weight-space fidelity — measured on every quantized tensor at pack time (58,224 per build):
| Build | Size | Cosine sim | SNR (dB) | Rel. error |
|---|---|---|---|---|
6-bit
|
671 GB | 0.9998 | 37.2 | 1.7 % |
4-bit
|
459 GB | 0.9968 | 22.9 | 7.6 % |
3-bit
|
368 GB | 0.9865 | 16.7 | 15.7 % |
2-bit
|
322 GB | 0.9517 | 11.2 | 29.7 % |
Worst-case per build (
cos_min
/
snr_min
):
6-bit
0.99972 / 32.5 dB ·
4-bit
0.99509 / 20.1 dB ·
3-bit
0.97869 / 13.7 dB ·
2-bit
0.92718 / 8.3 dB.
Relative error is the mean of the per-tensor relative error
10^(-SNR/20)over all 58,224 quantized tensors — not a value back-derived from the mean SNR, which would understate it (1.4 / 7.1 / 14.7 / 27.5 %).
Per role — this is where the OrcaSAQ policy shows up:
| Role | bits/gs | 2-bit cos | 3-bit cos | 4-bit cos | 6-bit cos |
|---|---|---|---|---|---|
Expert
gate_proj
/
up_proj
|
base | 0.93417 | 0.98169 | 0.99570 | 0.99975 |
Expert
down_proj
|
base +1 | 0.98510 | 0.99568 | 0.99898 | 0.99998 |
| Shared expert | base +2 | 0.99561 | 0.99896 | 0.99974 | 0.99998 |
| MLA attention | 8/64 | 0.99998 | 0.99998 | 0.99998 | 0.99998 |
| Dense MLP | 6/64 | 0.99975 | 0.99975 | 0.99975 | 0.99975 |
Cosine distribution across all quantized tensors (tight percentiles = no outlier tensors hiding behind a good mean):
| Build | min | p1 | p5 | median | p95 | max |
|---|---|---|---|---|---|---|
2-bit
|
0.92718 | 0.93133 | 0.93390 | 0.93437 | 0.98515 | 0.99999 |
3-bit
|
0.97869 | 0.98047 | 0.98157 | 0.98178 | 0.99571 | 0.99999 |
4-bit
|
0.99509 | 0.99546 | 0.99566 | 0.99571 | 0.99899 | 0.99999 |
6-bit
|
0.99972 | 0.99974 | 0.99975 | 0.99975 | 0.99999 | 0.99999 |
The worst tensors in every build are the same ones — early-layer routed experts (
layers.3–5
, e.g.
layers.4.mlp.experts.168.gate_proj
) — and
6-bit
still holds them above 0.9997.
Build verification — every build passed a structural release gate before upload:
weight
/
scales
/
biases
triplets all paired
keep
goes through a proper block dequant, never a raw cast)
model.safetensors.index.json
resolves every tensor;
total_size
matches the shards on disk
glm_moe_dsa
module tree vs the post-sanitize key set:
1497/1497
, zero missing, zero extra
The full-precision model is live on OrcaRouter as
z-ai/glm-5.3
— 1M context, 128K max output, $1.26 / $3.96 per 1M input / output tokens:
import os
from openai import OpenAI

client = OpenAI(
    base_url="https://api.orcarouter.ai/v1",
    api_key=os.environ["ORCAROUTER_API_KEY"],
)

response = client.chat.completions.create(
    model="z-ai/glm-5.3",
    messages=[{"role": "user", "content": "Refactor this module and explain the tradeoffs."}],
)
print(response.choices[0].message.content)
https://www.orcarouter.ai/models/z-ai/glm-5.3
Use
mlx-vlm, notmlx-lm. GLM-5.3 is a text-only model, but as of mlx-lm 0.31.3 theglm_moe_dsaimplementation builds an indexer for every layer, while this checkpoint shares one indexer across four layers (indexer_types) — 285 tensors come up missing. mlx-vlm 0.6.17 implements the shared-indexer layout and loads these builds as-is. Check for mlx-lm support before switching back.
pip install -U "mlx-vlm>=0.6.17"
The repo root is the 4-bit build, so the recommended default needs no subfolder — the excludes are what stop
hf download
from also pulling the four variant folders:
hf download orcarouter/GLM-5.3-MLX --local-dir ./GLM-5.3-MLX \
    --exclude "2-bit/*" "3-bit/*" "4-bit/*" "6-bit/*"

python -m mlx_vlm.generate --model ./GLM-5.3-MLX \
    --prompt "Write a Rust function that merges overlapping intervals." --max-tokens 512
To pick a different precision, download just that subfolder and load it from the local path:
hf download orcarouter/GLM-5.3-MLX --include "6-bit/*" --local-dir ./GLM-5.3-MLX

python -m mlx_vlm.generate --model ./GLM-5.3-MLX/6-bit \
    --prompt "Write a Rust function that merges overlapping intervals." --max-tokens 512
Python API:
from mlx_vlm import load, generate
from mlx_vlm.prompt_utils import apply_chat_template

model, processor = load("./GLM-5.3-MLX")          # repo root == 4-bit
prompt = apply_chat_template(processor, model.config, "Explain MLA vs GQA in three sentences.")

print(generate(model, processor, prompt, max_tokens=512, verbose=True))
Reasoning effort.
GLM-5.3's chat template takes a
reasoning_effort
variable —
low
,
high
, or
max
(the default when unset) — emitted as a system directive, plus a
clear_thinking
flag that strips prior
<think>
blocks from the history. Both pass straight through
apply_chat_template
:
prompt = apply_chat_template(processor, model.config, "Port this service to async.",
                             reasoning_effort="low")
Tool calling is in the template too (
<tool_call>
/
<arg_key>
blocks,
tools=[...]
).
Long context.
max_position_embeddingsis 1,048,576 (rope_theta8e6). The KV cache, not the weights, is what will bite you at those lengths — budget for it, or cap it with--max-kv-size/ quantize it with--kv-bits.On Apple Silicon the Metal backend is used automatically. On the Linux CUDA backend install
mlx[cuda]and setMLX_CUDA_USE_CUDNN_SDPA=0.
Models are only half the system.
OrcaCode Review turns every model listed on OrcaRouter into a production code-review agent:
Open model. Open harness. Open bill.
| Source |
zai-org/GLM-5.3
(FP8, 141 shards, 756 GB)
|
| Quantized | 2026-08-28 |
| Toolchain | MLX 0.32.2, safetensors 0.8.0, NumPy 2.5.2 |
| Method | OrcaSAQ — calibration-free, role-based mixed precision |
| Per-build files |
140 shards +
config.json
,
quantization_map.json
,
build_manifest.json
,
fidelity_summary.json
, tokenizer, chat template
|
Each folder carries its own
build_manifest.json
(exact recipe, source path, dropped-tensor count, toolchain versions) and
fidelity_summary.json
(per-role cosine/SNR with the five worst tensors named), so any claim in this card can be checked against the build itself.
Available full-precision on the OrcaRouter API as
z-ai/glm-5.3— https://www.orcarouter.ai/models/z-ai/glm-5.3
GLM-5.3 uses the same base model as GLM-5.2 — every gain comes from post-training. Compared with GLM-5.2, it is much better at complex coding and long-horizon tasks:

Reported by Z.AI for the full-precision model. These are the upstream model's numbers, not measurements of these MLX builds — see Quality vs FP8 above for how each quantization tracks the FP8 release.
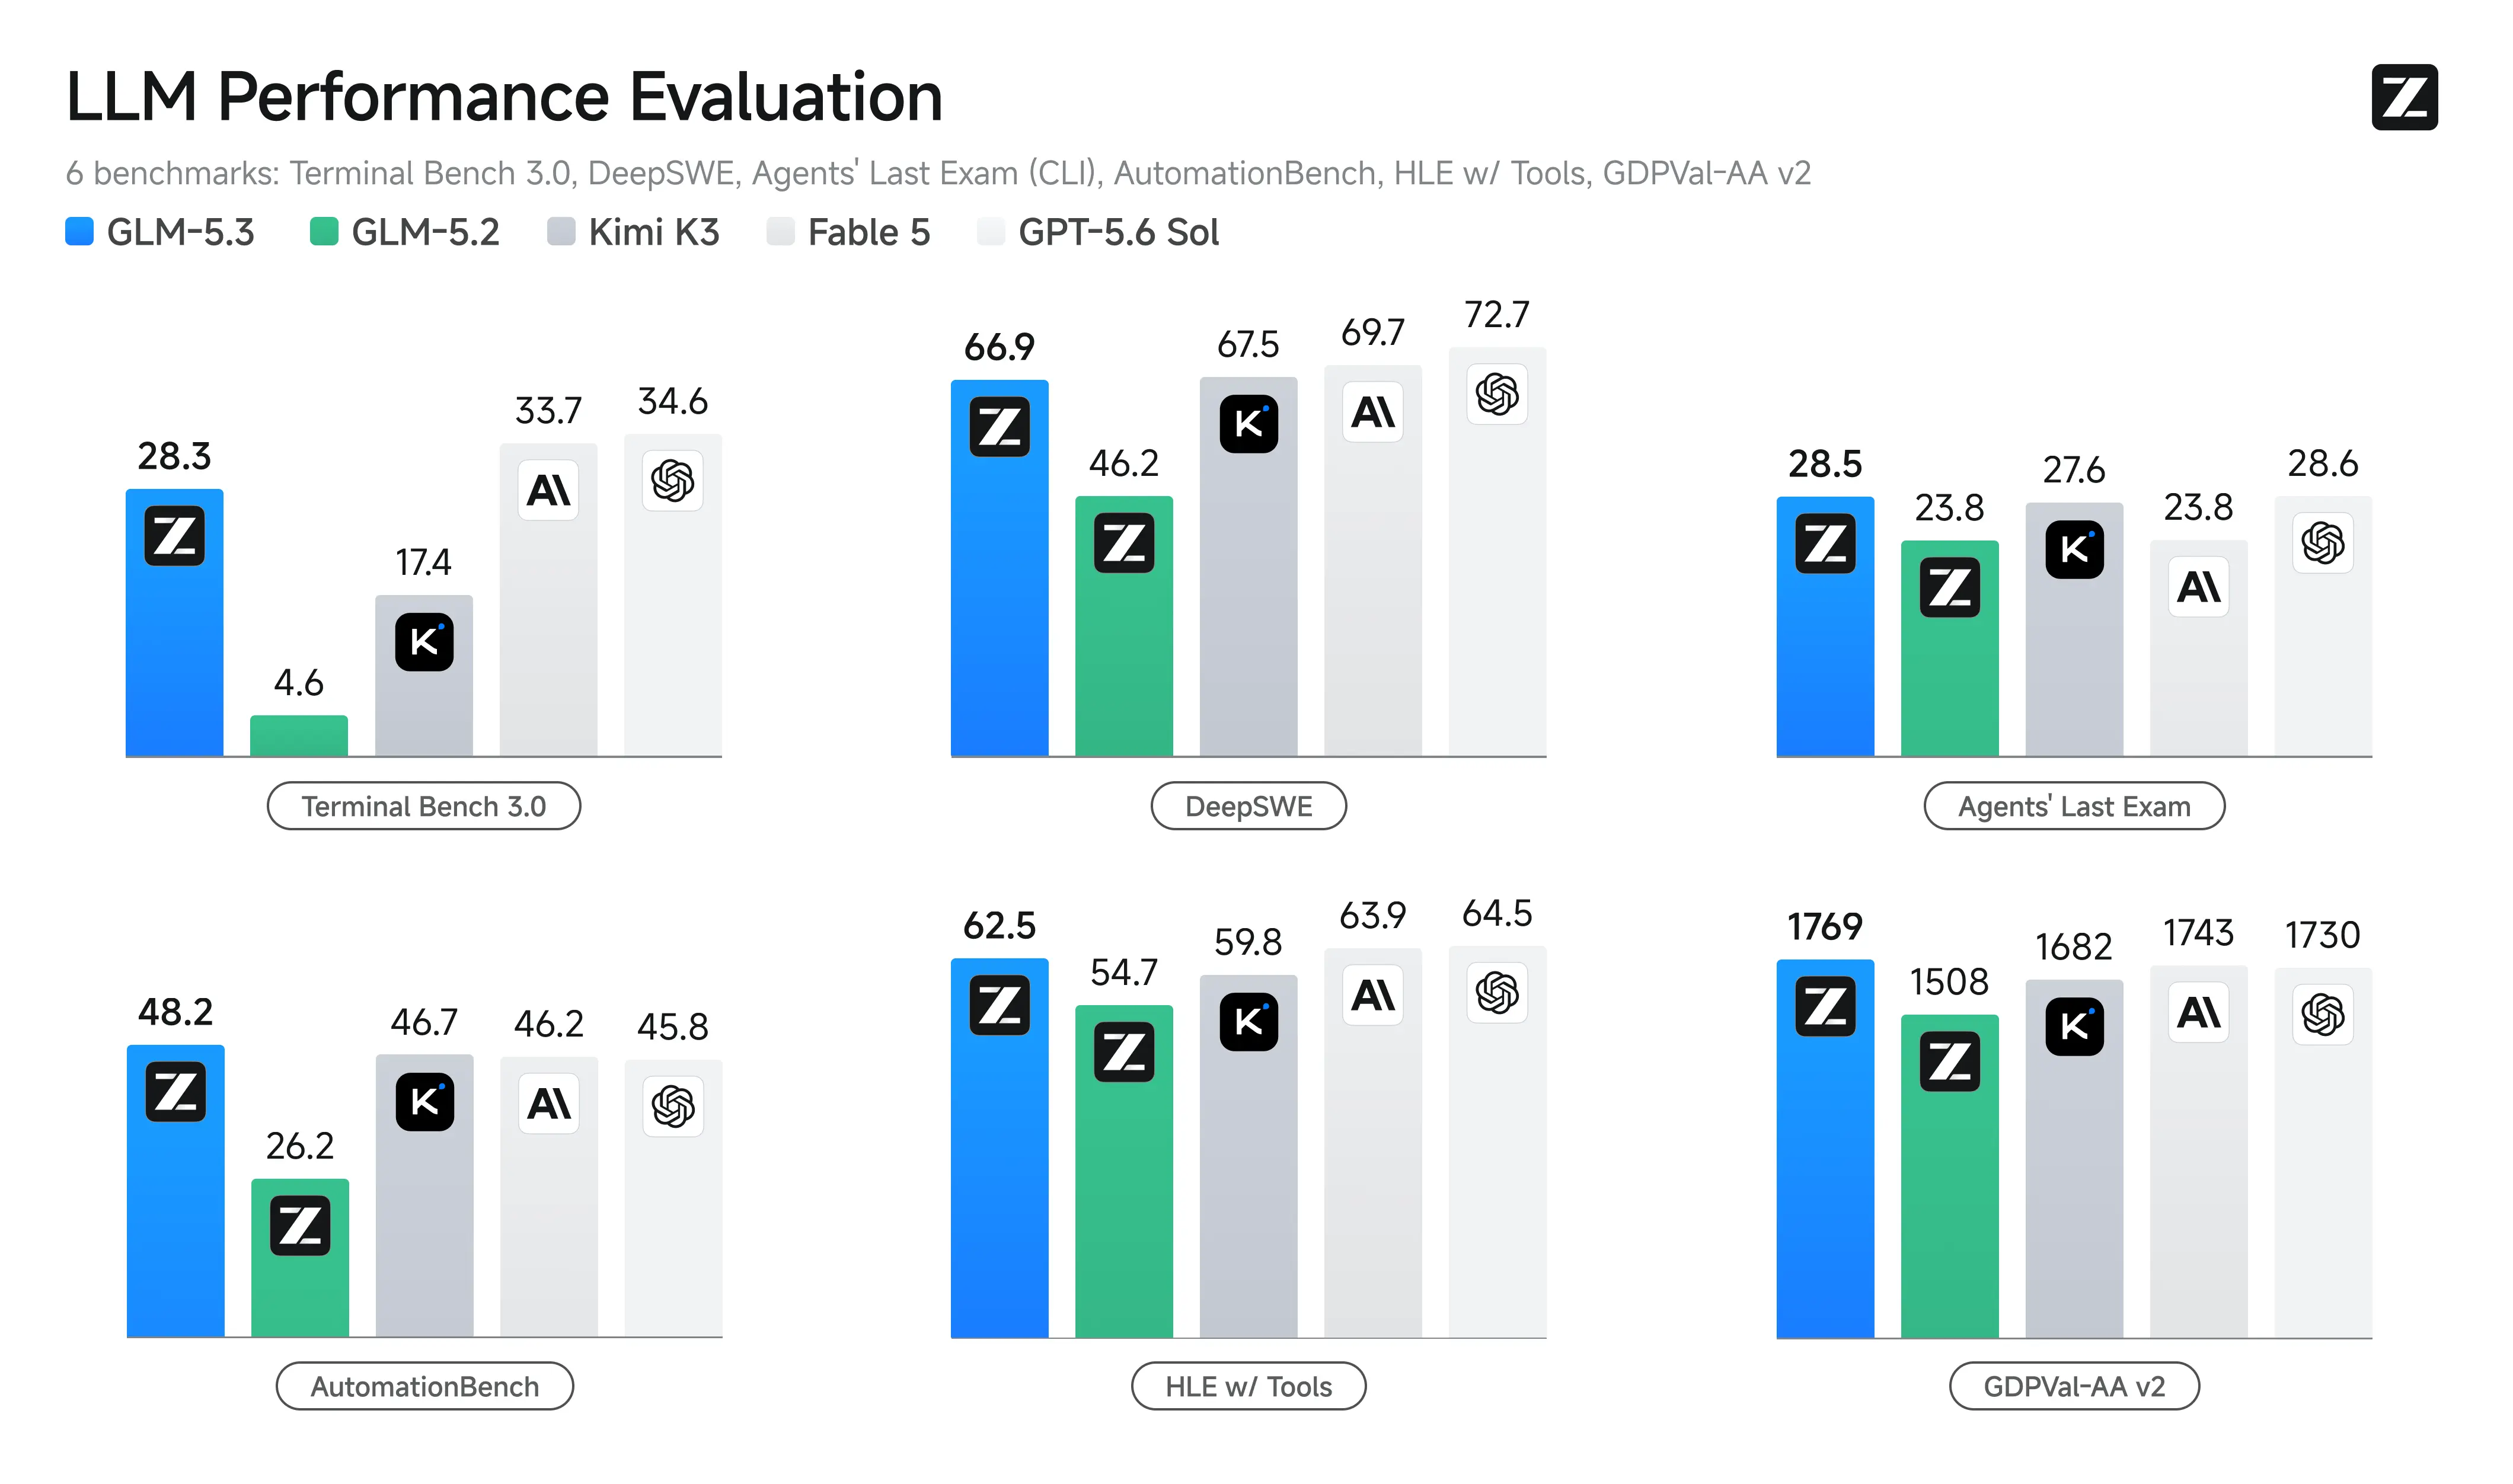
| Benchmark | GLM-5.3 | GLM-5.2 | Kimi K3 | DeepSeek-V4 Pro-0813 | Qwen3.8-Max | Opus 4.8 | Fable 5 (w/ fallback) | GPT-5.6 Sol |
|---|---|---|---|---|---|---|---|---|
| Terminal Bench 2.1 | 88.2 | 81.0 | 88.3 | 87.9 | 86.6 | 85.0 | 88.0 | 88.8 |
| Terminal Bench 3.0 | 28.3 | 4.6 | 17.4 | – | – | 21.1 | 33.7 | 34.6 |
| DeepSWE (v1.1) | 66.9 | 46.2 | 67.5 | 62.7 | 56.6 | 58.0 | 69.7 | 72.7 |
| NL2Repo | 58.0 | 48.9 | 58.0 | 61.1 | 55.9 | 69.7 | – | – |
| ProgramBench (Almost Solved) | 19.0 | 9.5 | 17.5 | – | 10.5 | 15.5 | 33.0 | 23.0 |
| FrontierSWE | 78.1 | 67.5 | – | – | – | 66.5 | 88.2 | – |
| SWE-Marathon (v1.1) | 42.5 | 19.4 | 48.1 | – | – | 48.8 | 33.1 | 42.5 |
| PostTrainBench | 39.8 | 31.7 | 32.0 | – | – | 32.9 | 41.8 | 36.2 |
| CyberGym | 84.5 | 77.2 | 80.0 | 83.3 | 78.5 | 78.1 | 83.8 | 83.6 |
| ExploitGym (2h / 6h) | 105 / 130 | 29 / 39 | 36 / 70 | – | 14 / 26 | 80 / 120 | 181 / 247 | 216 / 293 |
| ExploitBench | 54.4 | 24.4 | 32.2 | – | 28.8 | 40.0 | 78.0 | 76.5 |
| Toolathlon Verified | 73.0 | 59.9 | 76.5 | 74.1 | 72.5 | 76.2 | 74.7 | 74.9 |
| AutomationBench (v1.0.6) | 48.2 | 26.2 | 46.7 | 43.2 | 39.8 | 41.0 | 46.2 | 45.8 |
| Agents' Last Exam (ALE-CLI) | 28.5 | 23.8 | 27.6 | 25.7 | 27.0 | 25.7 | 23.8 | 28.6 |
| HLE w/ Tools | 62.5 | 54.7 | 59.8 | 60.0 | 56.2 | 57.9 | 63.9 | 64.5 |
| GDPval-AA v2 | 1769 | 1508 | 1682 | 1590 | 1739 | 1588 | 1743 | 1730 |
Full evaluation protocols and footnotes are in the official model card .
glm_moe_dsa
,
GlmMoeDsaForCausalLM
)
e_score_correction_bias
, single group,
routed_scaling_factor
2.5
q_lora_rank
2048,
kv_lora_rank
512, 64 heads,
qk_nope
192 +
qk_rope
64,
v_head_dim
256 — with a
DeepSeek-style sparse-attention indexer
(
index_topk
2048, 32 index heads) built on every 4th layer and shared by the three that follow
e4m3
, 128×128), dynamic activation scheme
6-bit
for near-lossless,
4-bit
(repo root) as the everyday default,
3-bit
when memory is the binding constraint,
2-bit
when nothing else fits — the tables above quantify the trade at each step.
generation_config.json
is
temperature
1.0,
top_p
0.95; long-horizon agentic and coding tasks want generous
max-tokens
headroom.
max
for hard engineering work; drop to
low
for latency-sensitive turns.
z-ai/glm-5.3
.
@misc{glm5team2026glm5vibecodingagentic,
      title={GLM-5: from Vibe Coding to Agentic Engineering},
      author={GLM-5-Team and Aohan Zeng and Xin Lv and Zhenyu Hou and Zhengxiao Du and others},
      year={2026},
      eprint={2602.15763},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2602.15763},
}
Inherited from
zai-org/GLM-5.3
— an MIT-style grant (use, modify, distribute, fine-tune, sell) with one added condition: operators of a
Model-as-a-Service
business whose aggregate revenue exceeds
US$10B over any 12 consecutive months
must pass a Z.AI security review before commercial use. The full text ships as
LICENSE
in this repo. Quantization does not change the underlying license obligations.