



Total runs:
2.5K
Run Growth:
-1.0K
Growth Rate:
-39.84%
This is an NF4 quantized model of Qwen-image so it can run on GPUs using 20GB VRAM. You can run it on lower VRAM like 16GB. There were other NF4 models but they made the mistake of blindly quantizing all layers in the transformer. This one does not. We retain some layers at full precision in order to ensure that we get quality output.
You can use the original Qwen-Image parameters as is though I recommend atleast 20 inference steps.
This model is available for inference, modifications and commercial use by support AT justlab.ai
from diffusers import DiffusionPipeline
import torch

model_name = "ovedrive/qwen-image-2512-4bit"

# Load the pipeline
if torch.cuda.is_available():
    torch_dtype = torch.bfloat16
    device = "cuda"
else:
    torch_dtype = torch.float32
    device = "cpu"

pipe = DiffusionPipeline.from_pretrained(model_name, torch_dtype=torch_dtype)
pipe = pipe.to(device)

positive_magic = {
    "en": "Ultra HD, 4K, cinematic composition." # for english prompt,
    "zh": "超清,4K,电影级构图" # for chinese prompt,
}

# Generate image
prompt = '''A coffee shop entrance features a chalkboard sign reading "Qwen Coffee 😊 $2 per cup," with a neon light beside it displaying "通义千问". Next to it hangs a poster showing a beautiful Chinese woman, and beneath the poster is written "π≈3.1415926-53589793-23846264-33832795-02384197". Ultra HD, 4K, cinematic composition'''

negative_prompt = " " # using an empty string if you do not have specific concept to remove


# Generate with different aspect ratios
aspect_ratios = {
    "1:1": (1328, 1328),
    "16:9": (1664, 928),
    "9:16": (928, 1664),
    "4:3": (1472, 1140),
    "3:4": (1140, 1472),
    "3:2": (1584, 1056),
    "2:3": (1056, 1584),
}

width, height = aspect_ratios["16:9"]

image = pipe(
    prompt=prompt + positive_magic["en"],
    negative_prompt=negative_prompt,
    width=width,
    height=height,
    num_inference_steps=20,
    true_cfg_scale=4.0,
    generator=torch.Generator(device="cuda").manual_seed(42)
).images[0]

image.save("example.png")
The original Qwen-Image attributions are included verabtim below.

💜
Qwen Chat
| 🤗
Hugging Face
| 🤖
ModelScope
| 📑
Tech Report
| 📑
Blog
🖥️
Demo
| 💬
WeChat (微信)
| 🫨
Discord
|
Github
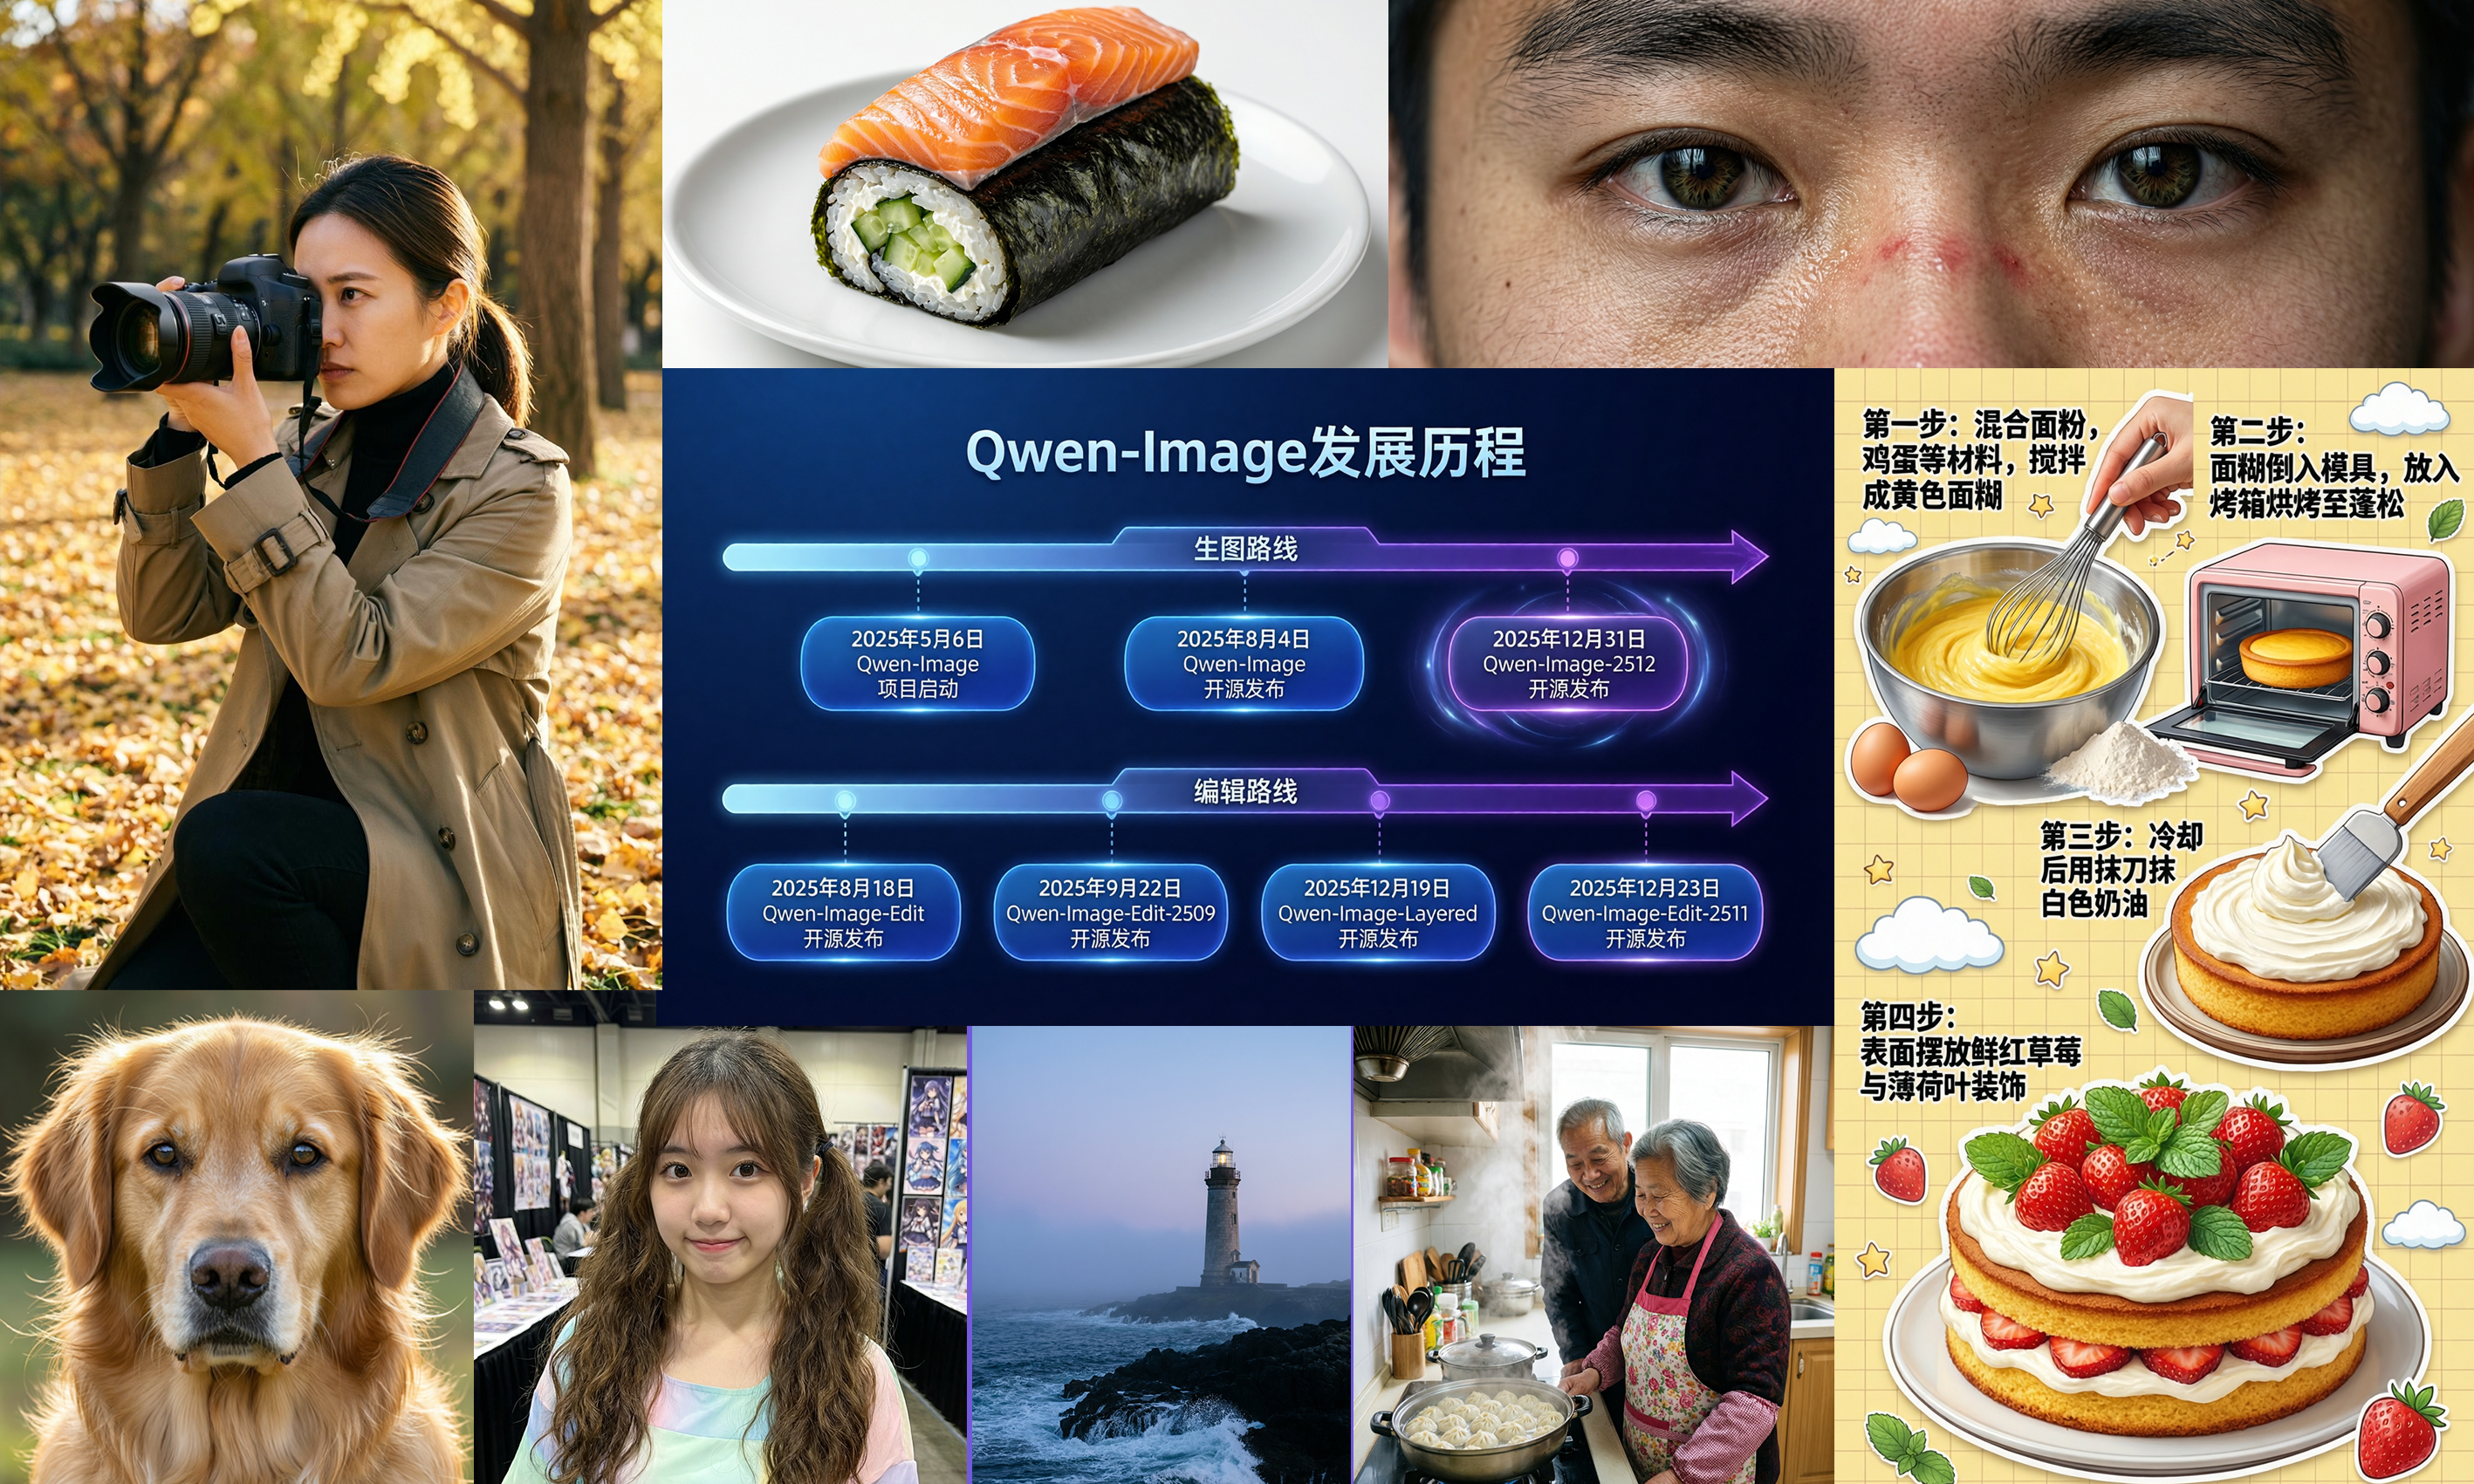
We are excited to introduce Qwen-Image-2512, the December update of Qwen-Image’s text-to-image foundational model. You are welcome to try the latest model at Qwen Chat . Compared to the base Qwen-Image model released in August, Qwen-Image-2512 features the following key improvements:
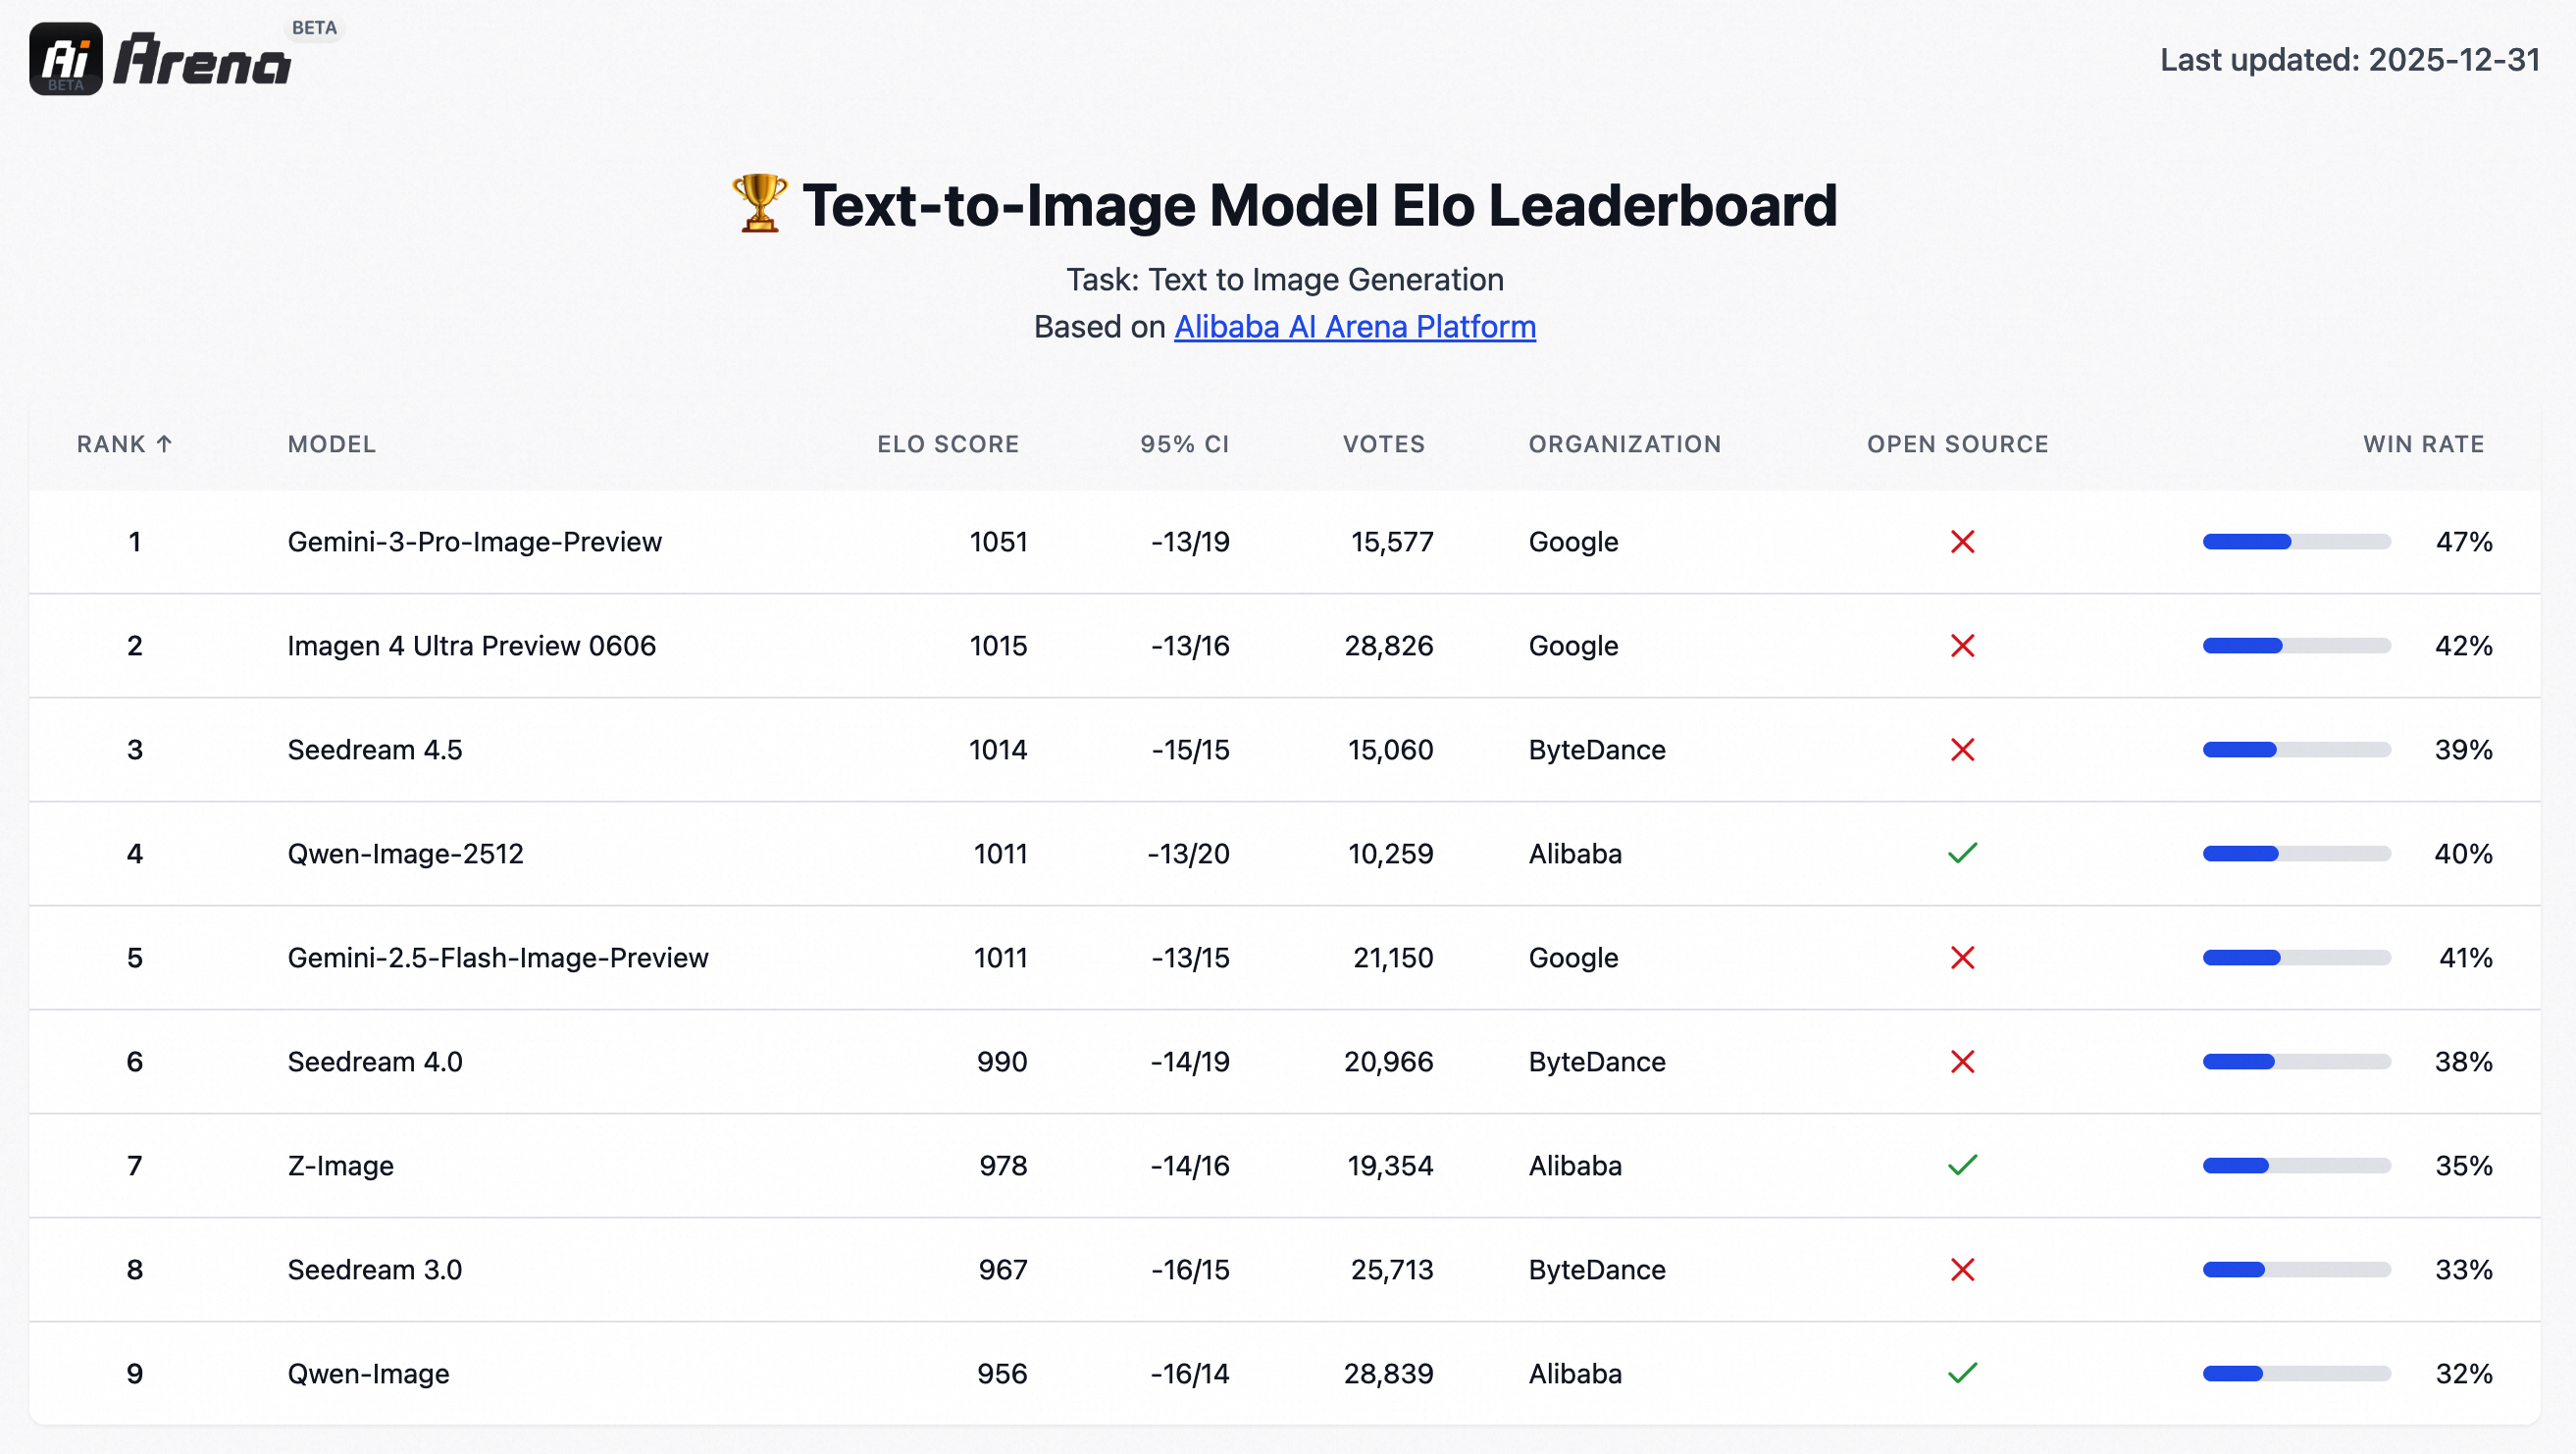
We conducted over 10,000 rounds of blind model evaluations on AI Arena , and the results show that Qwen-Image-2512 is currently the strongest open-source model—while remaining highly competitive even among closed-source models.
Install the latest version of diffusers
pip install git+https://github.com/huggingface/diffusers
The following contains a code snippet illustrating how to use
Qwen-Image-2512
:
from diffusers import DiffusionPipeline
import torch

model_name = "Qwen/Qwen-Image-2512"

# Load the pipeline
if torch.cuda.is_available():
    torch_dtype = torch.bfloat16
    device = "cuda"
else:
    torch_dtype = torch.float32
    device = "cpu"

pipe = DiffusionPipeline.from_pretrained(model_name, torch_dtype=torch_dtype).to(device)

# Generate image
prompt = '''A 20-year-old East Asian girl with delicate, charming features and large, bright brown eyes—expressive and lively, with a cheerful or subtly smiling expression. Her naturally wavy long hair is either loose or tied in twin ponytails. She has fair skin and light makeup accentuating her youthful freshness. She wears a modern, cute dress or relaxed outfit in bright, soft colors—lightweight fabric, minimalist cut. She stands indoors at an anime convention, surrounded by banners, posters, or stalls. Lighting is typical indoor illumination—no staged lighting—and the image resembles a casual iPhone snapshot: unpretentious composition, yet brimming with vivid, fresh, youthful charm.'''

negative_prompt = "低分辨率,低画质,肢体畸形,手指畸形,画面过饱和,蜡像感,人脸无细节,过度光滑,画面具有AI感。构图混乱。文字模糊,扭曲。"


# Generate with different aspect ratios
aspect_ratios = {
    "1:1": (1328, 1328),
    "16:9": (1664, 928),
    "9:16": (928, 1664),
    "4:3": (1472, 1104),
    "3:4": (1104, 1472),
    "3:2": (1584, 1056),
    "2:3": (1056, 1584),
}

width, height = aspect_ratios["16:9"]

image = pipe(
    prompt=prompt,
    negative_prompt=negative_prompt,
    width=width,
    height=height,
    num_inference_steps=50,
    true_cfg_scale=4.0,
    generator=torch.Generator(device="cuda").manual_seed(42)
).images[0]

image.save("example.png")
Enhanced Huamn Realism
In Qwen-Image-2512, human depiction has been substantially refined. Compared to the August release, Qwen-Image-2512 adds significantly richer facial details and better environmental context. For example:
A Chinese female college student, around 20 years old, with a very short haircut that conveys a gentle, artistic vibe. Her hair naturally falls to partially cover her cheeks, projecting a tomboyish yet charming demeanor. She has cool-toned fair skin and delicate features, with a slightly shy yet subtly confident expression—her mouth crooked in a playful, youthful smirk. She wears an off-shoulder top, revealing one shoulder, with a well-proportioned figure. The image is framed as a close-up selfie: she dominates the foreground, while the background clearly shows her dormitory—a neatly made bed with white linens on the top bunk, a tidy study desk with organized stationery, and wooden cabinets and drawers. The photo is captured on a smartphone under soft, even ambient lighting, with natural tones, high clarity, and a bright, lively atmosphere full of youthful, everyday energy.
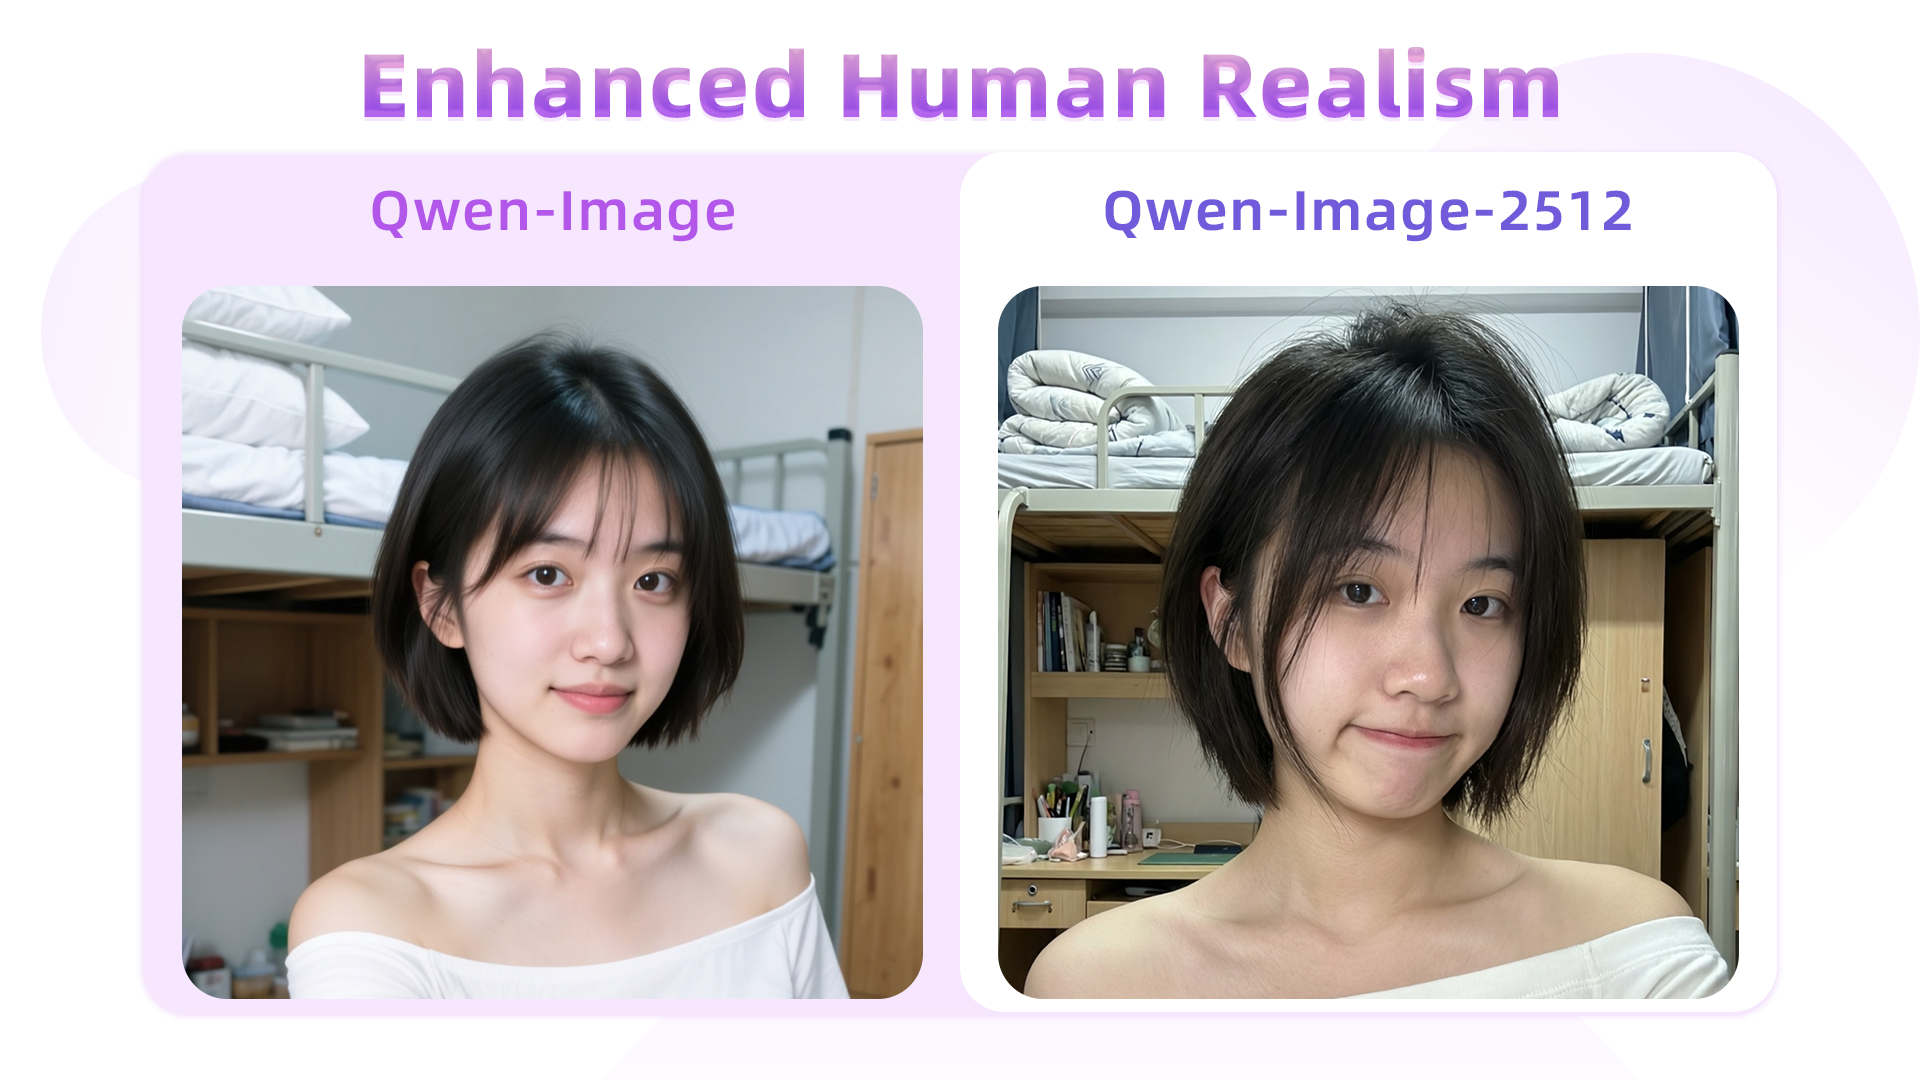
For the same prompt, Qwen-Image-2512 yields notably more lifelike facial features, and background objects—e.g., the desk, stationery, and bedding—are rendered with significantly greater clarity than in Qwen-Image.
A 20-year-old East Asian girl with delicate, charming features and large, bright brown eyes—expressive and lively, with a cheerful or subtly smiling expression. Her naturally wavy long hair is either loose or tied in twin ponytails. She has fair skin and light makeup accentuating her youthful freshness. She wears a modern, cute dress or relaxed outfit in bright, soft colors—lightweight fabric, minimalist cut. She stands indoors at an anime convention, surrounded by banners, posters, or stalls. Lighting is typical indoor illumination—no staged lighting—and the image resembles a casual iPhone snapshot: unpretentious composition, yet brimming with vivid, fresh, youthful charm.
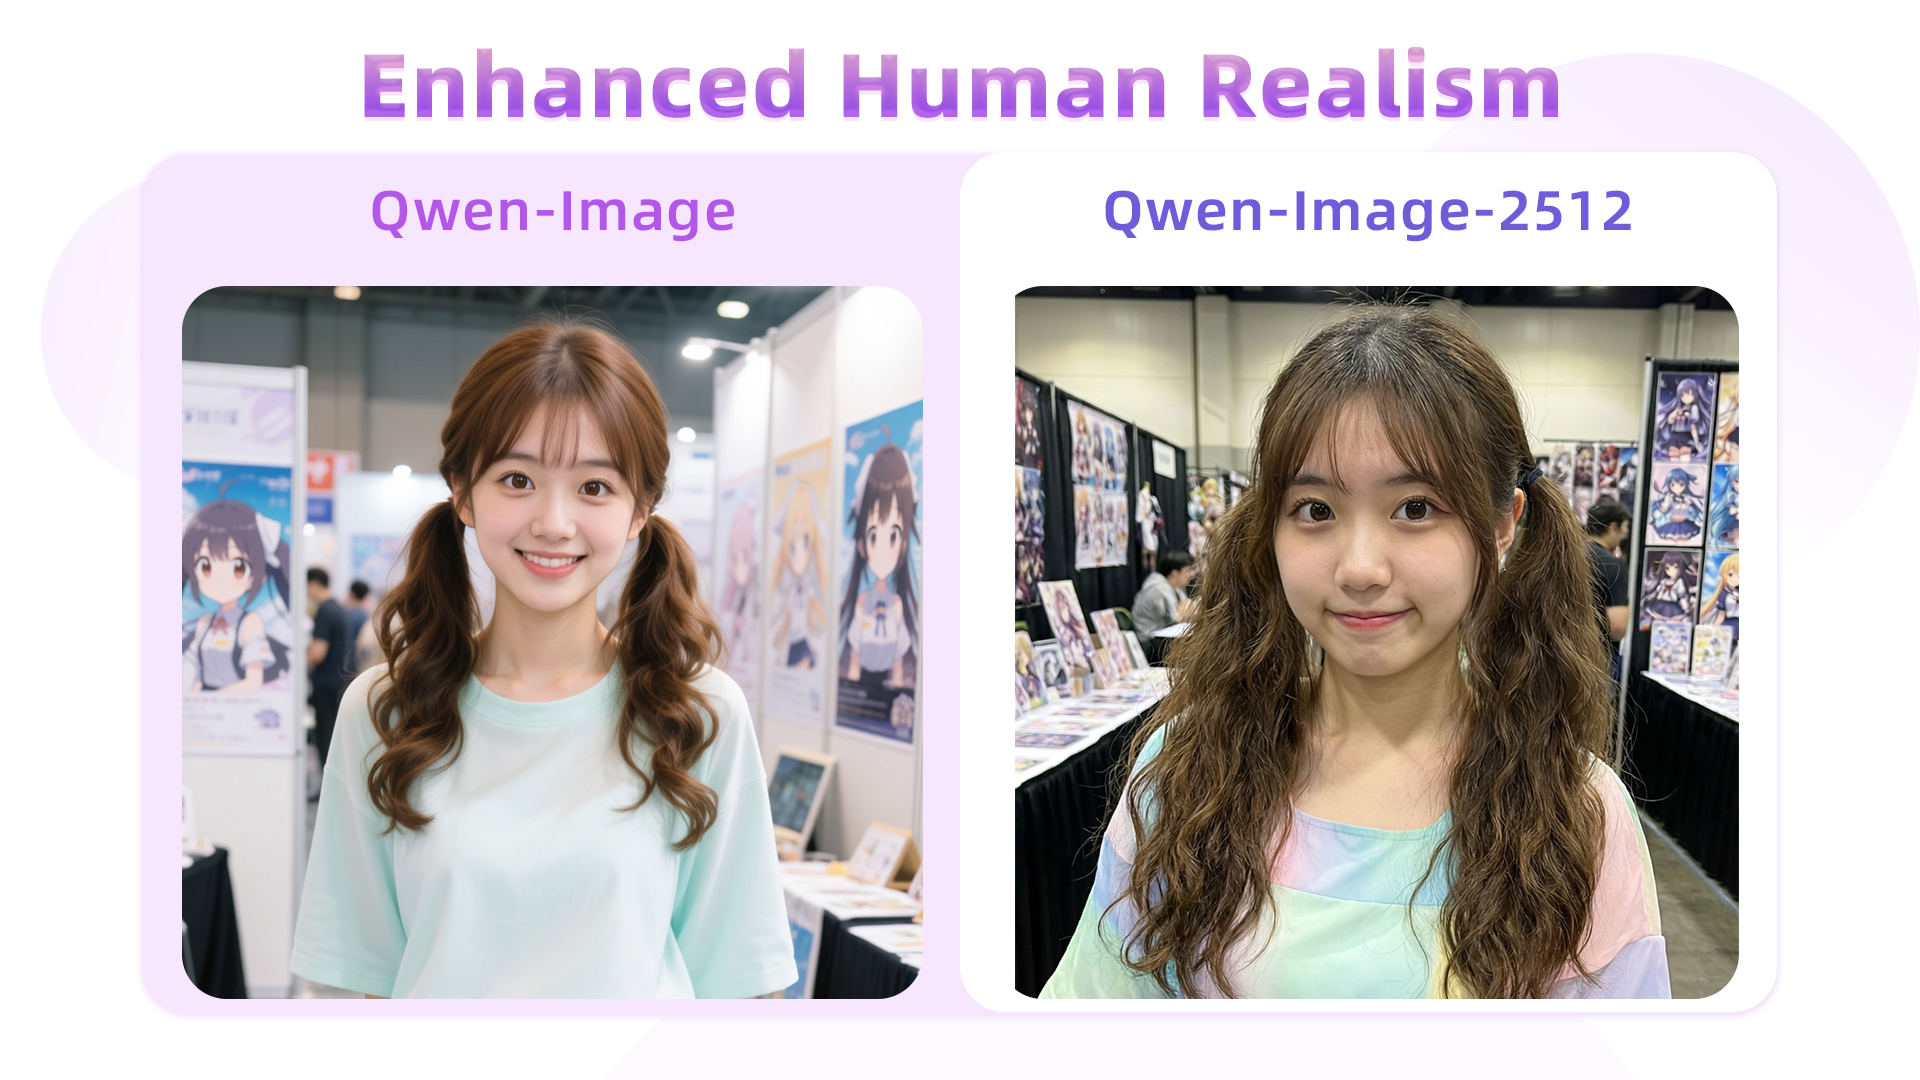
Here, hair strands serve as a key differentiator: Qwen-Image’s August version tends to blur them together, losing fine detail, whereas Qwen-Image-2512 renders individual strands with precision, resulting in a more natural and realistic appearance.
Another case:
An East Asian teenage boy, aged 15–18, with soft, fluffy black short hair and refined facial contours. His large, warm brown eyes sparkle with energy. His fair skin and sunny, open smile convey an approachable, friendly demeanor—no makeup or blemishes. He wears a blue-and-white summer uniform shirt, slightly unbuttoned, made of thin breathable fabric, with black headphones hanging around his neck. His hands are in his pockets, body leaning slightly forward in a relaxed pose, as if engaged in conversation. Behind him lies a summer school playground: lush green grass and a red rubber track in the foreground, blurred school buildings in the distance, a clear blue sky with fluffy white clouds. The bright, airy lighting evokes a joyful, carefree adolescent atmosphere.
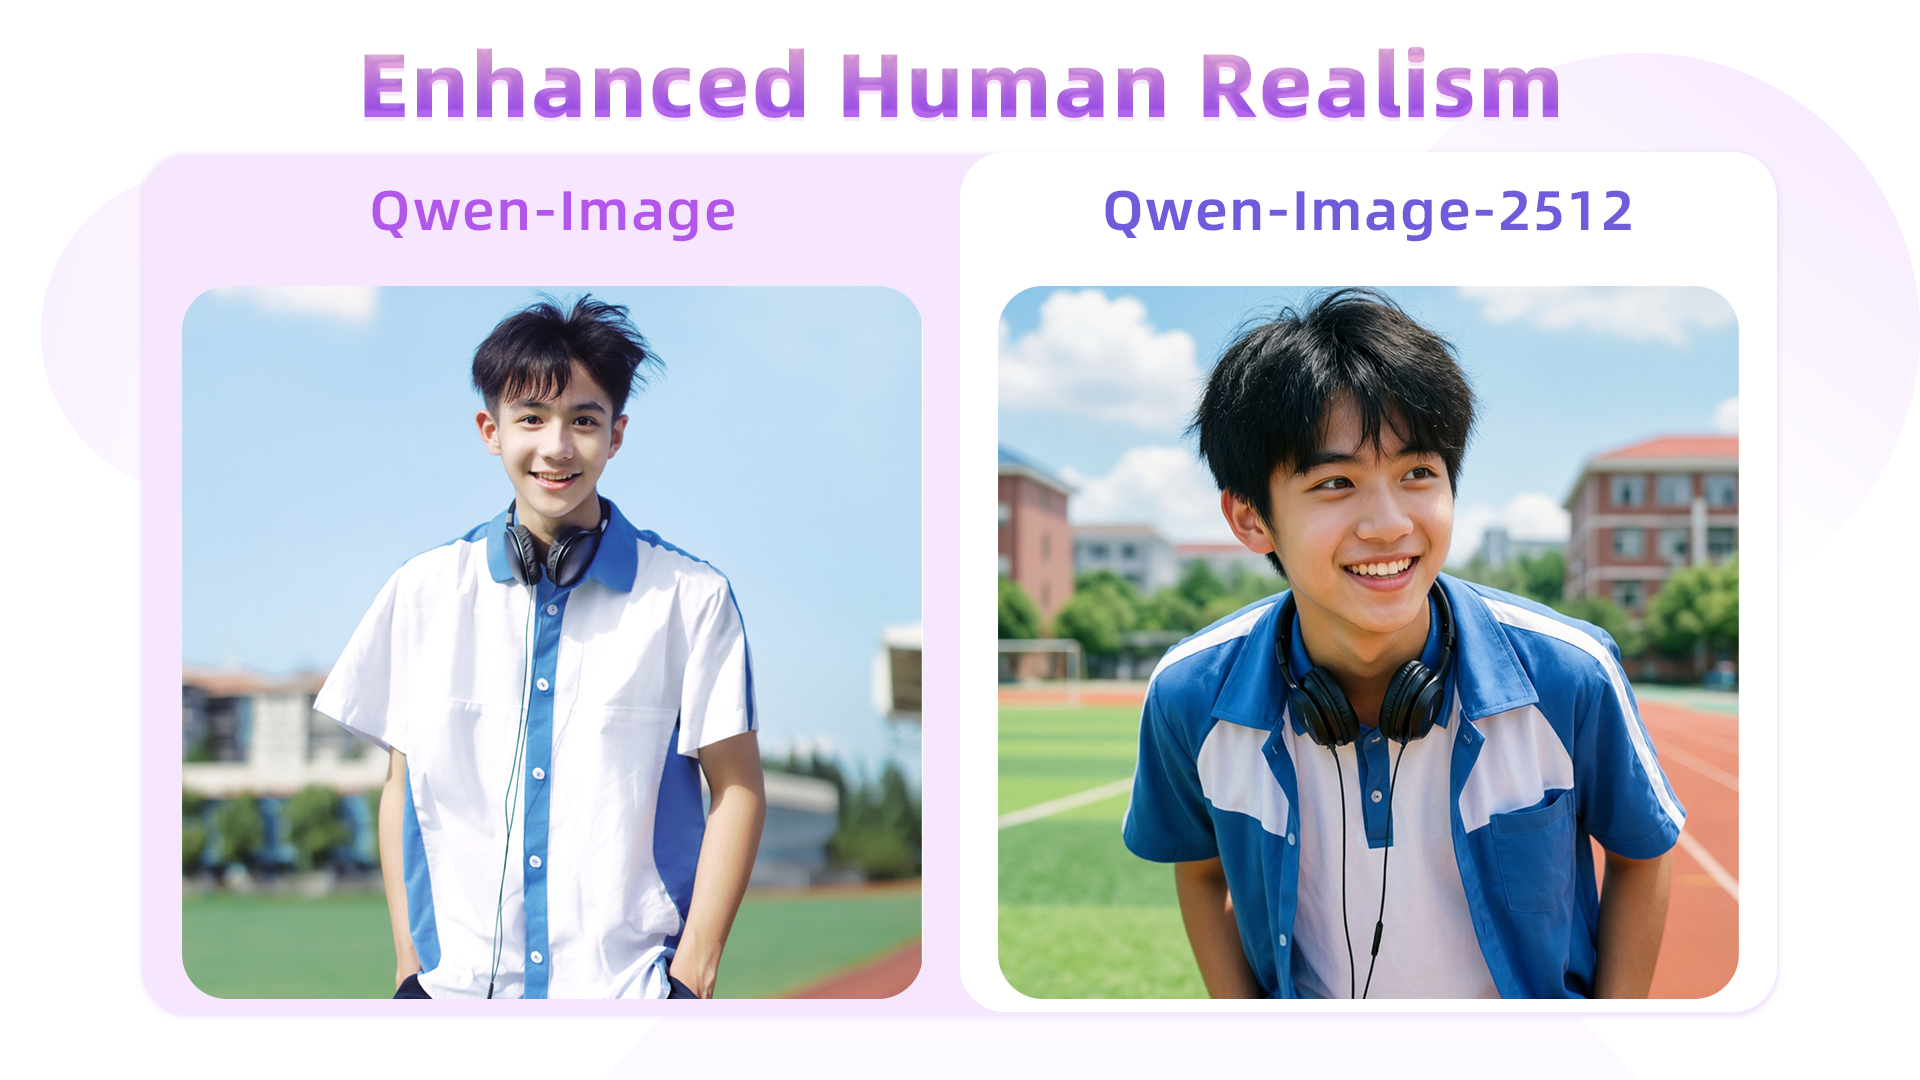
In this example, Qwen-Image-2512 better adheres to semantic instructions—for instance, the prompt specifies “body leaning slightly forward,” and Qwen-Image-2512 accurately captures this posture, unlike its predecessor.
An elderly Chinese couple in their 70s in a clean, organized home kitchen. The woman has a kind face and a warm smile, wearing a patterned apron; the man stands behind her, also smiling, as they both gaze at a steaming pot of buns on the stove. The kitchen is bright and tidy, exuding warmth and harmony. The scene is captured with a wide-angle lens to fully show the subjects and their surroundings.
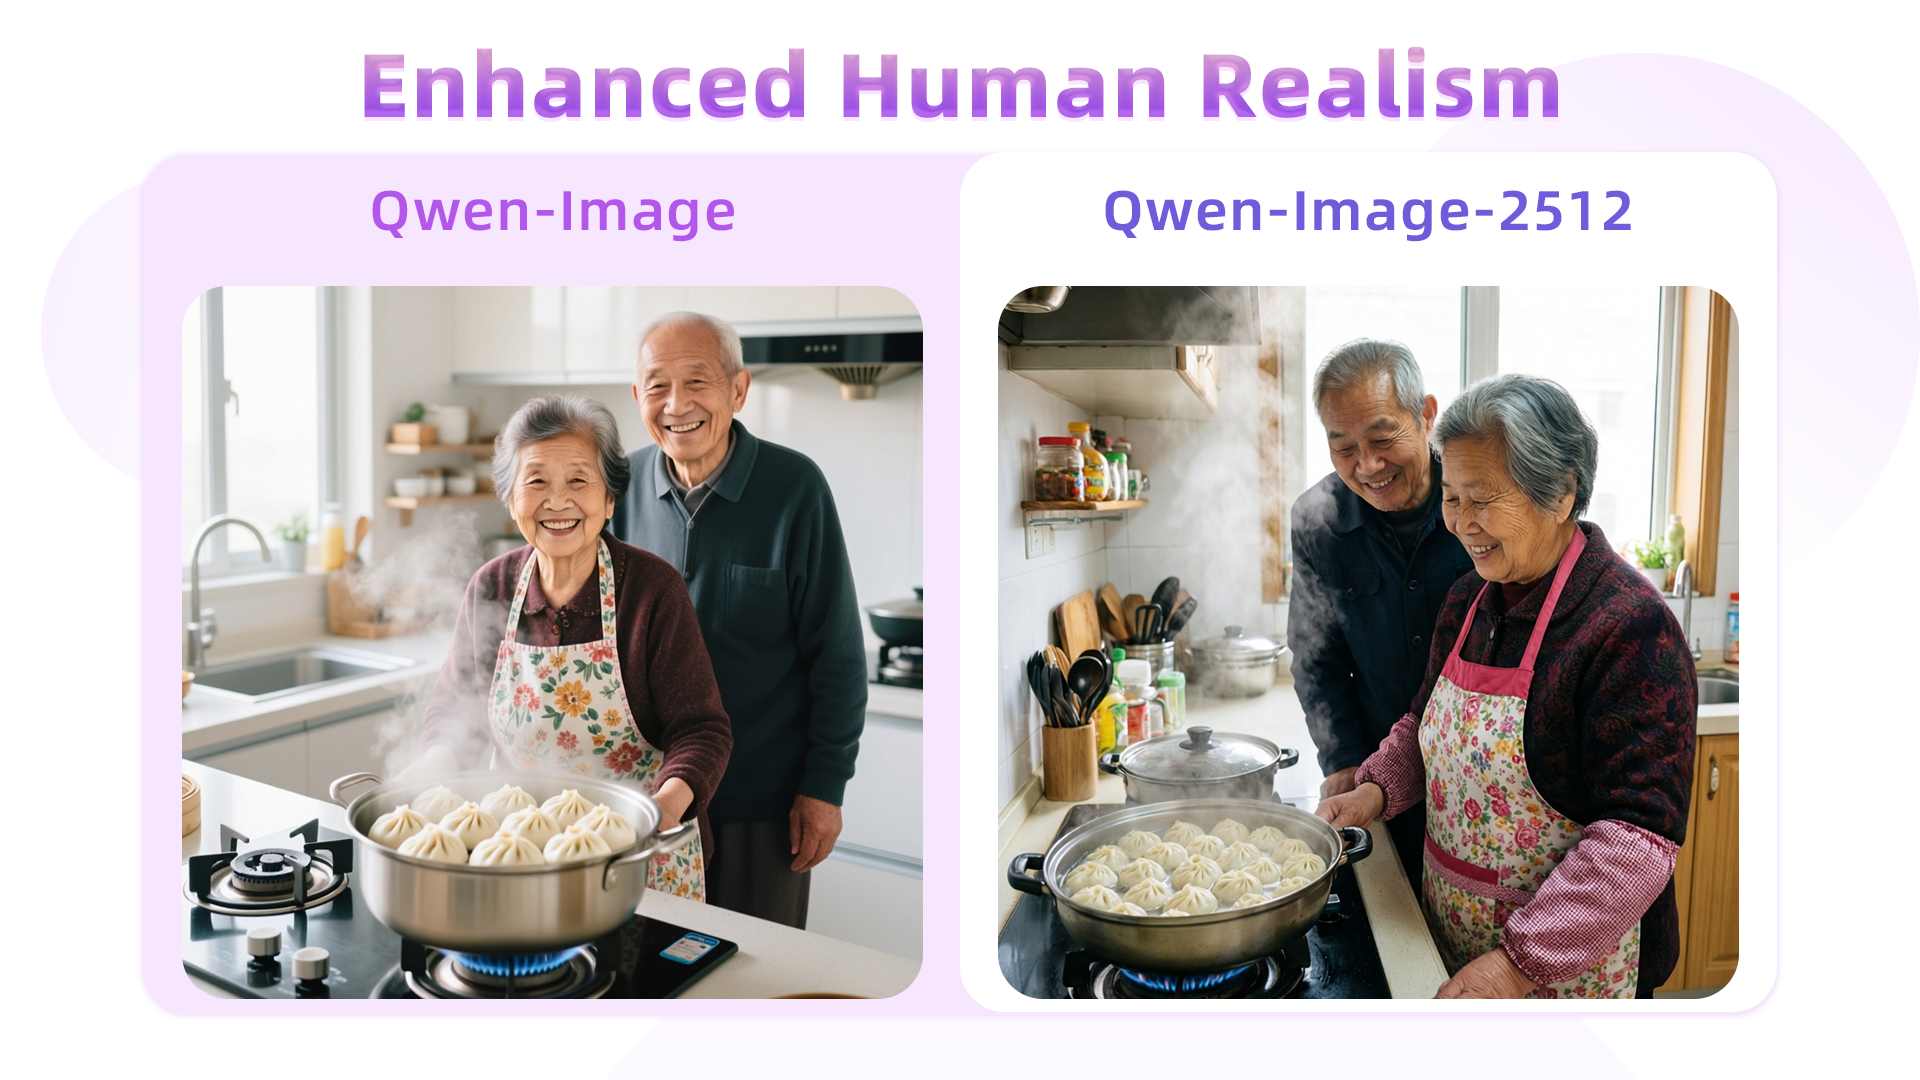
This comparison starkly highlights the gap between the August and December models. The original Qwen-Image struggles to accurately render aged facial features (e.g., wrinkles), resulting in an artificial “AI look.” In contrast, Qwen-Image-2512 precisely captures age cues, dramatically boosting realism.
Finer Natural Detail
Qwen-Image-2512’s enhanced detail rendering extends beyond humans—to landscapes, wildlife, and more. For instance:
A turquoise river winds through a lush canyon. Thick moss and dense ferns blanket the rocky walls; multiple waterfalls cascade from above, enveloped in mist. At noon, sunlight filters through the dense canopy, dappling the river surface with shimmering light. The atmosphere is humid and fresh, pulsing with primal jungle vitality. No humans, text, or artificial traces present.
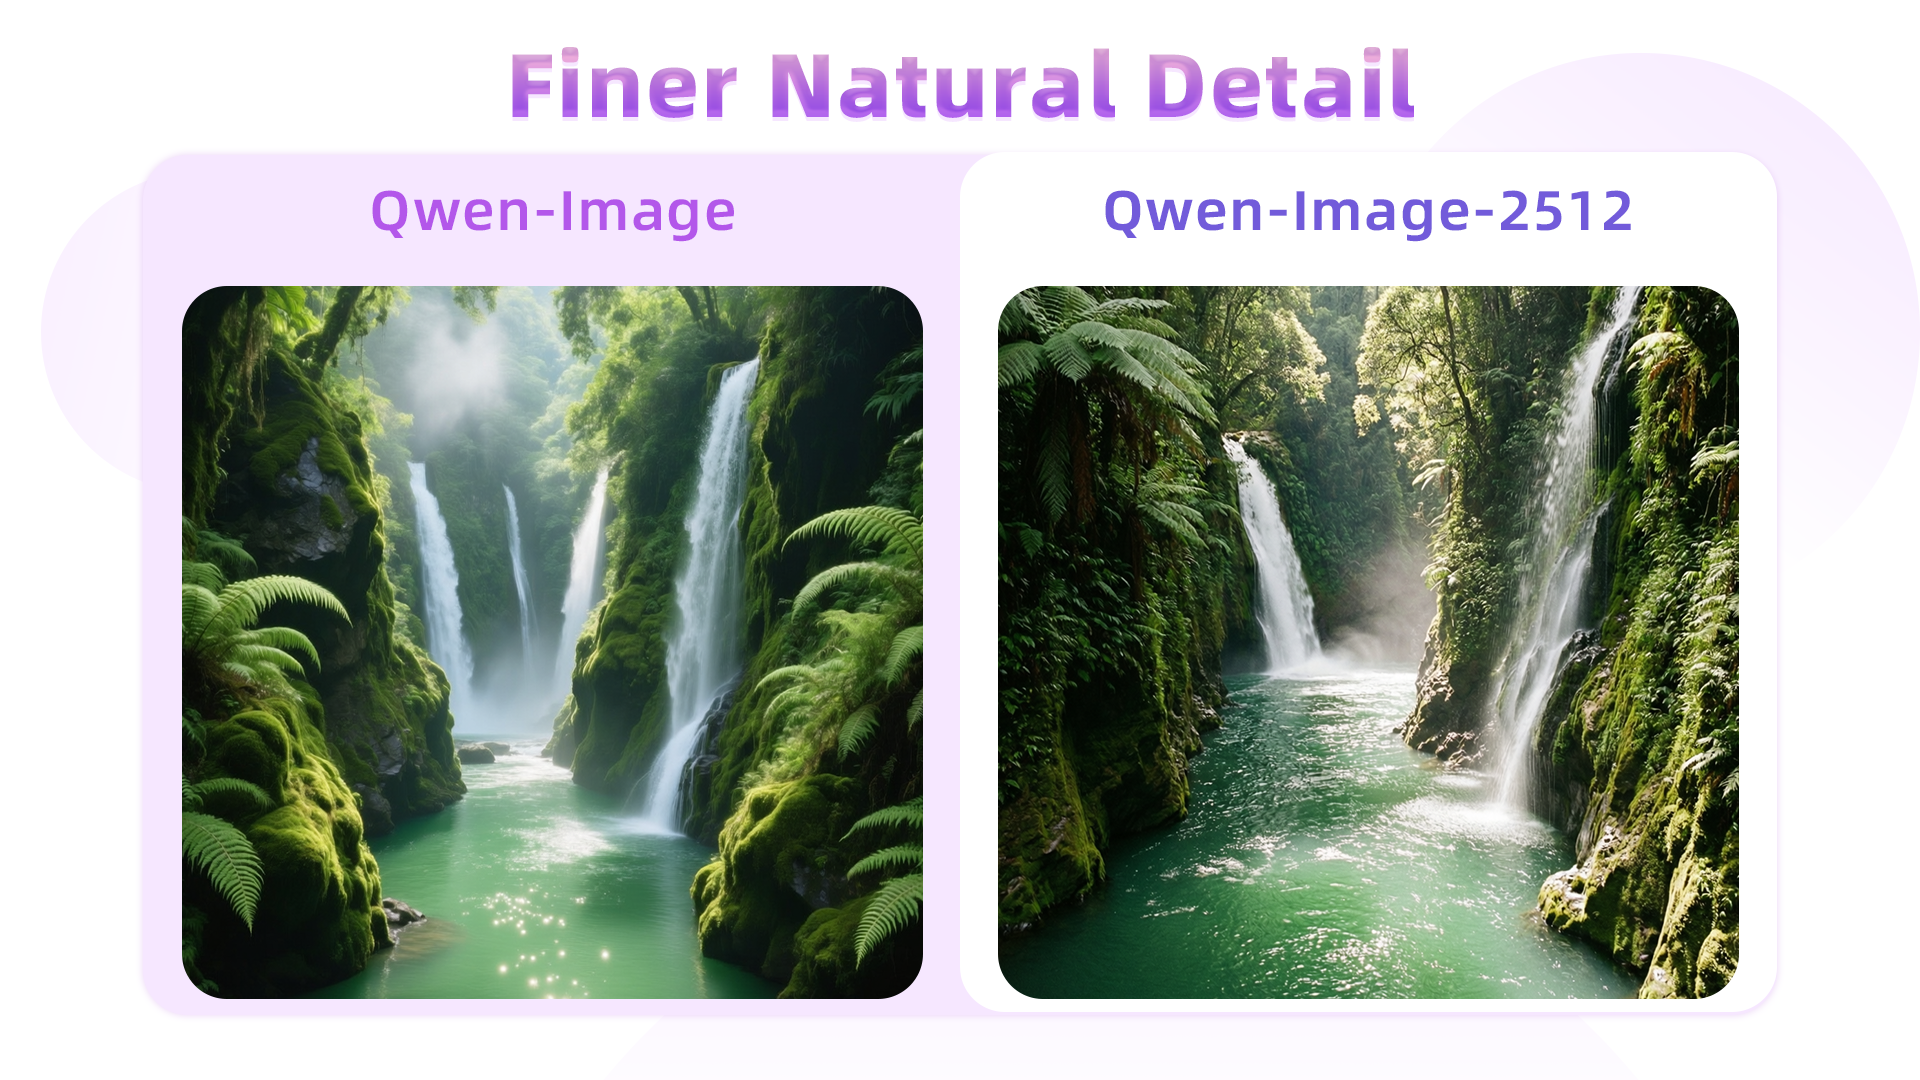
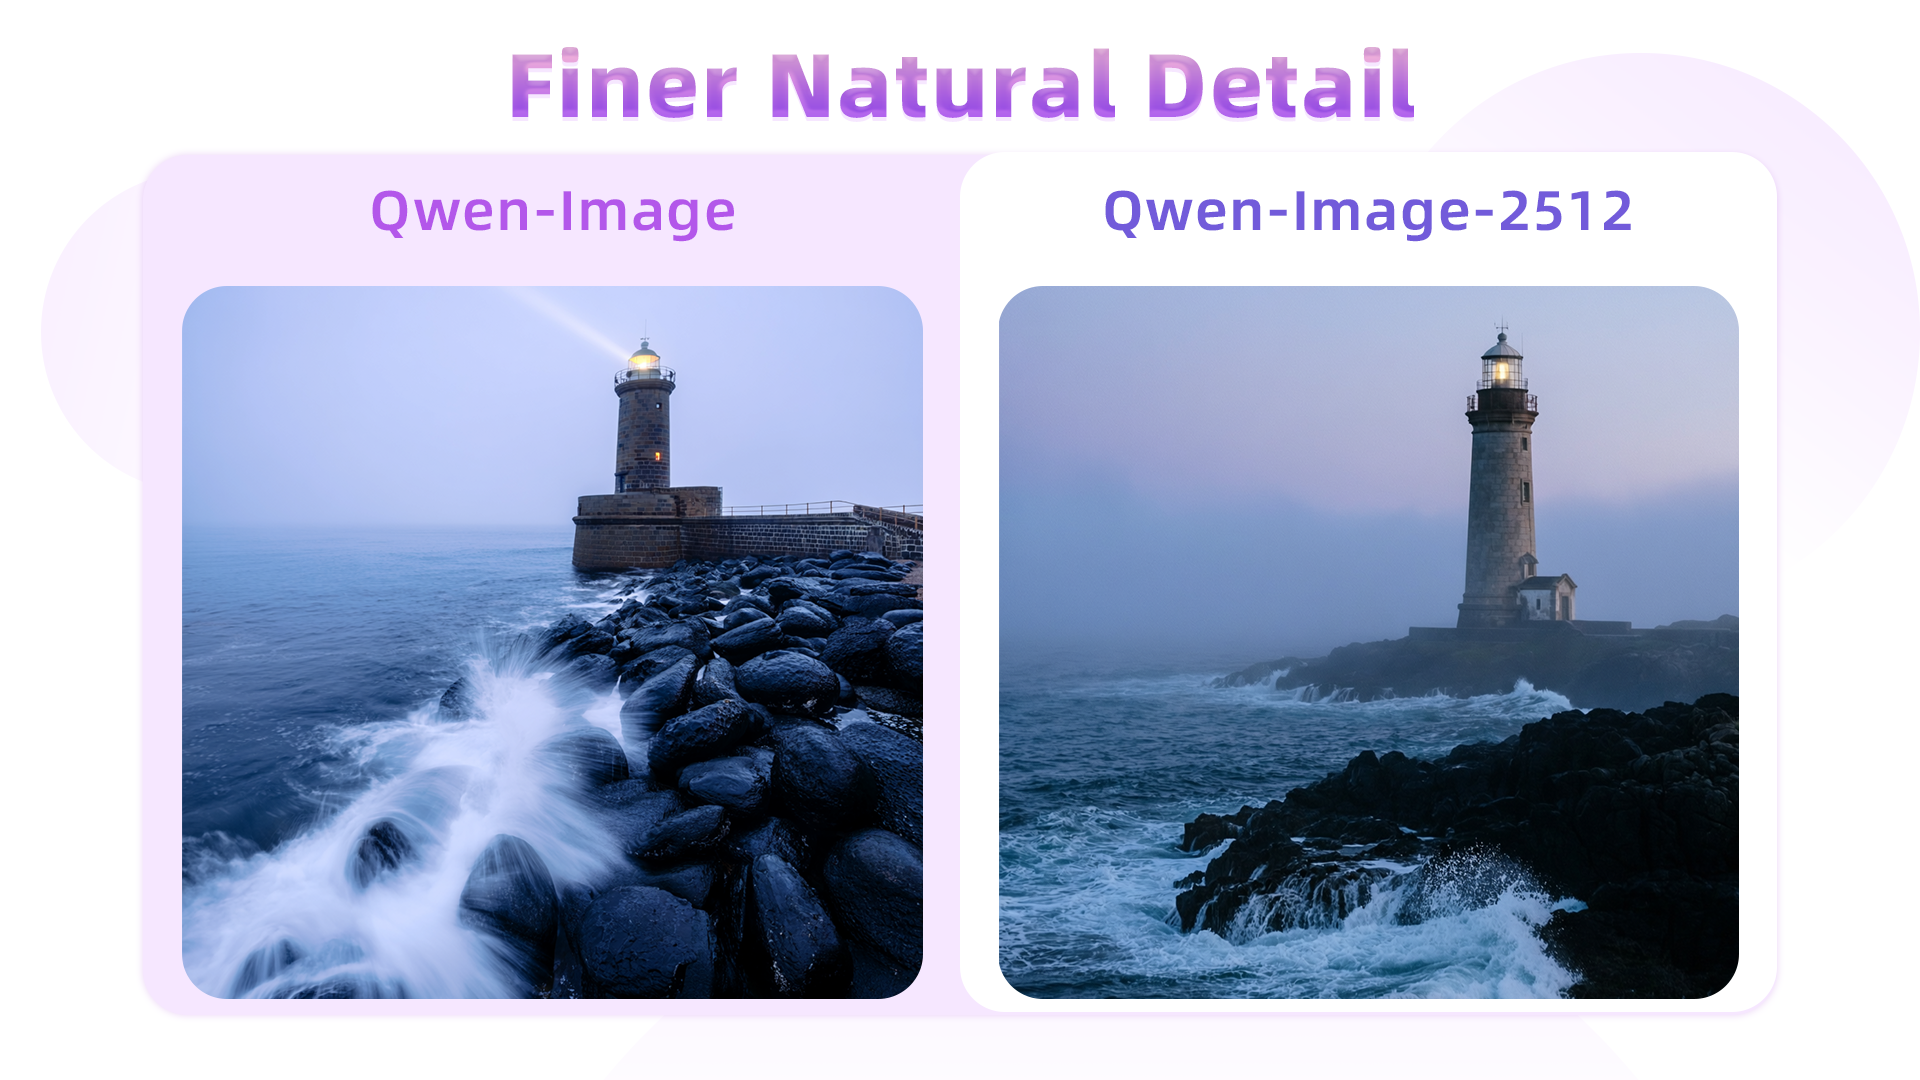
Side-by-side, Qwen-Image-2512 exhibits superior fidelity in water flow, foliage, and waterfall mist—and renders richer gradation in greens. Another example (wave rendering):
At dawn, a thin mist veils the sea. An ancient stone lighthouse stands at the cliff’s edge, its beacon faintly visible through the fog. Black rocks are pounded by waves, sending up bursts of white spray. The sky glows in soft blue-purple hues under cool, hazy light—evoking solitude and solemn grandeur.
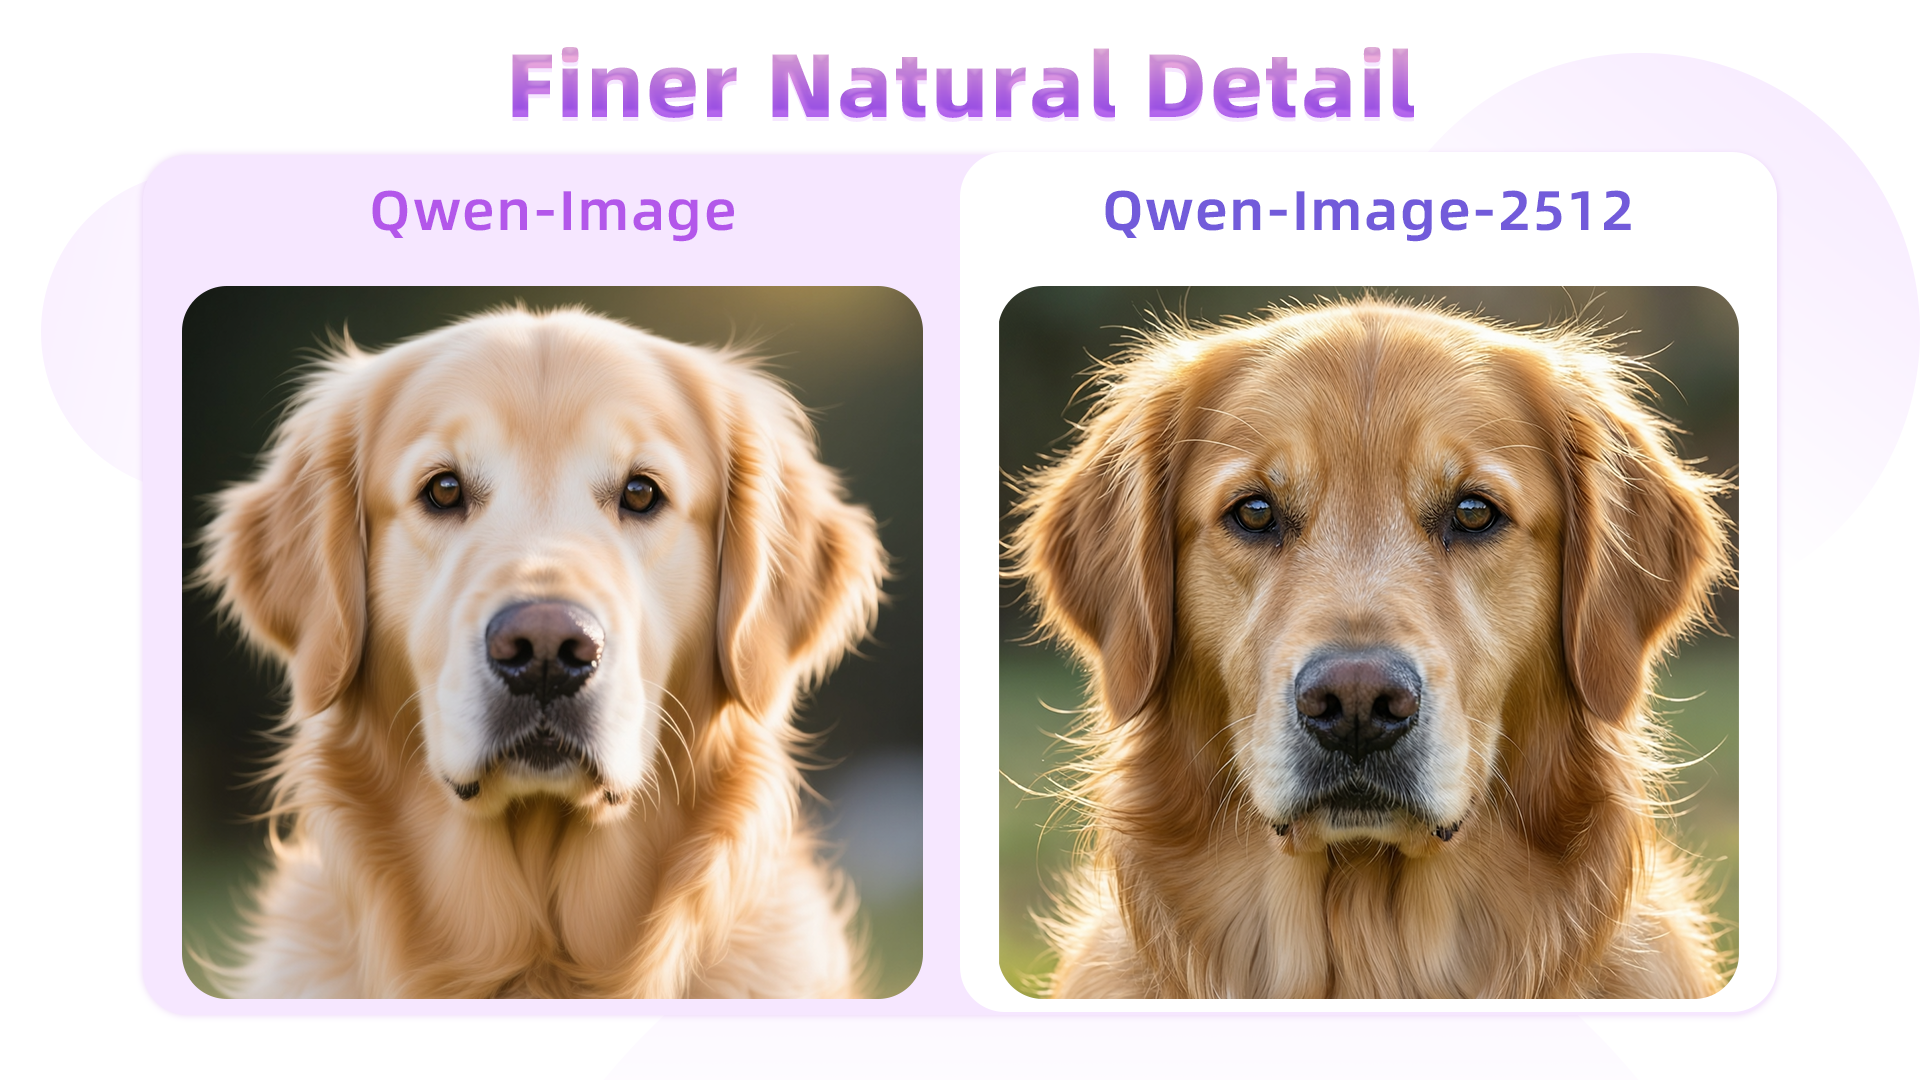
Fur detail is another highlight—here, a golden retriever portrait:
An ultra-realistic close-up of a golden retriever outdoors under soft daylight. Hair is exquisitely detailed: strands distinct, color transitioning naturally from warm gold to light cream, light glinting delicately at the tips; a gentle breeze adds subtle volume. Undercoat is soft and dense; guard hairs are long and well-defined, with visible layering. Eyes are moist, expressive; nose is slightly damp with fine specular highlights. Background is softly blurred to emphasize the dog’s tangible texture and vivid expression.
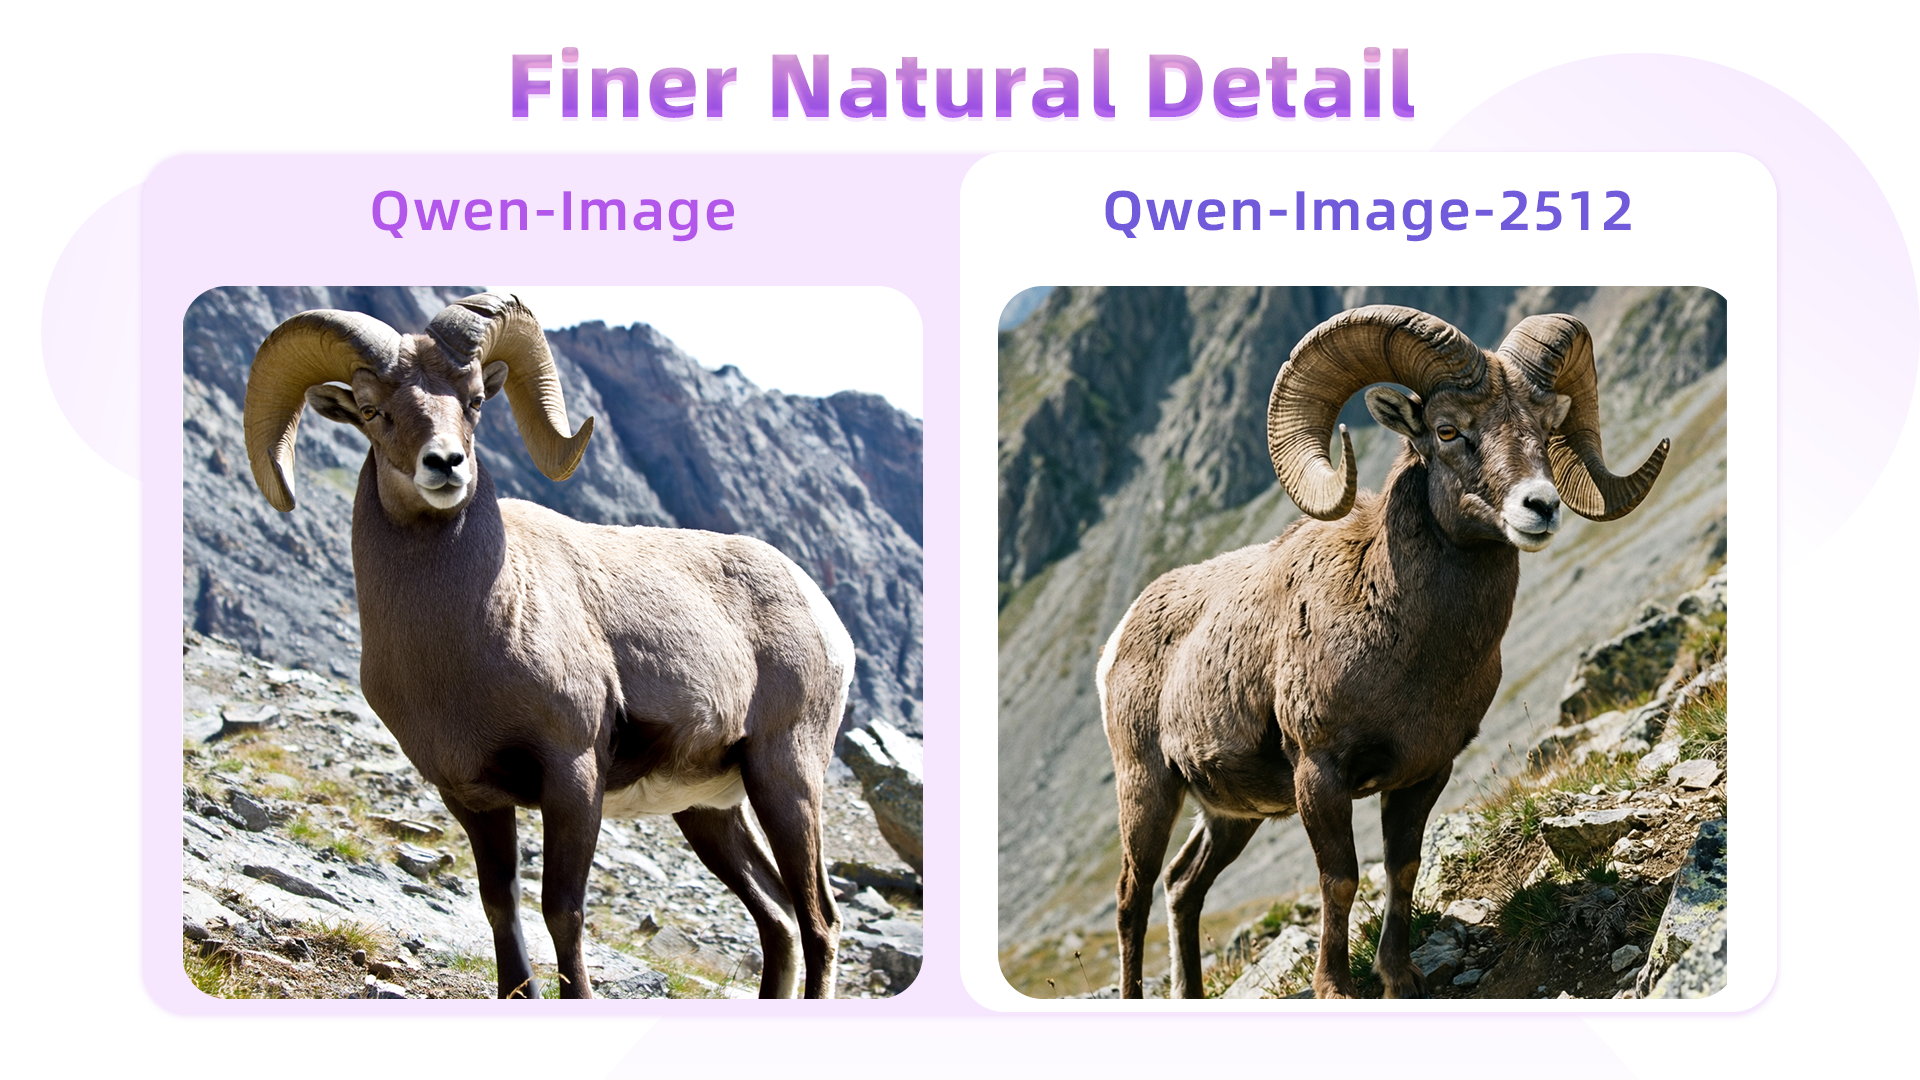
Similarly, texture quality improves in depictions of rugged wildlife—for example, a male argali sheep:
A male argali stands atop a barren, rocky mountainside. Its coarse, dense grey-brown coat covers a powerful, muscular body. Most striking are its massive, thick, outward-spiraling horns—a symbol of wild strength. Its gaze is alert and sharp. The background reveals steep alpine terrain: jagged peaks, sparse low vegetation, and abundant sunlight—conveying the harsh yet majestic wilderness and the animal’s resilient vitality.
Improved Text Rendering
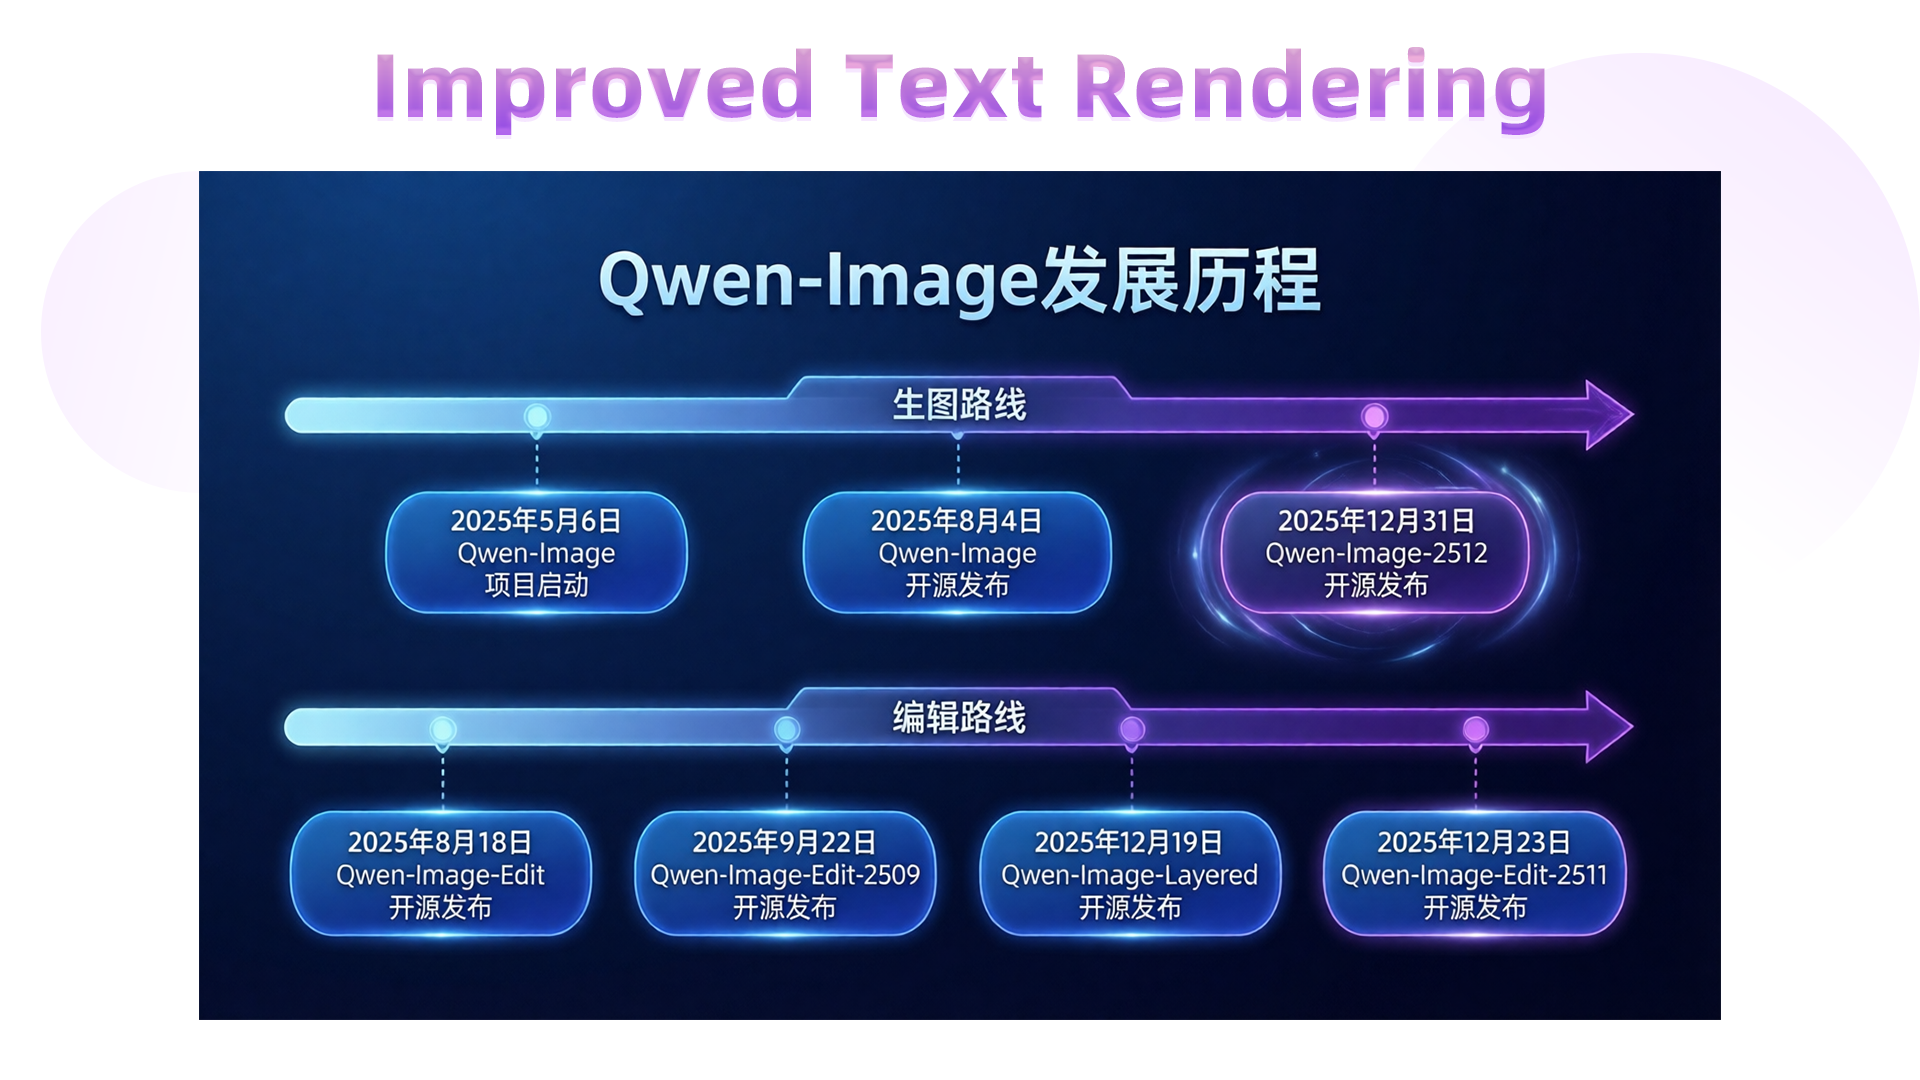
Qwen-Image-2512 further elevates text rendering—already a strength of the original—by improving accuracy, layout, and multimodal integration.
For instance, this prompt requests a complete PPT slide illustrating Qwen-Image’s development roadmap (generation and editing tracks):
这是一张现代风格的科技感幻灯片,整体采用深蓝色渐变背景。标题是“Qwen-Image发展历程”。下方一条水平延伸的发光时间轴,轴线中间写着“生图路线”。由左侧淡蓝色渐变为右侧深紫色,并以精致的箭头收尾。时间轴上每个节点通过虚线连接至下方醒目的蓝色圆角矩形日期标签,标签内为清晰白色字体,从左向右依次写着:“2025年5月6日 Qwen-Image 项目启动”“2025年8月4日 Qwen-Image 开源发布”“2025年12月31日 Qwen-Image-2512 开源发布” (周围光晕显著)在下方一条水平延伸的发光时间轴,轴线中间写着“编辑路线”。由左侧淡蓝色渐变为右侧深紫色,并以精致的箭头收尾。时间轴上每个节点通过虚线连接至下方醒目的蓝色圆角矩形日期标签,标签内为清晰白色字体,从左向右依次写着:“2025年8月18日 Qwen-Image-Edit 开源发布”“2025年9月22日 Qwen-Image-Edit-2509 开源发布”“2025年12月19日 Qwen-Image-Layered 开源发布”“2025年12月23日 Qwen-Image-Edit-2511 开源发布”
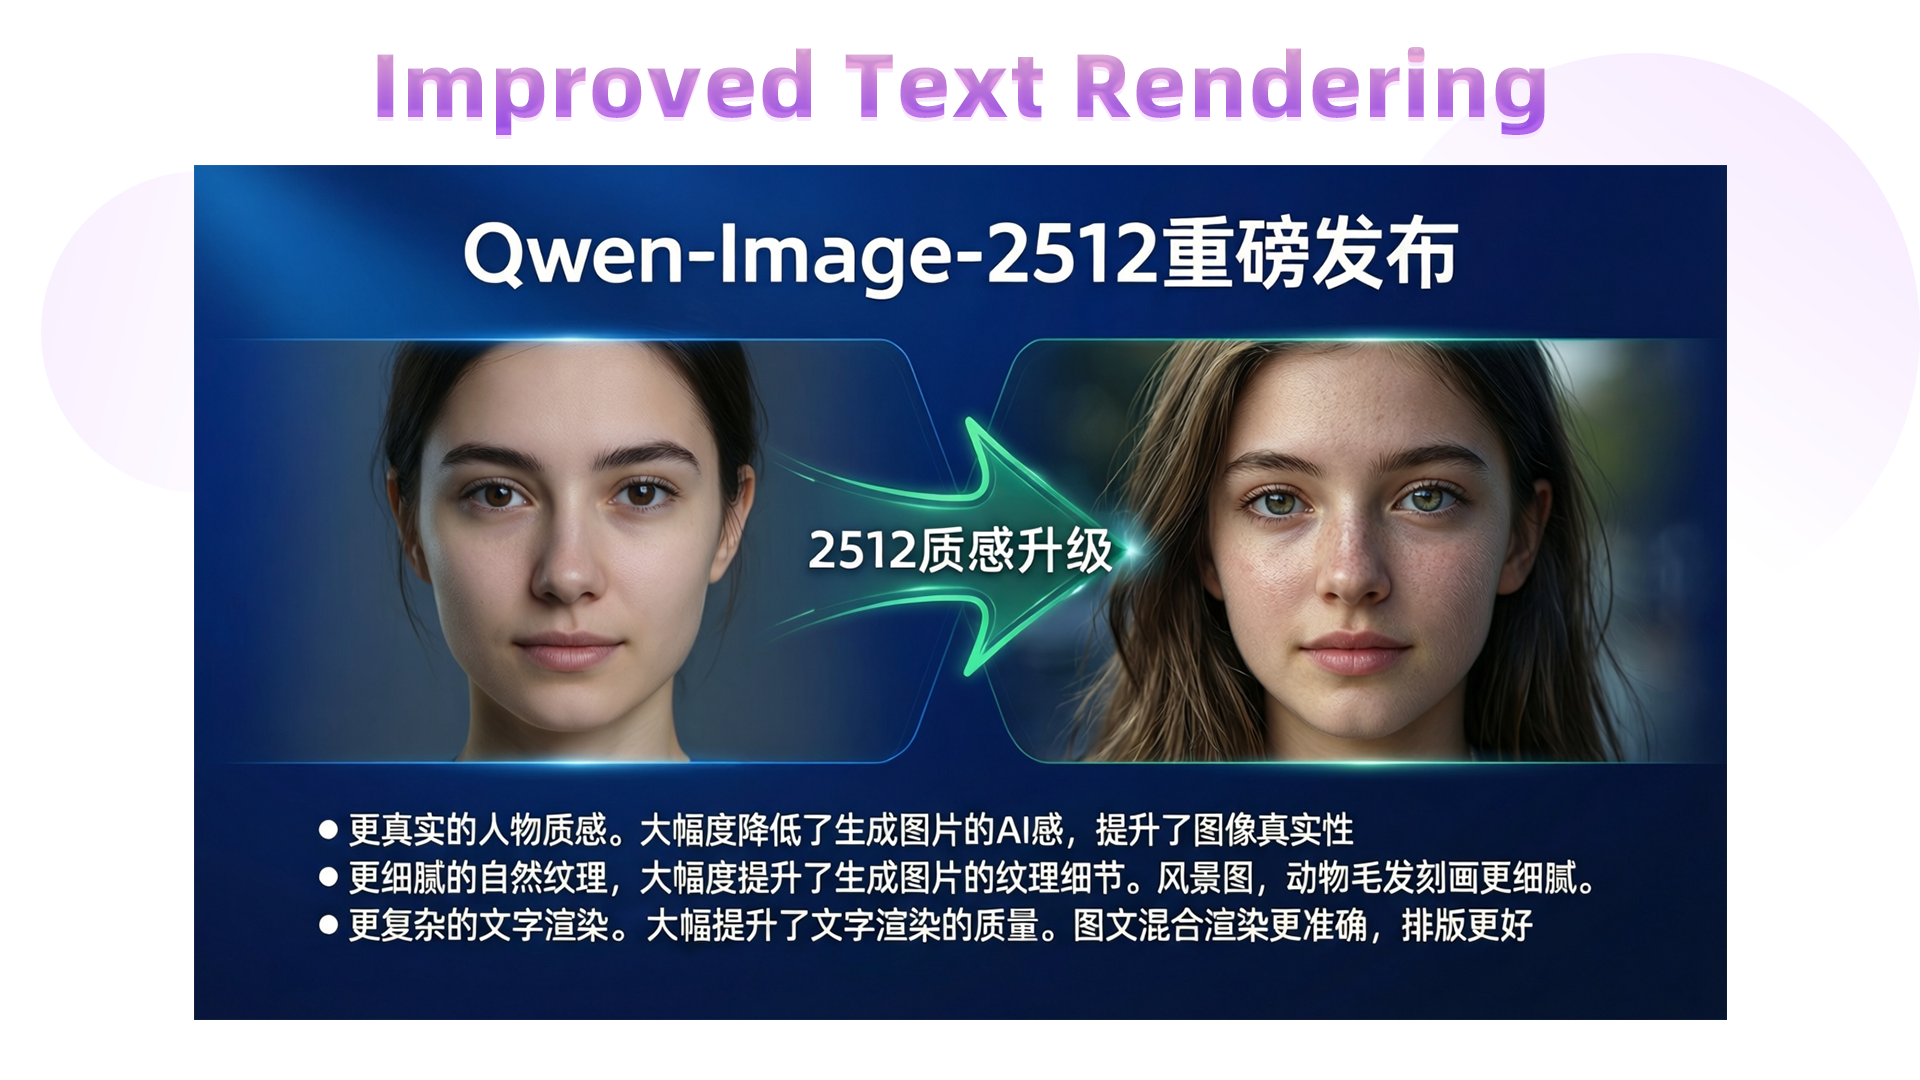
We can even generate a before-and-after comparison slide to highlight the leap from “AI-blurry” to “photorealistic”:
这是一张现代风格的科技感幻灯片,整体采用深蓝色渐变背景。顶部中央为白色无衬线粗体大字标题“Qwen-Image-2512重磅发布”。画面主体为横向对比图,视觉焦点集中于中间的升级对比区域。左侧为面部光滑没有任何细节的女性人像,质感差;右侧为高度写实的年轻女性肖像,皮肤呈现真实毛孔纹理与细微光影变化,发丝根根分明,眼眸透亮,表情自然,整体质感接近写实摄影。两图像之间以一个绿色流线型箭头链接。造型科技感十足,中部标注“2512质感升级”,使用白色加粗字体,居中显示。箭头两侧有微弱光晕效果,增强动态感。在图像下方,以白色文字呈现三行说明:“● 更真实的人物质感。大幅度降低了生成图片的AI感,提升了图像真实性 ● 更细腻的自然纹理。大幅度提升了生成图片的纹理细节。风景图,动物毛发刻画更细腻。● 更复杂的文字渲染。大幅提升了文字渲染的质量。图文混合渲染更准确,排版更好”
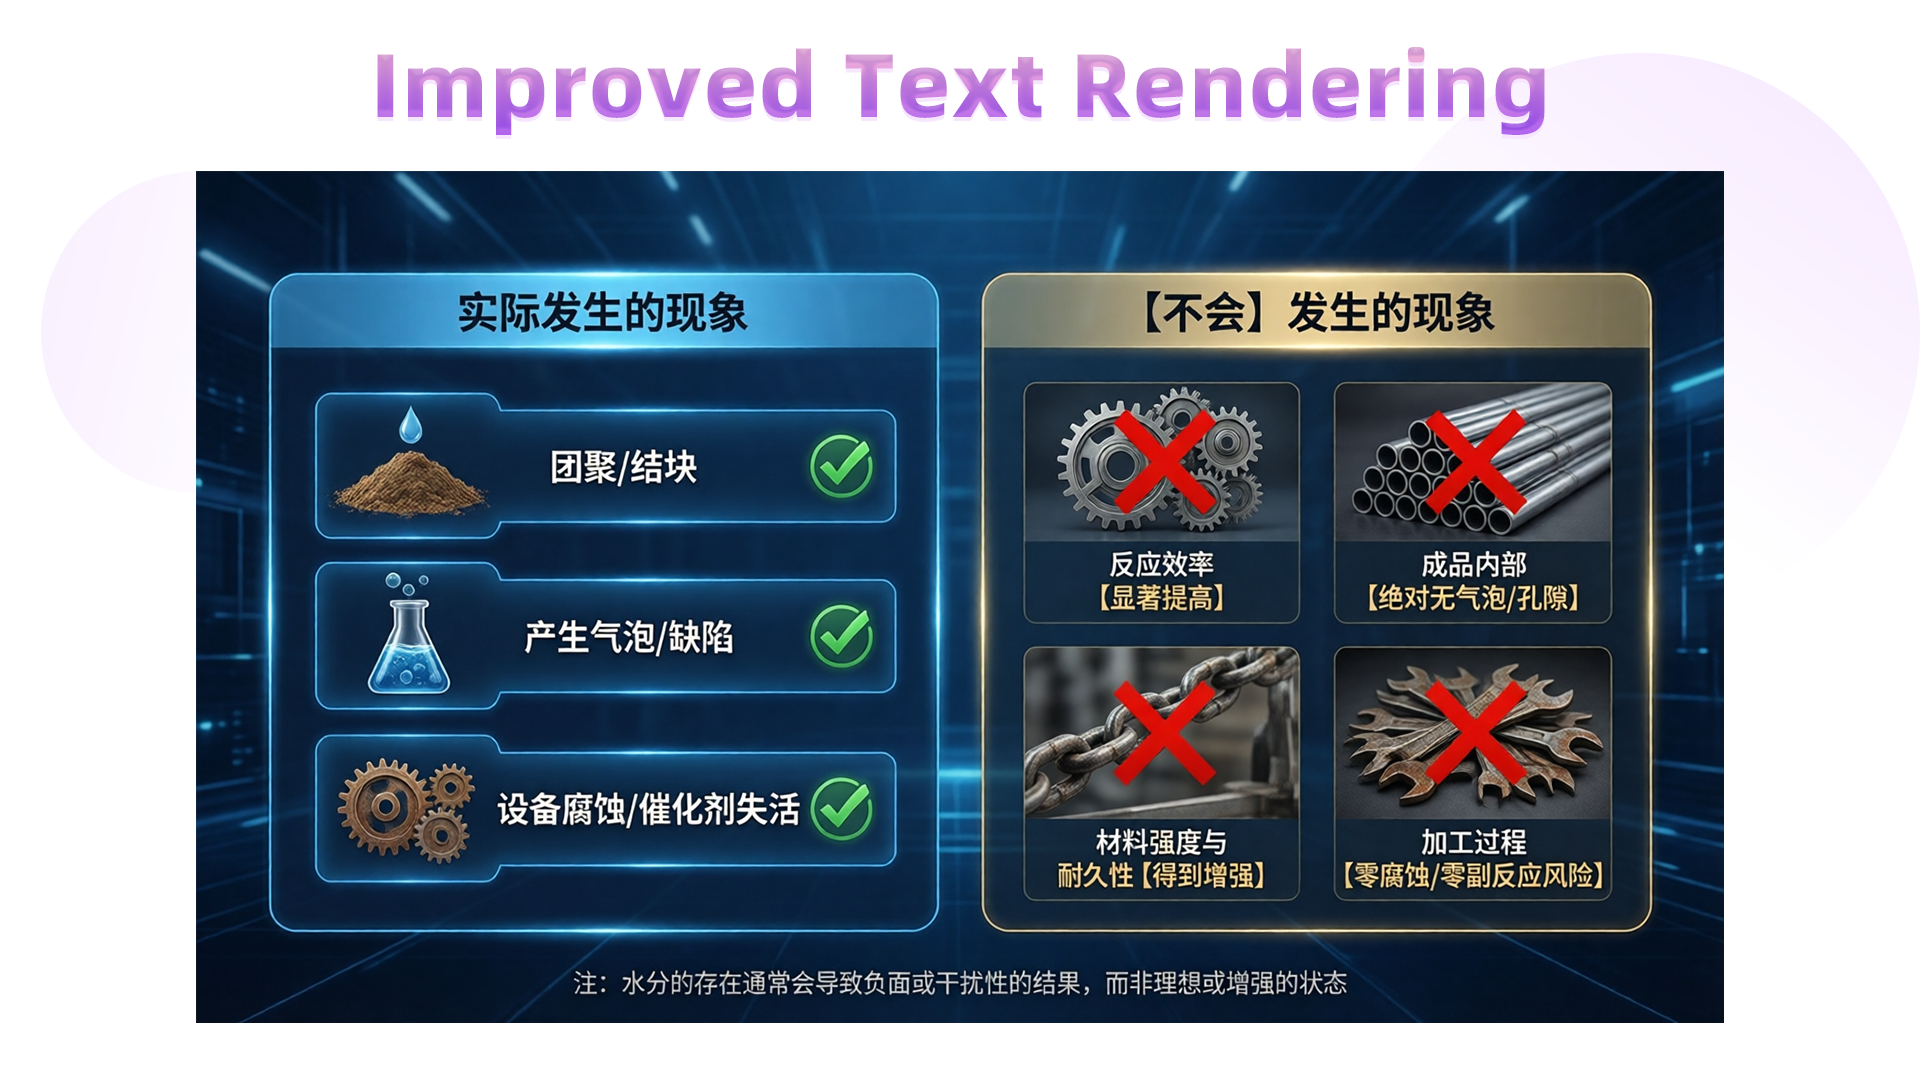
A more complex infographic example:
这是一幅专业级工业技术信息图表,整体采用深蓝色科技感背景,光线均匀柔和,营造出冷静、精准的现代工业氛围。画面分为左右两大板块,布局清晰,视觉层次分明。左侧板块标题为“实际发生的现象”,以浅蓝色圆角矩形框突出显示,内部排列三个深蓝色按钮式条目,第一个条目展示一堆棕色粉末状原料上滴落水滴的图标,文字为“团聚/结块”,后面配有绿色对钩;第二个条目为一个装有蓝色液体并冒出气泡的锥形瓶,文字为“产生气泡/缺陷”,后面配有绿色对钩;第三个条目为两个生锈的齿轮,文字为“设备腐蚀/催化剂失活”,后面配有绿色对钩。右侧板块标题为“【不会】发生的现象”,使用米黄色圆角矩形框呈现,内部四个条目均置于深灰色背景方框中。图标分别为:一组精密啮合的金属齿轮,文字为“反应效率【显著提高】”,上方覆盖醒目的红色叉号;一捆整齐排列的金属管材,文字为“成品内部【绝对无气泡/孔隙】”,上方覆盖醒目的红色叉号;一条坚固的金属链条正在承受拉力,文字为“材料强度与耐久性【得到增强】”,上方覆盖醒目的红色叉号;一堆腐蚀的扳手,文字为“加工过程【零腐蚀/零副反应风险】”,上方覆盖醒目的红色叉号。底部中央有一行小字注释:“注:水分的存在通常会导致负面或干扰性的结果,而非理想或增强的状态”,字体为白色,清晰可读。整体风格现代简约,配色对比强烈,图形符号准确传达技术逻辑,适合用于工业培训或科普演示场景。
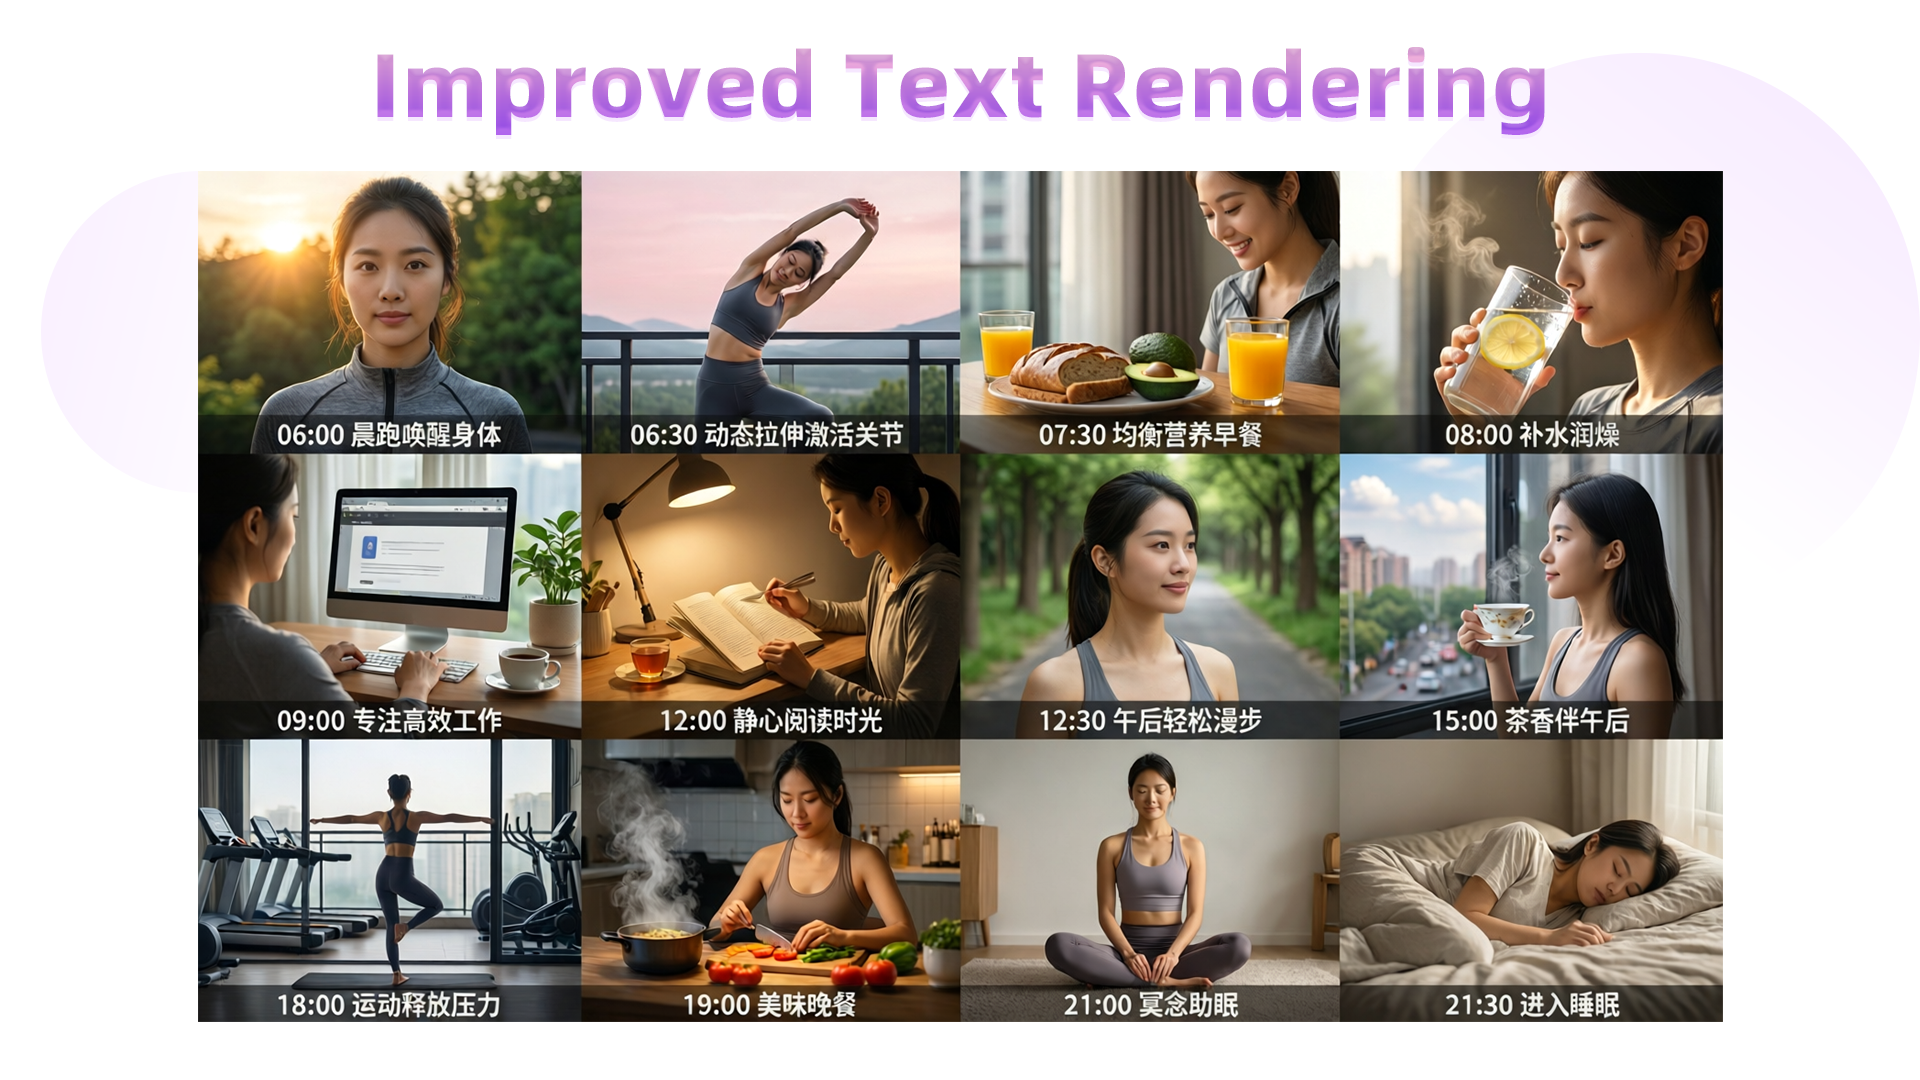
Or even a full educational poster:
这是一幅由十二个分格组成的3×4网格布局的写实摄影作品,整体呈现“健康的一天”主题,画面风格简洁清晰,每一分格独立成景又统一于生活节奏的叙事脉络。第一行分别是“06:00 晨跑唤醒身体”:面部特写,一位女性身穿灰色运动套装,背景是初升的朝阳与葱郁绿树;“06:30 动态拉伸激活关节”:女性身着瑜伽服在阳台做晨间拉伸,身体舒展,背景为淡粉色天空与远山轮廓;“07:30 均衡营养早餐”:桌上摆放全麦面包、牛油果和一杯橙汁,女性微笑着准备用餐;“08:00 补水润燥”:透明玻璃水杯中浮有柠檬片,女性手持水杯轻啜,阳光从左侧斜照入室,杯壁水珠滑落;第二行分别是:“09:00 专注高效工作”:女性专注敲击键盘,屏幕显示简洁界面,身旁放有一杯咖啡与一盆绿植;“12:00 静心阅读时光”:女性坐在书桌前翻阅纸质书籍,台灯散发暖光,书页泛黄,旁放半杯红茶;“12:30 午后轻松漫步”:女性在林荫道上漫步,脸部特写;“15:00 茶香伴午后”:女性端着骨瓷茶杯站在窗边,窗外是城市街景与飘动云朵,茶香袅袅;第三行分别是:“18:00 运动释放压力”:健身房内,女性正在练习瑜伽;“19:00 美味晚餐”:女性在开放式厨房中切菜,砧板上有番茄与青椒,锅中热气升腾,灯光温暖;“21:00 冥想助眠”:女性盘腿坐在柔软地毯上冥想,双手轻放膝上,闭目宁静;“21:30 进入睡眠”:女性躺在床上休息。整体采用自然光线为主,色调以暖白与米灰为基调,光影层次分明,画面充满温馨的生活气息与规律的节奏感。
These are the core enhancements in this update. We hope you enjoy using Qwen-Image-2512!
If Qwen-Image-2512 proves helpful in your research, we’d greatly appreciate your citation 📝 :)
@misc{wu2025qwenimagetechnicalreport,
      title={Qwen-Image Technical Report},
      author={Chenfei Wu and Jiahao Li and Jingren Zhou and Junyang Lin and Kaiyuan Gao and Kun Yan and Sheng-ming Yin and Shuai Bai and Xiao Xu and Yilei Chen and Yuxiang Chen and Zecheng Tang and Zekai Zhang and Zhengyi Wang and An Yang and Bowen Yu and Chen Cheng and Dayiheng Liu and Deqing Li and Hang Zhang and Hao Meng and Hu Wei and Jingyuan Ni and Kai Chen and Kuan Cao and Liang Peng and Lin Qu and Minggang Wu and Peng Wang and Shuting Yu and Tingkun Wen and Wensen Feng and Xiaoxiao Xu and Yi Wang and Yichang Zhang and Yongqiang Zhu and Yujia Wu and Yuxuan Cai and Zenan Liu},
      year={2025},
      eprint={2508.02324},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2508.02324},
}