




Total runs:
67.9K
Run Growth:
-16.5K
Growth Rate:
-24.34%
The base model pretrained and fine-tuned on 960 hours of Librispeech on 16kHz sampled speech audio. When using the model make sure that your speech input is also sampled at 16Khz.
Authors: Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli
Abstract
While the general idea of self-supervised learning is identical across modalities, the actual algorithms and objectives differ widely because they were developed with a single modality in mind. To get us closer to general self-supervised learning, we present data2vec, a framework that uses the same learning method for either speech, NLP or computer vision. The core idea is to predict latent representations of the full input data based on a masked view of the input in a self-distillation setup using a standard Transformer architecture. Instead of predicting modality-specific targets such as words, visual tokens or units of human speech which are local in nature, data2vec predicts contextualized latent representations that contain information from the entire input. Experiments on the major benchmarks of speech recognition, image classification, and natural language understanding demonstrate a new state of the art or competitive performance to predominant approaches.
The original model can be found under https://github.com/pytorch/fairseq/tree/main/examples/data2vec .
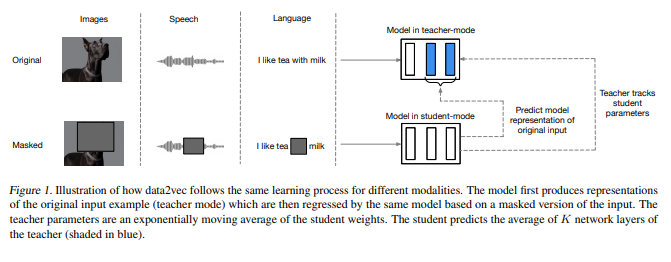
For more information, please take a look at the official paper .
To transcribe audio files the model can be used as a standalone acoustic model as follows:
 from transformers import Wav2Vec2Processor, Data2VecForCTC
 from datasets import load_dataset
 import torch

 # load model and processor
 processor = Wav2Vec2Processor.from_pretrained("facebook/data2vec-audio-base-960h")
 model = Data2VecForCTC.from_pretrained("facebook/data2vec-audio-base-960h")

 # load dummy dataset and read soundfiles
 ds = load_dataset("patrickvonplaten/librispeech_asr_dummy", "clean", split="validation")

 # tokenize
 input_values = processor(ds[0]["audio"]["array"],, return_tensors="pt", padding="longest").input_values  # Batch size 1

 # retrieve logits
 logits = model(input_values).logits

 # take argmax and decode
 predicted_ids = torch.argmax(logits, dim=-1)
 transcription = processor.batch_decode(predicted_ids)
This code snippet shows how to evaluate facebook/data2vec-audio-base-960h on LibriSpeech's "clean" and "other" test data.
 from transformers import Wav2Vec2Processor, Data2VecForCTC
 from datasets import load_dataset
 import torch
 from jiwer import wer

 # load model and processor
 processor = Wav2Vec2Processor.from_pretrained("facebook/data2vec-audio-base-960h").to("cuda")
 model = Data2VecForCTC.from_pretrained("facebook/data2vec-audio-base-960h")


librispeech_eval = load_dataset("librispeech_asr", "clean", split="test")

def map_to_pred(batch):
    input_values = processor(batch["audio"]["array"], return_tensors="pt", padding="longest").input_values
    with torch.no_grad():
        logits = model(input_values.to("cuda")).logits

    predicted_ids = torch.argmax(logits, dim=-1)
    transcription = processor.batch_decode(predicted_ids)
    batch["transcription"] = transcription
    return batch

result = librispeech_eval.map(map_to_pred, batched=True, batch_size=1, remove_columns=["audio"])

print("WER:", wer(result["text"], result["transcription"]))
Result (WER) :
| "clean" | "other" |
|---|---|
| 2.77 | 7.08 |