



Total runs:
3.7K
Run Growth:
2.7K
Growth Rate:
73.83%
Logic2Vision is a LLaVA-1.5-13B model finetuned on VisReas dataset for complex visual reasoning tasks.

Logic2Vision is a LLaVA-1.5-13B model finetuned on VisReas dataset for complex visual reasoning tasks. The model has been finetuned using LoRA to generate python pseudocode outputs to solve a complex visual reasoning tasks.
The inference method is similar to LLaVA-1.5-13B .
Question
Question
import torch
from transformers import LlavaProcessor, LlavaForConditionalGeneration
import requests
from PIL import Image

class LLaVACodeTemplate:
    prompt = """
    USER: <image>
    Executes the code and logs the results step-by-step to provide an answer to the question.
    Question
    {question}
    Code
    {codes}
    ASSISTANT:
    Log
    """

    answer = """
    {logs}
    Answer:
    {answer}</s>
    """

template = LLaVACodeTemplate()
model = LlavaForConditionalGeneration.from_pretrained("RE-N-Y/logic2vision", torch_dtype=torch.bfloat16, low_cpu_mem_usage=True, cache_dir="/data/tir/projects/tir6/general/sakter/cache")
model.to("cuda")

processor = LlavaProcessor.from_pretrained("RE-N-Y/logic2vision")
processor.tokenizer.pad_token = processor.tokenizer.eos_token
processor.tokenizer.padding_side = "left"

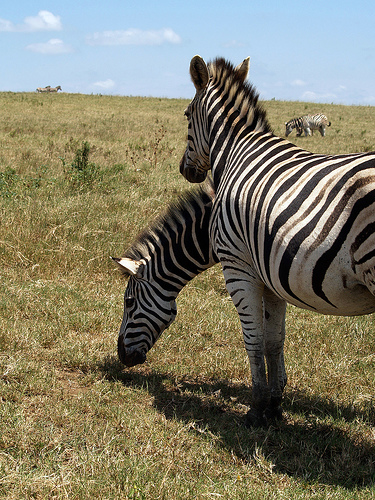
image = Image.open(requests.get("https://huggingface.co/RE-N-Y/logic2vision/resolve/main/zebras.jpg", stream=True).raw)
question = "What else in the image is striped as the rope and the mane to the left of the white clouds?"
codes = """selected_clouds = select(clouds)
filtered_clouds = filter(selected_clouds, ['white'])
related_mane = relate(mane, to the left of, o, filtered_clouds)
selected_rope = select(rope)
pattern = query_pattern(['selected_rope', 'related_mane'])
result = select(objects, attr=pattern)
"""

prompt = template.prompt.format(question=question, codes=codes)
inputs = processor(images=image, text=prompt, return_tensors="pt")
inputs.to("cuda")

generate_ids = model.generate(**inputs, max_new_tokens=256)
output = processor.batch_decode(generate_ids, skip_special_tokens=True)
print(output[0])

# USER:
# Executes the code and logs the results step-by-step to provide an answer to the question.
# Question
# What else in the image is striped as the rope and the mane to the left of the white clouds?

# Code
# selected_clouds = select(clouds)
# filtered_clouds = filter(selected_clouds, ['white'])
# related_mane = relate(mane, to the left of, o, filtered_clouds)
# selected_rope = select(rope)
# pattern = query_pattern(['selected_rope', 'related_mane'])
# result = select(objects, attr=pattern)

# ASSISTANT:
# Log
# ('clouds', ['white'])
# ('clouds', ['white'])
# ('mane', ['striped'])
# ('rope', ['no object'])
# ['the question itself is problematic']
# ['the question itself is problematic']
# Answer:
# the question itself is problematic


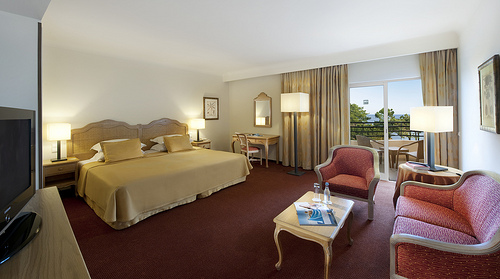
image = Image.open(requests.get("https://huggingface.co/RE-N-Y/logic2vision/resolve/main/room.jpg", stream=True).raw)
question = "What material do the chair and the table have in common?"
codes = """selected_chair = select(chair)
selected_table = select(table)
materials = query_material([selected_chair, selected_table])
common_material = common(materials)
"""

prompt = template.prompt.format(question=question, codes=codes)
inputs = processor(images=image, text=prompt, return_tensors="pt")
inputs.to("cuda")

generate_ids = model.generate(**inputs, max_new_tokens=256)
output = processor.batch_decode(generate_ids, skip_special_tokens=True)
print(output[0])

# USER:
# Executes the code and logs the results step-by-step to provide an answer to the question.
# Question
# What material do the chair and the table have in common?
# Code
# selected_chair = select(chair)
# selected_table = select(table)
# materials = query_material([selected_chair, selected_table])
# common_material = common(materials)

# ASSISTANT:
# Log
# ('chair', ['wood'])
# ('table', ['wood'])
# [['wood'], ['wood']]
# ['wood']
# Answer:
# wood
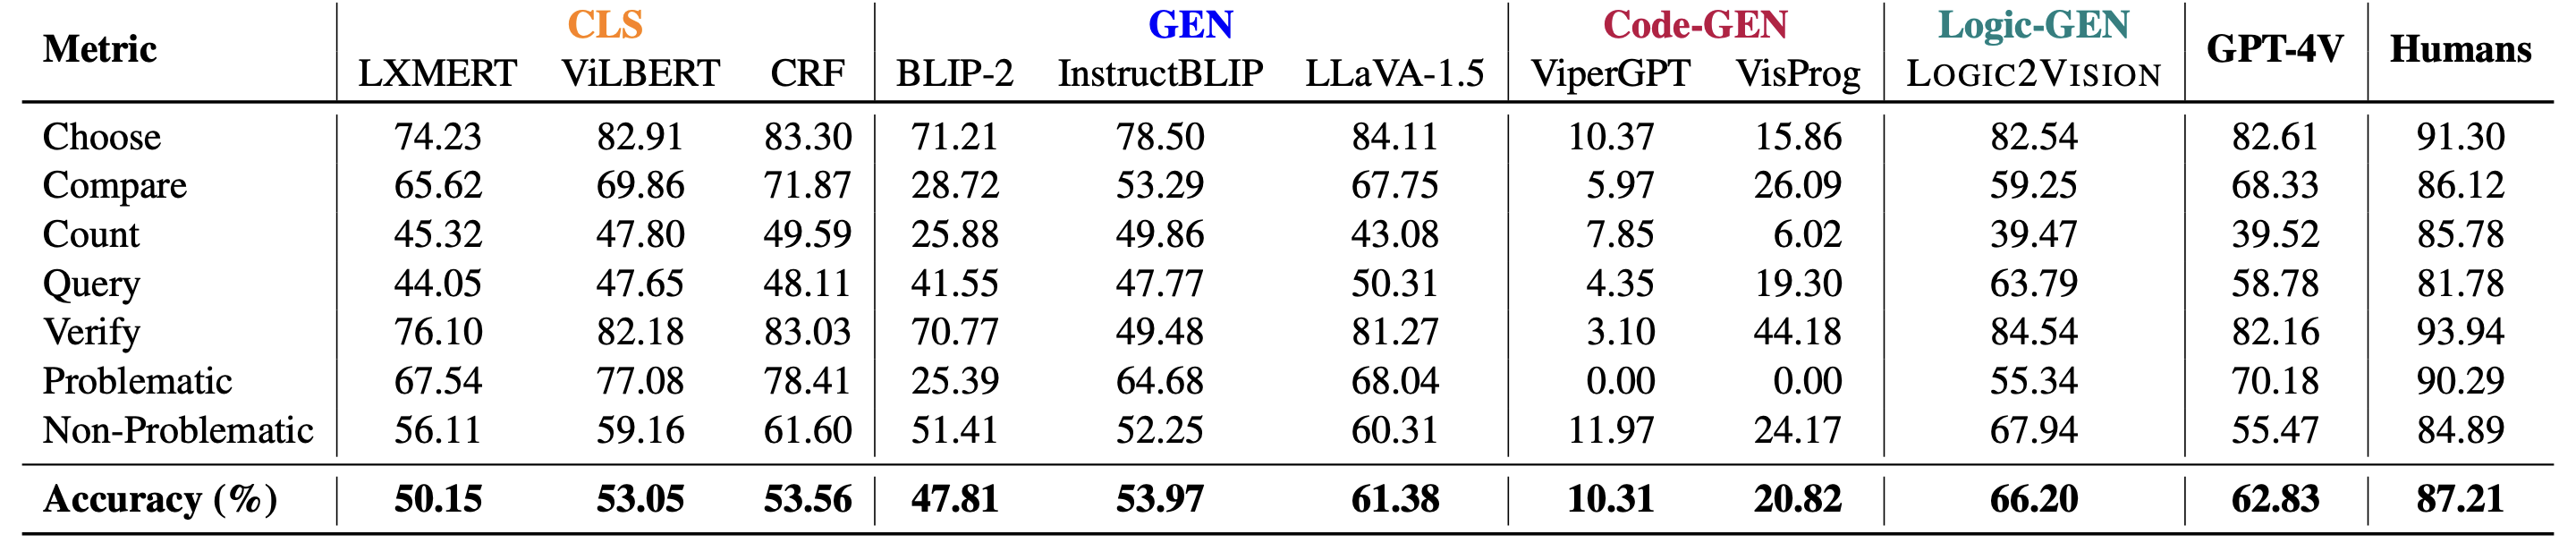
The model has been mostly trained on VisReas dataset which is generated from Visual Genome dataset. Furthermore, since the VLM was mostly finetuned to solve visual reasoning tasks by "generating python pseudocode" outputs provided by the user. Hence, it may struggle to adopt to different prompt styles and code formats.
The model has been finetuned using 2 A6000 GPUs on CMU LTI's Babel cluster. The model has been finetuned using LoRA (
r=8, alpha=16, dropout=0.05, task_type="CAUSAL_LM"
).
LoRA modules were attached to
["q_proj", "v_proj"]
. We use DDP for distributed training and BF16 to speed up training. For more details, check
our paper
!
BibTeX:
@misc{akter2024visreas,
    title={VISREAS: Complex Visual Reasoning with Unanswerable Questions},
    author={Syeda Nahida Akter and Sangwu Lee and Yingshan Chang and Yonatan Bisk and Eric Nyberg},
    year={2024},
    eprint={2403.10534},
    archivePrefix={arXiv},
    primaryClass={cs.CV}
}