



Total runs:
515
Run Growth:
358
Growth Rate:
69.38%
nomic-embed-text-v1
is 8192 context length text encoder that surpasses OpenAI text-embedding-ada-002 and text-embedding-3-small performance on short and long context tasks.
| Name | SeqLen | MTEB | LoCo | Jina Long Context | Open Weights | Open Training Code | Open Data |
|---|---|---|---|---|---|---|---|
| nomic-embed-text-v1 | 8192 | 62.39 | 85.53 | 54.16 | ✅ | ✅ | ✅ |
| jina-embeddings-v2-base-en | 8192 | 60.39 | 85.45 | 51.90 | ✅ | ❌ | ❌ |
| text-embedding-3-small | 8191 | 62.26 | 82.40 | 58.20 | ❌ | ❌ | ❌ |
| text-embedding-ada-002 | 8191 | 60.99 | 52.7 | 55.25 | ❌ | ❌ | ❌ |
The easiest way to get started with Nomic Embed is through the Nomic Embedding API.
Generating embeddings with the
nomic
Python client is as easy as
from nomic import embed

output = embed.text(
    texts=['Nomic Embedding API', '#keepAIOpen'],
    model='nomic-embed-text-v1',
    task_type='search_document'
)

print(output)
For more information, see the API reference
Click the Nomic Atlas map below to visualize a 5M sample of our contrastive pretraining data!
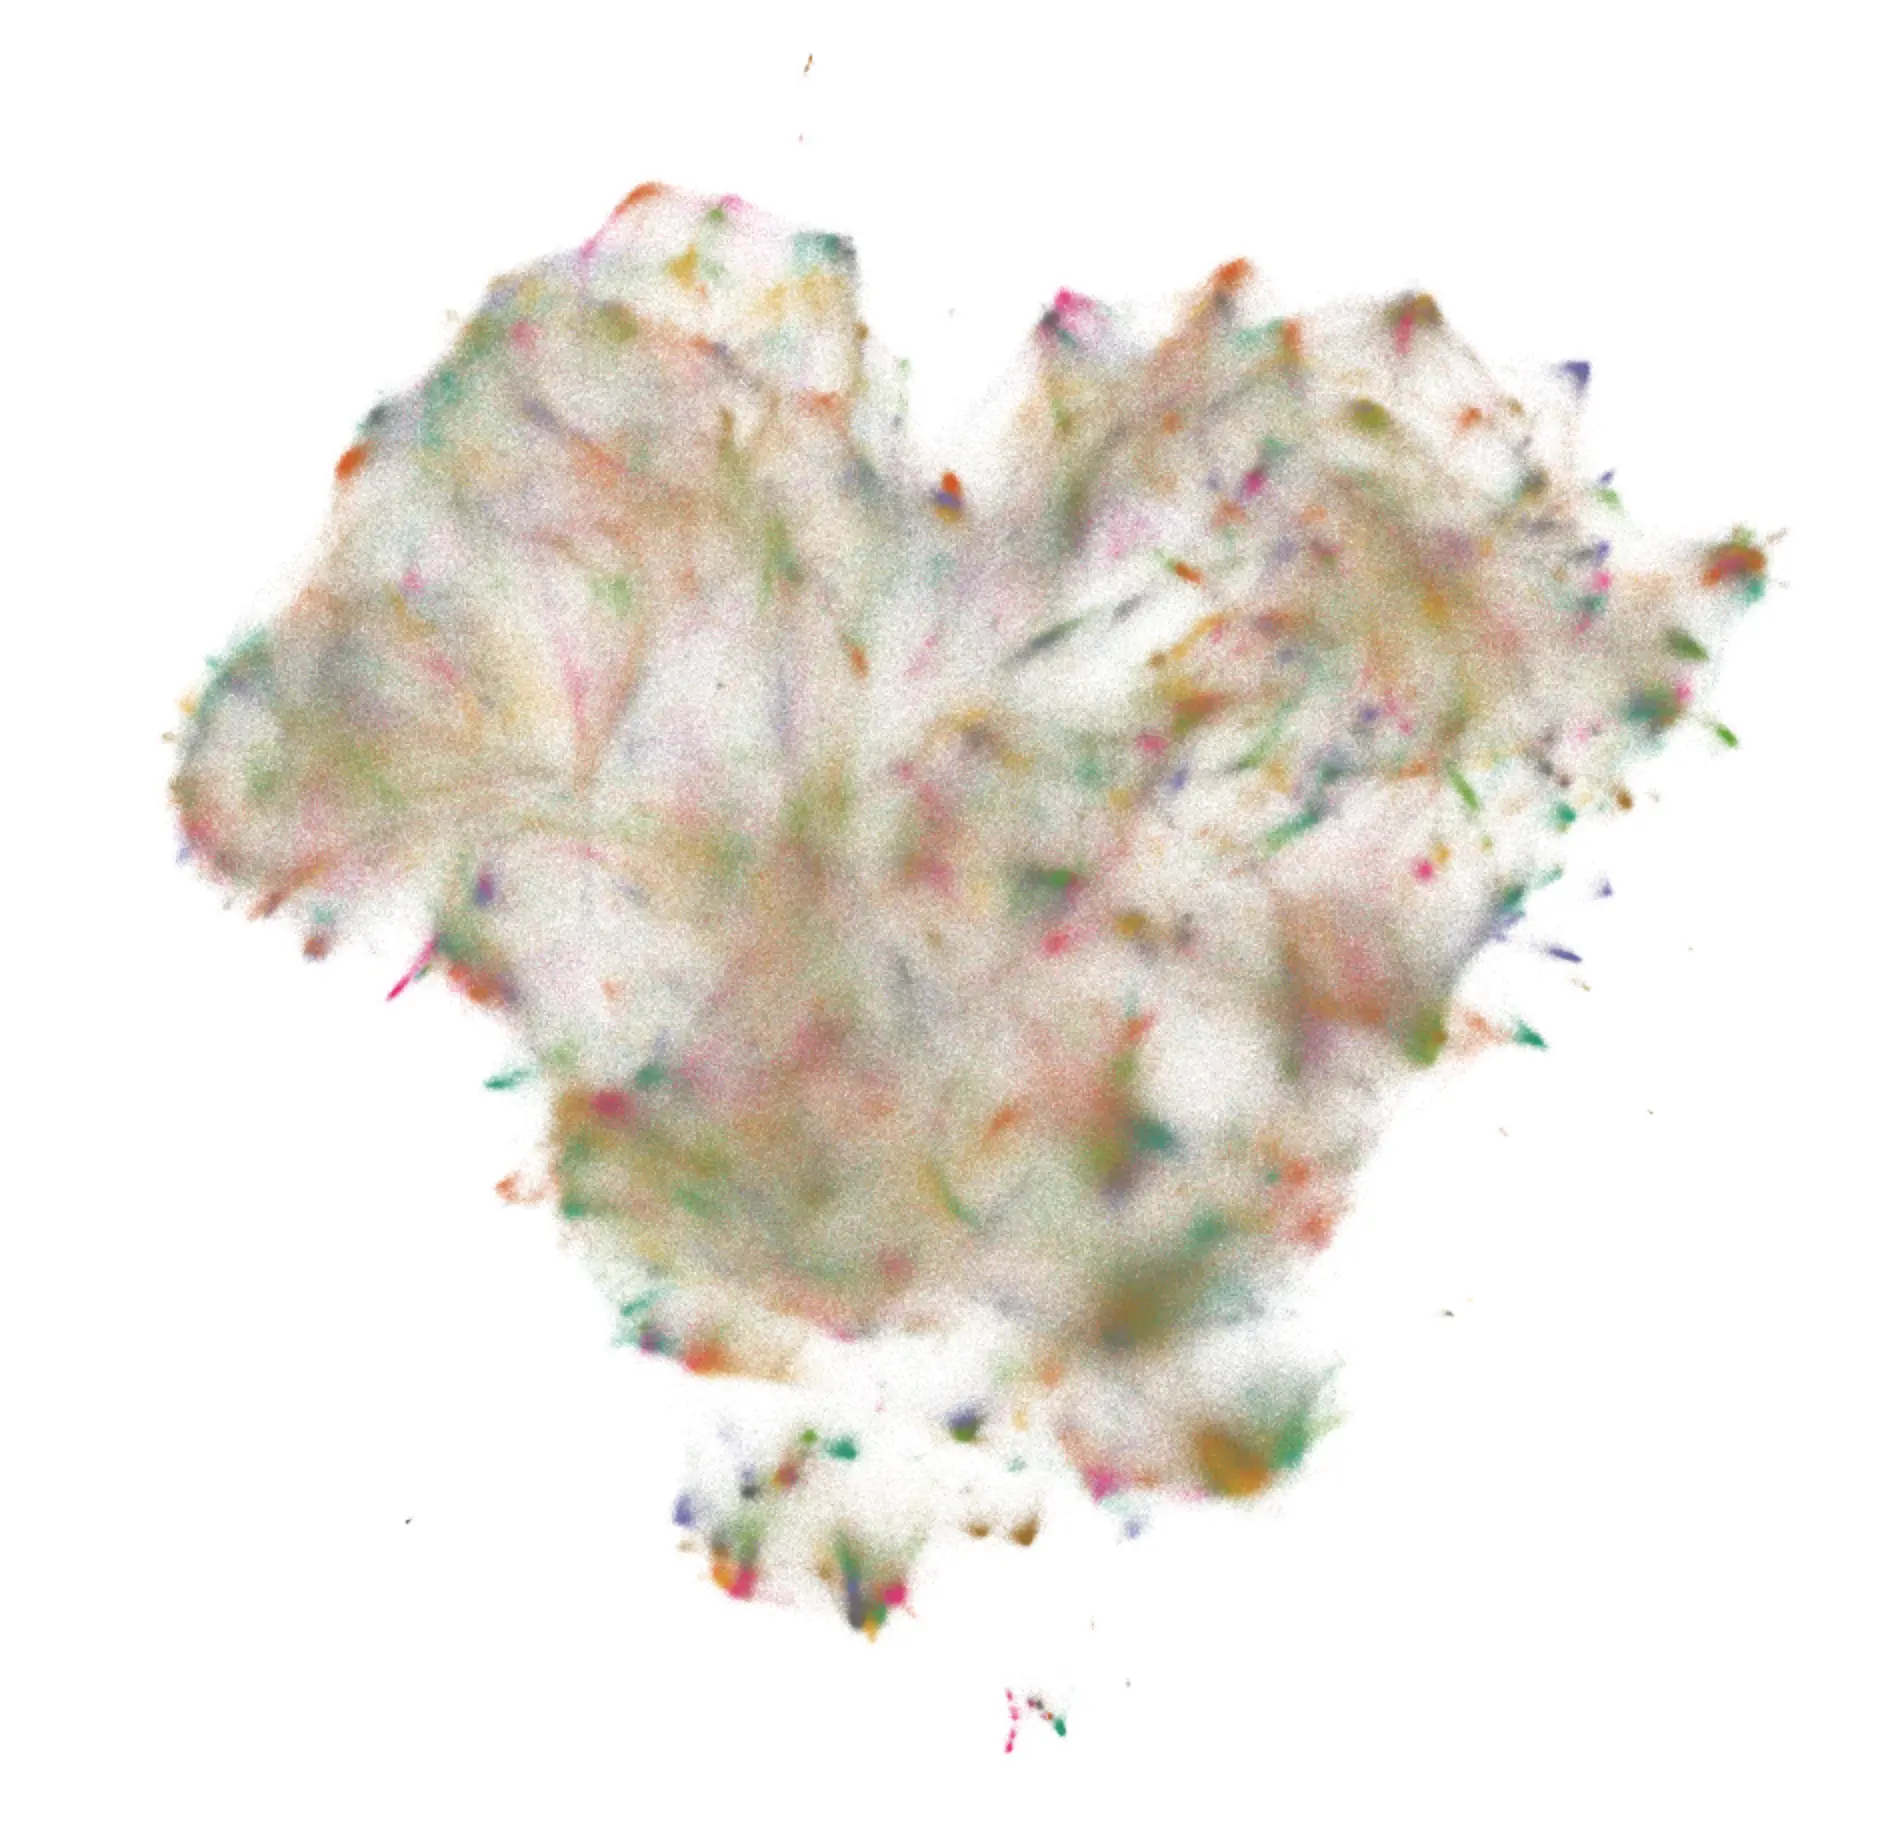
We train our embedder using a multi-stage training pipeline. Starting from a long-context BERT model , the first unsupervised contrastive stage trains on a dataset generated from weakly related text pairs, such as question-answer pairs from forums like StackExchange and Quora, title-body pairs from Amazon reviews, and summarizations from news articles.
In the second finetuning stage, higher quality labeled datasets such as search queries and answers from web searches are leveraged. Data curation and hard-example mining is crucial in this stage.
For more details, see the Nomic Embed Technical Report and corresponding blog post .
Training data to train the models is released in its entirety. For more details, see the
contrastors
repository
Note
nomic-embed-text
requires prefixes! We support the prefixes
[search_query, search_document, classification, clustering]
.
For retrieval applications, you should prepend
search_document
for all your documents and
search_query
for your queries.
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("nomic-ai/nomic-embed-text-v1", trust_remote_code=True)
sentences = ['search_query: What is TSNE?', 'search_query: Who is Laurens van der Maaten?']
embeddings = model.encode(sentences)
print(embeddings)
import torch
import torch.nn.functional as F
from transformers import AutoTokenizer, AutoModel

def mean_pooling(model_output, attention_mask):
    token_embeddings = model_output[0]
    input_mask_expanded = attention_mask.unsqueeze(-1).expand(token_embeddings.size()).float()
    return torch.sum(token_embeddings * input_mask_expanded, 1) / torch.clamp(input_mask_expanded.sum(1), min=1e-9)

sentences = ['search_query: What is TSNE?', 'search_query: Who is Laurens van der Maaten?']

tokenizer = AutoTokenizer.from_pretrained('bert-base-uncased')
model = AutoModel.from_pretrained('nomic-ai/nomic-embed-text-v1', trust_remote_code=True)
model.eval()

encoded_input = tokenizer(sentences, padding=True, truncation=True, return_tensors='pt')

with torch.no_grad():
    model_output = model(**encoded_input)

embeddings = mean_pooling(model_output, encoded_input['attention_mask'])
embeddings = F.normalize(embeddings, p=2, dim=1)
print(embeddings)
The model natively supports scaling of the sequence length past 2048 tokens. To do so,
- tokenizer = AutoTokenizer.from_pretrained('bert-base-uncased')
+ tokenizer = AutoTokenizer.from_pretrained('bert-base-uncased', model_max_length=8192)


- model = AutoModel.from_pretrained('nomic-ai/nomic-embed-text-v1', trust_remote_code=True)
+ model = AutoModel.from_pretrained('nomic-ai/nomic-embed-text-v1', trust_remote_code=True, rotary_scaling_factor=2)
import { pipeline } from '@xenova/transformers';

// Create a feature extraction pipeline
const extractor = await pipeline('feature-extraction', 'nomic-ai/nomic-embed-text-v1', {
    quantized: false, // Comment out this line to use the quantized version
});

// Compute sentence embeddings
const texts = ['What is TSNE?', 'Who is Laurens van der Maaten?'];
const embeddings = await extractor(texts, { pooling: 'mean', normalize: true });
console.log(embeddings);
If you find the model, dataset, or training code useful, please cite our work
@misc{nussbaum2024nomic,
      title={Nomic Embed: Training a Reproducible Long Context Text Embedder},
      author={Zach Nussbaum and John X. Morris and Brandon Duderstadt and Andriy Mulyar},
      year={2024},
      eprint={2402.01613},
      archivePrefix={arXiv},
      primaryClass={cs.CL}
}