

























Table of Contents
- Key Points
- Building Your AI Image Classifier with TensorFlow
- Understanding Word Embeddings and Their Impact
- Pros and Cons of Using TensorFlow for Image Classification
- Frequently Asked Questions (FAQ)
- Related Questions



Building Your AI Image Classifier with TensorFlow
What is an Image Classifier?
An image classifier is a type of artificial intelligence model that is designed to categorize images into predefined classes or labels. It is a fundamental component in various computer vision applications, ranging from simple object recognition to complex medical image analysis. Image classifiers analyze the visual content of an image and assign it to the most appropriate category based on patterns and features learned during training. This process involves using machine learning algorithms, often deep learning models like convolutional neural networks (CNNs), to learn from a large dataset of labeled images. The goal is to create a model that can accurately predict the category of new, unseen images. Key aspects of an effective image classifier include: Feature Extraction: Identifying relevant features within images, such as edges, textures, and shapes. Training Data: Using a diverse and labeled dataset to train the model effectively. Model Architecture: Selecting an appropriate neural network architecture to capture complex patterns. Evaluation Metrics: Measuring the performance of the classifier using metrics like accuracy, precision, and recall. Image classifiers are used in a multitude of industries, including Healthcare, retail, security, and autonomous vehicles, demonstrating their broad applicability and importance in modern technology. Understanding the principles and techniques behind image classifiers is crucial for anyone looking to delve into the field of AI and computer vision. By leveraging the power of libraries like TensorFlow, Pandas, and Numpy, you can create robust and accurate image classifiers to solve real-world problems. Effective optimization and validation ensure that the model generalizes well to new data, making it a valuable tool for automated image analysis and decision-making.
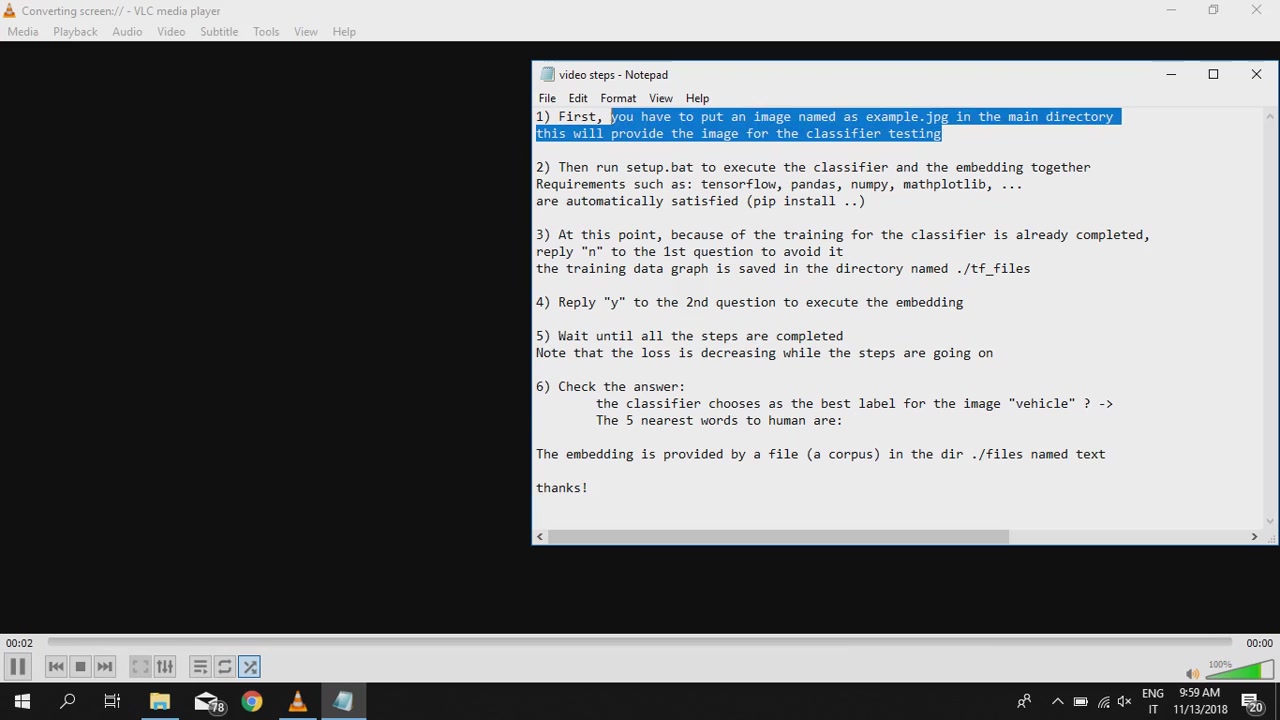
Step-by-Step Guide to Setting Up Your Environment
Setting up your environment is the crucial first step in any AI project, and creating an image classifier using TensorFlow is no exception. Here's a detailed, SEO-friendly guide to get you started:
- Install Python:
- Ensure Python is installed on your system. Python 3.6 or higher is recommended for TensorFlow compatibility.
- Download the latest version from the official Python website.
- Install TensorFlow:
- TensorFlow is the backbone of this project. Use pip, the Python package installer, to install it.
- Open your command line or terminal and run:
pip install tensorflow - For GPU support (optional but recommended for faster training):
pip install tensorflow-gpu - Make sure you have the necessary NVIDIA drivers installed for GPU support.
- Install Pandas:
- Pandas is essential for data manipulation and analysis.
- Install it using pip:
pip install pandas
- Install NumPy:
- NumPy is the fundamental package for scientific computing in Python.
- Install it using pip:
pip install numpy
-
Verify Installation:
-
To ensure all packages are installed correctly, run the following script in Python:
import tensorflow as tf import pandas as pd import numpy as np print("TensorFlow version:", tf.__version__) print("Pandas version:", pd.__version__) print("NumPy version:", np.__version__) - This script will print the versions of each library, confirming that they are properly installed.
-
- Organize Your Project Directory:
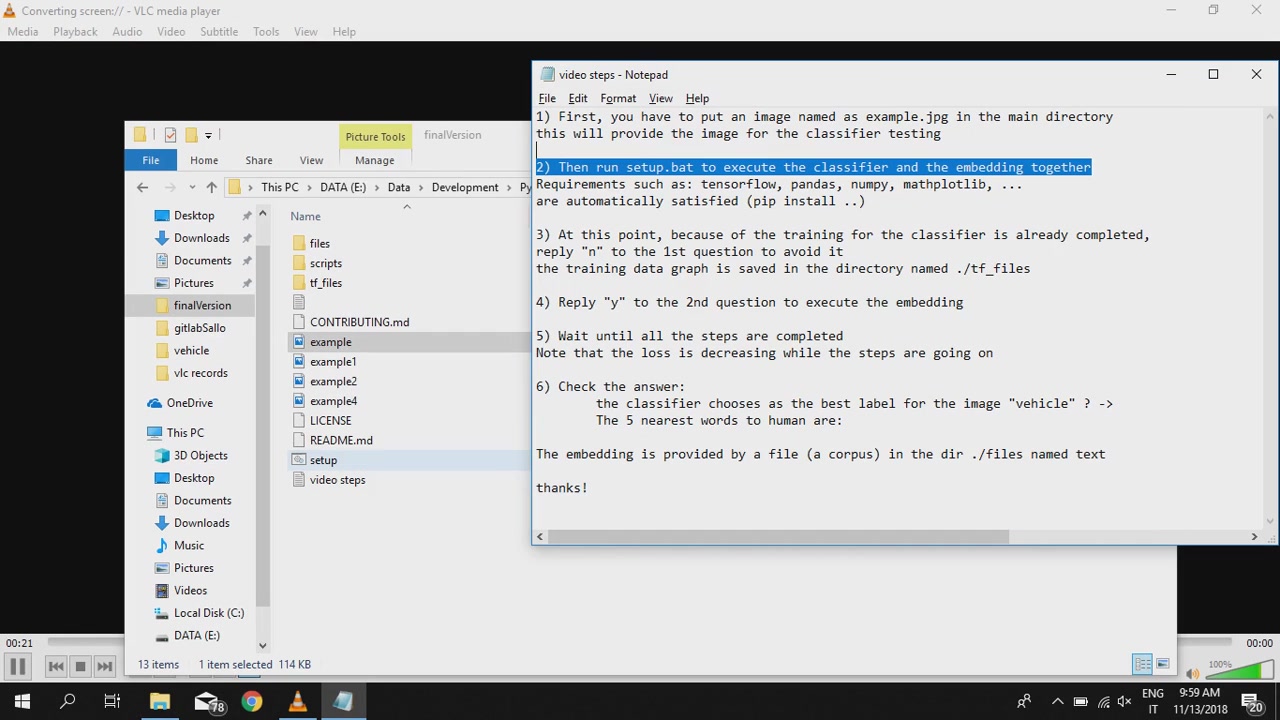
- Create a main directory for your project. This directory will house all your project files, including images, scripts, and the 'setup.bat' file.
- Place your image files, named according to your needs, in this directory. For testing purposes, an image named 'example.jpg' is recommended.
SEO Keywords: Python, TensorFlow, Pandas, Numpy, environment setup, image classifier, AI development, pip install
By following these steps, you'll have a robust environment ready for building your AI image classifier with TensorFlow.
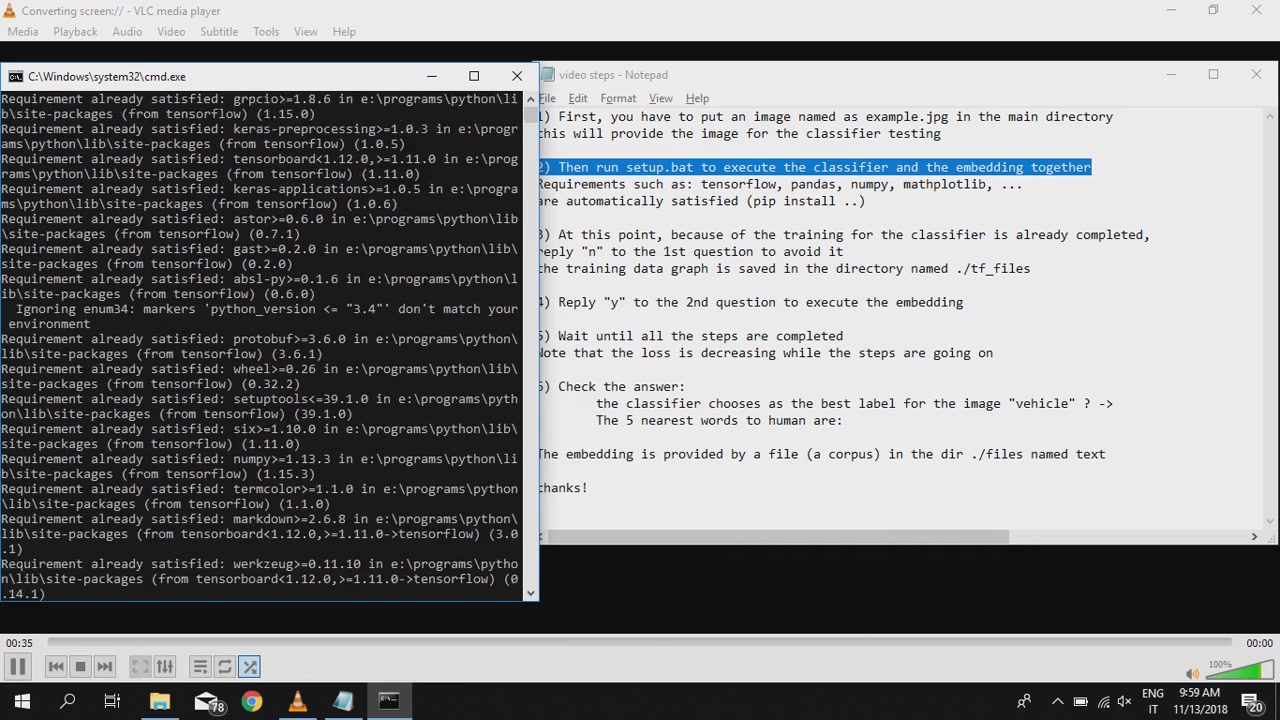
Executing the setup.bat File
The setup.bat file streamlines the process of setting up and running your image classifier and embedding techniques. Here's a detailed breakdown of how to execute this file effectively:
- Locate the
setup.batFile:- Navigate to your project directory where you have placed the
setup.batfile. This file is designed to automate the execution of your classifier and embedding scripts.
- Navigate to your project directory where you have placed the
- Double-Click to Execute:
- Simply double-click the
setup.batfile. This will open a command Prompt window and begin the execution process.
- Simply double-click the
- Monitor the Execution:
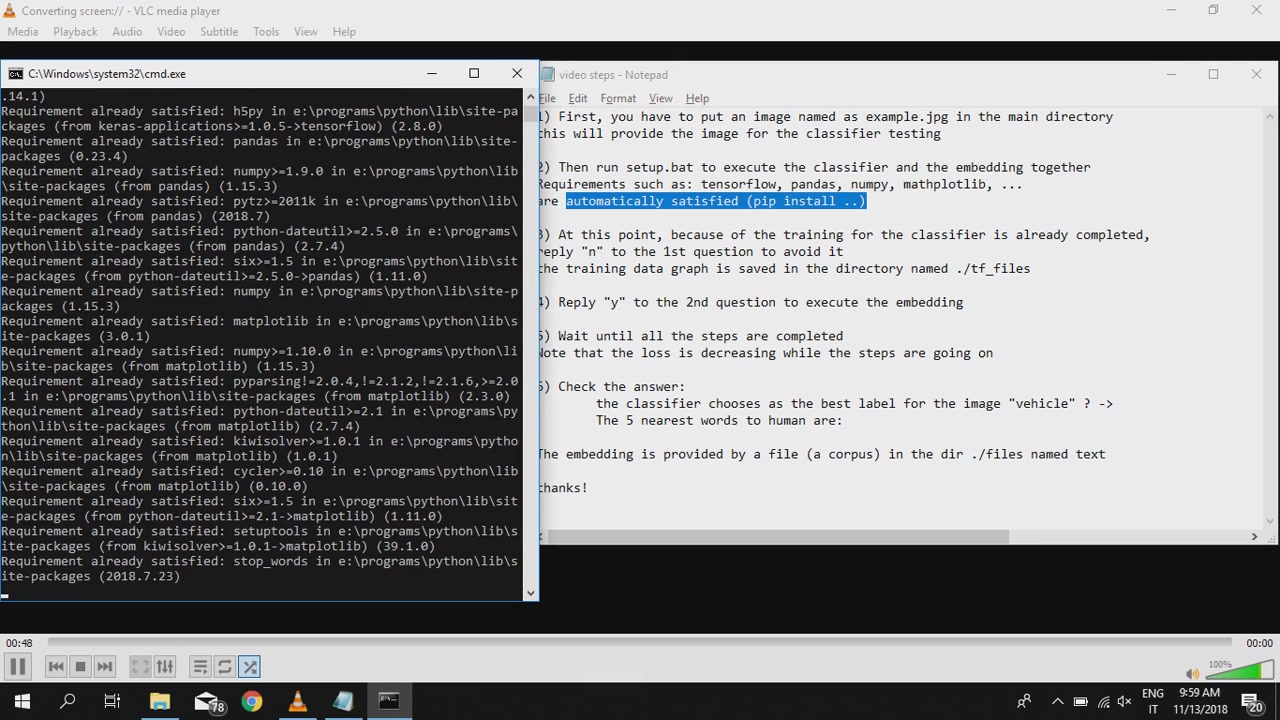
- The command prompt will display various messages and outputs as the script runs. Pay close attention to these messages to ensure that the script is executing as expected.
- The script will likely install missing packages, execute training scripts, and perform other setup tasks.
- Initial Training Question:
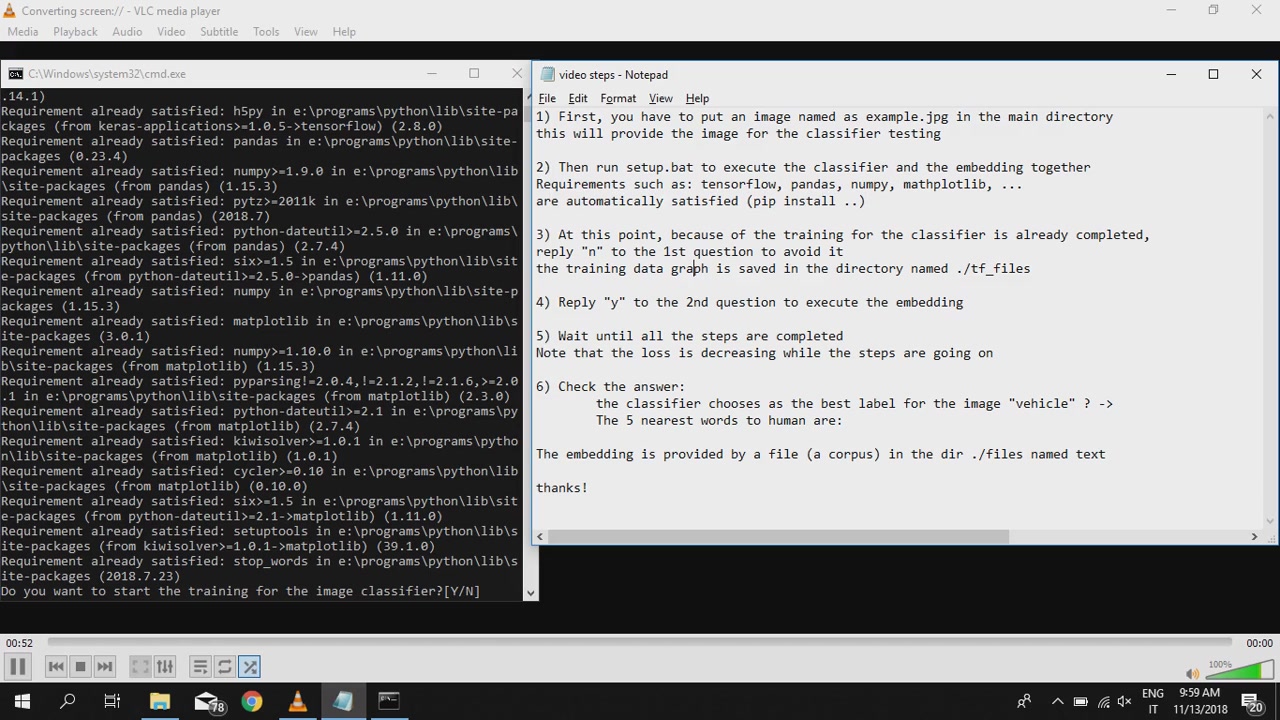
- At one point, the script might ask if you want to start the training for the image classifier. If the classifier is already trained, you should reply
nto avoid retraining. - This step is essential because retraining an already optimized classifier can lead to suboptimal results.
- At one point, the script might ask if you want to start the training for the image classifier. If the classifier is already trained, you should reply
- Embedding Execution:
- After the initial training question, the script will likely ask if you want to run the embedding. Reply
yto execute the embedding process. - The embedding process is crucial for generating WORD embeddings, which help the classifier understand relationships between different words and images.
- After the initial training question, the script will likely ask if you want to run the embedding. Reply
- Wait for Completion:
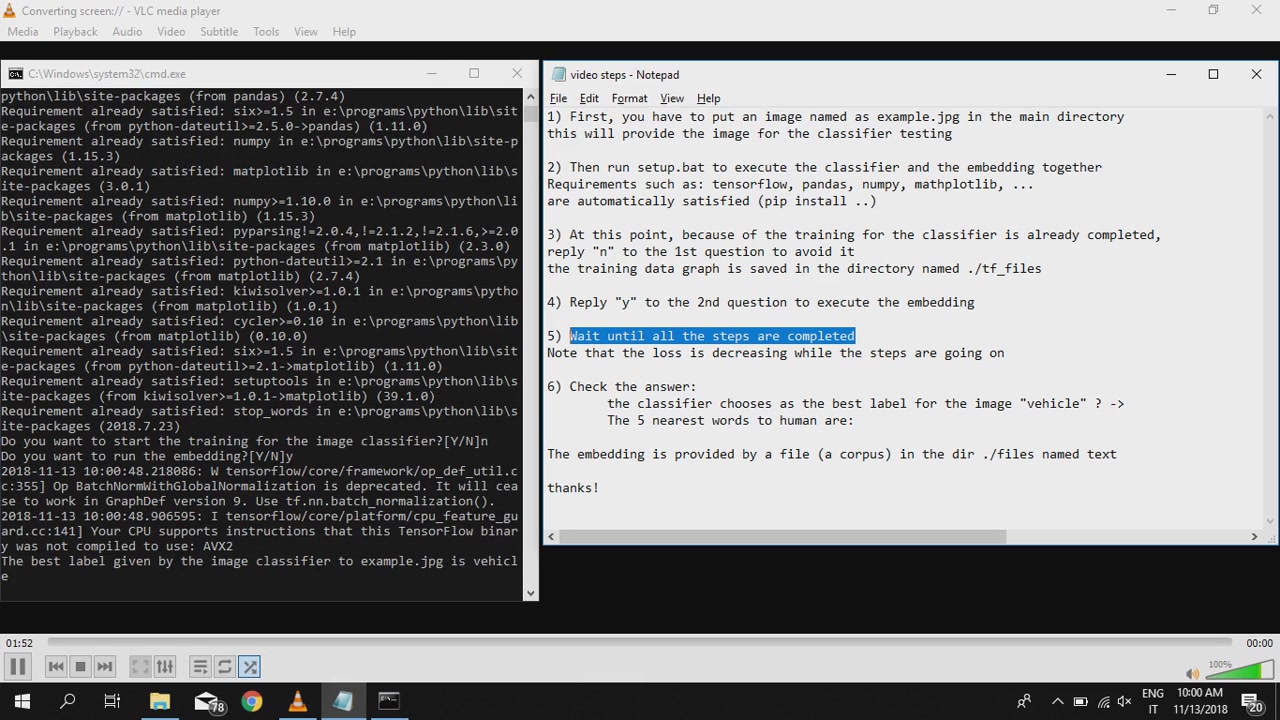
- Allow the script to run until all steps are completed. This may take some time, depending on the size of your dataset and the computational power of your system.
- Watch for messages indicating successful completion of each step.
- Check the Output:
- Once the script has finished executing, check the output in the command prompt for any errors or warnings.
- Verify that the classifier and embedding have been set up correctly by examining the generated files and directories.
SEO Keywords: setup.bat, execute script, image classifier, embedding, TensorFlow, automated setup, command prompt
By carefully executing the setup.bat file and monitoring its progress, you can ensure that your environment is properly configured for building and testing your AI image classifier.
Avoiding Retraining: The 'n' Response
In the process of setting up your image classifier with TensorFlow, you'll encounter a critical question: whether to start training for the image classifier. If you have already trained your classifier and saved the training data, you should respond with 'n' (for no) to avoid unnecessary retraining. Here’s why this step is essential and how to execute it correctly:
- Why Avoid Retraining?
- Time Efficiency: Retraining a model can be time-consuming, especially with large datasets. Avoiding retraining saves valuable time.
- Resource Conservation: Training models requires significant computational resources. Skipping retraining conserves these resources.
- Preserving Optimization: If your classifier is already optimized and performs well, retraining can disrupt the optimized state, potentially leading to decreased performance.
- How to Respond Correctly:
- When the command prompt displays the question
Do you want to start the training for the image classifier? [Y/n], typenand press Enter. - Ensure that you type the response correctly. Incorrect responses can lead to unintended retraining.
- When the command prompt displays the question
- Confirming the Skip:
- After responding with
n, the script should proceed to the next step without initiating the training process. - Monitor the output in the command prompt to confirm that the training step has been skipped.
- After responding with
- What Happens Next?
- By avoiding retraining, the script will proceed to execute the embedding process or other subsequent steps in the setup.
- The embedding process is crucial for generating word embeddings, which help the classifier understand relationships between different words and images.
SEO Keywords: avoid retraining, image classifier, TensorFlow, optimization, training data, 'n' response, time efficiency, resource conservation
By strategically avoiding retraining when it's not necessary, you can streamline the setup process, conserve resources, and preserve the optimized state of your image classifier.
Executing Embedding: The 'y' Response
After setting up the basic environment and potentially skipping the retraining phase, the next crucial step is to execute the embedding. Embedding is a technique used to represent words or images in a high-dimensional space, capturing semantic relationships between them. To initiate this process, you will typically be prompted with a question like, Do you want to run the embedding? [Y/n]. Here’s a detailed guide on how to respond correctly:
- Understanding Embedding:
- Embedding transforms words or images into numerical vectors, allowing AI models to understand and process them.
- Word embeddings are particularly useful for tasks like natural language processing and image captioning.
- The embedding process uses a corpus of text (often provided in a
.textfile) to learn relationships between words.
- Responding with 'y':
- When prompted with
Do you want to run the embedding? [Y/n], typeyand press Enter. - This command signals the script to proceed with the embedding process.
- When prompted with
- Monitoring the Process:
- The command prompt will display progress messages as the embedding process runs. Monitor these messages to ensure the process is executing correctly.
- Embedding can take a significant amount of time, depending on the size of the corpus and the complexity of the model.
- Verifying Completion:
- Upon completion, the script will typically generate embedding files, which are used by the classifier to understand relationships between words and images.
- Check the output directory for these files to confirm that the embedding process has been successful.
SEO Keywords: embedding, run embedding, TensorFlow, word embeddings, image classifier, 'y' response, semantic relationships, corpus
Correctly executing the embedding process is essential for enhancing the performance of your image classifier. By responding with 'y' and monitoring the progress, you ensure that your model has the necessary understanding of semantic relationships to accurately classify images.
Monitoring Progress: Loss Decrease and Completion
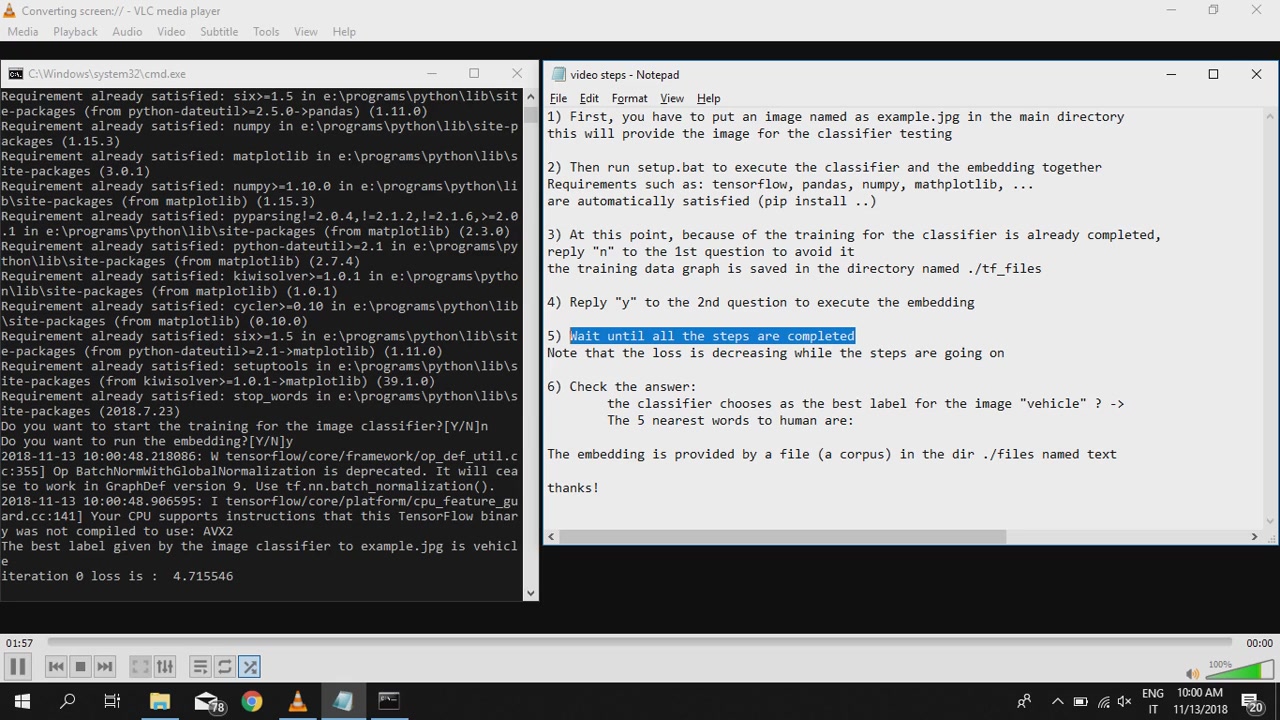
After initiating the embedding process, monitoring the progress of the training steps is crucial to ensure that your image classifier is learning effectively. One key indicator of successful training is the decrease in loss. Loss measures the difference between the model's predictions and the actual values. Here’s what you need to know about monitoring progress:
- Understanding Loss:
- Loss represents the error rate of the model. A lower loss indicates better performance.
- During training, the goal is to minimize the loss by adjusting the model's parameters.
- Common loss functions include categorical cross-entropy for classification tasks.
-
Monitoring Loss Decrease:
-
As the training steps progress, observe the loss values printed in the command prompt.
-
The loss should generally decrease over time. A stable, low loss indicates that the model is converging to an optimal solution.
-
If the loss plateaus or increases, it may indicate issues such as overfitting or a poor learning rate.
-
- Recognizing Completion:
- The training process typically runs for a predefined number of iterations or until the loss reaches a satisfactory level.
- The script will display a completion message once the training is finished.
- Ensure that the script completes all steps without errors before proceeding.
- Example Loss Values :
| Iteration | Loss |
|---|---|
| 0 | 4.715546 |
| 3000 | 2.292539 |
| 6000 | 2.112372 |
| 9000 | 2.038714 |
| 12000 | 2.008921 |
| 15000 | 1.998197 |
| 27000 | 1.9912927 |
- Troubleshooting:
- If the loss does not decrease, consider adjusting the learning rate or the model architecture.
- Check for issues with the training data, such as incorrect labels or insufficient data.
SEO Keywords: loss decrease, training progress, image classifier, TensorFlow, optimization, error rate, overfitting, learning rate
By closely monitoring the loss decrease and ensuring that all steps complete without errors, you can have confidence in the performance of your image classifier. This careful monitoring is essential for achieving accurate and reliable results.
Verification: Classifier Accuracy and Nearest Words
Once the training and embedding processes are complete, the next critical step is to verify the accuracy of your image classifier and the quality of the word embeddings. Here’s how to perform these verifications:
-
Classifier Accuracy:
-
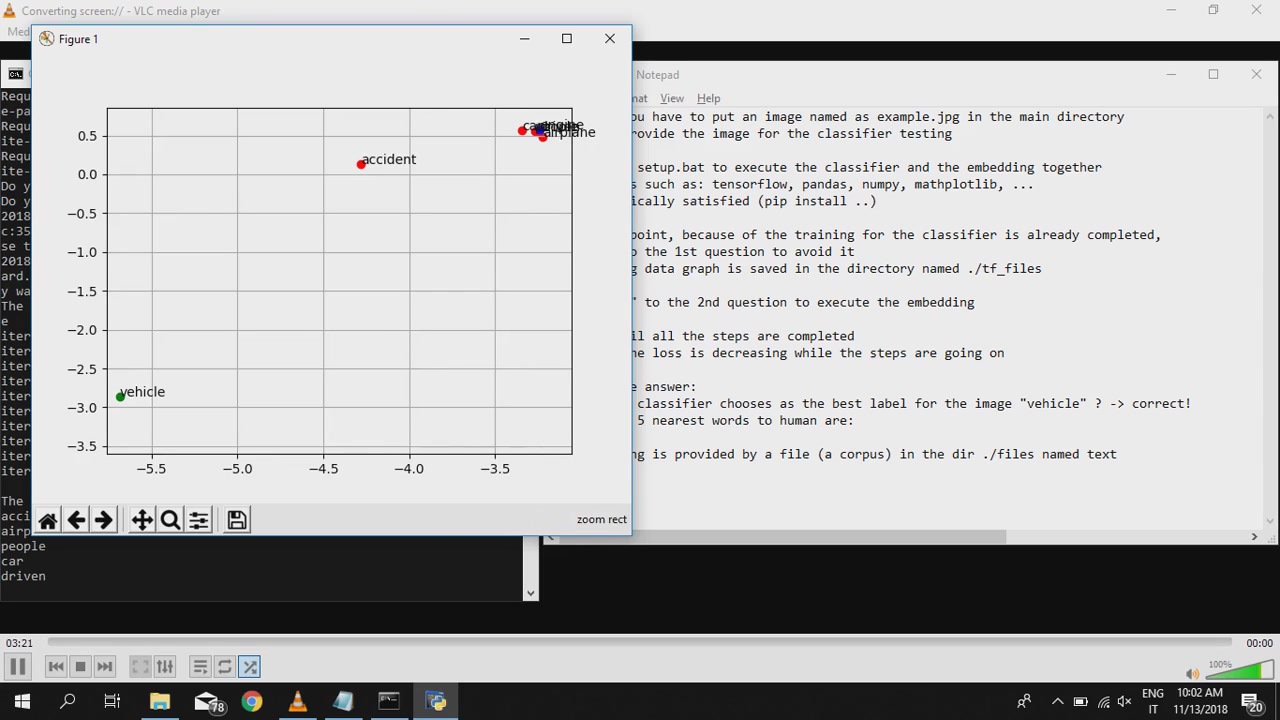
After the script finishes, it should display the best label given by the image classifier for your test image (e.g.,
example.jpg).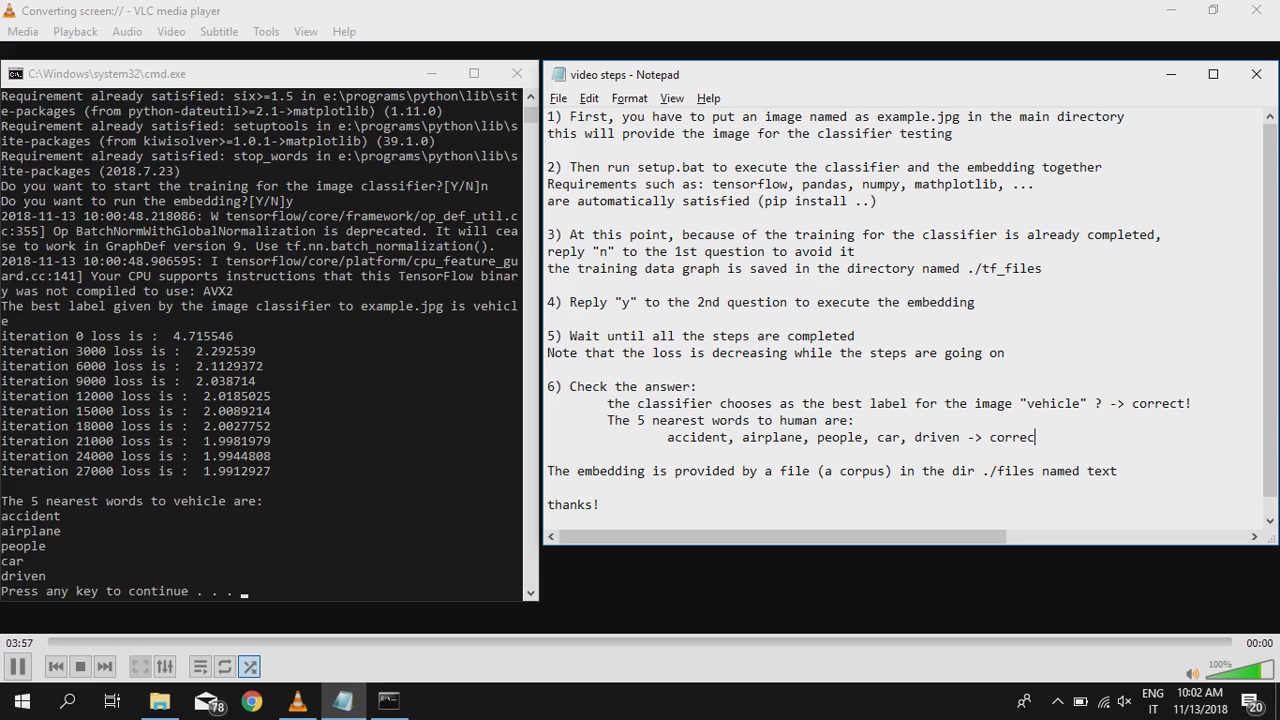
-
Verify that the classifier has correctly identified the image. If the classifier labels the image as 'vehicle', then the classification is considered correct.
-
A correct classification indicates that the model has learned to recognize the key features of the image and assign it to the appropriate category.
-
- Nearest Words Examination :
- The script will also display the five nearest words to the classified label. These nearest words provide insights into the quality of the word embeddings.
- Examine these nearest words to ensure they are semantically related to the classified label. For instance, if the label is 'vehicle', the nearest words might include 'accident', 'airplane', 'people', 'car', and 'driven'.
- Semantically coherent nearest words indicate that the embedding process has successfully captured relationships between different words.
- Interpreting Results:
- If the classifier accuracy is high and the nearest words are semantically relevant, you can be confident in the performance of your image classifier.
- If the classifier mislabels the image or the nearest words are not semantically related, further training and optimization may be required.
-
Example Results :
- The best label given by the image classifier to
example.jpgis vehicle --> correct! - The 5 nearest words to vehicle are:
- accident
- airplane
- people
- car
- driven
- The best label given by the image classifier to
- Text File Examination:
- Open the text file located in the ./files directory to view the structure and context of the training data
SEO Keywords: classifier accuracy, nearest words, TensorFlow, image classifier, verification, semantic relationships, word embeddings, classification results
By verifying the classifier accuracy and examining the nearest words, you can gain valuable insights into the performance of your image classifier. These verifications help ensure that your model is accurately classifying images and that the word embeddings are capturing meaningful relationships.
Understanding Word Embeddings and Their Impact
What Are Word Embeddings?
Word embeddings are a technique in natural language processing (NLP) where words are mapped to vectors of real numbers in a high-dimensional space. This mapping captures the semantic relationships between words, allowing AI models to understand context and meaning. Unlike traditional methods like one-hot encoding, word embeddings represent words in a continuous space, where similar words are located close to each other. The power of word embeddings lies in their ability to distill the contextual meaning of words into a format that machine learning algorithms can understand and process. The position of a word vector in this space is learned based on the word's usage and context within a large corpus of text. Several popular algorithms are used to generate word embeddings, including Word2Vec, GloVe, and FastText. These algorithms analyze the statistical co-occurrence of words in a text corpus to create the embedding vectors. Word embeddings have become a cornerstone of modern NLP and are used in various applications, such as sentiment analysis, machine translation, and information retrieval. Their ability to capture semantic relationships makes them invaluable for tasks where understanding the context and meaning of words is crucial. By leveraging word embeddings, AI models can achieve higher accuracy and better performance in understanding human language. The quality of the word embeddings directly influences the effectiveness of these models. Therefore, selecting an appropriate algorithm and using a large, diverse corpus for training are essential for generating high-quality word embeddings.
How Word Embeddings Enhance Image Classification
Word embeddings, primarily known for their applications in natural language processing (NLP), also play a significant role in enhancing image classification tasks. Here's how word embeddings contribute to improved image classification:
- Semantic Contextualization:
- Word embeddings help provide semantic context to image labels. Instead of treating labels as isolated categories, the model understands their relationships with other words.
- For example, the word embedding for 'car' will be closer to 'vehicle' than to 'tree', allowing the model to leverage these semantic relationships.
- Feature Enrichment:
- By incorporating word embeddings, image classifiers can enrich the feature set used for classification. The model doesn't just rely on visual features but also on the semantic features captured by the word embeddings.
- This is particularly useful when dealing with complex images where semantic understanding is crucial for accurate classification.
- Improved Generalization:
- Word embeddings help improve the generalization capabilities of the image classifier. The model can better handle unseen images or variations in the training data by leveraging the semantic context provided by the word embeddings.
- For instance, the model can still classify a new type of 'car' based on its semantic similarity to existing 'vehicle' embeddings.
- Multi-Modal Learning:
- Word embeddings enable multi-modal learning, where the model learns from both visual and textual data. The model can leverage the knowledge gained from a large corpus of text to improve its image classification performance.
- This is particularly beneficial when training data is limited, as the model can leverage the semantic knowledge from text to augment its visual understanding.
- Application in Specific Scenarios:
- Image captioning is a prime example where word embeddings enhance image classification. The model uses word embeddings to generate descriptive captions for images, combining visual recognition with semantic understanding.
- Semantic image search also benefits from word embeddings, allowing users to search for images based on semantic queries rather than just visual features.
SEO Keywords: word embeddings, image classification, semantic context, feature enrichment, improved generalization, multi-modal learning, image captioning, semantic image search
Word embeddings transform image classification by adding semantic understanding and contextual knowledge. This results in better precision, greater resilience, and innovative applications in AI and computer vision.


Most people like





































Report
Please select a reason for reporting
- 13 Reasons to Switch from Snapchat to Text Messaging
- 7 Powerful Speech to Text Apps to Boost Productivity
- 10 Best Speech to Text Tools for Effortless Transcription
- 13 Free Tools to Easily Transcribe Audio to Text
- 15 Surprising Ways Google's Speech-to-Text Boosts Productivity
- 7 Best Free Online Audio to Text Transcription Tools
- 9 Tips to Transcribe Speech to Text Faster and Better
- 13 Best Speech to Text Software for Windows 10 in 2023
- 7 Tips for Choosing the Best Transcriber for Audio to Text
- 11 Reasons Why Dragon Speech-to-Text Apps are Game-Changers
- 6 Secrets to Enhance Your Speech to Text Transcription
- 6 Brilliant Ways to Boost Productivity with Talk-to-Text on Your MacBook
- 6 Ways Transcription Software Converts Audio to Text
- 8 Tips to Transcribe Speech to Text Like a Pro
- 6 Reasons IBM Watson Speech to Text is a Game-Changer
- 14 Powerful Ways Talk-to-Text Improves Your Workflow
- 12 Top Windows Speech-to-Text Software for Efficient Transcription
- 12 Game-Changing Benefits of Apple's Speech to Text Technology
- 9 Powerful Use Cases for AWS Speech to Text Technology
- 10 Easy Steps to Transcribe YouTube Videos to Text
- transcription audio en texte
- online audio transcription
- free audio file transcription
- free ai audio transcription
- audio transcription service
- audio transcription online free
- audio transcription free online
- audio to transcription software
- audio and transcript
- ai audio transcription free
- voice recording to text converter
- translate voice recording to text
- record voice to text
- audio recording to text converter
- voice recording and transcription
- chatgpt voice to text
- gmail voice to text
- speech to text reader
- speech to text ai free
- speech to talk
- Twitter/X API Alternatives for AI Agents and Developers in 2026
- ChatGPT Knows Ford. It Just Doesn't Quote Ford
- Meshy AI: How to Create 3D Models from Text and Images
- How SEO and Marketing Dashboards Empower Agencies to Drive Results
- How to Use AI Tools to Find Internal Linking Opportunities Across a Business Website
- Discover Your Perfect Haircut with AI Hairstyle Apps
- Free Reputation Calculator Tools: How They're Adapting to Score AI Visibility, Not Just Rankings
- Design Professional Flyers for Free on Your Phone
- Best Free Flyer Maker Apps for Android: Design Like a Pro
- How to Know If Your Business Is Ready for an AI Customer Service Agent
- Top 10 AI Marketing Tools Content Creators Need in 2025
- Top 5 Cold Email Software: Maximize Your Outreach in 2025
- Testing Audio-Visual Realism: An In-Depth Look at Modern Facial Re-Animation
- Inside Motion Sync: A Real-World Test of AI Character Animation
- Twitter/X API Alternatives for AI Agents and Developers in 2026
- Your Business Data Could Be Worth Up to $4M. Find Out Without Uploading a Single File.
- Can an eSIM Plan Save You Time During Travel Setup?
- AI Video Editor Review: A Hands-On Look at Prompt-Based Video Editing
- Keep Characters Consistent Across Scenes With Image-to-Video AI
- How to Convert BTC to HNT

Copyright ©2026 toolify