



Total runs:
38.3K
Run Growth:
-3.1K
Growth Rate:
-8.04%
🎮️ Github | 🤗 Hugging Face | 🤖 ModelScope | 📑 Home Page | 📙 Paper
Valley is a cutting-edge multimodal large model designed to handle a variety of tasks involving text, images, and video data, which is developed by ByteDance. Our model
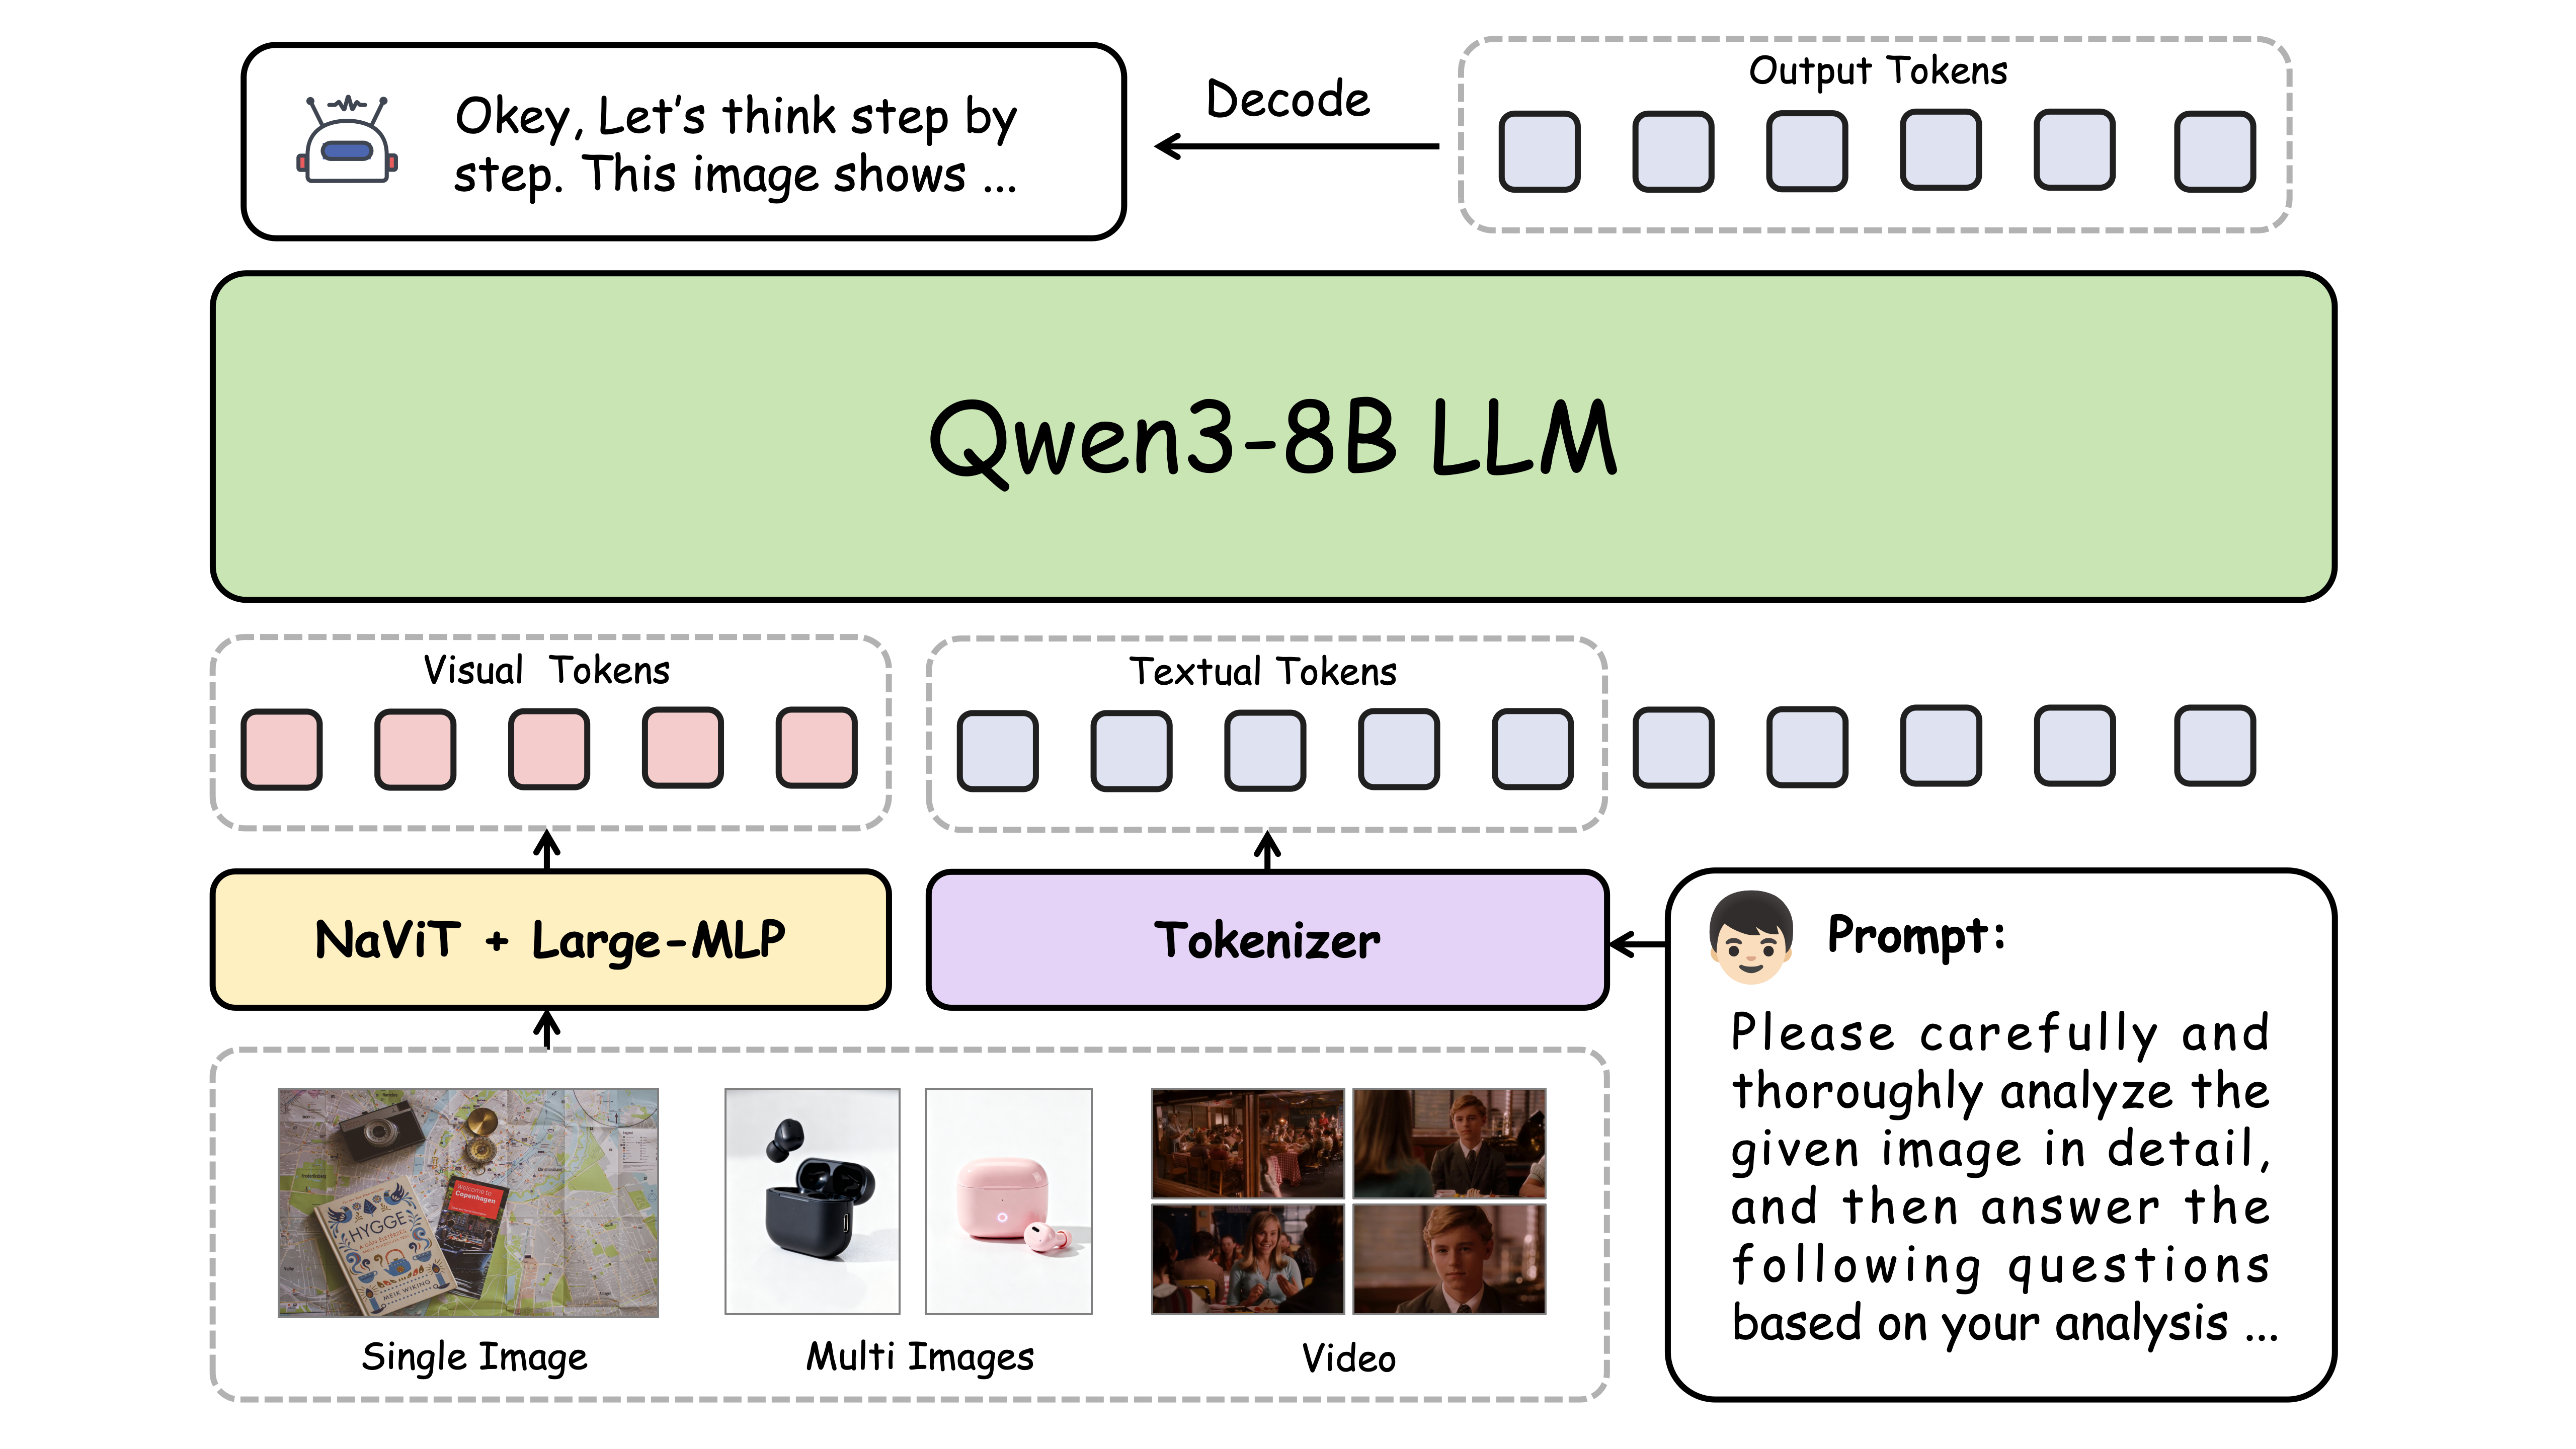
For the LLM, we select Qwen3-8B-Base, chosen for its strong reasoning and language comprehension abilities. The Vision Encoder leverages Qwen2-VL-ViT, capable of processing dynamic-resolution inputs—a more robust alternative to the commonly used tiling approach when dealing with images of extreme aspect ratios. The Projector employs a 2×2 pixelshuffle downsampling on visual tokens, followed by a two-layer MLP with a 64k hidden dimension, providing high alignment capacity between modalities. This architectural design ensures that Valley2.5 achieves a balanced trade-off between representational power, computational efficiency, and multimodal adaptability.
The overall architecture is shown as follows:
pip install torch==2.4.0 torchvision==0.19.0 torchaudio==2.4.0 --index-url https://download.pytorch.org/whl/cu121
pip install -r requirements.txt
All of our open-source models are licensed under the Apache-2.0 license.
We list related Project
All of our open-source models are licensed under the Apache-2.0 license.
The Data-Ecommerce-Platform Governance-Basic Algorithms Team focuses on the research and development of multi-modal large model algorithms and foundational algorithms, continuously delving deeply into this field. Our mission is to optimize algorithms and collaborate with business teams to comprehensively govern the quality and ecosystem of ByteDance's e-commerce products. Currently, the team has a strong demand for foundational algorithm expertise in NLP, CV, and multimodal technologies. We welcome inquiries and look forward to working on challenging projects with talented individuals like you!
Location: Beijing / Shanghai / Singapore
Contact & Resume Submission: [email protected]
Tiktok-电商,基础算法团队专注于多模态大模型算法和基础算法的研发,并在此方向上持续深耕,期待和优秀的你(实习/全职),一起做有挑战的事情!
岗位城市:北京/上海/新加坡
咨询&简历投递: [email protected]
@article{wu2025valley2,
  title={Valley2: Exploring Multimodal Models with Scalable Vision-Language Design},
  author={Wu, Ziheng and Chen, Zhenghao and Luo, Ruipu and Zhang, Can and Gao, Yuan and He, Zhentao and Wang, Xian and Lin, Haoran and Qiu, Minghui},
  journal={arXiv preprint arXiv:2501.05901},
  year={2025}
}