



Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
This model was converted to Core ML for use on Apple Silicon devices by following Apple's instructions
here
.
Provide the model to an app such as
Mochi Diffusion
to generate images.
split_einsum
version is compatible with all compute unit options including Neural Engine.
original
version is only compatible with CPU & GPU option.
Source: Hugging Face
Anything V3.1 is a third-party continuation of a latent diffusion model, Anything V3.0. This model is claimed to be a better version of Anything V3.0 with a fixed VAE model and a fixed CLIP position id key. The CLIP reference was taken from Stable Diffusion V1.5. The VAE was swapped using Kohya's merge-vae script and the CLIP was fixed using Arena's stable-diffusion-model-toolkit webui extensions.
Anything V3.2 is supposed to be a resume training of Anything V3.1. The current model has been fine-tuned with a learning rate of 2.0e-6, 50 epochs, and 4 batch sizes on datasets collected from many sources, with 1/4 of them being synthetic datasets. The dataset has been preprocessed using the Aspect Ratio Bucketing Tool so that it can be converted to latents and trained at non-square resolutions. This model is supposed to be a test model to see how the clip fix affects training. Like other anime-style Stable Diffusion models, it also supports Danbooru tags to generate images.
e.g. 1girl, white hair, golden eyes, beautiful eyes, detail, flower meadow, cumulonimbus clouds, lighting, detailed sky, garden
Automatic1111's Stable Diffusion Webui
see:
'how-to-use'
diffusers
Anything V3.1
here
, or
Anything V3.2
here
, all model are in
.safetensors
format.
lowres, bad anatomy, bad hands, text, error, missing fingers, extra digit, fewer digits, cropped, worst quality, low quality, normal quality, jpeg artifacts, signature, watermark, username, blurry
masterpiece, best quality, illustration, beautiful detailed, finely detailed, dramatic light, intricate details
This model can be used just like any other Stable Diffusion model. For more information, please have a look at the Stable Diffusion . You can also export the model to ONNX , MPS and/or FLAX/JAX . Pretrained model currently based on Anything V3.1.
You should install dependencies below in order to running the pipeline
pip install diffusers transformers accelerate scipy safetensors
Running the pipeline (if you don't swap the scheduler it will run with the default DDIM, in this example we are swapping it to DPMSolverMultistepScheduler):
import torch
from torch import autocast
from diffusers import StableDiffusionPipeline, DPMSolverMultistepScheduler

model_id = "cag/anything-v3-1"

# Use the DPMSolverMultistepScheduler (DPM-Solver++) scheduler here instead
pipe = StableDiffusionPipeline.from_pretrained(model_id, torch_dtype=torch.float16)
pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config)
pipe = pipe.to("cuda")

prompt = "masterpiece, best quality, high quality, 1girl, solo, sitting, confident expression, long blonde hair, blue eyes, formal dress"
negative_prompt = "lowres, bad anatomy, bad hands, text, error, missing fingers, extra digit, fewer digits, cropped, worst quality, low quality, normal quality, jpeg artifacts, signature, watermark, username, blurry"

with autocast("cuda"):
    image = pipe(prompt,
                 negative_prompt=negative_prompt,
                 width=512,
                 height=728,
                 guidance_scale=12,
                 num_inference_steps=50).images[0]

image.save("anime_girl.png")
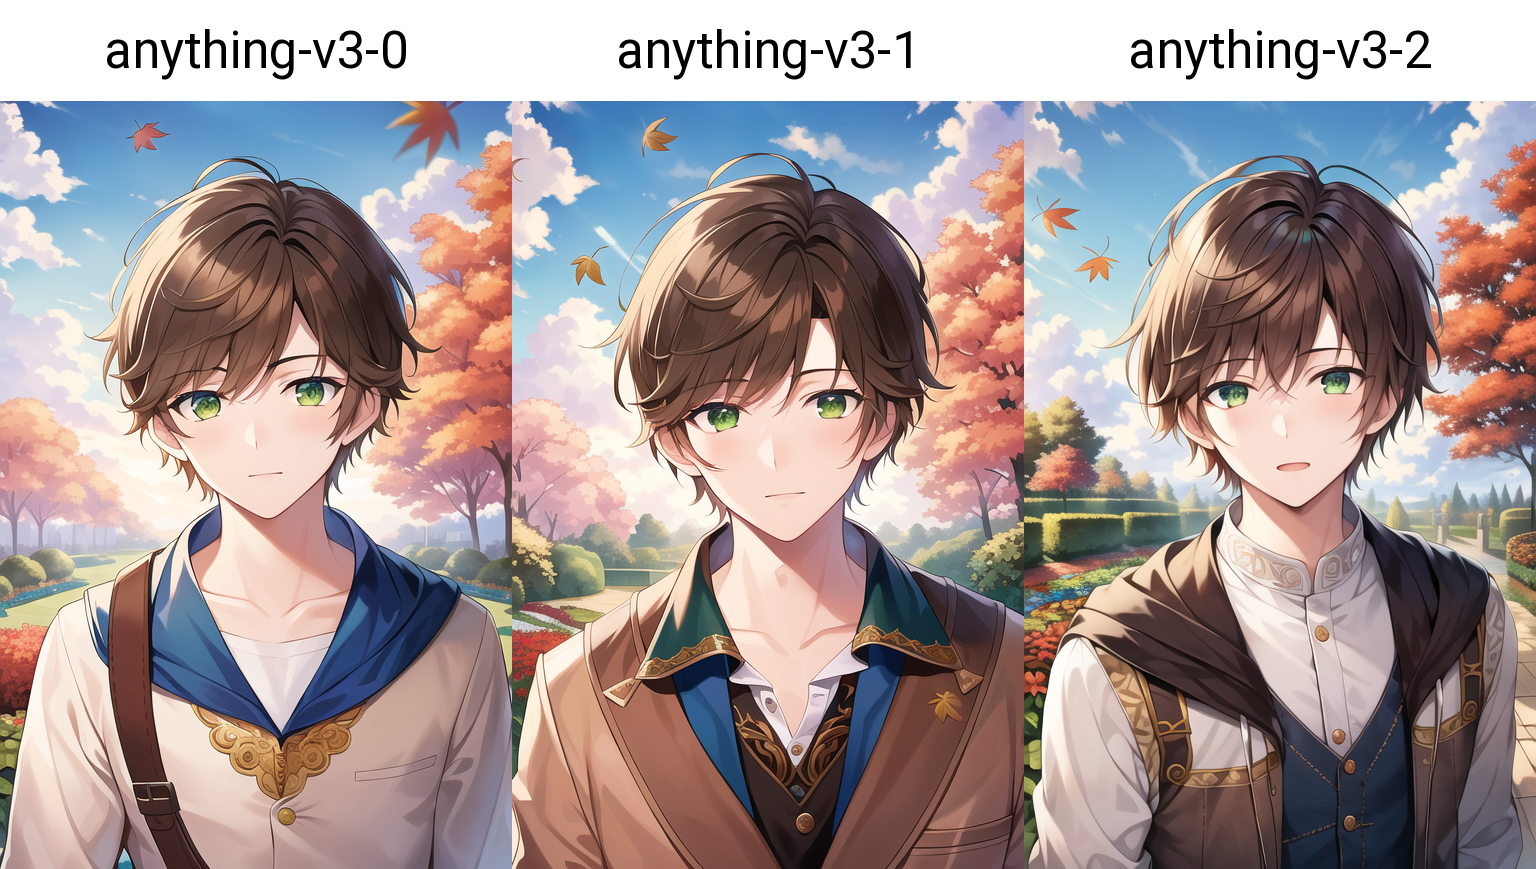
This model is overfitted and cannot follow prompts well, even after the text encoder has been fixed. This leads to laziness in prompting, as you will only get good results by typing 1girl. Additionally, this model is anime-based and biased towards anime female characters. It is difficult to generate masculine male characters without providing specific prompts. Furthermore, not much has changed compared to the Anything V3.0 base model, as it only involved swapping the VAE and CLIP models and then fine-tuning for 50 epochs with small scale datasets.
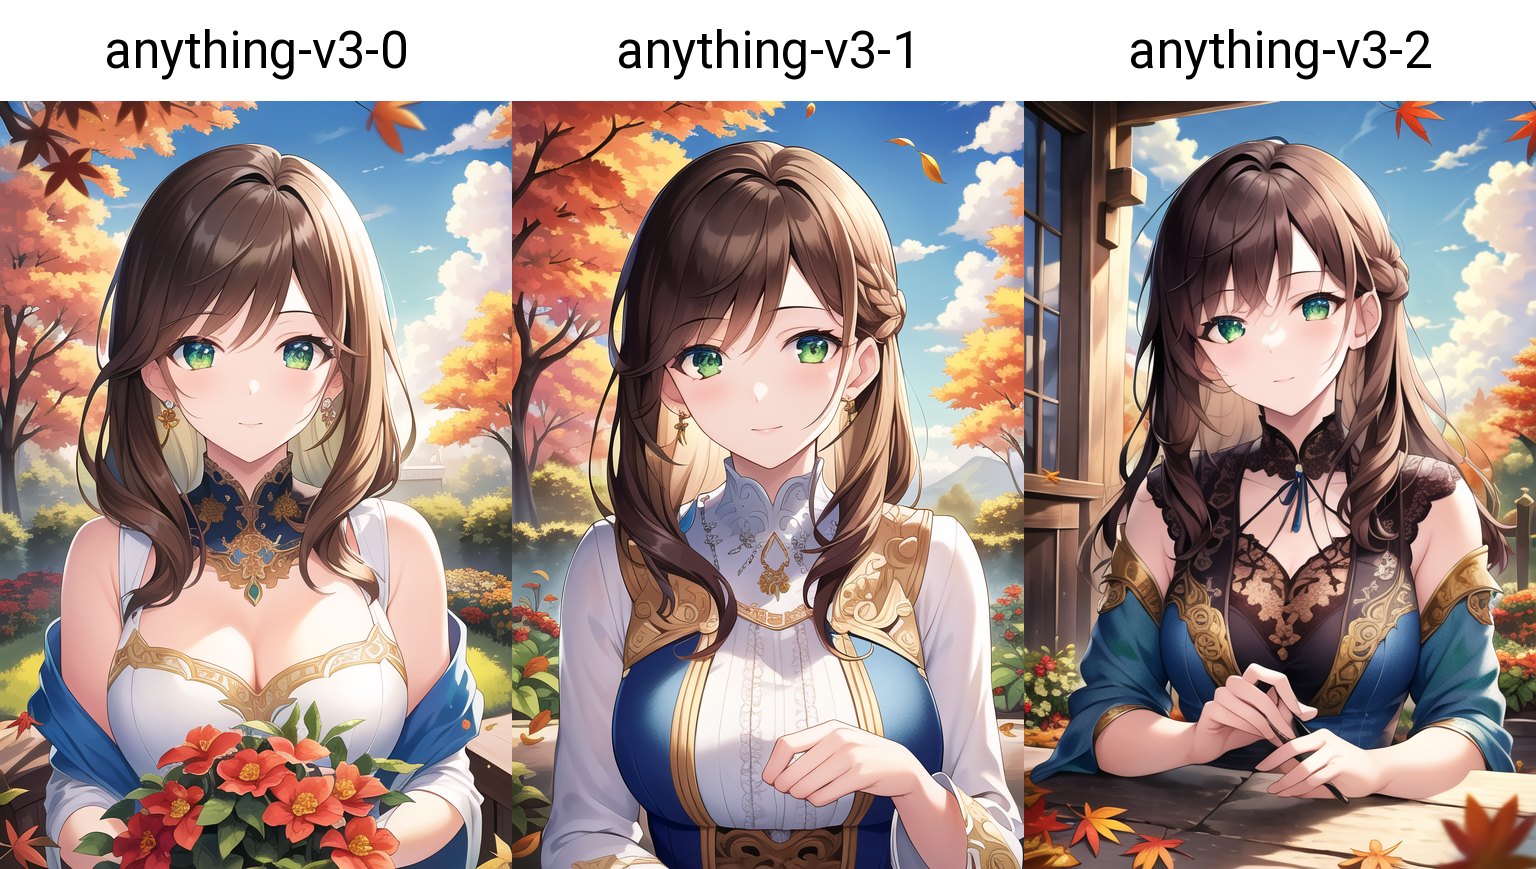
Here is some cherrypicked samples and comparison between available models
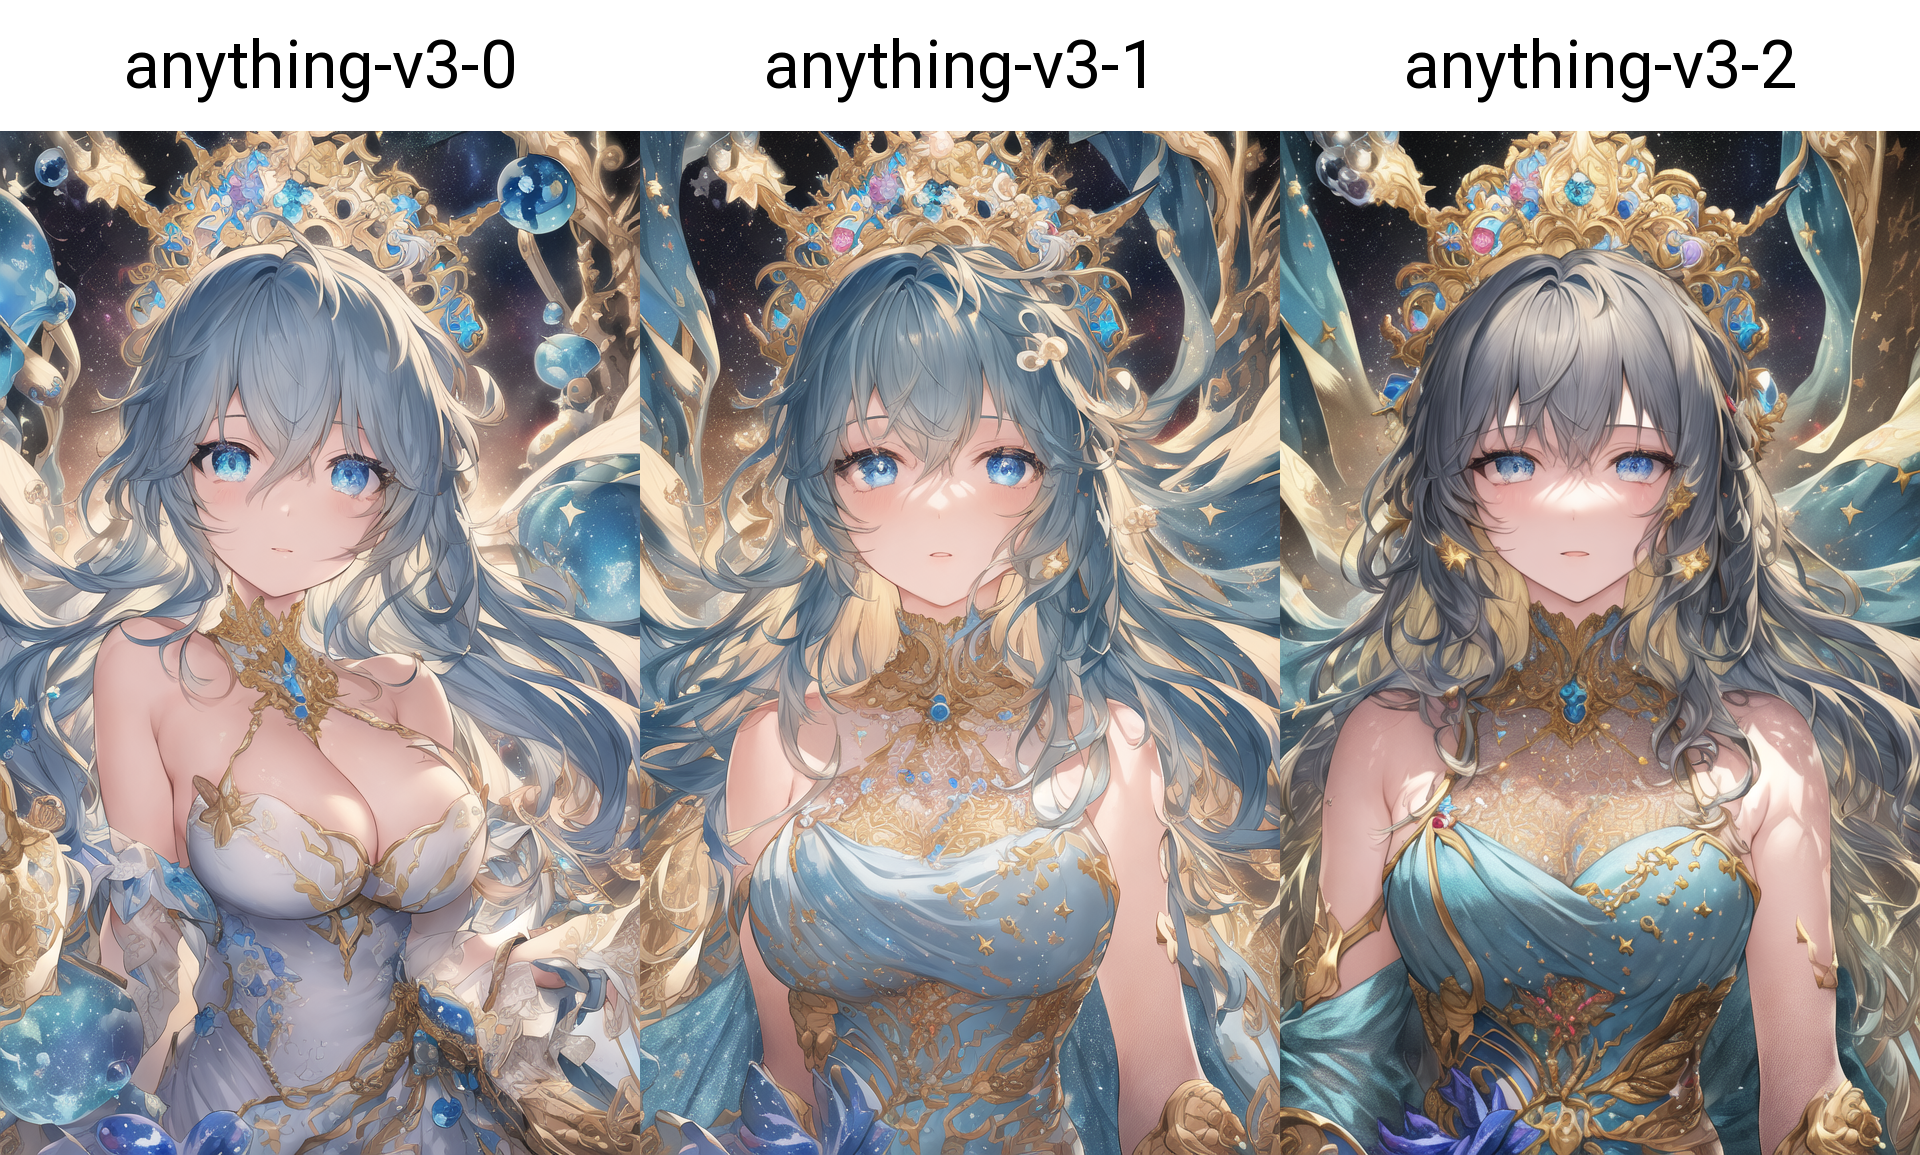
This model is open access and available to all, with a CreativeML OpenRAIL-M license further specifying rights and usage. The CreativeML OpenRAIL License specifies:
Public domain.