



Total runs:
1.8K
Run Growth:
699
Growth Rate:
39.83%

👋 Join our
WeChat
and
Discord
community
📍 Use GLM-OCR's
API
👉
GLM-OCR SDK
Recommended
GLM-OCR is a multimodal OCR model for complex document understanding, built on the GLM-V encoder–decoder architecture. It introduces Multi-Token Prediction (MTP) loss and stable full-task reinforcement learning to improve training efficiency, recognition accuracy, and generalization. The model integrates the CogViT visual encoder pre-trained on large-scale image–text data, a lightweight cross-modal connector with efficient token downsampling, and a GLM-0.5B language decoder. Combined with a two-stage pipeline of layout analysis and parallel recognition based on PP-DocLayout-V3, GLM-OCR delivers robust and high-quality OCR performance across diverse document layouts.
Key Features
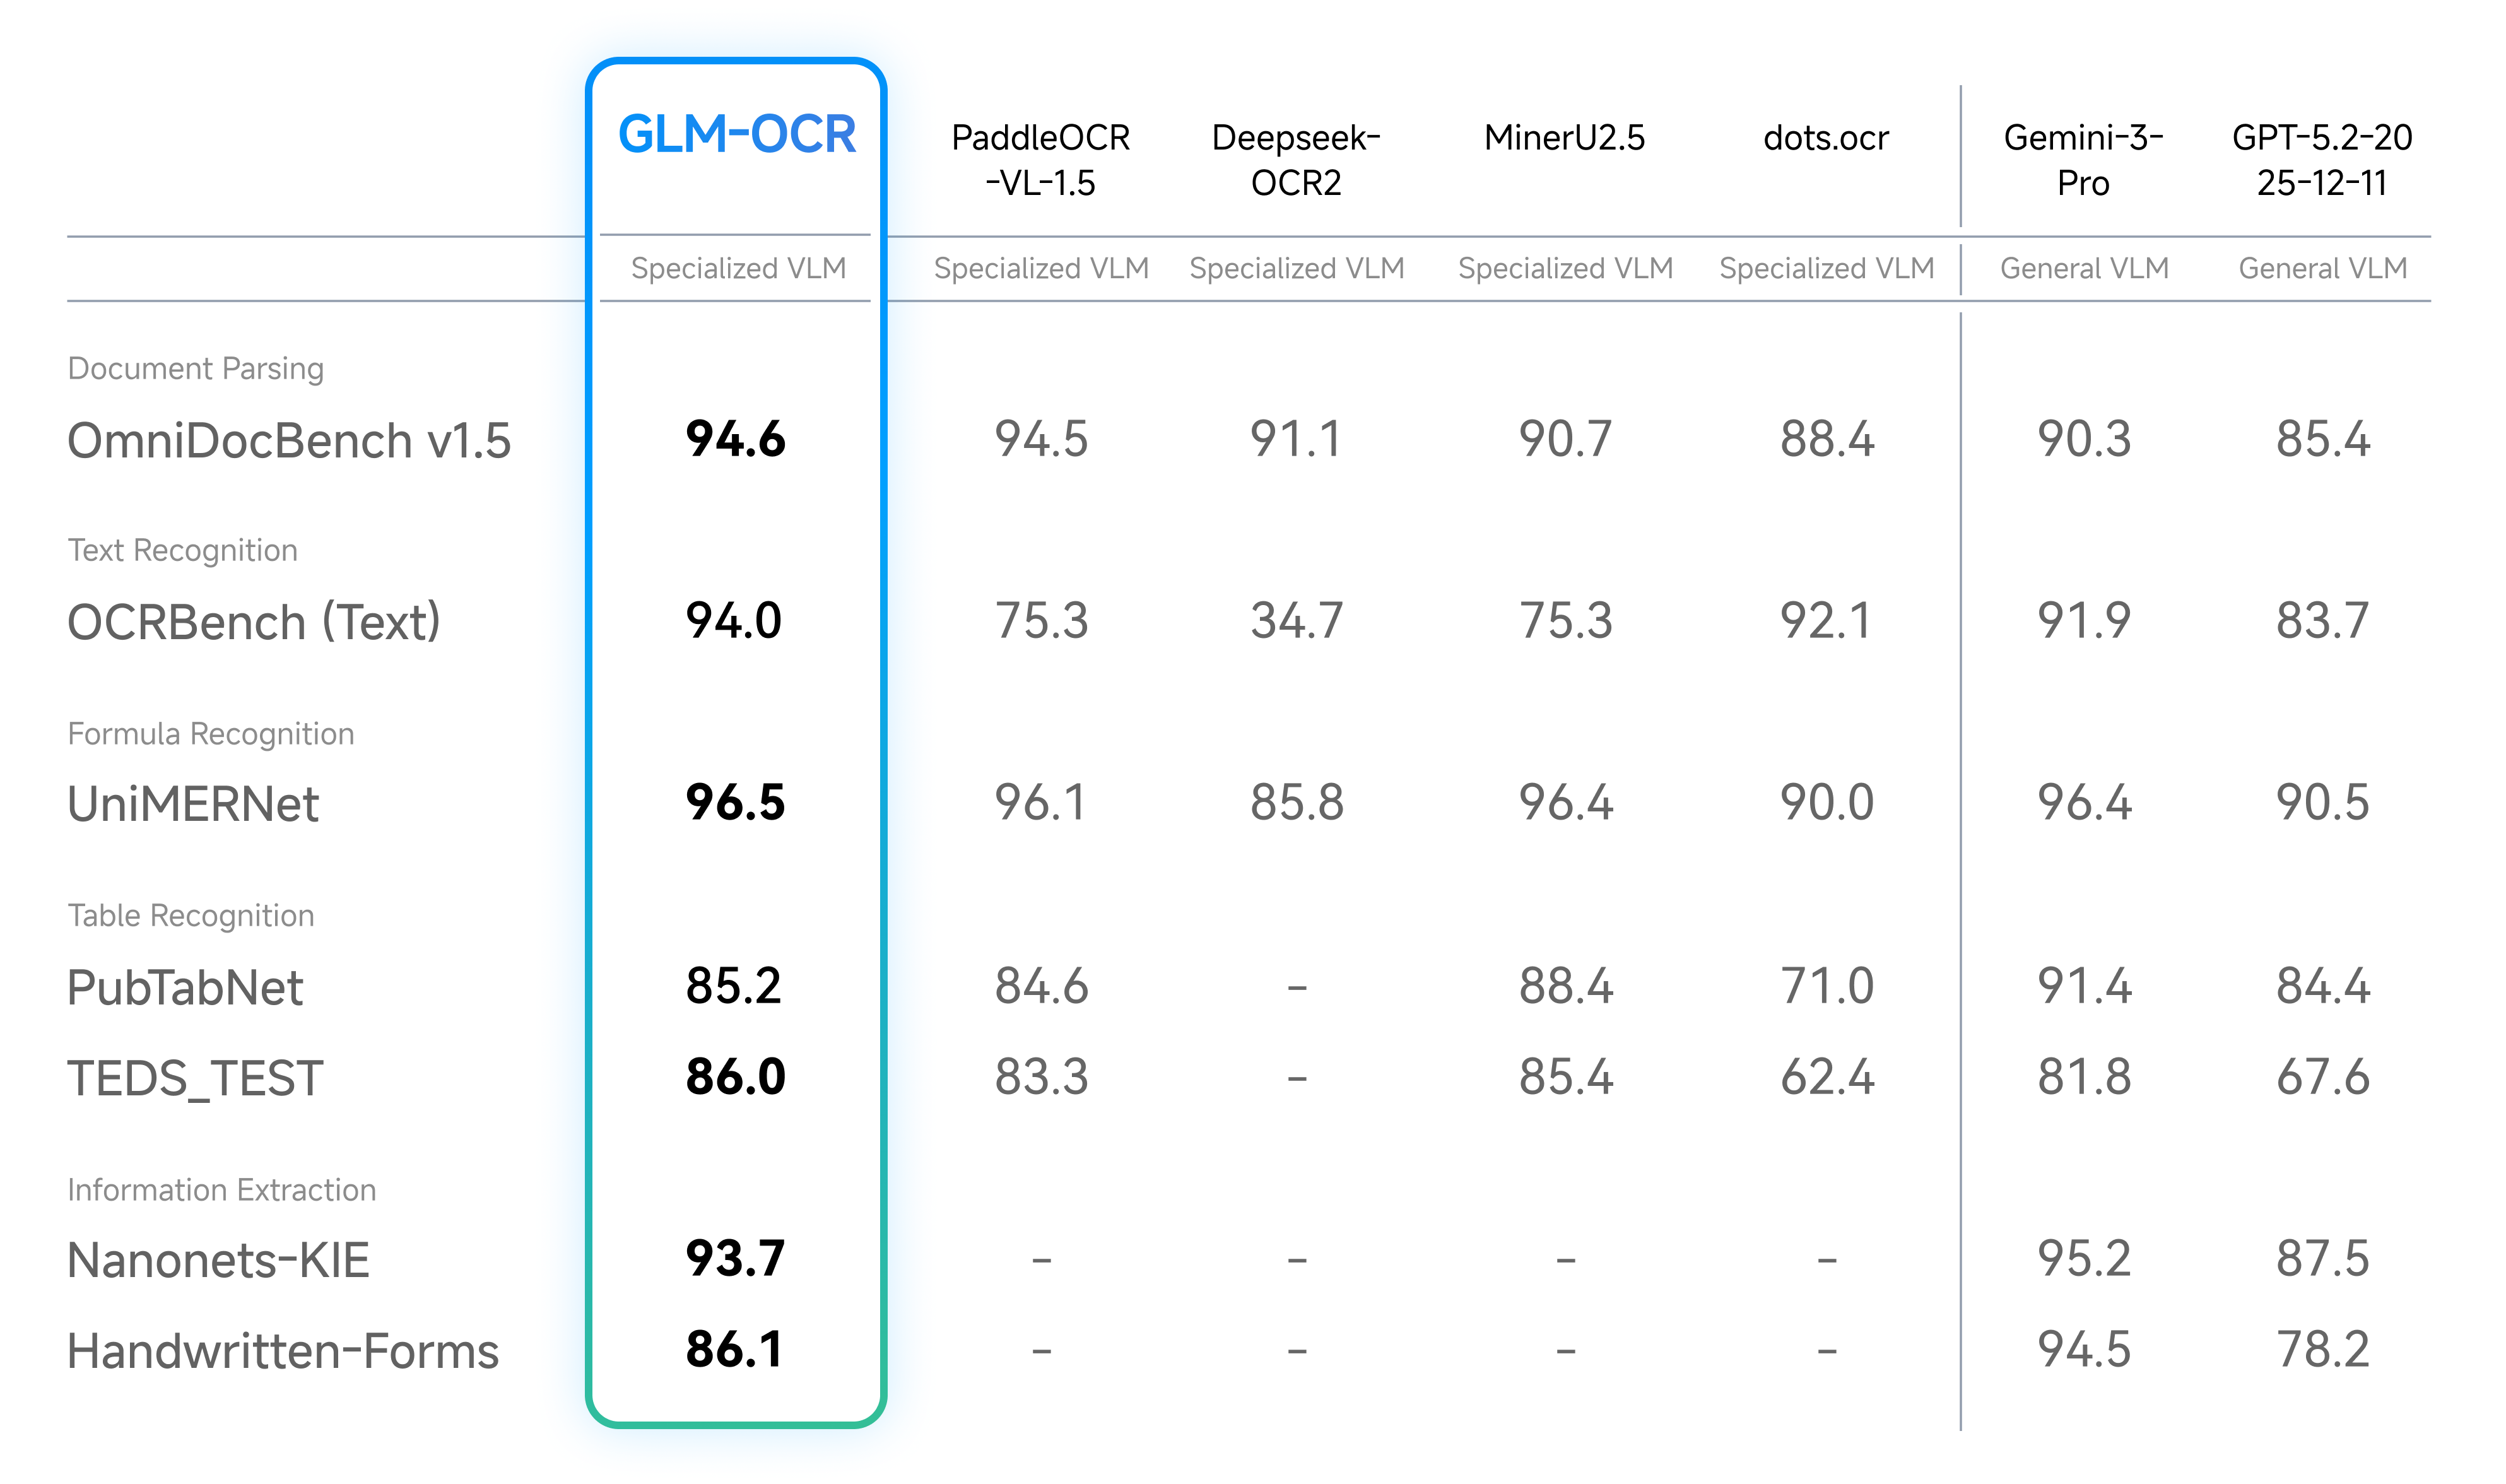
State-of-the-Art Performance : Achieves a score of 94.62 on OmniDocBench V1.5, ranking #1 overall, and delivers state-of-the-art results across major document understanding benchmarks, including formula recognition, table recognition, and information extraction.
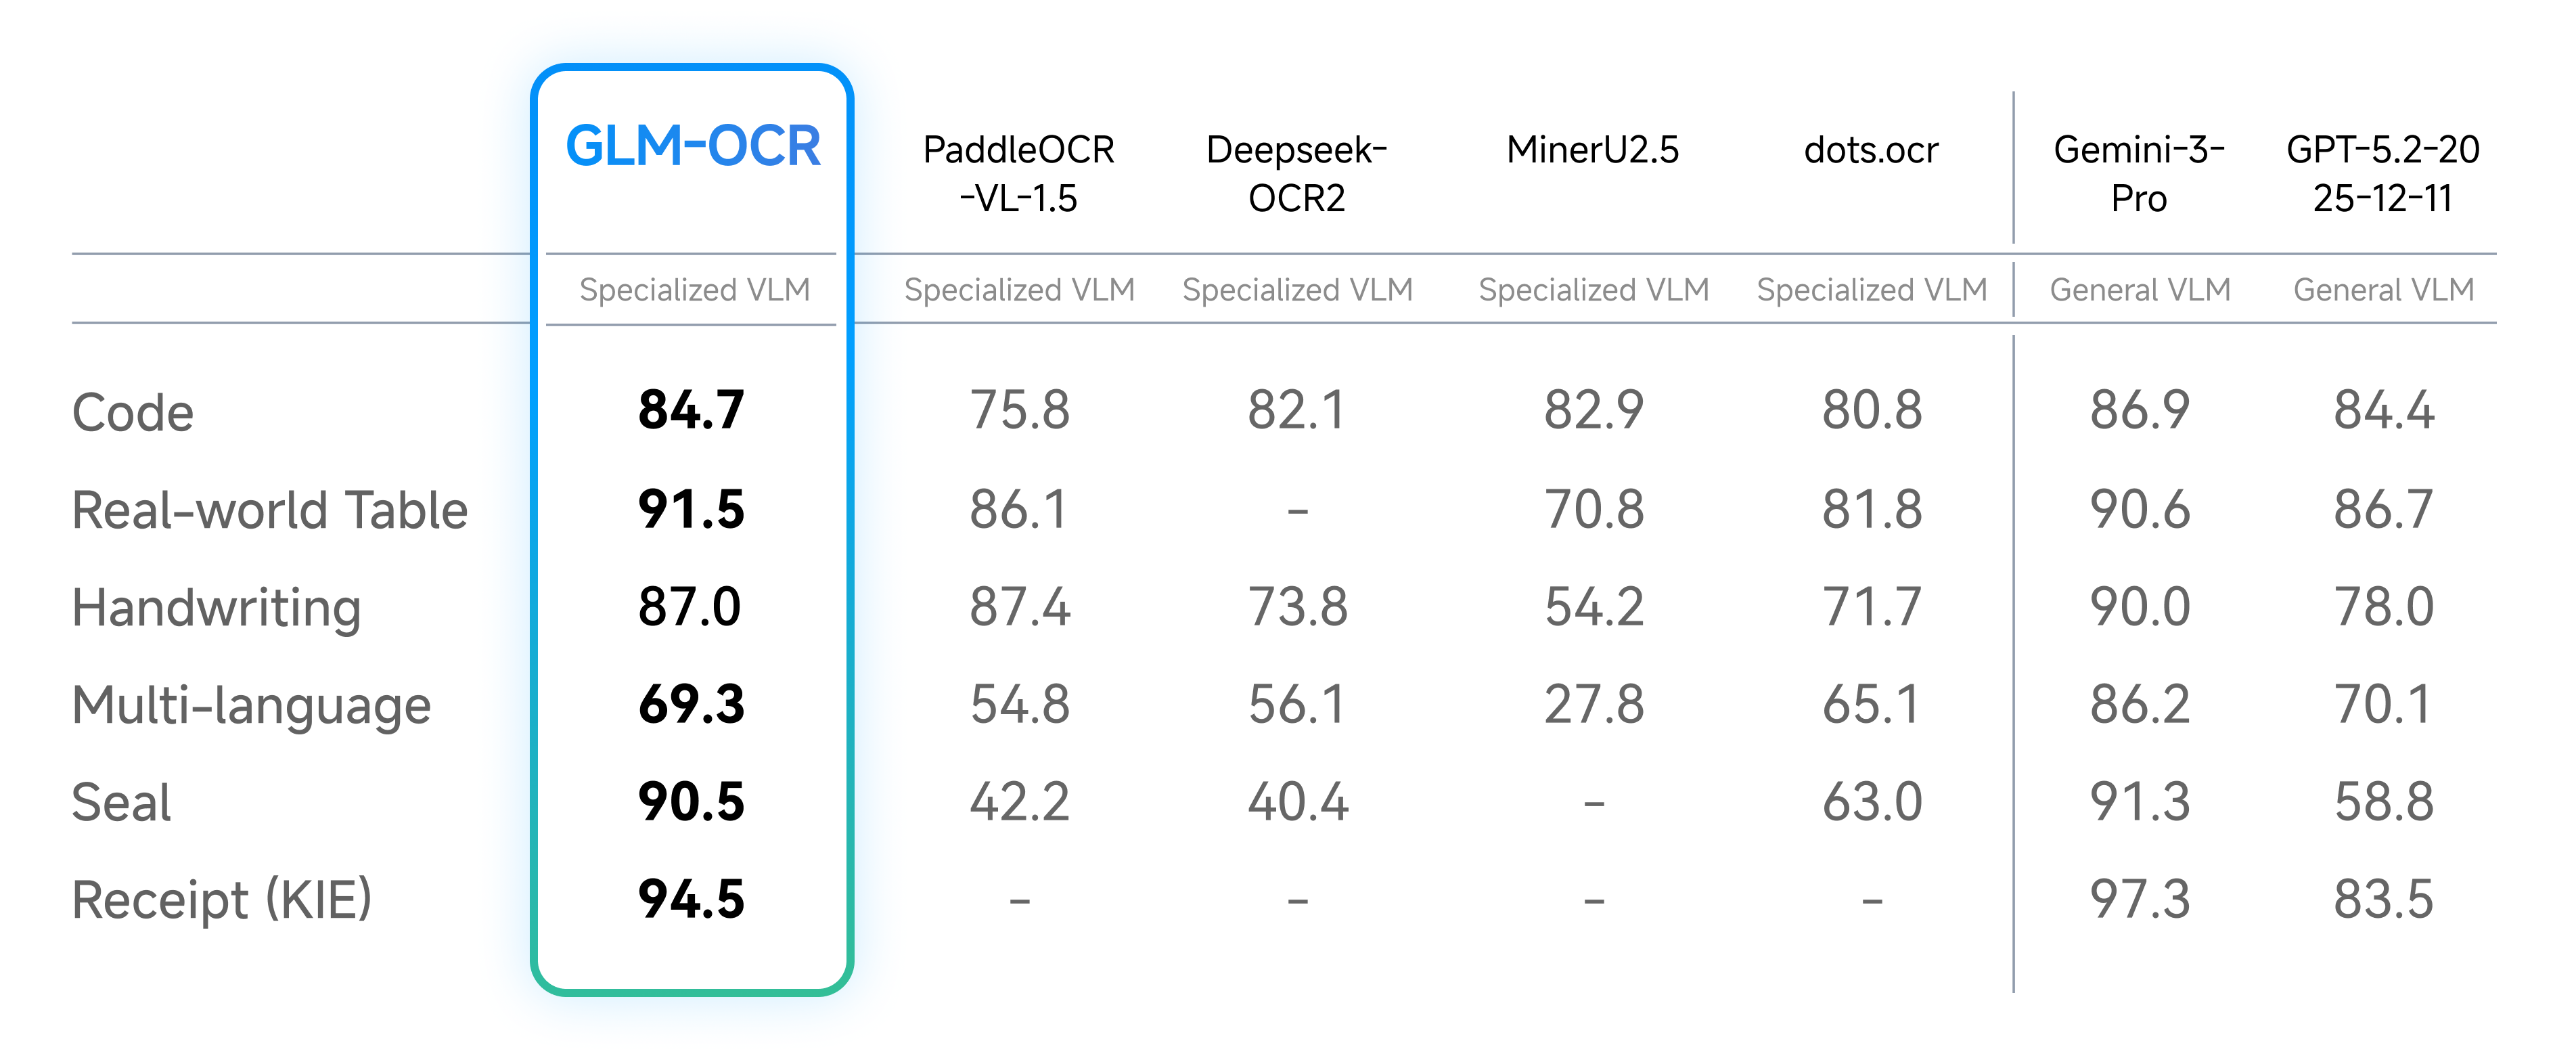
Optimized for Real-World Scenarios : Designed and optimized for practical business use cases, maintaining robust performance on complex tables, code-heavy documents, seals, and other challenging real-world layouts.
Efficient Inference : With only 0.9B parameters, GLM-OCR supports deployment via vLLM, SGLang, and Ollama, significantly reducing inference latency and compute cost, making it ideal for high-concurrency services and edge deployments.
Easy to Use : Fully open-sourced and equipped with a comprehensive SDK and inference toolchain, offering simple installation, one-line invocation, and smooth integration into existing production pipelines.
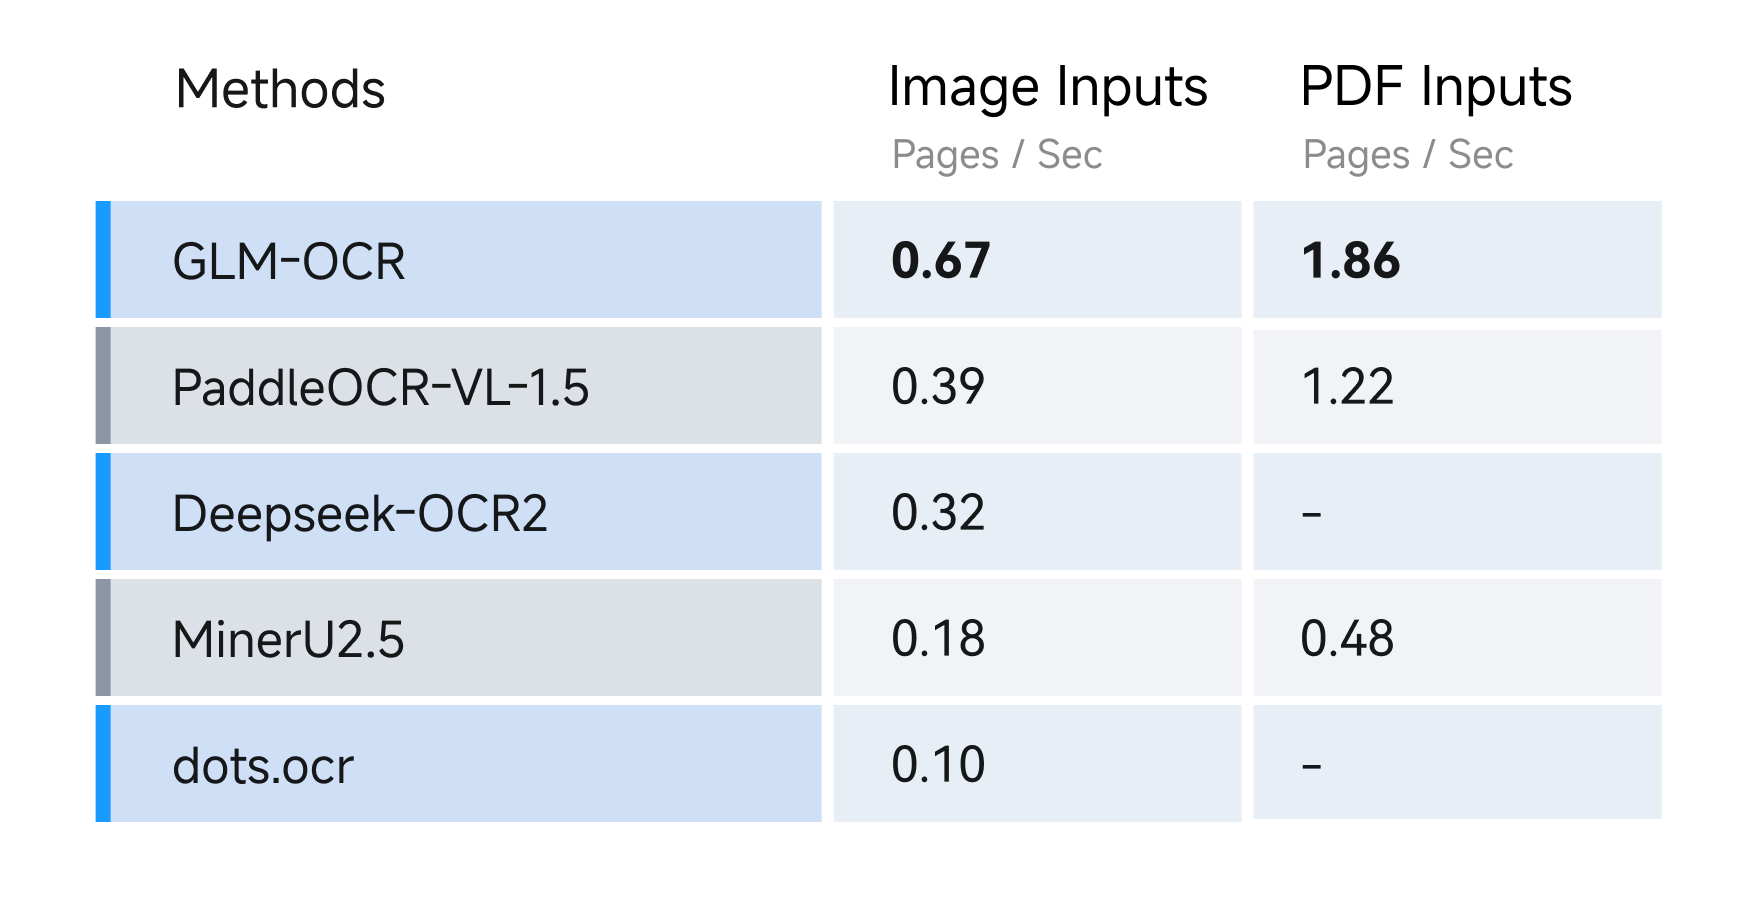
For speed, we compared different OCR methods under identical hardware and testing conditions (single replica, single concurrency), evaluating their performance in parsing and exporting Markdown files from both image and PDF inputs. Results show GLM-OCR achieves a throughput of 1.86 pages/second for PDF documents and 0.67 images/second for images, significantly outperforming comparable models.
For document parsing tasks, we strongly recommend using our official SDK . Compared with model-only inference, the SDK integrates PP-DocLayoutV3 and provides a complete, easy-to-use pipeline for document parsing, including layout analysis and structured output generation. This significantly reduces the engineering overhead required to build end-to-end document intelligence systems.
Note that the SDK is currently designed for document parsing tasks only. For information extraction tasks, please refer to the following section and run inference directly with the model.
pip install -U vllm --extra-index-url https://wheels.vllm.ai/nightly
or using docker with:
docker pull vllm/vllm-openai:nightly
pip install git+https://github.com/huggingface/transformers.git
vllm serve zai-org/GLM-OCR  --allowed-local-media-path /  --port 8080
docker pull lmsysorg/sglang:dev
or build it from source with:
pip install git+https://github.com/sgl-project/sglang.git#subdirectory=python
pip install git+https://github.com/huggingface/transformers.git
python -m sglang.launch_server --model zai-org/GLM-OCR --port 8080
ollama run glm-ocr
Ollama will automatically use image file path when an image is dragged into the terminal:
ollama run glm-ocr Text Recognition: ./image.png
pip install git+https://github.com/huggingface/transformers.git
from transformers import AutoProcessor, AutoModelForImageTextToText
import torch

MODEL_PATH = "zai-org/GLM-OCR"
messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image",
                "url": "test_image.png"
            },
            {
                "type": "text",
                "text": "Text Recognition:"
            }
        ],
    }
]
processor = AutoProcessor.from_pretrained(MODEL_PATH)
model = AutoModelForImageTextToText.from_pretrained(
    pretrained_model_name_or_path=MODEL_PATH,
    torch_dtype="auto",
    device_map="auto",
)
inputs = processor.apply_chat_template(
    messages,
    tokenize=True,
    add_generation_prompt=True,
    return_dict=True,
    return_tensors="pt"
).to(model.device)
inputs.pop("token_type_ids", None)
generated_ids = model.generate(**inputs, max_new_tokens=8192)
output_text = processor.decode(generated_ids[0][inputs["input_ids"].shape[1]:], skip_special_tokens=False)
print(output_text)
GLM-OCR currently supports two types of prompt scenarios:
{
    "text": "Text Recognition:",
    "formula": "Formula Recognition:",
    "table": "Table Recognition:"
}
请按下列JSON格式输出图中信息:
{
    "id_number": "",
    "last_name": "",
    "first_name": "",
    "date_of_birth": "",
    "address": {
        "street": "",
        "city": "",
        "state": "",
        "zip_code": ""
    },
    "dates": {
        "issue_date": "",
        "expiration_date": ""
    },
    "sex": ""
}
⚠️ Note: When using information extraction, the output must strictly adhere to the defined JSON schema to ensure downstream processing compatibility.
This project is inspired by the excellent work of the following projects and communities:
The GLM-OCR model is released under the MIT License.
The complete OCR pipeline integrates PP-DocLayoutV3 for document layout analysis, which is licensed under the Apache License 2.0. Users should comply with both licenses when using this project.