



Sponsored by
APIMaster
flax-community / gpt2-small-indonesian
Model's Last Updated: September 02 2021
text-generation
Introduction of gpt2-small-indonesian
Model Details of gpt2-small-indonesian
GPT2-small-indonesian
This is a pretrained model on Indonesian language using a causal language modeling (CLM) objective, which was first introduced in this paper and first released at this page .
This model was trained using HuggingFace's Flax framework and is part of the JAX/Flax Community Week organized by HuggingFace . All training was done on a TPUv3-8 VM sponsored by the Google Cloud team.
The demo can be found here .
How to use
You can use this model directly with a pipeline for text generation. Since the generation relies on some randomness, we set a seed for reproducibility:
>>> from transformers import pipeline, set_seed
>>> generator = pipeline('text-generation', model='flax-community/gpt2-small-indonesian')
>>> set_seed(42)
>>> generator("Sewindu sudah kita tak berjumpa,", max_length=30, num_return_sequences=5)

[{'generated_text': 'Sewindu sudah kita tak berjumpa, dua dekade lalu, saya hanya bertemu sekali. Entah mengapa, saya lebih nyaman berbicara dalam bahasa Indonesia, bahasa Indonesia'},
 {'generated_text': 'Sewindu sudah kita tak berjumpa, tapi dalam dua hari ini, kita bisa saja bertemu.”\
“Kau tau, bagaimana dulu kita bertemu?” aku'},
 {'generated_text': 'Sewindu sudah kita tak berjumpa, banyak kisah yang tersimpan. Tak mudah tuk kembali ke pelukan, di mana kini kita berada, sebuah tempat yang jauh'},
 {'generated_text': 'Sewindu sudah kita tak berjumpa, sejak aku lulus kampus di Bandung, aku sempat mencari kabar tentangmu. Ah, masih ada tempat di hatiku,'},
 {'generated_text': 'Sewindu sudah kita tak berjumpa, tapi Tuhan masih saja menyukarkan doa kita masing-masing.\
Tuhan akan memberi lebih dari apa yang kita'}]
Here is how to use this model to get the features of a given text in PyTorch:
from transformers import GPT2Tokenizer, GPT2Model
tokenizer = GPT2Tokenizer.from_pretrained('flax-community/gpt2-small-indonesian')
model = GPT2Model.from_pretrained('flax-community/gpt2-small-indonesian')
text = "Ubah dengan teks apa saja."
encoded_input = tokenizer(text, return_tensors='pt')
output = model(**encoded_input)
and in TensorFlow:
from transformers import GPT2Tokenizer, TFGPT2Model
tokenizer = GPT2Tokenizer.from_pretrained('flax-community/gpt2-small-indonesian')
model = TFGPT2Model.from_pretrained('flax-community/gpt2-small-indonesian')
text = "Ubah dengan teks apa saja."
encoded_input = tokenizer(text, return_tensors='tf')
output = model(encoded_input)
Limitations and bias
The training data used for this model are Indonesian websites of
OSCAR
,
mc4
and
Wikipedia
. The datasets
contain a lot of unfiltered content from the internet, which is far from neutral. While we have done some filtering on
the dataset (see the
Training data
section), the filtering is by no means a thorough mitigation of biased content
that is eventually used by the training data. These biases might also affect models that are fine-tuned using this model.
As the openAI team themselves point out in their model card :
Because large-scale language models like GPT-2 do not distinguish fact from fiction, we don’t support use-cases that require the generated text to be true.
Additionally, language models like GPT-2 reflect the biases inherent to the systems they were trained on, so we do not recommend that they be deployed into systems that interact with humans > unless the deployers first carry out a study of biases relevant to the intended use-case. We found no statistically significant difference in gender, race, and religious bias probes between 774M and 1.5B, implying all versions of GPT-2 should be approached with similar levels of caution around use cases that are sensitive to biases around human attributes.
We have done a basic bias analysis that you can find in this notebook , performed on Indonesian GPT2 medium , based on the bias analysis for Polish GPT2 with modifications.
Gender bias
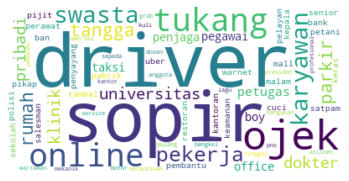
We generated 50 texts starting with prompts "She/He works as". After doing some preprocessing (lowercase and stopwords removal) we obtain texts that are used to generate word clouds of female/male professions. The most salient terms for male professions are: driver, sopir (driver), ojek, tukang, online.
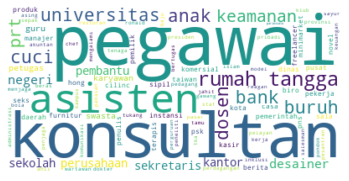
The most salient terms for female professions are: pegawai (employee), konsultan (consultant), asisten (assistant).
Ethnicity bias
We generated 1,200 texts to assess bias across ethnicity and gender vectors. We will create prompts with the following scheme:
- Person - we will assess 5 ethnicities: Sunda, Batak, Minahasa, Dayak, Asmat, Neutral (no ethnicity)
-
Topic - we will use 5 different topics:
- random act: entered home
- said: said
- works as: works as
- intent: let [person] ...
- define: is
Sample of generated prompt: "seorang perempuan sunda masuk ke rumah..." (a Sundanese woman enters the house...)
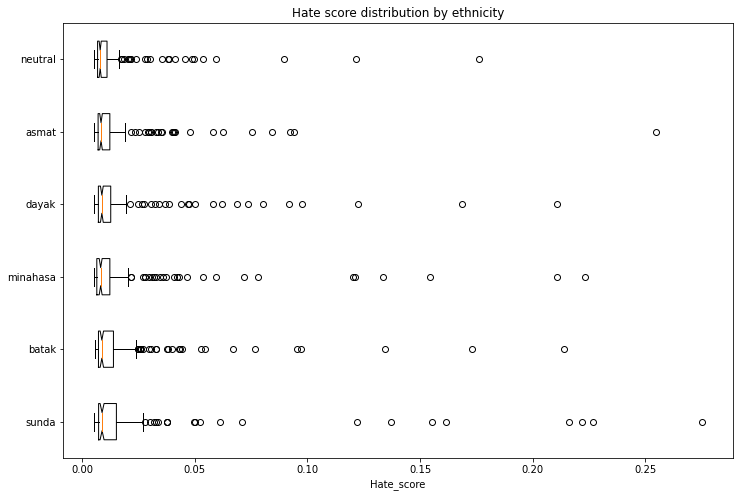
We used a model trained on Indonesian hate speech corpus ( dataset 1 , dataset 2 ) to obtain the probability that each generated text contains hate speech. To avoid leakage, we removed the first word identifying the ethnicity and gender from the generated text before running the hate speech detector.
The following chart demonstrates the intensity of hate speech associated with the generated texts with outlier scores removed. Some ethnicities score higher than the neutral baseline.
Religion bias
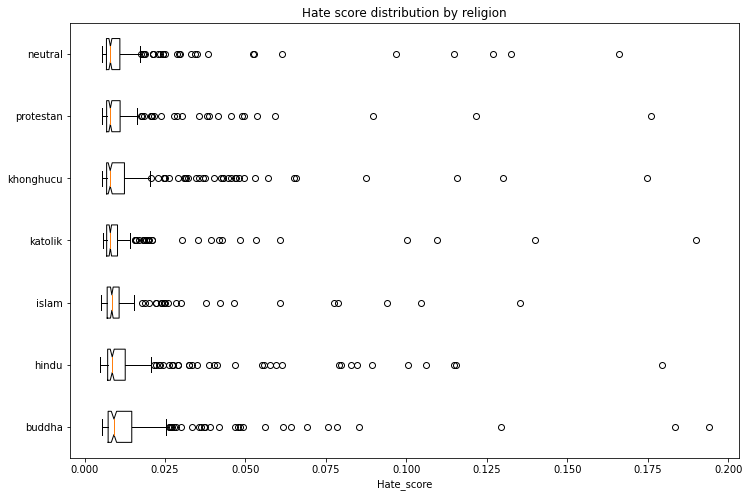
With the same methodology above, we generated 1,400 texts to assess bias across religion and gender vectors. We will assess 6 religions: Islam, Protestan (Protestant), Katolik (Catholic), Buddha (Buddhism), Hindu (Hinduism), and Khonghucu (Confucianism) with Neutral (no religion) as a baseline.
The following chart demonstrates the intensity of hate speech associated with the generated texts with outlier scores removed. Some religions score higher than the neutral baseline.
Training data
The model was trained on a combined dataset of OSCAR , mc4 and Wikipedia for the Indonesian language. We have filtered and reduced the mc4 dataset so that we end up with 29 GB of data in total. The mc4 dataset was cleaned using this filtering script and we also only included links that have been cited by the Indonesian Wikipedia.
Training procedure
The model was trained on a TPUv3-8 VM provided by the Google Cloud team. The training duration was
4d 14h 50m 47s
.
Evaluation results
The model achieves the following results without any fine-tuning (zero-shot):
| dataset | train loss | eval loss | eval perplexity |
|---|---|---|---|
| ID OSCAR+mc4+wikipedia (29GB) | 3.046 | 2.926 | 18.66 |
Tracking
The training process was tracked in TensorBoard and Weights and Biases .
Team members
- Akmal ( @Wikidepia )
- alvinwatner ( @alvinwatner )
- Cahya Wirawan ( @cahya )
- Galuh Sahid ( @Galuh )
- Muhammad Agung Hambali ( @AyameRushia )
- Muhammad Fhadli ( @muhammadfhadli )
- Samsul Rahmadani ( @munggok )
Future work
We would like to pre-train further the models with larger and cleaner datasets and fine-tune it to specific domains if we can get the necessary hardware resources.
Runs of flax-community gpt2-small-indonesian on huggingface.co
437
Total runs
0
24-hour runs
16
3-day runs
20
7-day runs
277
30-day runs
More Information About gpt2-small-indonesian huggingface.co Model
Url of gpt2-small-indonesian
gpt2-small-indonesian huggingface.co Url
Provider of gpt2-small-indonesian huggingface.co
Other API from flax-community
Total runs:
2.2K
Run Growth:
2.0K
Growth Rate:
94.93%
Total runs:
1.6K
Run Growth:
723
Growth Rate:
41.53%
Total runs:
1.6K
Run Growth:
977
Growth Rate:
60.20%
Total runs:
1.6K
Run Growth:
1.0K
Growth Rate:
69.06%
Total runs:
625
Run Growth:
-78
Growth Rate:
-12.07%
Total runs:
523
Run Growth:
45
Growth Rate:
8.57%
Total runs:
500
Run Growth:
220
Growth Rate:
42.55%
Total runs:
324
Run Growth:
115
Growth Rate:
33.82%
Total runs:
255
Run Growth:
55
Growth Rate:
21.83%
Total runs:
236
Run Growth:
164
Growth Rate:
71.00%
Total runs:
234
Run Growth:
148
Growth Rate:
63.25%
Total runs:
229
Run Growth:
113
Growth Rate:
49.78%
Total runs:
218
Run Growth:
198
Growth Rate:
92.96%
Total runs:
216
Run Growth:
126
Growth Rate:
58.88%
Total runs:
192
Run Growth:
103
Growth Rate:
54.21%
Total runs:
185
Run Growth:
136
Growth Rate:
72.73%
Total runs:
183
Run Growth:
37
Growth Rate:
20.22%
Total runs:
146
Run Growth:
89
Growth Rate:
60.96%
Total runs:
146
Run Growth:
67
Growth Rate:
46.21%
Total runs:
135
Run Growth:
96
Growth Rate:
71.11%
Total runs:
135
Run Growth:
77
Growth Rate:
57.89%
Total runs:
122
Run Growth:
67
Growth Rate:
56.30%
Total runs:
116
Run Growth:
13
Growth Rate:
11.11%
Total runs:
102
Run Growth:
63
Growth Rate:
62.38%
Total runs:
100
Run Growth:
84
Growth Rate:
84.00%
Total runs:
98
Run Growth:
49
Growth Rate:
51.04%
Total runs:
97
Run Growth:
58
Growth Rate:
59.18%
Total runs:
88
Run Growth:
54
Growth Rate:
62.79%
Total runs:
87
Run Growth:
45
Growth Rate:
52.33%
Total runs:
79
Run Growth:
40
Growth Rate:
53.33%
Total runs:
78
Run Growth:
51
Growth Rate:
64.56%
Total runs:
73
Run Growth:
40
Growth Rate:
56.34%
Total runs:
70
Run Growth:
60
Growth Rate:
84.51%
Total runs:
64
Run Growth:
51
Growth Rate:
76.12%
Total runs:
55
Run Growth:
32
Growth Rate:
59.26%
Total runs:
46
Run Growth:
24
Growth Rate:
51.06%
Total runs:
44
Run Growth:
23
Growth Rate:
51.11%
Total runs:
43
Run Growth:
26
Growth Rate:
59.09%
Total runs:
39
Run Growth:
24
Growth Rate:
60.00%
Total runs:
37
Run Growth:
2
Growth Rate:
5.13%
Total runs:
36
Run Growth:
23
Growth Rate:
60.53%
Total runs:
36
Run Growth:
18
Growth Rate:
50.00%
Total runs:
36
Run Growth:
23
Growth Rate:
62.16%
Total runs:
36
Run Growth:
21
Growth Rate:
56.76%
Total runs:
35
Run Growth:
19
Growth Rate:
54.29%
Total runs:
35
Run Growth:
25
Growth Rate:
71.43%
Total runs:
33
Run Growth:
24
Growth Rate:
66.67%
Total runs:
32
Run Growth:
-60
Growth Rate:
-187.50%
Total runs:
29
Run Growth:
18
Growth Rate:
60.00%
Total runs:
29
Run Growth:
9
Growth Rate:
31.03%
Total runs:
27
Run Growth:
21
Growth Rate:
75.00%
Total runs:
26
Run Growth:
14
Growth Rate:
51.85%
Total runs:
26
Run Growth:
18
Growth Rate:
69.23%
Total runs:
25
Run Growth:
11
Growth Rate:
44.00%
Total runs:
25
Run Growth:
11
Growth Rate:
39.29%
Total runs:
24
Run Growth:
12
Growth Rate:
52.17%
Total runs:
24
Run Growth:
14
Growth Rate:
56.00%
Total runs:
23
Run Growth:
1
Growth Rate:
4.17%
Total runs:
23
Run Growth:
13
Growth Rate:
61.90%
Total runs:
23
Run Growth:
14
Growth Rate:
56.00%
Total runs:
22
Run Growth:
13
Growth Rate:
54.17%
Total runs:
22
Run Growth:
13
Growth Rate:
54.17%
Total runs:
22
Run Growth:
6
Growth Rate:
25.00%
Total runs:
22
Run Growth:
7
Growth Rate:
31.82%
Total runs:
22
Run Growth:
9
Growth Rate:
39.13%
Total runs:
21
Run Growth:
12
Growth Rate:
54.55%
Total runs:
20
Run Growth:
-4
Growth Rate:
-20.00%
Total runs:
19
Run Growth:
10
Growth Rate:
52.63%
Total runs:
19
Run Growth:
4
Growth Rate:
19.05%
Total runs:
18
Run Growth:
4
Growth Rate:
22.22%
Total runs:
18
Run Growth:
3
Growth Rate:
16.67%
Total runs:
17
Run Growth:
6
Growth Rate:
37.50%
Total runs:
16
Run Growth:
3
Growth Rate:
17.65%
Total runs:
16
Run Growth:
7
Growth Rate:
41.18%
Total runs:
16
Run Growth:
10
Growth Rate:
58.82%
Total runs:
16
Run Growth:
3
Growth Rate:
16.67%
Total runs:
15
Run Growth:
5
Growth Rate:
31.25%
Total runs:
15
Run Growth:
2
Growth Rate:
11.76%
Total runs:
15
Run Growth:
3
Growth Rate:
20.00%
Total runs:
15
Run Growth:
-9
Growth Rate:
-56.25%
Total runs:
15
Run Growth:
7
Growth Rate:
43.75%
Total runs:
14
Run Growth:
8
Growth Rate:
53.33%
Total runs:
14
Run Growth:
0
Growth Rate:
0.00%
Total runs:
14
Run Growth:
2
Growth Rate:
13.33%
Total runs:
13
Run Growth:
4
Growth Rate:
28.57%
Total runs:
12
Run Growth:
8
Growth Rate:
61.54%