



Sponsored by
PostMcpAi
gpustack / jina-embeddings-v2-base-en-GGUF
Model's Last Updated: November 01 2024
feature-extraction
Introduction of jina-embeddings-v2-base-en-GGUF
Model Details of jina-embeddings-v2-base-en-GGUF
jina-embeddings-v2-base-en-GGUF
Model creator
:
jinaai
Original model
:
jina-embeddings-v2-base-en
GGUF quantization
: based on llama.cpp release
61408e7f
The text embedding set trained by Jina AI .
Quick Start
The easiest way to starting using
jina-embeddings-v2-base-en
is to use Jina AI's
Embedding API
.
Intended Usage & Model Info
jina-embeddings-v2-base-en
is an English, monolingual
embedding model
supporting
8192 sequence length
.
It is based on a BERT architecture (JinaBERT) that supports the symmetric bidirectional variant of
ALiBi
to allow longer sequence length.
The backbone
jina-bert-v2-base-en
is pretrained on the C4 dataset.
The model is further trained on Jina AI's collection of more than 400 millions of sentence pairs and hard negatives.
These pairs were obtained from various domains and were carefully selected through a thorough cleaning process.
The embedding model was trained using 512 sequence length, but extrapolates to 8k sequence length (or even longer) thanks to ALiBi. This makes our model useful for a range of use cases, especially when processing long documents is needed, including long document retrieval, semantic textual similarity, text reranking, recommendation, RAG and LLM-based generative search, etc.
With a standard size of 137 million parameters, the model enables fast inference while delivering better performance than our small model. It is recommended to use a single GPU for inference. Additionally, we provide the following embedding models:
-
jina-embeddings-v2-small-en: 33 million parameters. -
jina-embeddings-v2-base-en: 137 million parameters (you are here) . -
jina-embeddings-v2-base-zh: Chinese-English Bilingual embeddings. -
jina-embeddings-v2-base-de: German-English Bilingual embeddings. -
jina-embeddings-v2-base-es: Spanish-English Bilingual embeddings.
Data & Parameters
Jina Embeddings V2 technical report
Usage
Please apply mean pooling when integrating the model.
Why mean pooling?
mean poooling
takes all token embeddings from model output and averaging them at sentence/paragraph level.
It has been proved to be the most effective way to produce high-quality sentence embeddings.
We offer an
encode
function to deal with this.
However, if you would like to do it without using the default
encode
function:
import torch
import torch.nn.functional as F
from transformers import AutoTokenizer, AutoModel

def mean_pooling(model_output, attention_mask):
    token_embeddings = model_output[0]
    input_mask_expanded = attention_mask.unsqueeze(-1).expand(token_embeddings.size()).float()
    return torch.sum(token_embeddings * input_mask_expanded, 1) / torch.clamp(input_mask_expanded.sum(1), min=1e-9)

sentences = ['How is the weather today?', 'What is the current weather like today?']

tokenizer = AutoTokenizer.from_pretrained('jinaai/jina-embeddings-v2-small-en')
model = AutoModel.from_pretrained('jinaai/jina-embeddings-v2-small-en', trust_remote_code=True)

encoded_input = tokenizer(sentences, padding=True, truncation=True, return_tensors='pt')

with torch.no_grad():
    model_output = model(**encoded_input)

embeddings = mean_pooling(model_output, encoded_input['attention_mask'])
embeddings = F.normalize(embeddings, p=2, dim=1)
You can use Jina Embedding models directly from transformers package.
!pip install transformers
from transformers import AutoModel
from numpy.linalg import norm

cos_sim = lambda a,b: (a @ b.T) / (norm(a)*norm(b))
model = AutoModel.from_pretrained('jinaai/jina-embeddings-v2-base-en', trust_remote_code=True) # trust_remote_code is needed to use the encode method
embeddings = model.encode(['How is the weather today?', 'What is the current weather like today?'])
print(cos_sim(embeddings[0], embeddings[1]))
If you only want to handle shorter sequence, such as 2k, pass the
max_length
parameter to the
encode
function:
embeddings = model.encode(
    ['Very long ... document'],
    max_length=2048
)
Using the its latest release (v2.3.0) sentence-transformers also supports Jina embeddings (Please make sure that you are logged into huggingface as well):
!pip install -U sentence-transformers
from sentence_transformers import SentenceTransformer
from sentence_transformers.util import cos_sim

model = SentenceTransformer(
    "jinaai/jina-embeddings-v2-base-en", # switch to en/zh for English or Chinese
    trust_remote_code=True
)

# control your input sequence length up to 8192
model.max_seq_length = 1024

embeddings = model.encode([
    'How is the weather today?',
    'What is the current weather like today?'
])
print(cos_sim(embeddings[0], embeddings[1]))
Alternatives to Using Transformers (or SentencTransformers) Package
- Managed SaaS : Get started with a free key on Jina AI's Embedding API .
- Private and high-performance deployment : Get started by picking from our suite of models and deploy them on AWS Sagemaker .
Use Jina Embeddings for RAG
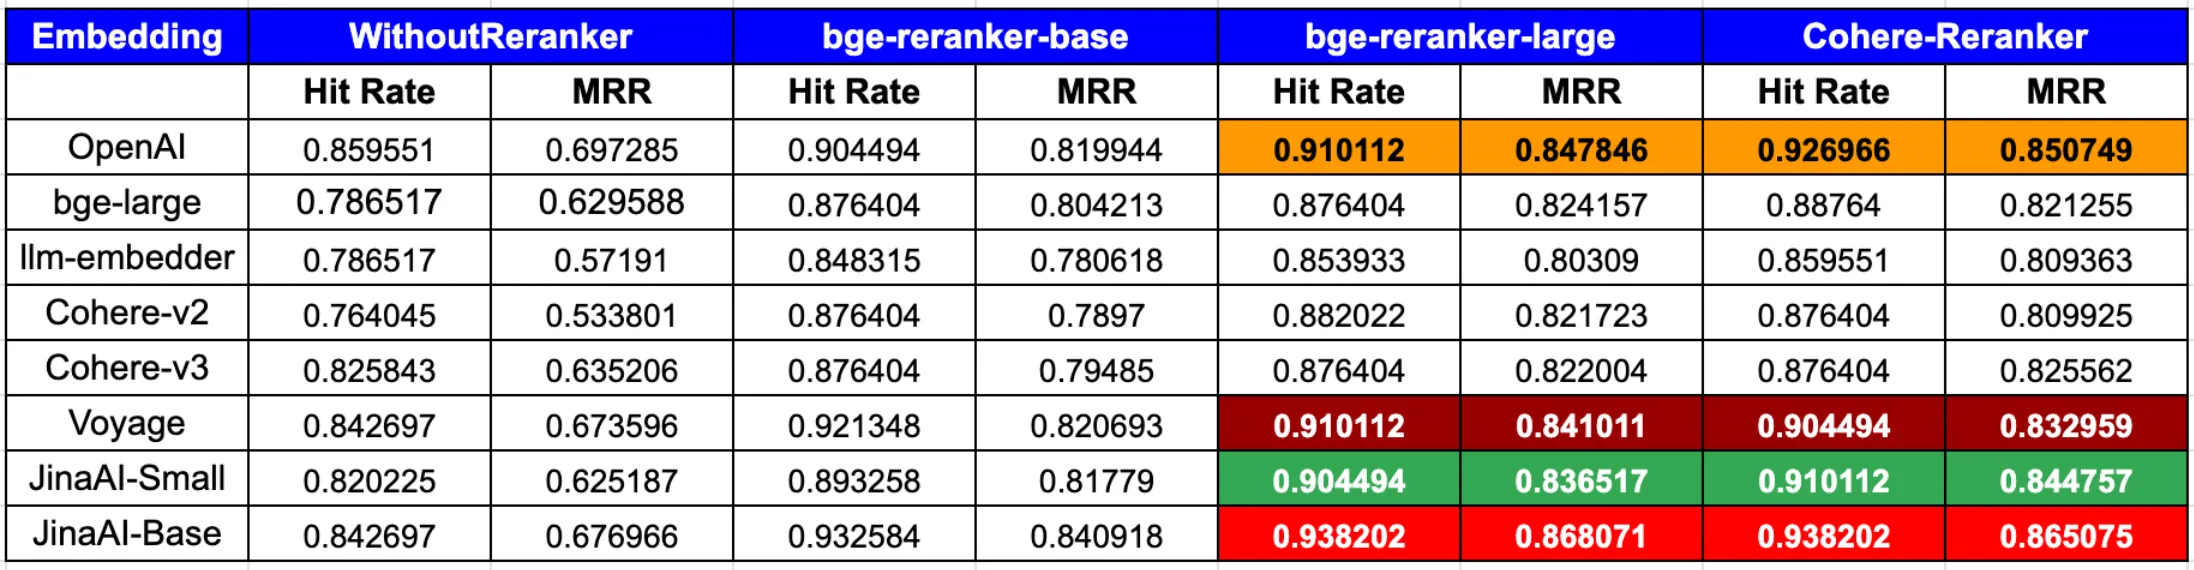
According to the latest blog post from LLamaIndex ,
In summary, to achieve the peak performance in both hit rate and MRR, the combination of OpenAI or JinaAI-Base embeddings with the CohereRerank/bge-reranker-large reranker stands out.
Plans
- Bilingual embedding models supporting more European & Asian languages, including Spanish, French, Italian and Japanese.
- Multimodal embedding models enable Multimodal RAG applications.
- High-performt rerankers.
Trouble Shooting
Loading of Model Code failed
If you forgot to pass the
trust_remote_code=True
flag when calling
AutoModel.from_pretrained
or initializing the model via the
SentenceTransformer
class, you will receive an error that the model weights could not be initialized.
This is caused by tranformers falling back to creating a default BERT model, instead of a jina-embedding model:
Some weights of the model checkpoint at jinaai/jina-embeddings-v2-base-en were not used when initializing BertModel: ['encoder.layer.2.mlp.layernorm.weight', 'encoder.layer.3.mlp.layernorm.weight', 'encoder.layer.10.mlp.wo.bias', 'encoder.layer.5.mlp.wo.bias', 'encoder.layer.2.mlp.layernorm.bias', 'encoder.layer.1.mlp.gated_layers.weight', 'encoder.layer.5.mlp.gated_layers.weight', 'encoder.layer.8.mlp.layernorm.bias', ...
User is not logged into Huggingface
The model is only availabe under gated access . This means you need to be logged into huggingface load load it. If you receive the following error, you need to provide an access token, either by using the huggingface-cli or providing the token via an environment variable as described above:
OSError: jinaai/jina-embeddings-v2-base-en is not a local folder and is not a valid model identifier listed on 'https://huggingface.co/models'
If this is a private repository, make sure to pass a token having permission to this repo with `use_auth_token` or log in with `huggingface-cli login` and pass `use_auth_token=True`.
Contact
Join our Discord community and chat with other community members about ideas.
Citation
If you find Jina Embeddings useful in your research, please cite the following paper:
@misc{günther2023jina,
      title={Jina Embeddings 2: 8192-Token General-Purpose Text Embeddings for Long Documents},
      author={Michael Günther and Jackmin Ong and Isabelle Mohr and Alaeddine Abdessalem and Tanguy Abel and Mohammad Kalim Akram and Susana Guzman and Georgios Mastrapas and Saba Sturua and Bo Wang and Maximilian Werk and Nan Wang and Han Xiao},
      year={2023},
      eprint={2310.19923},
      archivePrefix={arXiv},
      primaryClass={cs.CL}
}
Runs of gpustack jina-embeddings-v2-base-en-GGUF on huggingface.co
284
Total runs
0
24-hour runs
32
3-day runs
35
7-day runs
188
30-day runs
More Information About jina-embeddings-v2-base-en-GGUF huggingface.co Model
Url of jina-embeddings-v2-base-en-GGUF
jina-embeddings-v2-base-en-GGUF huggingface.co Url
Provider of jina-embeddings-v2-base-en-GGUF huggingface.co
Other API from gpustack
Total runs:
26.6K
Run Growth:
7.0K
Growth Rate:
26.49%
Total runs:
4.2K
Run Growth:
-362
Growth Rate:
-8.56%
Total runs:
3.8K
Run Growth:
1.9K
Growth Rate:
49.27%
Total runs:
2.5K
Run Growth:
1.0K
Growth Rate:
41.63%
Total runs:
2.0K
Run Growth:
260
Growth Rate:
13.01%
Total runs:
1.9K
Run Growth:
-152
Growth Rate:
-7.77%
Total runs:
1.3K
Run Growth:
762
Growth Rate:
57.68%
Total runs:
1.1K
Run Growth:
128
Growth Rate:
11.69%
Total runs:
839
Run Growth:
-1.7K
Growth Rate:
-200.12%
Total runs:
790
Run Growth:
233
Growth Rate:
28.94%
Total runs:
600
Run Growth:
52
Growth Rate:
9.40%
Total runs:
427
Run Growth:
94
Growth Rate:
25.41%
Total runs:
411
Run Growth:
-2.2K
Growth Rate:
-450.31%
Total runs:
359
Run Growth:
143
Growth Rate:
41.94%
Total runs:
344
Run Growth:
-5.8K
Growth Rate:
-1598.90%
Total runs:
262
Run Growth:
60
Growth Rate:
22.81%
Total runs:
250
Run Growth:
112
Growth Rate:
59.26%
Total runs:
244
Run Growth:
-45
Growth Rate:
-19.31%
Total runs:
235
Run Growth:
-42
Growth Rate:
-17.65%
Total runs:
180
Run Growth:
93
Growth Rate:
57.76%
Total runs:
165
Run Growth:
-26
Growth Rate:
-16.46%
Total runs:
157
Run Growth:
-5
Growth Rate:
-5.62%
Total runs:
151
Run Growth:
63
Growth Rate:
43.45%
Total runs:
135
Run Growth:
35
Growth Rate:
39.77%
Total runs:
106
Run Growth:
-55
Growth Rate:
-52.88%
Total runs:
98
Run Growth:
-1.8K
Growth Rate:
-1947.31%
Total runs:
92
Run Growth:
-939
Growth Rate:
-968.04%
Total runs:
82
Run Growth:
-2
Growth Rate:
-2.33%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%