



Total runs:
1.7M
Run Growth:
-249.4K
Growth Rate:
-14.40%
The text embedding set trained by Jina AI .
The easiest way to starting using
jina-embeddings-v2-base-es
is to use Jina AI's
Embedding API
.
jina-embeddings-v2-base-es
is a Spanish/English bilingual text
embedding model
supporting
8192 sequence length
.
It is based on a BERT architecture (JinaBERT) that supports the symmetric bidirectional variant of
ALiBi
to allow longer sequence length.
We have designed it for high performance in mono-lingual & cross-lingual applications and trained it specifically to support mixed Spanish-English input without bias.
Additionally, we provide the following embedding models:
jina-embeddings-v2-base-es
es un modelo (embedding) de texto bilingüe Inglés/Español que admite una longitud de secuencia de 8192.
Se basa en la arquitectura BERT (JinaBERT) que incorpora la variante bi-direccional simétrica de
ALiBi
para permitir una mayor longitud de secuencia.
Hemos diseñado este modelo para un alto rendimiento en aplicaciones monolingües y bilingües, y está entrenando específicamente para admitir entradas mixtas de español e inglés sin sesgo.
Adicionalmente, proporcionamos los siguientes modelos (embeddings):
jina-embeddings-v2-small-en
: 33 million parameters.
jina-embeddings-v2-base-en
: 137 million parameters.
jina-embeddings-v2-base-zh
: Chinese-English Bilingual embeddings.
jina-embeddings-v2-base-de
: German-English Bilingual embeddings.
jina-embeddings-v2-base-es
: Spanish-English Bilingual embeddings
(you are here)
.
The data and training details are described in this technical report
mean pooling
takes all token embeddings from model output and averaging them at sentence/paragraph level.
It has been proved to be the most effective way to produce high-quality sentence embeddings.
We offer an
encode
function to deal with this.
However, if you would like to do it without using the default
encode
function:
import torch
import torch.nn.functional as F
from transformers import AutoTokenizer, AutoModel

def mean_pooling(model_output, attention_mask):
    token_embeddings = model_output[0]
    input_mask_expanded = attention_mask.unsqueeze(-1).expand(token_embeddings.size()).float()
    return torch.sum(token_embeddings * input_mask_expanded, 1) / torch.clamp(input_mask_expanded.sum(1), min=1e-9)

sentences = ['How is the weather today?', 'What is the current weather like today?']

tokenizer = AutoTokenizer.from_pretrained('jinaai/jina-embeddings-v2-base-es')
model = AutoModel.from_pretrained('jinaai/jina-embeddings-v2-base-es', trust_remote_code=True)

encoded_input = tokenizer(sentences, padding=True, truncation=True, return_tensors='pt')

with torch.no_grad():
    model_output = model(**encoded_input)

embeddings = mean_pooling(model_output, encoded_input['attention_mask'])
embeddings = F.normalize(embeddings, p=2, dim=1)
You can use Jina Embedding models directly from the
transformers
package:
!pip install transformers
from transformers import AutoModel
from numpy.linalg import norm

cos_sim = lambda a,b: (a @ b.T) / (norm(a)*norm(b))
model = AutoModel.from_pretrained('jinaai/jina-embeddings-v2-base-es', trust_remote_code=True) # trust_remote_code is needed to use the encode method
embeddings = model.encode(['How is the weather today?', '¿Qué tiempo hace hoy?'])
print(cos_sim(embeddings[0], embeddings[1]))
If you only want to handle shorter sequence, such as 2k, pass the
max_length
parameter to the
encode
function:
embeddings = model.encode(
    ['Very long ... document'],
    max_length=2048
)
Or you can use the model with the
sentence-transformers
package:
from sentence_transformers import SentenceTransformer, util

model = SentenceTransformer("jinaai/jina-embeddings-v2-base-es", trust_remote_code=True)
embeddings = model.encode(['How is the weather today?', '¿Qué tiempo hace hoy?'])
print(util.cos_sim(embeddings[0], embeddings[1]))
And if you only want to handle shorter sequence, such as 2k, then you can set the
model.max_seq_length
model.max_seq_length = 2048
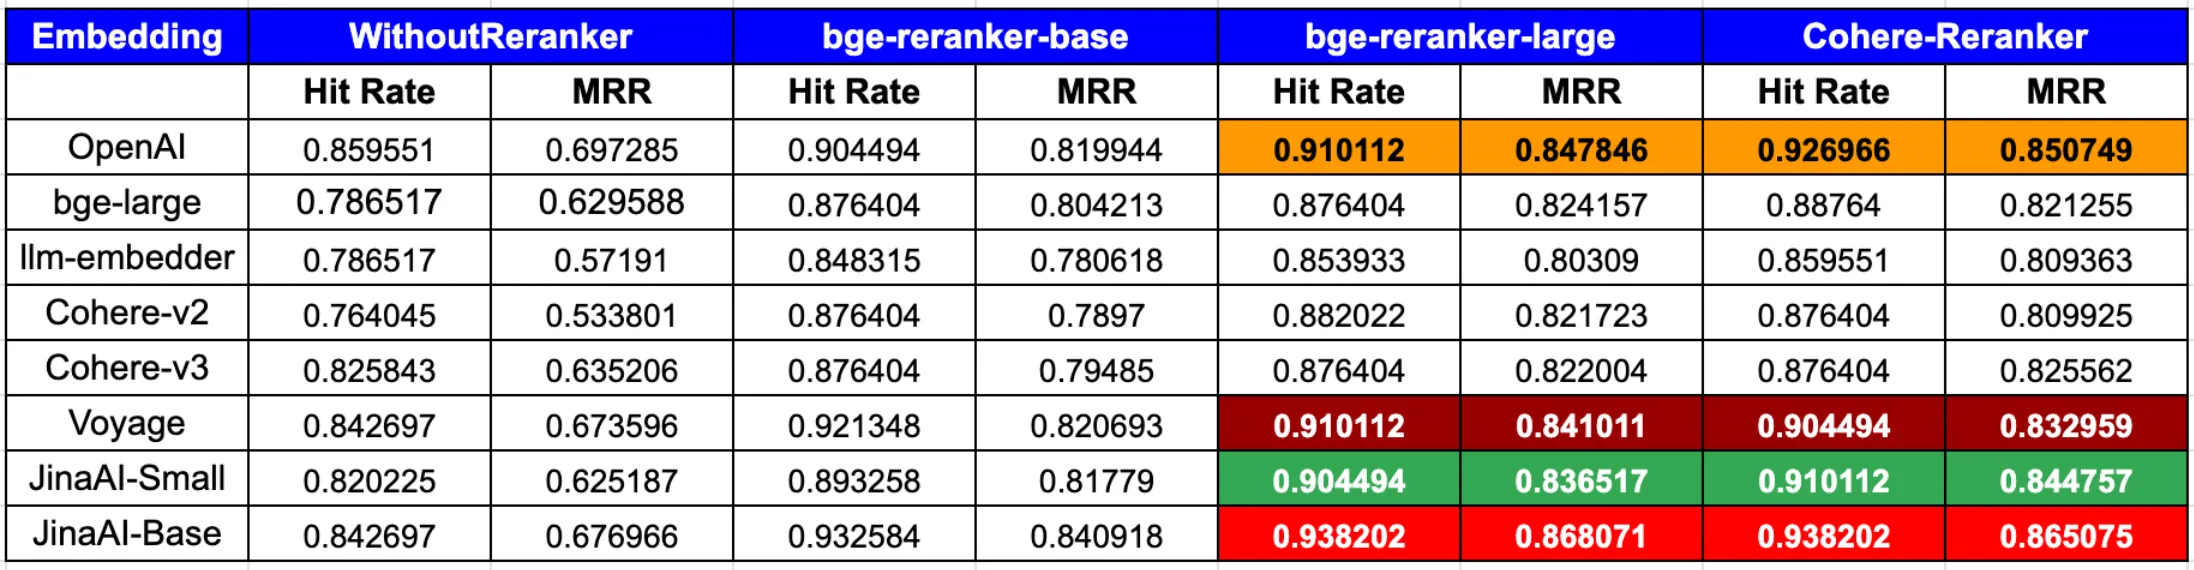
According to the latest blog post from LLamaIndex ,
In summary, to achieve the peak performance in both hit rate and MRR, the combination of OpenAI or JinaAI-Base embeddings with the CohereRerank/bge-reranker-large reranker stands out.
Join our Discord community and chat with other community members about ideas.
If you find Jina Embeddings useful in your research, please cite the following paper:
@article{mohr2024multi,
  title={Multi-Task Contrastive Learning for 8192-Token Bilingual Text Embeddings},
  author={Mohr, Isabelle and Krimmel, Markus and Sturua, Saba and Akram, Mohammad Kalim and Koukounas, Andreas and G{\"u}nther, Michael and Mastrapas, Georgios and Ravishankar, Vinit and Mart{\'\i}nez, Joan Fontanals and Wang, Feng and others},
  journal={arXiv preprint arXiv:2402.17016},
  year={2024}
}