



Sponsored by
iMean AI Trip Planner
lamm-mit / Cephalo-Phi-3-vision-128k-4b-alpha
Model's Last Updated: June 02 2024
image-text-to-text
Introduction of Cephalo-Phi-3-vision-128k-4b-alpha
Model Details of Cephalo-Phi-3-vision-128k-4b-alpha
Model Summary
Cephalo is a series of multimodal materials science focused vision large language models (V-LLMs) designed to integrate visual and linguistic data for advanced understanding and interaction in human-AI or multi-agent AI frameworks.
A novel aspect of Cephalo's development is the innovative dataset generation method. The extraction process employs advanced algorithms to accurately detect and separate images and their corresponding textual descriptions from complex PDF documents. It involves extracting images and captions from PDFs to create well-reasoned image-text pairs, utilizing large language models (LLMs) for natural language processing. These image-text pairs are then refined and validated through LLM-based NLP processing, ensuring high-quality and contextually relevant data for training.
Cephalo can interpret complex visual scenes and generating contextually accurate language descriptions and answer queries.
The model is developed to process diverse inputs, including images and text, facilitating a broad range of applications such as image captioning, visual question answering, and multimodal content generation. The architecture combines a vision encoder model and an autoregressive transformer to process complex natural language understanding.

Cephalo provides a robust framework for multimodal interaction and understanding, including the development of complex generative pipelines to create 2D and 3D renderings of material microstructures as input for additive manufacturing methods.
This version of Cephalo, lamm-mit/Cephalo-Phi-3-vision-128k-4b-alpha, is based on the Phi-3-Vision-128K-Instruct model. The model has a context length of 128,000 tokens. Further details, see: https://huggingface.co/microsoft/Phi-3-vision-128k-instruct .
Chat Format
Given the nature of the training data, the Cephalo-Phi-3-vision-128k-4b-alpha model is best suited for a single image input wih prompts using the chat format as follows.
You can provide the prompt as a single image with a generic template as follow:
<|user|>\n<|image_1|>\n{prompt}<|end|>\n<|assistant|>\n
The model generates the text after
<|assistant|>
. For multi-turn conversations, the prompt should be formatted as follows:
<|user|>\n<|image_1|>\n{prompt_1}<|end|>\n<|assistant|>\n{response_1}<|end|>\n<|user|>\n{prompt_2}<|end|>\n<|assistant|>\n
Sample inference code
This code snippets show how to get quickly started on a GPU:
from PIL import Image
import requests
from transformers import AutoModelForCausalLM
from transformers import AutoProcessor

model_id = "lamm-mit/Cephalo-Phi-3-vision-128k-4b-alpha"

model = AutoModelForCausalLM.from_pretrained(model_id, device_map="cuda", trust_remote_code=True, torch_dtype="auto")

processor = AutoProcessor.from_pretrained(model_id, trust_remote_code=True)

messages = [
    {"role": "user", "content": "<|image_1|>\nWhat is shown in this image, and what is the relevance for materials design?"},
    ]

url = "https://d2r55xnwy6nx47.cloudfront.net/uploads/2018/02/Ants_Lede1300.jpg"

image = Image.open(requests.get(url, stream=True).raw)

prompt = processor.tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)

inputs = processor(prompt, [image], return_tensors="pt").to("cuda:0")

generation_args = {
                    "max_new_tokens": 512,
                    "temperature": 0.1,
                    "do_sample": True,
                    "stop_strings": ['<|end|>',
                                     '<|endoftext|>'],
                    "tokenizer": processor.tokenizer,
                  }

generate_ids = model.generate(**inputs, eos_token_id=processor.tokenizer.eos_token_id, **generation_args)

# remove input tokens
generate_ids = generate_ids[:, inputs['input_ids'].shape[1]:]
response = processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]

print(response)
Sample output:
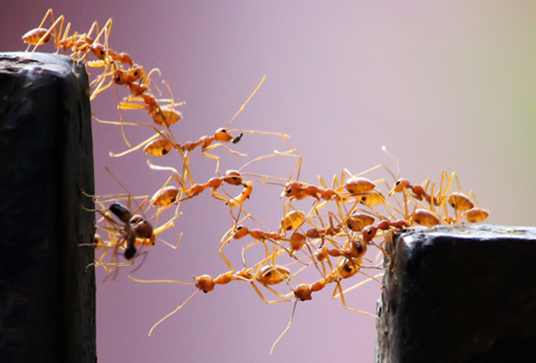 Image by
Vaishakh Manohar
The image shows a group of red imported fire ants (Solenopsis invicta) forming a bridge between two wooden posts. The relevance for materials design lies in the ants' ability to construct a bridge using their body parts, which demonstrates the potential for biomimetic design. Biomimetic design involves emulating natural processes and structures to create new materials and technologies. The ants' bridge construction could inspire the development of novel materials with enhanced structural properties, such as lightweight yet strong materials for construction and engineering applications.
Dataset generation
The schematic below shows a visualization of the approach to generate datasets for training the vision model. The extraction process employs advanced algorithms to accurately detect and separate images and their corresponding textual descriptions from complex PDF documents. It involves extracting images and captions from PDFs to create well-reasoned image-text pairs, utilizing large language models (LLMs) for natural language processing. These image-text pairs are then refined and validated through LLM-based NLP processing, ensuring high-quality and contextually relevant data for training.
The image below shows reproductions of two representative pages of the scientific article (here, Spivak, Buehler, et al., 2011), and how they are used to extract visual scientific data for training the Cephalo model.

Fine-tuning
Load base model
model_id = "microsoft/Phi-3-vision-128k-instruct"

model = AutoModelForCausalLM.from_pretrained(model_id, device_map="cuda", trust_remote_code=True, torch_dtype="auto")

processor = AutoProcessor.from_pretrained(model_id, trust_remote_code=True)
Define FT_repo_id to push on HF hub/save model:
FT_repo_id='xxxxx/' #<repo_ID>
from datasets import load_dataset

train_dataset = load_dataset("lamm-mit/Cephalo-Wikipedia-Materials", split="train")
import random

class MyDataCollator:
    def __init__(self, processor):
        self.processor = processor

    def __call__(self, examples):
        texts = []
        images = []
        for example in examples:
            image = example["image"]
            question = example["query"]
            answer = example["answer"]
            messages = [ {
                            "role": "user",  "content": '<|image_1|>\n'+question},
                           {"role": "assistant", "content": f"{answer}"}, ]

            text = processor.tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=False)

            images.append(image)

        batch = processor(text=text, images=[image], return_tensors="pt", padding=True

        labels = batch["input_ids"].clone()
        labels[labels <0] = -100

        batch["labels"] = labels

        return batch

data_collator = MyDataCollator(processor)
Then set up trainer, and train:
from transformers import TrainingArguments, Trainer

optim = "paged_adamw_8bit"

training_args = TrainingArguments(
    num_train_epochs=2,
    per_device_train_batch_size=1,
    #per_device_eval_batch_size=4,
    gradient_accumulation_steps=4,
    warmup_steps=250,
    learning_rate=1e-5,
    weight_decay=0.01,
    logging_steps=25,
    output_dir="output_training",
    optim=optim,
    save_strategy="steps",
    save_steps=1000,
    save_total_limit=16,
    #fp16=True,
    bf16=True,
    push_to_hub_model_id=FT_repo_id,
    remove_unused_columns=False,
    report_to="none",
)

trainer = Trainer(
    model=model,
    args=training_args,
    data_collator=data_collator,
    train_dataset=train_dataset,
)

trainer.train()
Citation
Please cite as:
@article{Buehler_Cephalo_2024,
  title={Cephalo: Multi-Modal Vision-Language Models for Bio-Inspired Materials Analysis and Design},
  author={Markus J. Buehler},
  journal={arXiv preprint arXiv:2405.19076},
  year={2024}
}
Runs of lamm-mit Cephalo-Phi-3-vision-128k-4b-alpha on huggingface.co
13
Total runs
1
24-hour runs
2
3-day runs
4
7-day runs
-1
30-day runs
More Information About Cephalo-Phi-3-vision-128k-4b-alpha huggingface.co Model
Url of Cephalo-Phi-3-vision-128k-4b-alpha
Cephalo-Phi-3-vision-128k-4b-alpha huggingface.co Url
Provider of Cephalo-Phi-3-vision-128k-4b-alpha huggingface.co
Other API from lamm-mit
Total runs:
246
Run Growth:
13
Growth Rate:
5.28%
Total runs:
183
Run Growth:
158
Growth Rate:
86.34%
Total runs:
173
Run Growth:
96
Growth Rate:
55.49%
Total runs:
172
Run Growth:
42
Growth Rate:
24.42%
Total runs:
159
Run Growth:
103
Growth Rate:
64.78%
Total runs:
138
Run Growth:
61
Growth Rate:
44.20%
Total runs:
116
Run Growth:
49
Growth Rate:
42.24%
Total runs:
115
Run Growth:
27
Growth Rate:
23.48%
Total runs:
98
Run Growth:
67
Growth Rate:
68.37%
Total runs:
94
Run Growth:
8
Growth Rate:
8.51%
Total runs:
93
Run Growth:
89
Growth Rate:
95.70%
Total runs:
89
Run Growth:
83
Growth Rate:
93.26%
Total runs:
74
Run Growth:
45
Growth Rate:
60.81%
Total runs:
72
Run Growth:
39
Growth Rate:
54.17%
Total runs:
71
Run Growth:
52
Growth Rate:
73.24%
Total runs:
58
Run Growth:
50
Growth Rate:
86.21%
Total runs:
55
Run Growth:
29
Growth Rate:
52.73%
Total runs:
54
Run Growth:
-38
Growth Rate:
-70.37%
Total runs:
52
Run Growth:
0
Growth Rate:
0.00%
Total runs:
49
Run Growth:
0
Growth Rate:
0.00%
Total runs:
37
Run Growth:
-76
Growth Rate:
-205.41%
Total runs:
36
Run Growth:
-25
Growth Rate:
-69.44%
Total runs:
32
Run Growth:
-65
Growth Rate:
-203.13%
Total runs:
31
Run Growth:
20
Growth Rate:
64.52%
Total runs:
29
Run Growth:
10
Growth Rate:
34.48%
Total runs:
29
Run Growth:
17
Growth Rate:
58.62%
Total runs:
28
Run Growth:
5
Growth Rate:
17.86%
Total runs:
27
Run Growth:
2
Growth Rate:
7.41%
Total runs:
26
Run Growth:
1
Growth Rate:
3.85%
Total runs:
26
Run Growth:
13
Growth Rate:
50.00%
Total runs:
26
Run Growth:
3
Growth Rate:
11.54%
Total runs:
25
Run Growth:
16
Growth Rate:
64.00%
Total runs:
23
Run Growth:
7
Growth Rate:
30.43%
Total runs:
22
Run Growth:
-5
Growth Rate:
-22.73%
Total runs:
22
Run Growth:
8
Growth Rate:
36.36%
Total runs:
20
Run Growth:
13
Growth Rate:
65.00%
Total runs:
20
Run Growth:
3
Growth Rate:
15.00%
Total runs:
20
Run Growth:
11
Growth Rate:
55.00%
Total runs:
19
Run Growth:
5
Growth Rate:
26.32%
Total runs:
19
Run Growth:
14
Growth Rate:
73.68%
Total runs:
19
Run Growth:
4
Growth Rate:
21.05%
Total runs:
18
Run Growth:
13
Growth Rate:
76.47%
Total runs:
17
Run Growth:
9
Growth Rate:
52.94%
Total runs:
17
Run Growth:
11
Growth Rate:
64.71%
Total runs:
17
Run Growth:
4
Growth Rate:
23.53%
Total runs:
16
Run Growth:
10
Growth Rate:
62.50%
Total runs:
16
Run Growth:
11
Growth Rate:
68.75%
Total runs:
14
Run Growth:
-8
Growth Rate:
-53.33%
Total runs:
14
Run Growth:
7
Growth Rate:
50.00%
Total runs:
14
Run Growth:
-45
Growth Rate:
-321.43%
Total runs:
14
Run Growth:
5
Growth Rate:
35.71%
Total runs:
13
Run Growth:
-8
Growth Rate:
-61.54%
Total runs:
12
Run Growth:
7
Growth Rate:
58.33%
Total runs:
12
Run Growth:
6
Growth Rate:
50.00%
Total runs:
11
Run Growth:
5
Growth Rate:
45.45%
Total runs:
10
Run Growth:
-5
Growth Rate:
-50.00%
Total runs:
10
Run Growth:
6
Growth Rate:
60.00%
Total runs:
9
Run Growth:
1
Growth Rate:
11.11%
Total runs:
9
Run Growth:
5
Growth Rate:
55.56%
Total runs:
8
Run Growth:
-25
Growth Rate:
-312.50%
Total runs:
8
Run Growth:
0
Growth Rate:
0.00%
Total runs:
8
Run Growth:
-17
Growth Rate:
-212.50%
Total runs:
8
Run Growth:
0
Growth Rate:
0.00%
Total runs:
7
Run Growth:
-5
Growth Rate:
-71.43%
Total runs:
6
Run Growth:
-7
Growth Rate:
-116.67%
Total runs:
5
Run Growth:
0
Growth Rate:
0.00%
Total runs:
5
Run Growth:
1
Growth Rate:
20.00%
Total runs:
4
Run Growth:
-9
Growth Rate:
-225.00%
Total runs:
3
Run Growth:
3
Growth Rate:
100.00%
Total runs:
1
Run Growth:
1
Growth Rate:
100.00%
Total runs:
1
Run Growth:
1
Growth Rate:
100.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%