




Total runs:
228.9K
Run Growth:
34.0K
Growth Rate:
14.86%
Quick launch via vLLM:
LLM_MEMORY_PROFILER_ESTIMATE_CUDAGRAPHS=1  \
vllm serve  --model ~/CoPaw-Flash-4B-FP8/  \
            --host 0.0.0.0    \
            --port 8070 \
            --tensor-parallel-size 1       \
            --max-model-len 262144         \
            --gpu-memory-utilization 0.92  \
            --trust-remote-code    \
            --tokenizer-mode auto  \
            --served-model-name CoPaw-Flash-4B  \
            --max-num-batched-tokens 16384   \
            --max-num-seqs 1  \
            --enable-auto-tool-choice  \
            --tool-call-parser qwen3_xml  \
            --kv-cache-dtype fp8_e4m3 \
            --reasoning-parser qwen3 \
            --enable-prefix-caching  \
            --enable-chunked-prefill

CoPaw-Flash is a lightweight model deeply optimized for the CoPaw autonomous agent scenario. Since its training phase, the model has been specifically refined for CoPaw tasks, delivering enhanced agentic performance in tool invocation, command execution, memory management, and multi-step planning.
The core strength of CoPaw-Flash stems from its native integration with the CoPaw ecosystem. We have constructed extensive, high-quality agent trajectory data sampled from real CoPaw environments, systematically enhancing the model's proficiency in high-frequency daily scenarios. Key features include:
CoPaw-Flash-2B/4B/9B is fine-tuned from Qwen3.5-2B/4B/9B, sharing the same architectural parameters.
The complexity of CoPaw's context engineering and tool usage poses heightened challenges for model evaluation. To address this, we have developed a dedicated benchmark tailored to the CoPaw environment. This benchmark systematically evaluates model performance across five high-frequency usage scenarios, covering key operational dimensions.
Results indicate that CoPaw-Flash delivers substantial improvements across multiple task categories, achieving performance comparable to leading flagship models—all while maintaining significantly lower resource requirements.
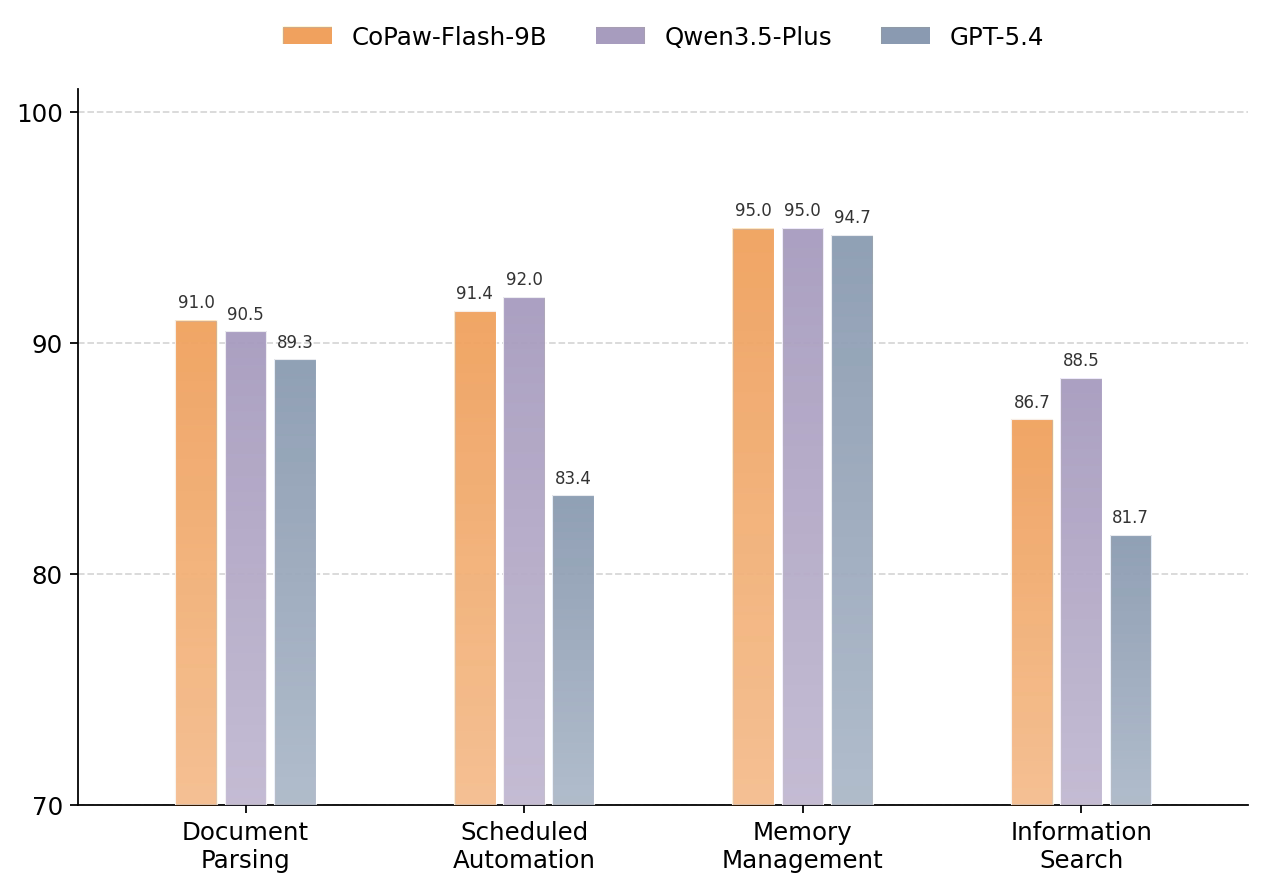
Figure 1: CoPaw-Flash-9B compared with other models.
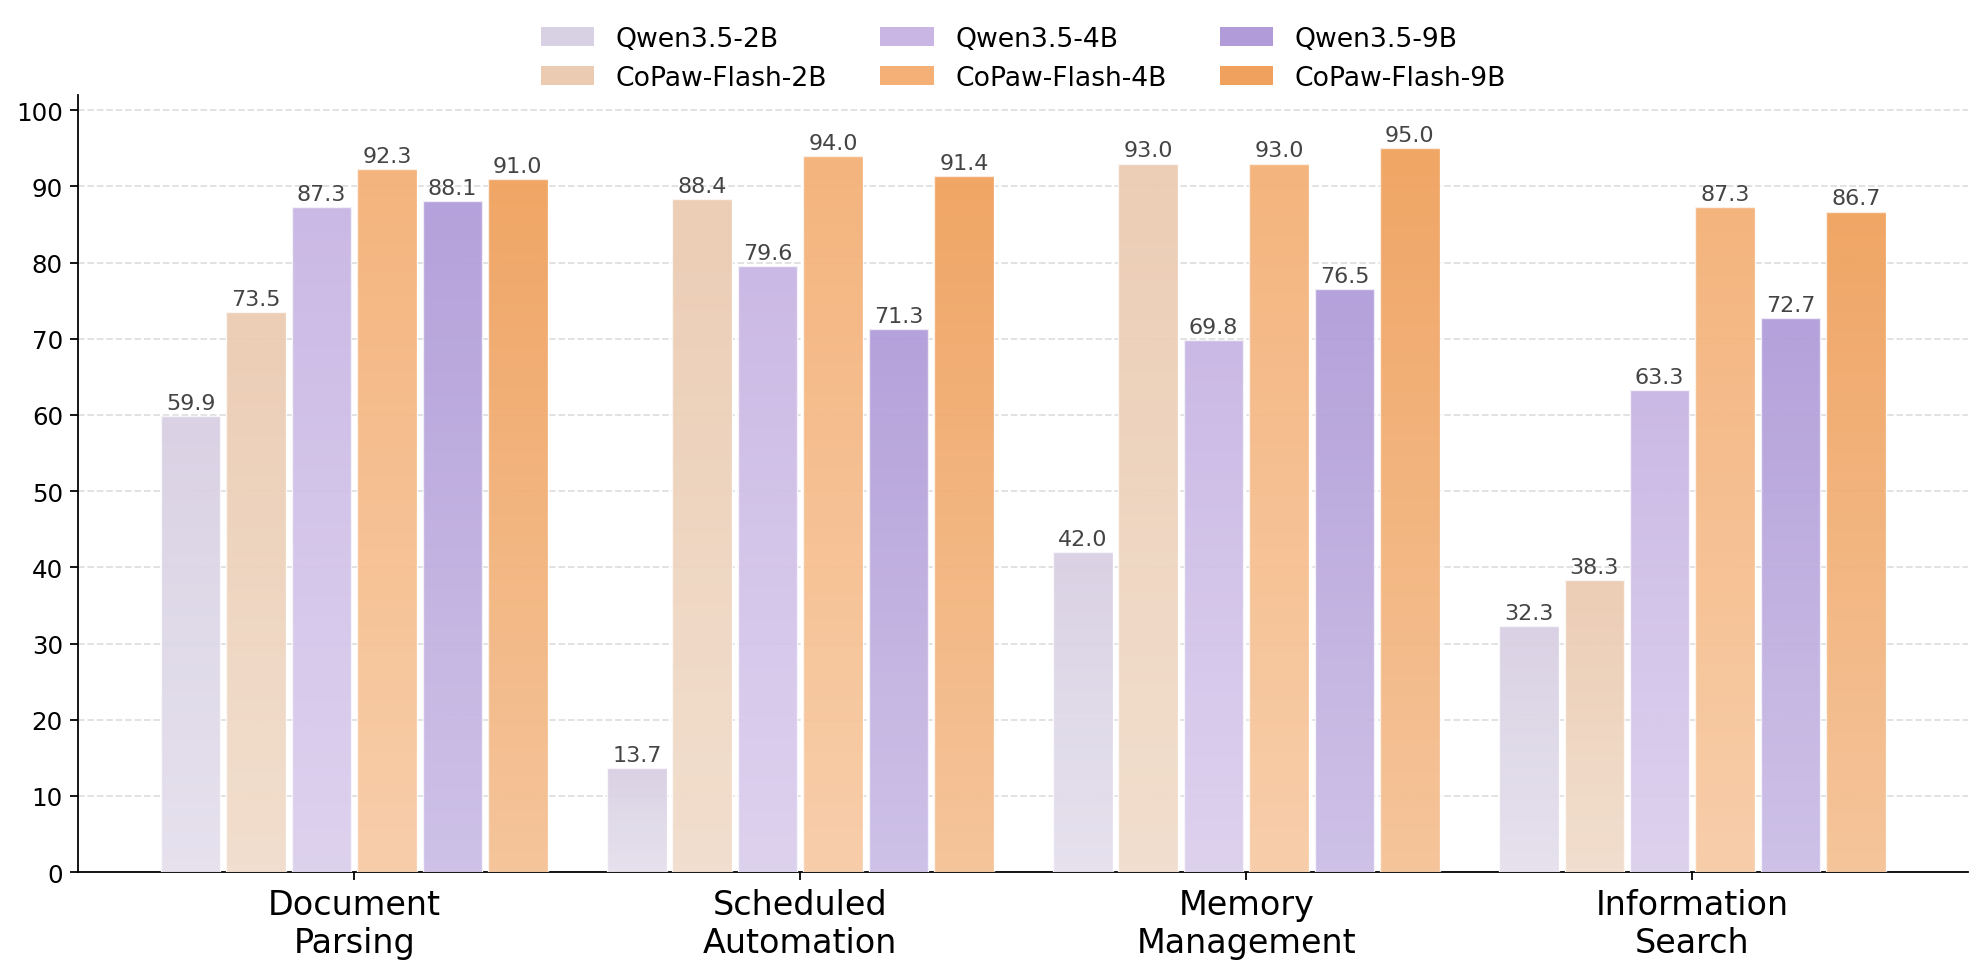
Figure 2: CoPaw-Flash-2B/4B/9B compared with their respective baseline models.
CoPaw-Flash can be served via APIs using popular inference frameworks. Below are example commands to launch OpenAI-compatible API servers for CoPaw-Flash.
vLLM is a high-throughput and memory-efficient inference and serving engine for LLMs. Since CoPaw-Flash leverages the Qwen3.5 architecture, the latest vLLM version is required for optimal compatibility. You can install it in a fresh environment using:
uv pip install vllm --torch-backend=auto --extra-index-url https://wheels.vllm.ai/nightly
Note: For more detailed usage guides and advanced configurations, please refer to the vLLM Documentation and the Qwen3.5 Documentation .
The following command creates API endpoints at
http://localhost:8000/v1
. This example demonstrates launching the standard version with a maximum context length of 262,144 tokens using tensor parallelism across 8 GPUs.
Bash
vllm serve <your_model_path> \
    --port 8000 \
    --tensor-parallel-size 8 \
    --max-model-len 262144 \
    --reasoning-parser qwen3 \
    --enable-auto-tool-choice \
    --tool-call-parser qwen3_xml
Once the server is running, you can access CoPaw-Flash via standard HTTP requests or OpenAI-compatible SDKs.
Ensure the OpenAI Python SDK is installed and your environment variables are configured:
pip install -U openai

# Set the following accordingly
export OPENAI_BASE_URL="http://localhost:8000/v1"
export OPENAI_API_KEY="EMPTY"
The following Python script demonstrates how to interact with the model using the OpenAI SDK:
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {"role": "user", "content": "Hello, Copaw!"},
]

chat_response = client.chat.completions.create(
    model=<your_model_path>,
    messages=messages,
    max_tokens=81920,
    temperature=1.0,
    top_p=0.95,
    presence_penalty=1.5,
    extra_body={
        "top_k": 20,
    },
)
print("Chat response:", chat_response)
CoPaw-Flash is developed by the AgentScope Team. If you would like to leave us a message, feel free to get in touch through the channels below.