




Total runs:
958.9K
Run Growth:
-60.4K
Growth Rate:
-6.24%
latin_PP-OCRv5_mobile_rec is one of the PP-OCRv5_rec that are the latest generation text line recognition models developed by PaddleOCR team. It aims to efficiently and accurately support the recognition of Korean. The key accuracy metrics are as follow:
| 模型 | 拉丁字母语言数据集 精度 (%) |
|---|---|
| latin_PP-OCRv5_mobile_rec | 84.7 |
Note : If any character (including punctuation) in a line was incorrect, the entire line was marked as wrong. This ensures higher accuracy in practical applications.
Please refer to the following commands to install PaddlePaddle using pip:
# for CUDA11.8
python -m pip install paddlepaddle-gpu==3.0.0 -i https://www.paddlepaddle.org.cn/packages/stable/cu118/

# for CUDA12.6
python -m pip install paddlepaddle-gpu==3.0.0 -i https://www.paddlepaddle.org.cn/packages/stable/cu126/

# for CPU
python -m pip install paddlepaddle==3.0.0 -i https://www.paddlepaddle.org.cn/packages/stable/cpu/
For details about PaddlePaddle installation, please refer to the PaddlePaddle official website .
Install the latest version of the PaddleOCR inference package from PyPI:
python -m pip install paddleocr
You can quickly experience the functionality with a single command:
paddleocr text_recognition \
    --model_name latin_PP-OCRv5_mobile_rec \
    -i https://cdn-uploads.huggingface.co/production/uploads/681c1ecd9539bdde5ae1733c/W_burWoWRF52gAT0sF13x.png
You can also integrate the model inference of the text recognition module into your project. Before running the following code, please download the sample image to your local machine.
from paddleocr import TextRecognition
model = TextRecognition(model_name="latin_PP-OCRv5_mobile_rec")
output = model.predict(input="W_burWoWRF52gAT0sF13x.png", batch_size=1)
for res in output:
    res.print()
    res.save_to_img(save_path="./output/")
    res.save_to_json(save_path="./output/res.json")
After running, the obtained result is as follows:
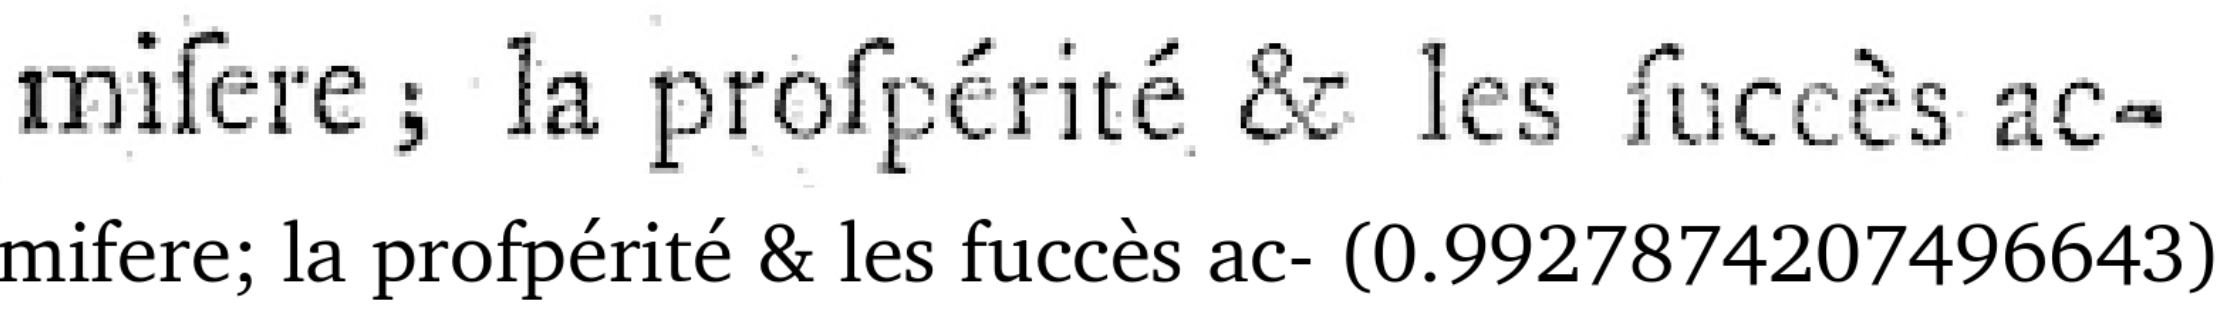
{'res': {'input_path': '/root/.paddlex/predict_input/W_burWoWRF52gAT0sF13x.png', 'page_index': None, 'rec_text': 'mifere; la profpérité & les fuccès ac-', 'rec_score': 0.9927874207496643}}
The visualized image is as follows:
For details about usage command and descriptions of parameters, please refer to the Document .
The ability of a single model is limited. But the pipeline consists of several models can provide more capacity to resolve difficult problems in real-world scenarios.
The PP-OCRv5 pipeline is used to solve text recognition tasks by extracting text information from images and outputting it in string format. And there are 5 modules in the pipeline:
Run a single command to quickly experience the OCR pipeline:
paddleocr ocr -i https://cdn-uploads.huggingface.co/production/uploads/681c1ecd9539bdde5ae1733c/MDydp3KQQXvS3lTrNKVcc.png \
    --text_recognition_model_name latin_PP-OCRv5_mobile_rec \
    --use_doc_orientation_classify False \
    --use_doc_unwarping False \
    --use_textline_orientation True \
    --save_path ./output \
    --device gpu:0
Results are printed to the terminal:
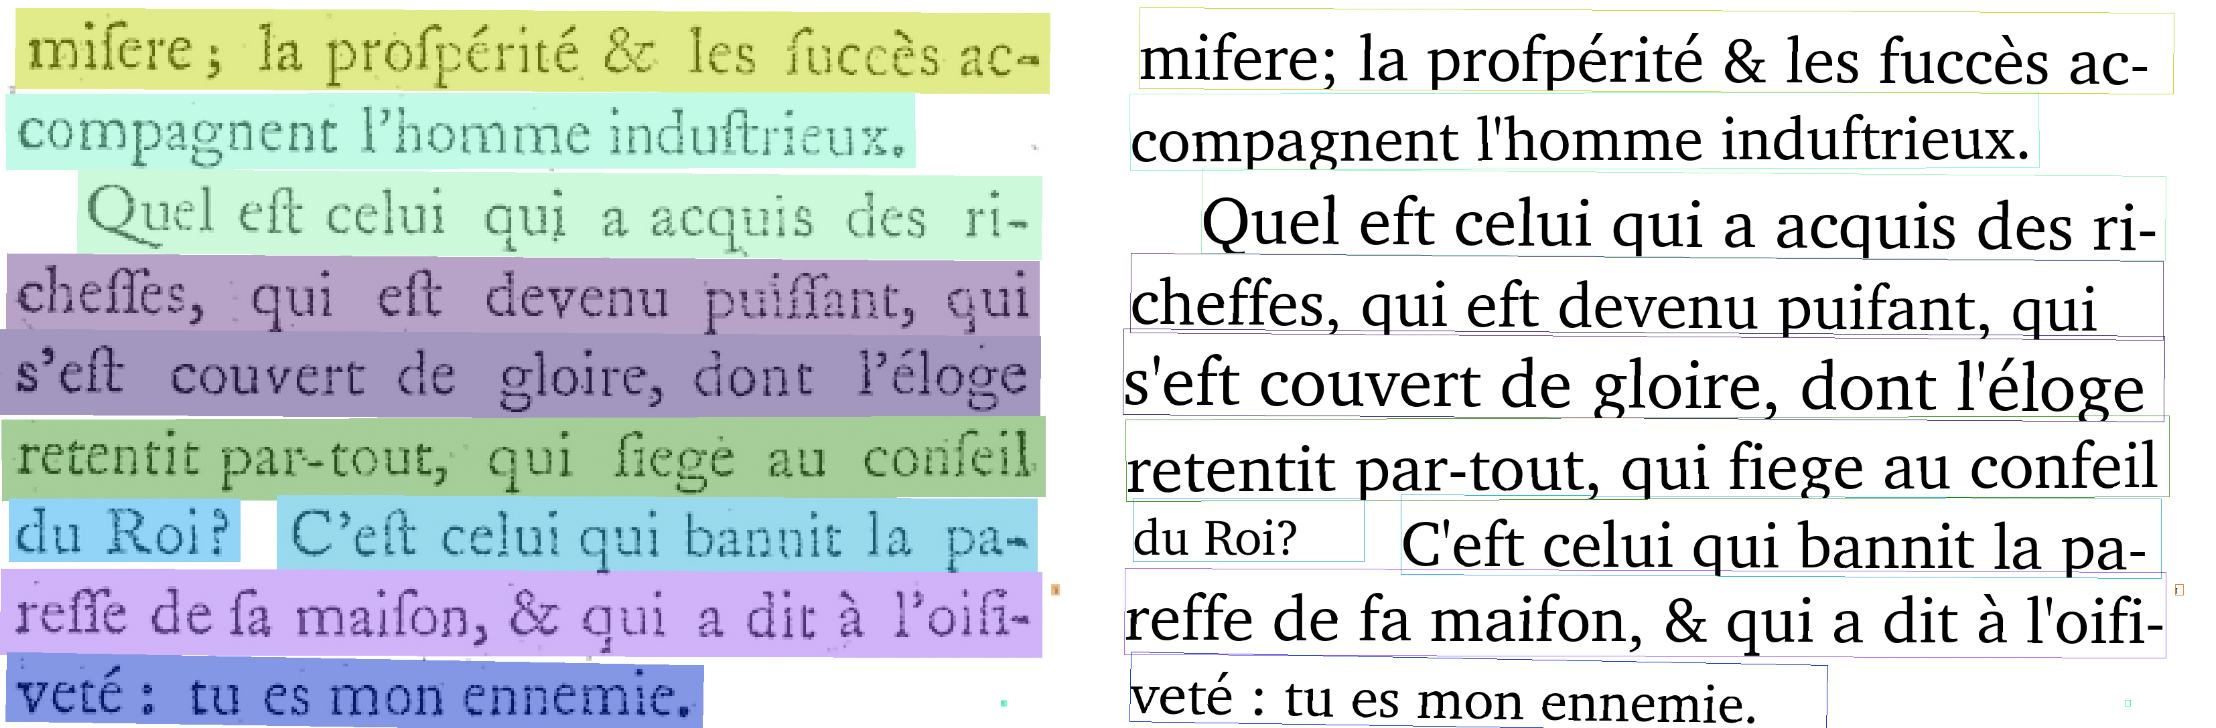
{'res': {'input_path': '/root/.paddlex/predict_input/MDydp3KQQXvS3lTrNKVcc.png', 'page_index': None, 'model_settings': {'use_doc_preprocessor': True, 'use_textline_orientation': True}, 'doc_preprocessor_res': {'input_path': None, 'page_index': None, 'model_settings': {'use_doc_orientation_classify': False, 'use_doc_unwarping': False}, 'angle': -1}, 'dt_polys': array([[[  56,   35],
        ...,
        [  55,  156]],

       ...,

       [[1527, 1070],
        ...,
        [1527, 1079]]], dtype=int16), 'text_det_params': {'limit_side_len': 64, 'limit_type': 'min', 'thresh': 0.3, 'max_side_limit': 4000, 'box_thresh': 0.6, 'unclip_ratio': 1.5}, 'text_type': 'general', 'textline_orientation_angles': array([0, ..., 1]), 'text_rec_score_thresh': 0.0, 'rec_texts': ['mifere; la profpérité & les fuccès ac-', "compagnent l'homme induftrieux.", 'Quel eft celui qui a acquis des ri-', 'cheffes, qui eft devenu puifant, qui', "s'eft couvert de gloire, dont l'éloge", 'retentit par-tout, qui fiege au confeil', 'du Roi?', "C'eft celui qui bannit la pa-", "reffe de fa maifon, & qui a dit à l'oifi-", 'I', 'veté : tu es mon ennemie.', '□'], 'rec_scores': array([0.98541331, ..., 0.48962179]), 'rec_polys': array([[[  56,   35],
        ...,
        [  55,  156]],

       ...,

       [[1527, 1070],
        ...,
        [1527, 1079]]], dtype=int16), 'rec_boxes': array([[  55, ...,  164],
       ...,
       [1527, ..., 1079]], dtype=int16)}}
If save_path is specified, the visualization results will be saved under
save_path
. The visualization output is shown below:
The command-line method is for quick experience. For project integration, also only a few codes are needed as well:
from paddleocr import PaddleOCR

ocr = PaddleOCR(
    text_recognition_model_name="latin_PP-OCRv5_mobile_rec",
    use_doc_orientation_classify=False, # Use use_doc_orientation_classify to enable/disable document orientation classification model
    use_doc_unwarping=False, # Use use_doc_unwarping to enable/disable document unwarping module
    use_textline_orientation=True, # Use use_textline_orientation to enable/disable textline orientation classification model
    device="gpu:0", # Use device to specify GPU for model inference
)
result = ocr.predict("https://cdn-uploads.huggingface.co/production/uploads/681c1ecd9539bdde5ae1733c/MDydp3KQQXvS3lTrNKVcc.png")
for res in result:
    res.print()
    res.save_to_img("output")
    res.save_to_json("output")
The default model used in pipeline is
PP-OCRv5_server_rec
, and you can also use the local model file by argument
text_recognition_model_dir
. For details about usage command and descriptions of parameters, please refer to the
Document
.