



Total runs:
12.0K
Run Growth:
2.8K
Growth Rate:
23.38%
These are NOT compatible with llama.cpp and its frontends and derivatives (LMStudio, Kobold, etc...). Use with ik_llama.cpp only.
Make sure to pass the
-ger
option to llama-server or llama-cli to enable grouped experts.
GGUF quants of Ling-mini-2.0
Using ik_llama.cpp (commit dbfd151594d723b8bed54326cb521d1bccfad802 )
The importance matrix was generated with eaddario/imatrix-calibration combined_all_medium dataset and grouped experts option enabled.
All quants were generated/calibrated with the imatrix, including the K quants.
Compressed from BF16.

🤗 Hugging Face | 🤖 ModelScope | 🐙 Experience Now
Today, we are excited to announce the open-sourcing of Ling 2.0 — a family of MoE-based large language models that combine SOTA performance with high efficiency . The first released version, Ling-mini-2.0, is compact yet powerful. It has 16B total parameters , but only 1.4B are activated per input token (non-embedding 789M). Trained on more than 20T tokens of high-quality data and enhanced through multi-stage supervised fine-tuning and reinforcement learning, Ling-mini-2.0 achieves remarkable improvements in complex reasoning and instruction following. With just 1.4B activated parameters, it still reaches the top-tier level of sub-10B dense LLMs and even matches or surpasses much larger MoE models.

We evaluated Ling-mini-2.0 on challenging general reasoning tasks in coding (LiveCodeBench, CodeForces) and mathematics (AIME 2025, HMMT 2025), as well as knowledge-intensive reasoning tasks across multiple domains (MMLU-Pro, Humanity's Last Exam). Compared with sub-10B dense models (e.g., Qwen3-4B-instruct-2507, Qwen3-8B-nothinking) and larger-scale MoE models (Ernie-4.5-21B-A3B-PT, GPT-OSS-20B/low), Ling-mini-2.0 demonstrated outstanding overall reasoning capabilities.
Guided by Ling Scaling Laws , Ling 2.0 adopts a 1/32 activation ratio MoE architecture, with empirically optimized design choices in expert granularity, shared expert ratio, attention ratio, aux-loss free + sigmoid routing strategy, MTP loss, QK-Norm, half RoPE, and more. This enables small-activation MoE models to achieve over 7× equivalent dense performance . In other words, Ling-mini-2.0 with only 1.4B activated parameters (non-embedding 789M) can deliver performance equivalent to a 7–8B dense model .

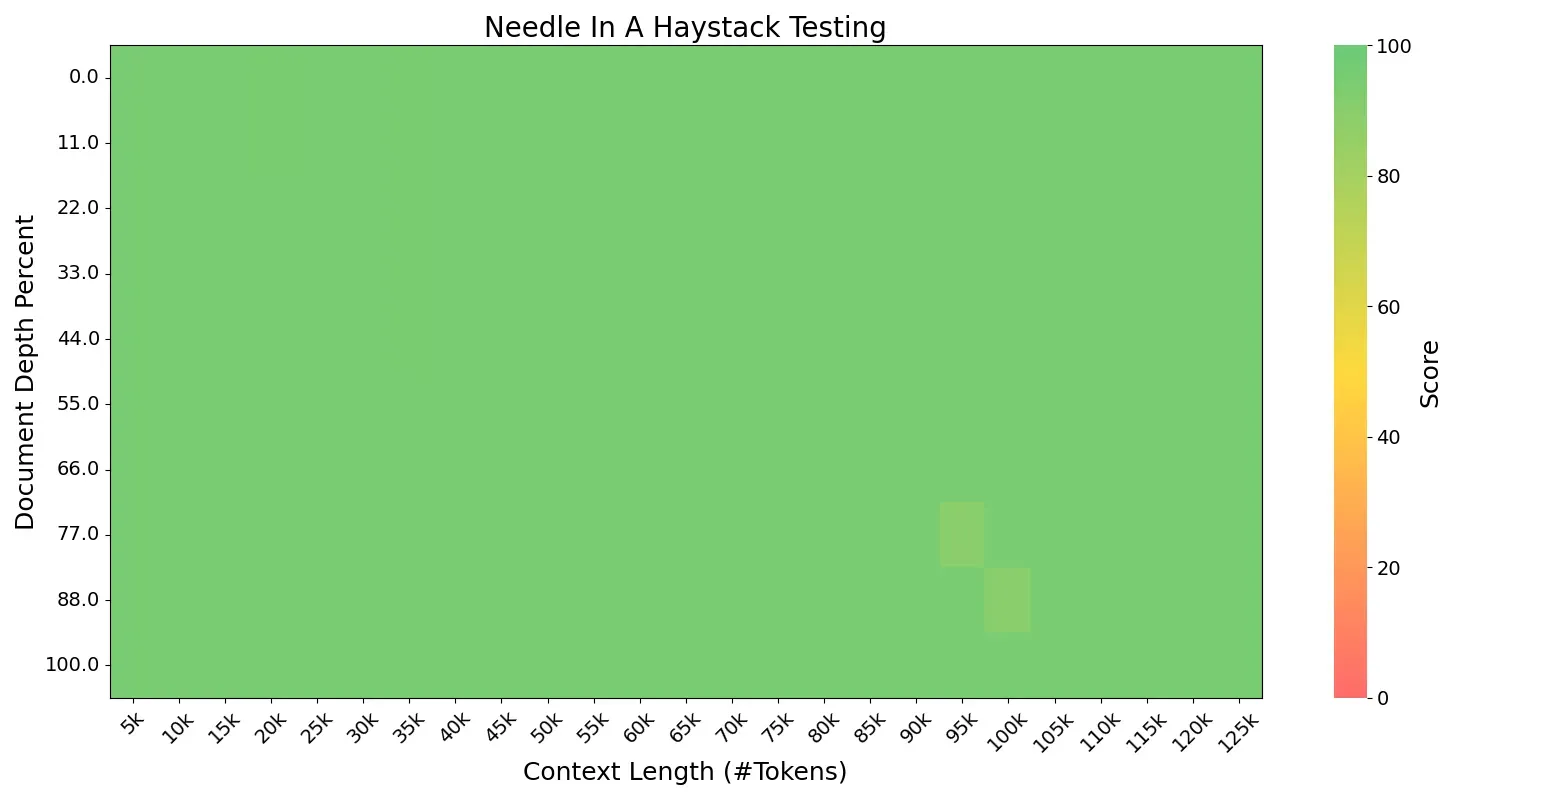
The highly sparse small-activation MoE architecture also delivers significant training and inference efficiency. In simple QA scenarios (within 2000 tokens), Ling-mini-2.0 generates at 300+ token/s (on H20 deployment) — more than 2× faster than an 8B dense model. Ling-mini-2.0 is able to handle 128K context length with YaRN, as sequence length increases, the relative speedup can reach over 7× .
Ling 2.0 employs FP8 mixed-precision training throughout. Compared with BF16, experiments with over 1T training tokens show nearly identical loss curves and downstream benchmark performance. To support the community in efficient continued pretraining and fine-tuning under limited compute, we are also open-sourcing our FP8 training solution . Based on tile/blockwise FP8 scaling, it further introduces FP8 optimizer, FP8 on-demand transpose weight, and FP8 padding routing map for extreme memory optimization. On 8/16/32 80G GPUs, compared with LLaMA 3.1 8B and Qwen3 8B, Ling-mini-2.0 achieved 30–60% throughput gains with MTP enabled, and 90–120% throughput gains with MTP disabled .
We believe Ling-mini-2.0 is an ideal starting point for MoE research. For the first time at this scale, it integrates 1/32 sparsity, MTP layers, and FP8 training — achieving both strong effectiveness and efficient training/inference performance, making it a prime candidate for the small-size LLM segment. To further foster community research, in addition to releasing the post-trained version, we are also open-sourcing five pretraining checkpoints : the pre-finetuning Ling-mini-2.0-base, along with four base models trained on 5T, 10T, 15T, and 20T tokens, enabling deeper research and broader applications.