



Total runs:
12.0K
Run Growth:
2.8K
Growth Rate:
23.38%
GGUF quants of Qwen3-VL-4B-Instruct
Using llama.cpp b6907 (commit bea04522ff1a0d8559ccfd353aa018dcfbb608cc )
The importance matrix was generated with eaddario/imatrix-calibration
All quants were generated/calibrated with the imatrix, including the K quants.
Compressed from BF16.
llama.cpp usage:
--jinja --temp 0.7 --top-p 0.8 --top-k 20
Meet Qwen3-VL — the most powerful vision-language model in the Qwen series to date.
This generation delivers comprehensive upgrades across the board: superior text understanding & generation, deeper visual perception & reasoning, extended context length, enhanced spatial and video dynamics comprehension, and stronger agent interaction capabilities.
Available in Dense and MoE architectures that scale from edge to cloud, with Instruct and reasoning‑enhanced Thinking editions for flexible, on‑demand deployment.
Visual Agent : Operates PC/mobile GUIs—recognizes elements, understands functions, invokes tools, completes tasks.
Visual Coding Boost : Generates Draw.io/HTML/CSS/JS from images/videos.
Advanced Spatial Perception : Judges object positions, viewpoints, and occlusions; provides stronger 2D grounding and enables 3D grounding for spatial reasoning and embodied AI.
Long Context & Video Understanding : Native 256K context, expandable to 1M; handles books and hours-long video with full recall and second-level indexing.
Enhanced Multimodal Reasoning : Excels in STEM/Math—causal analysis and logical, evidence-based answers.
Upgraded Visual Recognition : Broader, higher-quality pretraining is able to “recognize everything”—celebrities, anime, products, landmarks, flora/fauna, etc.
Expanded OCR : Supports 32 languages (up from 19); robust in low light, blur, and tilt; better with rare/ancient characters and jargon; improved long-document structure parsing.
Text Understanding on par with pure LLMs : Seamless text–vision fusion for lossless, unified comprehension.
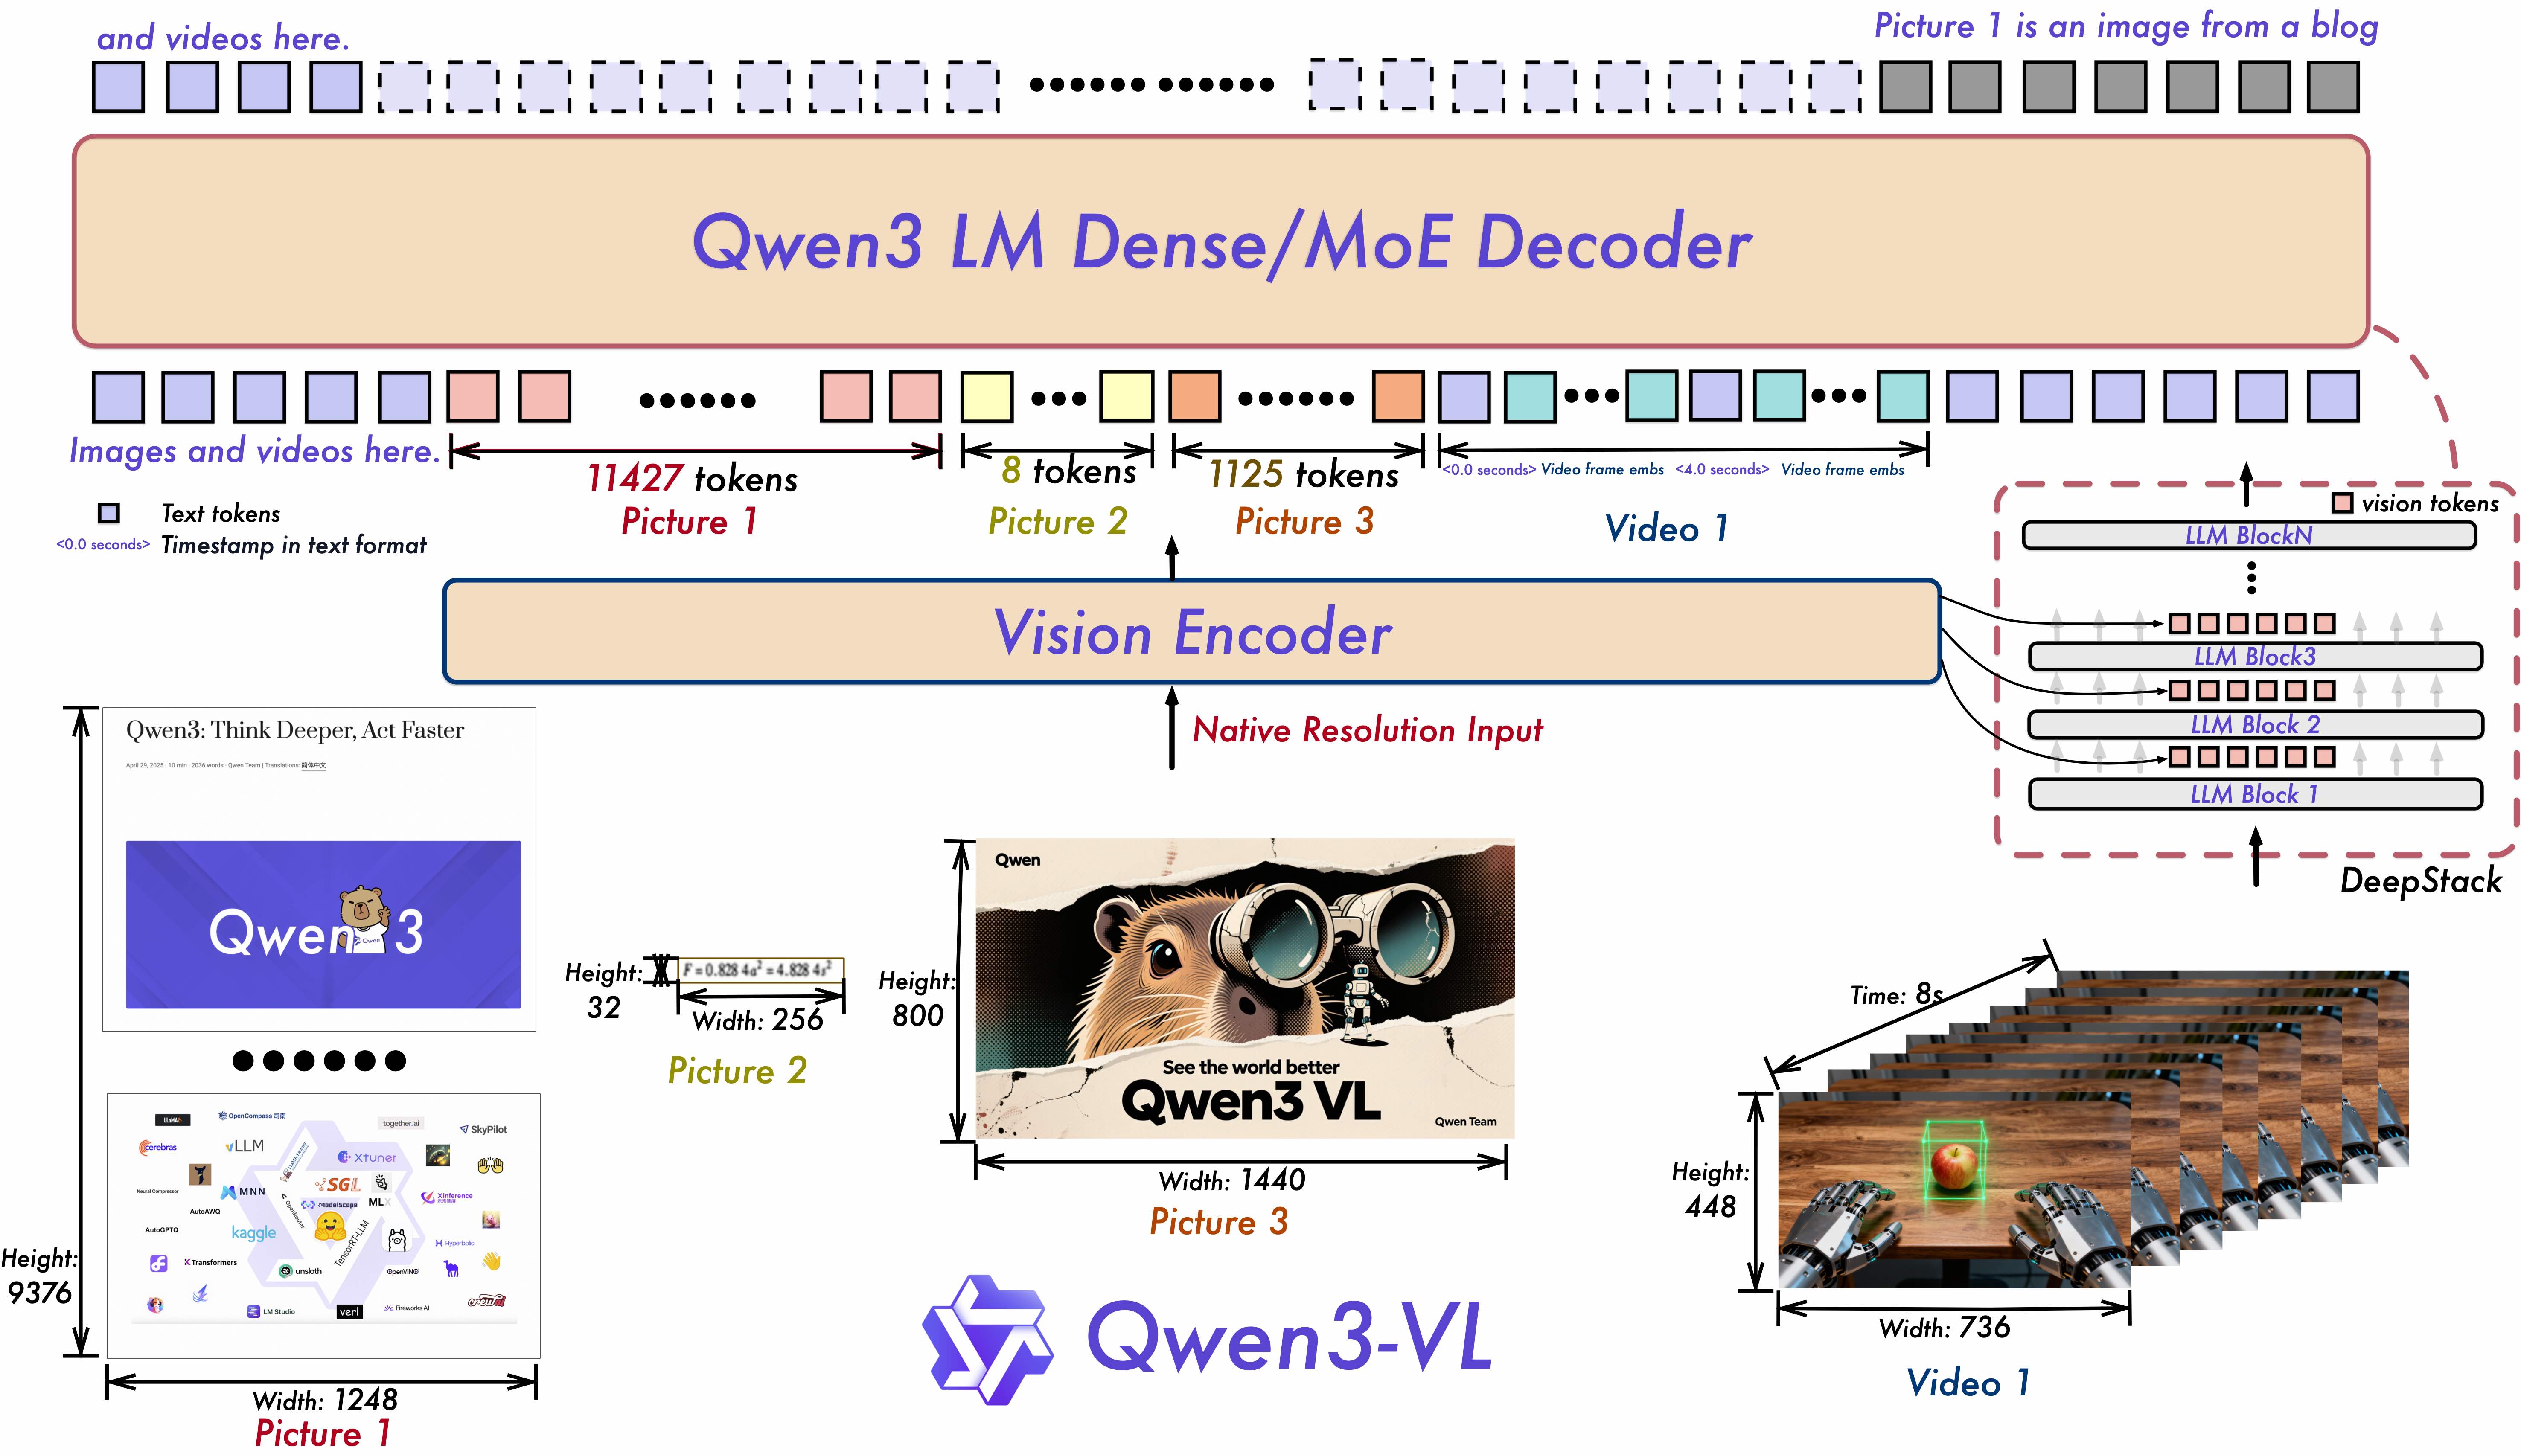
Interleaved-MRoPE : Full‑frequency allocation over time, width, and height via robust positional embeddings, enhancing long‑horizon video reasoning.
DeepStack : Fuses multi‑level ViT features to capture fine‑grained details and sharpen image–text alignment.
Text–Timestamp Alignment: Moves beyond T‑RoPE to precise, timestamp‑grounded event localization for stronger video temporal modeling.
This is the weight repository for Qwen3-VL-4B-Instruct.
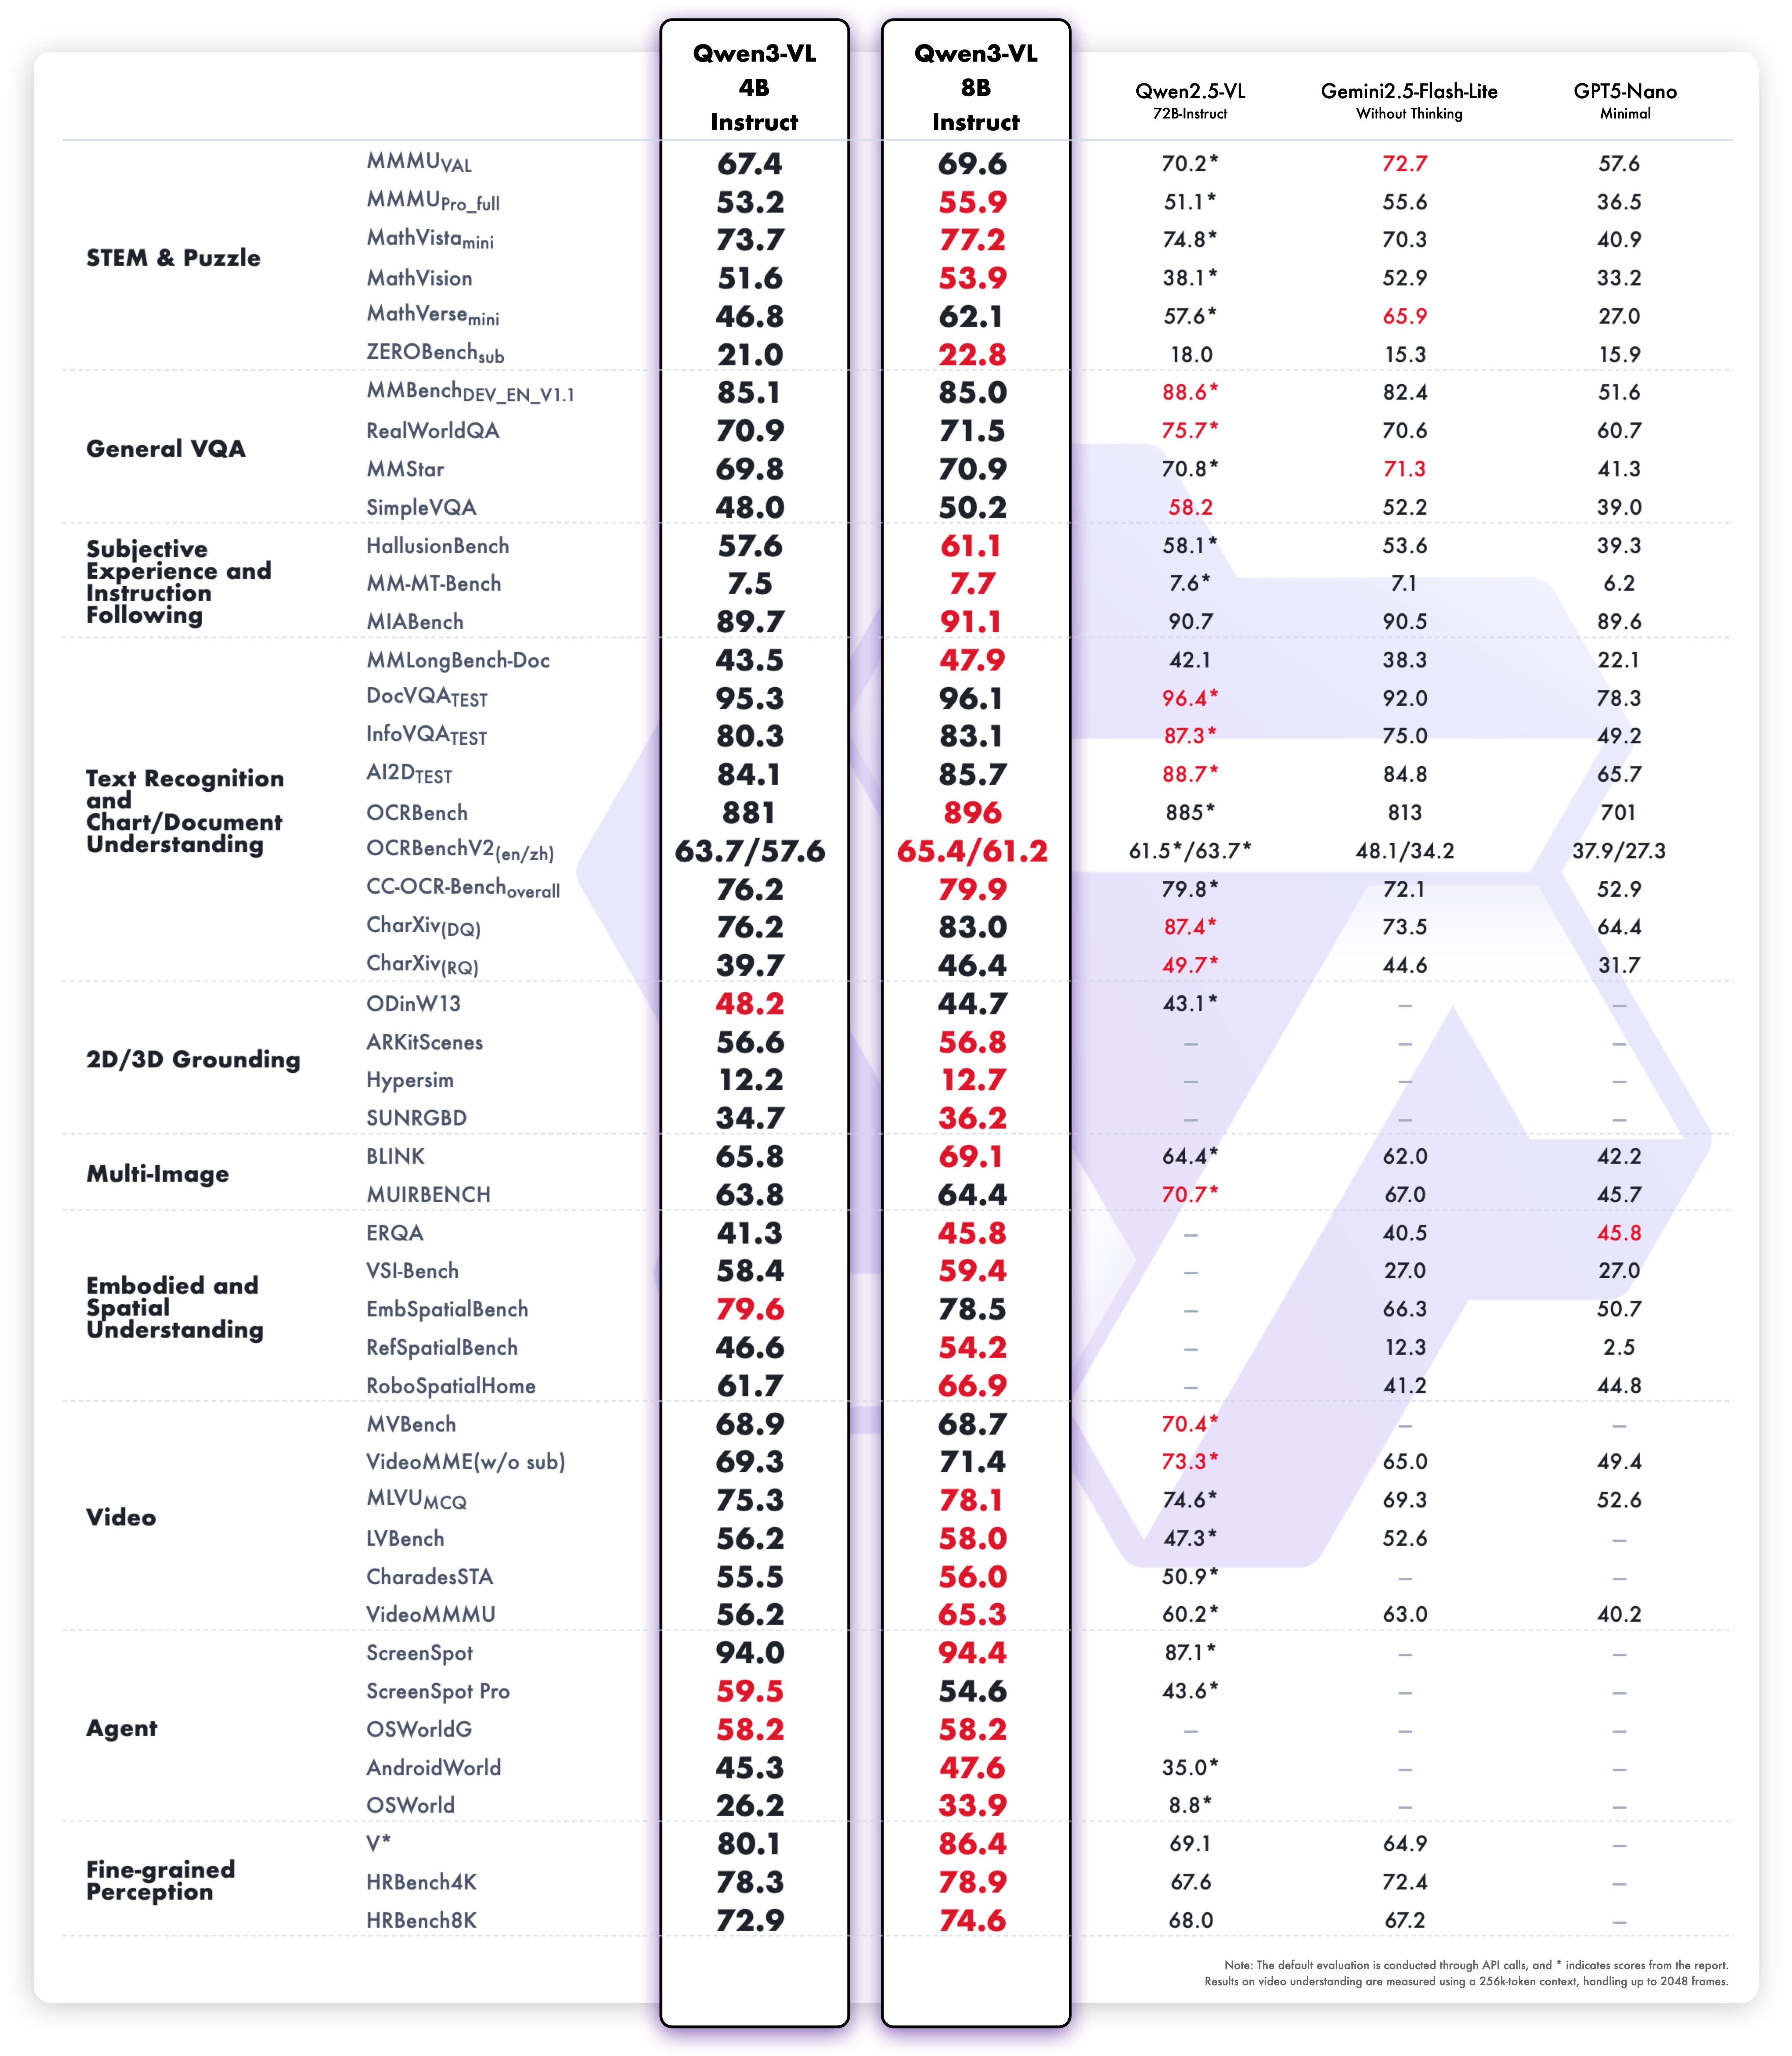
Multimodal performance
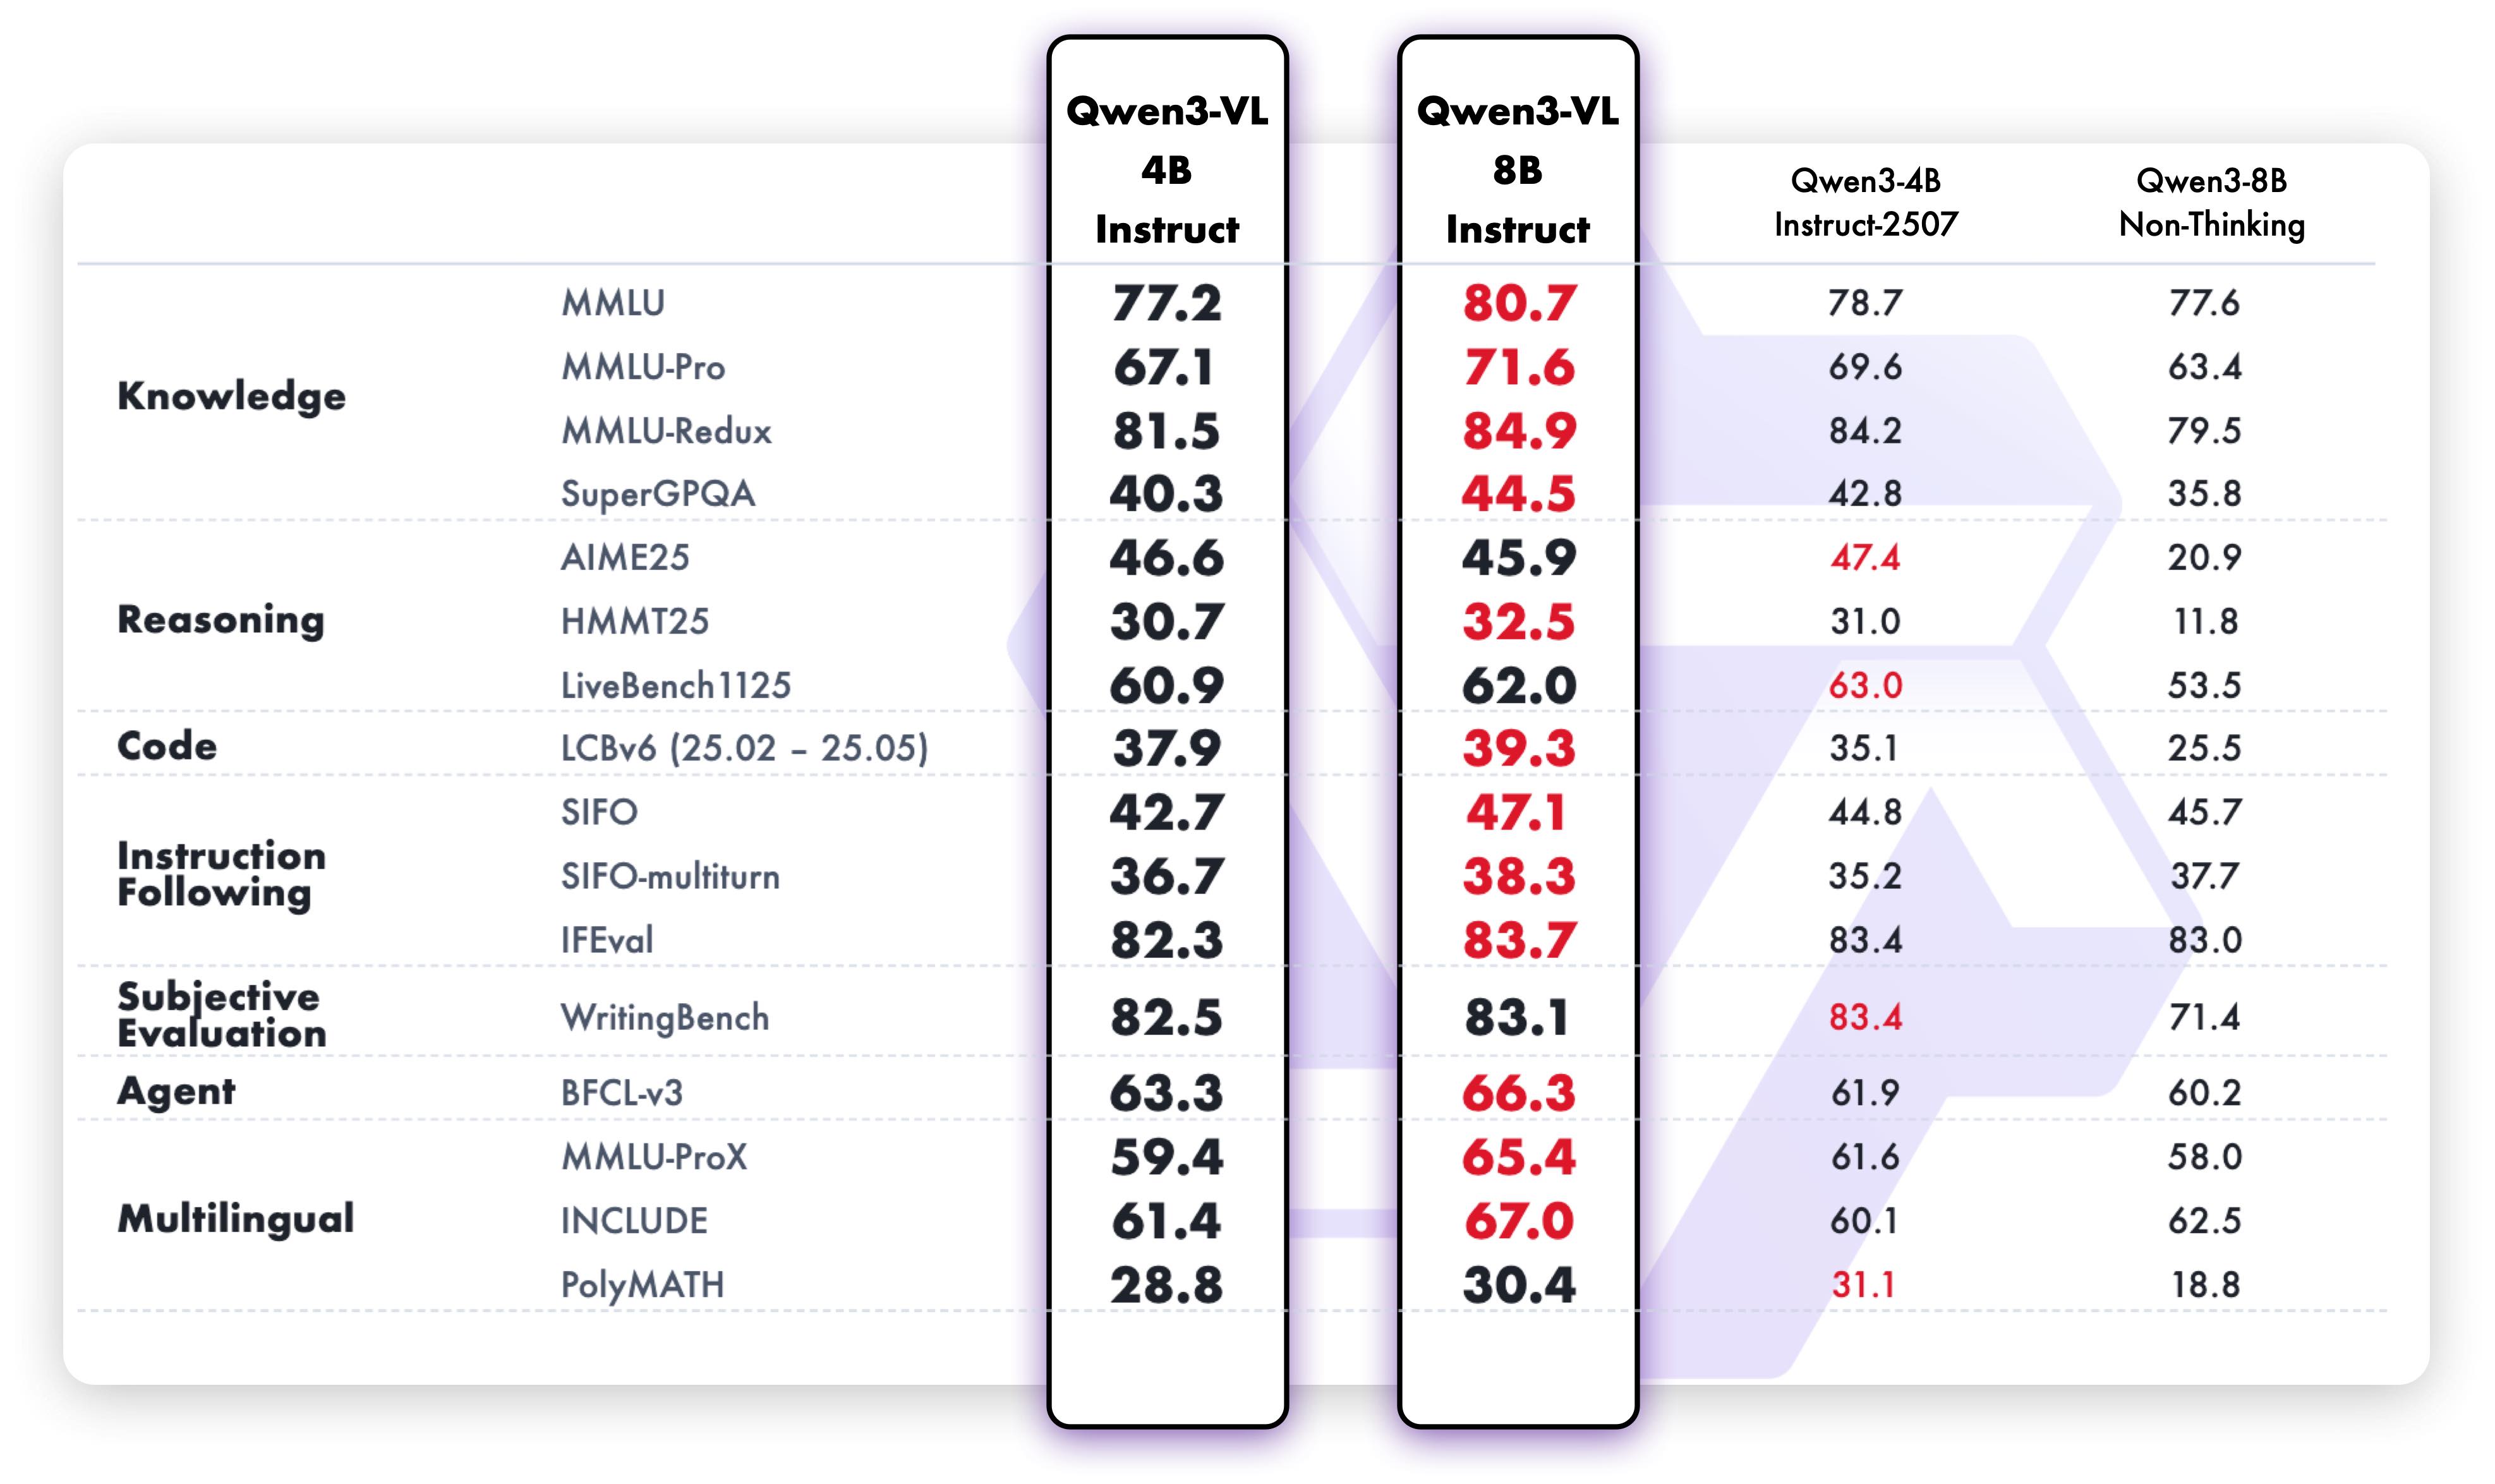
Pure text performance
export greedy='false'
export top_p=0.8
export top_k=20
export temperature=0.7
export repetition_penalty=1.0
export presence_penalty=1.5
export out_seq_length=16384
export greedy='false'
export top_p=1.0
export top_k=40
export repetition_penalty=1.0
export presence_penalty=2.0
export temperature=1.0
export out_seq_length=32768
If you find our work helpful, feel free to give us a cite.
@misc{qwen3technicalreport,
      title={Qwen3 Technical Report},
      author={Qwen Team},
      year={2025},
      eprint={2505.09388},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2505.09388},
}

@article{Qwen2.5-VL,
  title={Qwen2.5-VL Technical Report},
  author={Bai, Shuai and Chen, Keqin and Liu, Xuejing and Wang, Jialin and Ge, Wenbin and Song, Sibo and Dang, Kai and Wang, Peng and Wang, Shijie and Tang, Jun and Zhong, Humen and Zhu, Yuanzhi and Yang, Mingkun and Li, Zhaohai and Wan, Jianqiang and Wang, Pengfei and Ding, Wei and Fu, Zheren and Xu, Yiheng and Ye, Jiabo and Zhang, Xi and Xie, Tianbao and Cheng, Zesen and Zhang, Hang and Yang, Zhibo and Xu, Haiyang and Lin, Junyang},
  journal={arXiv preprint arXiv:2502.13923},
  year={2025}
}

@article{Qwen2VL,
  title={Qwen2-VL: Enhancing Vision-Language Model's Perception of the World at Any Resolution},
  author={Wang, Peng and Bai, Shuai and Tan, Sinan and Wang, Shijie and Fan, Zhihao and Bai, Jinze and Chen, Keqin and Liu, Xuejing and Wang, Jialin and Ge, Wenbin and Fan, Yang and Dang, Kai and Du, Mengfei and Ren, Xuancheng and Men, Rui and Liu, Dayiheng and Zhou, Chang and Zhou, Jingren and Lin, Junyang},
  journal={arXiv preprint arXiv:2409.12191},
  year={2024}
}

@article{Qwen-VL,
  title={Qwen-VL: A Versatile Vision-Language Model for Understanding, Localization, Text Reading, and Beyond},
  author={Bai, Jinze and Bai, Shuai and Yang, Shusheng and Wang, Shijie and Tan, Sinan and Wang, Peng and Lin, Junyang and Zhou, Chang and Zhou, Jingren},
  journal={arXiv preprint arXiv:2308.12966},
  year={2023}
}