



Sponsored by
Vmake Labs Video Enhancer
vidore / colsmolvlm-v0.1
Model's Last Updated: March 14 2025
visual-document-retrieval
Introduction of colsmolvlm-v0.1
Model Details of colsmolvlm-v0.1
ColSmolVLM-v0.1: Visual Retriever based on SmolVLM-Instruct with ColBERT strategy
This is a version trained with batch_size 128 for 3 epochs
ColSmolVLM is a model based on a novel model architecture and training strategy based on Vision Language Models (VLMs) to efficiently index documents from their visual features. It is a SmolVLM extension that generates ColBERT - style multi-vector representations of text and images. It was introduced in the paper ColPali: Efficient Document Retrieval with Vision Language Models and first released in this repository
This version is the untrained base version to guarantee deterministic projection layer initialization.
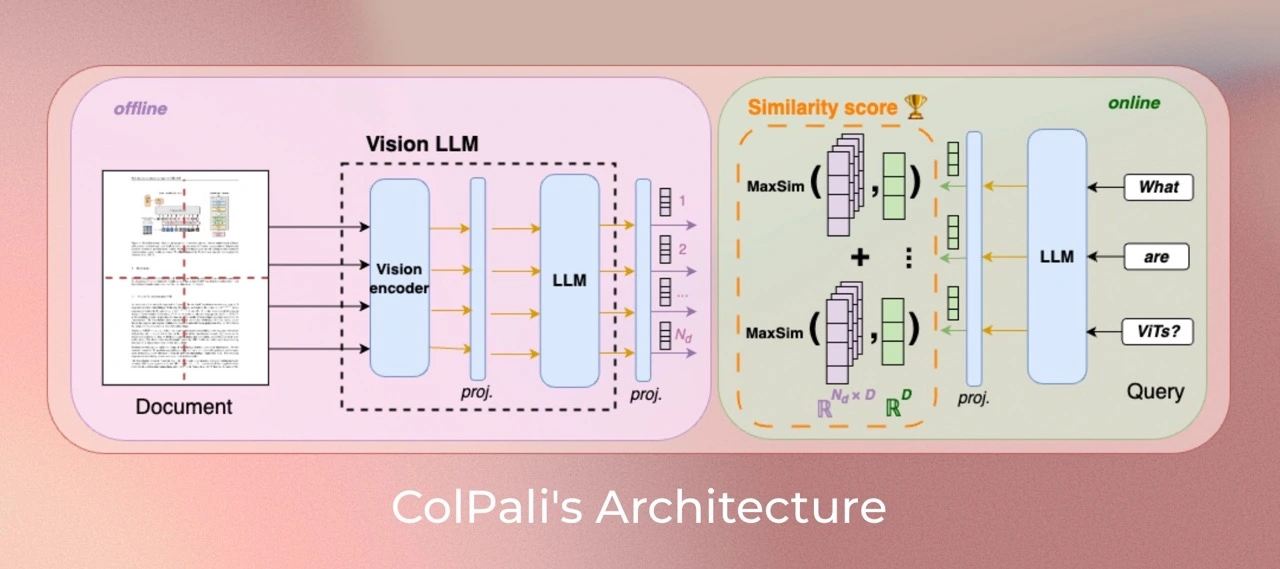
Version specificity
This version is trained with
colpali-engine==0.3.5
. (main branch from the repo)
Data is the same as the ColPali data described in the paper.
Model Training
Dataset
Our training dataset of 127,460 query-page pairs is comprised of train sets of openly available academic datasets (63%) and a synthetic dataset made up of pages from web-crawled PDF documents and augmented with VLM-generated (Claude-3 Sonnet) pseudo-questions (37%). Our training set is fully English by design, enabling us to study zero-shot generalization to non-English languages. We explicitly verify no multi-page PDF document is used both ViDoRe and in the train set to prevent evaluation contamination. A validation set is created with 2% of the samples to tune hyperparameters.
Note: Multilingual data is present in the pretraining corpus of the language model and most probably in the multimodal training.
Parameters
Unless specified otherwise, we train models in
bfloat16
format, use low-rank adapters (
LoRA
)
with
alpha=32
and
r=32
on the transformer layers from the language model,
as well as the final randomly initialized projection layer, and use a
paged_adamw_8bit
optimizer.
We train on a 4 GPU setup with data parallelism, a learning rate of 5e-4 with linear decay with 2.5% warmup steps, and a batch size of 32.
Usage
Make sure
colpali-engine
is installed from source or with a version superior to 0.3.5 (main branch from the repo currently).
transformers
version must be > 4.46.2.
pip install git+https://github.com/illuin-tech/colpali
import torch
from PIL import Image

from colpali_engine.models import ColIdefics3, ColIdefics3Processor

model = ColIdefics3.from_pretrained(
        "vidore/colsmolvlm-v0.1",
        torch_dtype=torch.bfloat16,
        device_map="cuda:0",
        attn_implementation="flash_attention_2" # or eager
    ).eval()
processor = ColIdefics3Processor.from_pretrained("vidore/colsmolvlm-v0.1")

# Your inputs
images = [
    Image.new("RGB", (32, 32), color="white"),
    Image.new("RGB", (16, 16), color="black"),
]
queries = [
    "Is attention really all you need?",
    "What is the amount of bananas farmed in Salvador?",
]

# Process the inputs
batch_images = processor.process_images(images).to(model.device)
batch_queries = processor.process_queries(queries).to(model.device)

# Forward pass
with torch.no_grad():
    image_embeddings = model(**batch_images)
    query_embeddings = model(**batch_queries)

scores = processor.score_multi_vector(query_embeddings, image_embeddings)
Limitations
- Focus : The model primarily focuses on PDF-type documents and high-ressources languages, potentially limiting its generalization to other document types or less represented languages.
- Support : The model relies on multi-vector retreiving derived from the ColBERT late interaction mechanism, which may require engineering efforts to adapt to widely used vector retrieval frameworks that lack native multi-vector support.
License
ColQwen2's vision language backbone model (Qwen2-VL) is under
apache2.0
license. The adapters attached to the model are under MIT license.
Contact
- Manuel Faysse: [email protected]
- Hugues Sibille: [email protected]
- Tony Wu: [email protected]
Citation
If you use any datasets or models from this organization in your research, please cite the original dataset as follows:
@misc{faysse2024colpaliefficientdocumentretrieval,
  title={ColPali: Efficient Document Retrieval with Vision Language Models},
  author={Manuel Faysse and Hugues Sibille and Tony Wu and Bilel Omrani and Gautier Viaud and Céline Hudelot and Pierre Colombo},
  year={2024},
  eprint={2407.01449},
  archivePrefix={arXiv},
  primaryClass={cs.IR},
  url={https://arxiv.org/abs/2407.01449},
}
Runs of vidore colsmolvlm-v0.1 on huggingface.co
25
Total runs
0
24-hour runs
0
3-day runs
-5
7-day runs
-21
30-day runs
More Information About colsmolvlm-v0.1 huggingface.co Model
Url of colsmolvlm-v0.1
colsmolvlm-v0.1 huggingface.co Url
Provider of colsmolvlm-v0.1 huggingface.co
Other API from vidore
Total runs:
232.3K
Run Growth:
16.1K
Growth Rate:
6.93%
Total runs:
96.5K
Run Growth:
-4.6K
Growth Rate:
-4.73%
Total runs:
22.1K
Run Growth:
-26.9K
Growth Rate:
-121.94%
Total runs:
3.7K
Run Growth:
-1.1K
Growth Rate:
-28.41%
Total runs:
109
Run Growth:
-29
Growth Rate:
-26.61%
Total runs:
67
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%
Total runs:
0
Run Growth:
0
Growth Rate:
0.00%