
vivym / bk-sdm-tiny-vpred

huggingface.co
Total runs: 11
24-hour runs: 0
7-day runs: -1
30-day runs: 5
Model's Last Updated: October 30 2023
text-to-image

Introduction of bk-sdm-tiny-vpred

Model Details of bk-sdm-tiny-vpred

v-prediction variant of BK-SDM-Tiny

Trained on text-image pairs from Midjourney v5.2, 13000 steps with a batch size of 2048.

BK-SDM Model Card

Block-removed Knowledge-distilled Stable Diffusion Model (BK-SDM) is an architecturally compressed SDM for efficient general-purpose text-to-image synthesis. This model is bulit with (i) removing several residual and attention blocks from the U-Net of Stable Diffusion v1.4 and (ii) distillation pretraining on only 0.22M LAION pairs (fewer than 0.1% of the full training set). Despite being trained with very limited resources, our compact model can imitate the original SDM by benefiting from transferred knowledge.

Examples with 🤗 Diffusers library .

An inference code with the default PNDM scheduler and 50 denoising steps is as follows.

import torch
from diffusers import StableDiffusionPipeline

pipe = StableDiffusionPipeline.from_pretrained("nota-ai/bk-sdm-tiny", torch_dtype=torch.float16)
pipe = pipe.to("cuda")

prompt = "a tropical bird sitting on a branch of a tree"
image = pipe(prompt).images[0]

image.save("example.png")

The following code is also runnable, because we compressed the U-Net of Stable Diffusion v1.4 while keeping the other parts (i.e., Text Encoder and Image Decoder) unchanged:

import torch
from diffusers import StableDiffusionPipeline, UNet2DConditionModel

pipe = StableDiffusionPipeline.from_pretrained("CompVis/stable-diffusion-v1-4", torch_dtype=torch.float16)
pipe.unet = UNet2DConditionModel.from_pretrained("nota-ai/bk-sdm-tiny", subfolder="unet", torch_dtype=torch.float16)
pipe = pipe.to("cuda")

prompt = "a tropical bird sitting on a branch of a tree"
image = pipe(prompt).images[0]

image.save("example.png")
Compression Method
U-Net Architecture

Certain residual and attention blocks were eliminated from the U-Net of SDM-v1.4:
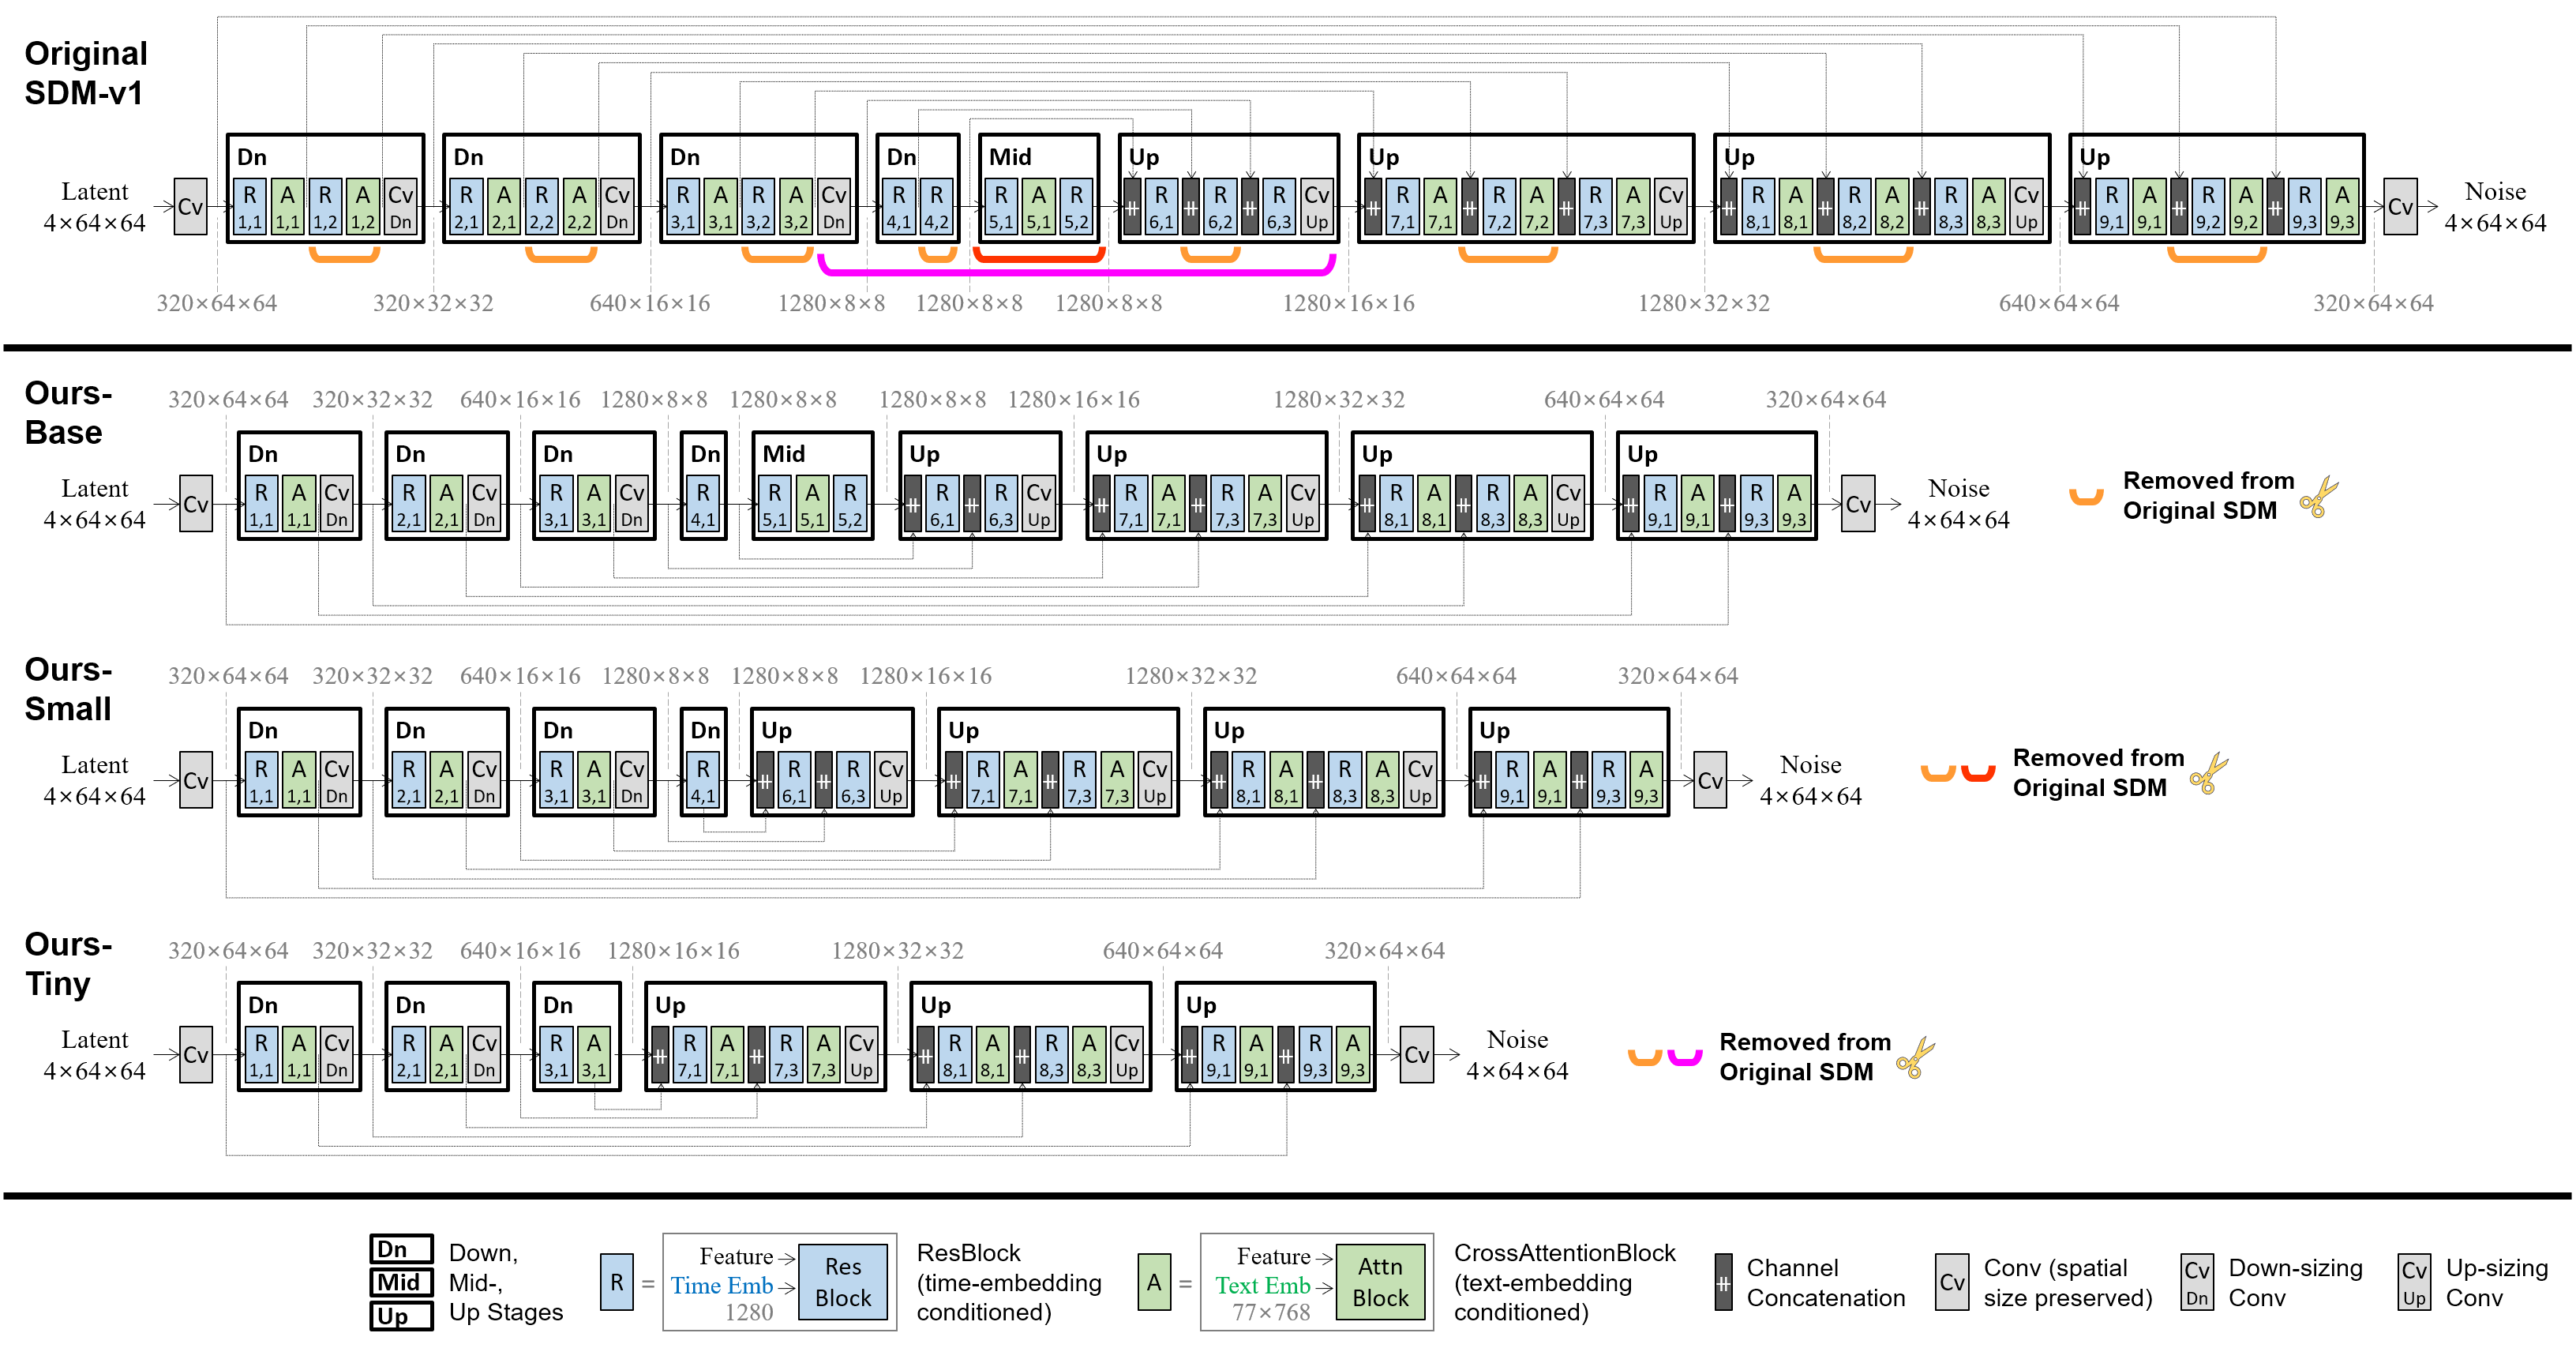
  • 1.04B-param SDM-v1.4 (0.86B-param U-Net): the original source model.
  • 0.76B-param BK-SDM-Base (0.58B-param U-Net): obtained with ① fewer blocks in outer stages.
  • 0.66B-param BK-SDM-Small (0.49B-param U-Net): obtained with ① and ② mid-stage removal.
  • 0.50B-param BK-SDM-Tiny (0.33B-param U-Net): obtained with ①, ②, and ③ further inner-stage removal.
U-Net architectures
Distillation Pretraining

The compact U-Net was trained to mimic the behavior of the original U-Net. We leveraged feature-level and output-level distillation, along with the denoising task loss.

KD-based pretraining

  • Training Data : 212,776 image-text pairs (i.e., 0.22M pairs) from LAION-Aesthetics V2 6.5+ .
  • Hardware: A single NVIDIA A100 80GB GPU
  • Gradient Accumulations : 4
  • Batch: 256 (=4×64)
  • Optimizer: AdamW
  • Learning Rate: a constant learning rate of 5e-5 for 50K-iteration pretraining
Experimental Results

The following table shows the zero-shot results on 30K samples from the MS-COCO validation split. After generating 512×512 images with the PNDM scheduler and 25 denoising steps, we downsampled them to 256×256 for evaluating generation scores. Our models were drawn at the 50K-th training iteration.

Model FID↓ IS↑ CLIP Score↑
(ViT-g/14)
# Params,
U-Net
# Params,
Whole SDM
Stable Diffusion v1.4 13.05 36.76 0.2958 0.86B 1.04B
BK-SDM-Base (Ours) 15.76 33.79 0.2878 0.58B 0.76B
BK-SDM-Small (Ours) 16.98 31.68 0.2677 0.49B 0.66B
BK-SDM-Tiny (Ours) 17.12 30.09 0.2653 0.33B 0.50B

The following figure depicts synthesized images with some MS-COCO captions.

Visual results

Uses

Note: This section is taken from the Stable Diffusion v1 model card ) (which was based on the DALLE-MINI model card ) and applies in the same way to BK-SDMs .

Direct Use

The model is intended for research purposes only. Possible research areas and tasks include

  • Safe deployment of models which have the potential to generate harmful content.
  • Probing and understanding the limitations and biases of generative models.
  • Generation of artworks and use in design and other artistic processes.
  • Applications in educational or creative tools.
  • Research on generative models.

Excluded uses are described below.

Misuse, Malicious Use, and Out-of-Scope Use

The model should not be used to intentionally create or disseminate images that create hostile or alienating environments for people. This includes generating images that people would foreseeably find disturbing, distressing, or offensive; or content that propagates historical or current stereotypes.

Out-of-Scope Use

The model was not trained to be factual or true representations of people or events, and therefore using the model to generate such content is out-of-scope for the abilities of this model.

Misuse and Malicious Use

Using the model to generate content that is cruel to individuals is a misuse of this model. This includes, but is not limited to:

  • Generating demeaning, dehumanizing, or otherwise harmful representations of people or their environments, cultures, religions, etc.
  • Intentionally promoting or propagating discriminatory content or harmful stereotypes.
  • Impersonating individuals without their consent.
  • Sexual content without consent of the people who might see it.
  • Mis- and disinformation
  • Representations of egregious violence and gore
  • Sharing of copyrighted or licensed material in violation of its terms of use.
  • Sharing content that is an alteration of copyrighted or licensed material in violation of its terms of use.
Limitations and Bias
Limitations
  • The model does not achieve perfect photorealism
  • The model cannot render legible text
  • The model does not perform well on more difficult tasks which involve compositionality, such as rendering an image corresponding to “A red cube on top of a blue sphere”
  • Faces and people in general may not be generated properly.
  • The model was trained mainly with English captions and will not work as well in other languages.
  • The autoencoding part of the model is lossy
  • The model was trained on a large-scale dataset LAION-5B which contains adult material and is not fit for product use without additional safety mechanisms and considerations.
  • No additional measures were used to deduplicate the dataset. As a result, we observe some degree of memorization for images that are duplicated in the training data. The training data can be searched at https://rom1504.github.io/clip-retrieval/ to possibly assist in the detection of memorized images.
Bias

While the capabilities of image generation models are impressive, they can also reinforce or exacerbate social biases. Stable Diffusion v1 was trained on subsets of LAION-2B(en) , which consists of images that are primarily limited to English descriptions. Texts and images from communities and cultures that use other languages are likely to be insufficiently accounted for. This affects the overall output of the model, as white and western cultures are often set as the default. Further, the ability of the model to generate content with non-English prompts is significantly worse than with English-language prompts.

Safety Module

The intended use of this model is with the Safety Checker in Diffusers. This checker works by checking model outputs against known hard-coded NSFW concepts. The concepts are intentionally hidden to reduce the likelihood of reverse-engineering this filter. Specifically, the checker compares the class probability of harmful concepts in the embedding space of the CLIPTextModel after generation of the images. The concepts are passed into the model with the generated image and compared to a hand-engineered weight for each NSFW concept.

Acknowledgments

Citation

@article{kim2023architectural,
  title={On Architectural Compression of Text-to-Image Diffusion Models},
  author={Kim, Bo-Kyeong and Song, Hyoung-Kyu and Castells, Thibault and Choi, Shinkook},
  journal={arXiv preprint arXiv:2305.15798},
  year={2023},
  url={https://arxiv.org/abs/2305.15798}
}
@article{Kim_2023_ICMLW,
  title={BK-SDM: Architecturally Compressed Stable Diffusion for Efficient Text-to-Image Generation},
  author={Kim, Bo-Kyeong and Song, Hyoung-Kyu and Castells, Thibault and Choi, Shinkook},
  journal={ICML Workshop on Efficient Systems for Foundation Models (ES-FoMo)},
  year={2023},
  url={https://openreview.net/forum?id=bOVydU0XKC}
}

This model card was written by Bo-Kyeong Kim and is based on the Stable Diffusion v1 model card .

Runs of vivym bk-sdm-tiny-vpred on huggingface.co

11
Total runs
0
24-hour runs
-1
3-day runs
-1
7-day runs
5
30-day runs

More Information About bk-sdm-tiny-vpred huggingface.co Model

More bk-sdm-tiny-vpred license Visit here:

https://choosealicense.com/licenses/creativeml-openrail-m

bk-sdm-tiny-vpred huggingface.co

bk-sdm-tiny-vpred huggingface.co is an AI model on huggingface.co that provides bk-sdm-tiny-vpred's model effect (), which can be used instantly with this vivym bk-sdm-tiny-vpred model. huggingface.co supports a free trial of the bk-sdm-tiny-vpred model, and also provides paid use of the bk-sdm-tiny-vpred. Support call bk-sdm-tiny-vpred model through api, including Node.js, Python, http.

bk-sdm-tiny-vpred huggingface.co Url

https://huggingface.co/vivym/bk-sdm-tiny-vpred

vivym bk-sdm-tiny-vpred online free

bk-sdm-tiny-vpred huggingface.co is an online trial and call api platform, which integrates bk-sdm-tiny-vpred's modeling effects, including api services, and provides a free online trial of bk-sdm-tiny-vpred, you can try bk-sdm-tiny-vpred online for free by clicking the link below.

vivym bk-sdm-tiny-vpred online free url in huggingface.co:

https://huggingface.co/vivym/bk-sdm-tiny-vpred

bk-sdm-tiny-vpred install

bk-sdm-tiny-vpred is an open source model from GitHub that offers a free installation service, and any user can find bk-sdm-tiny-vpred on GitHub to install. At the same time, huggingface.co provides the effect of bk-sdm-tiny-vpred install, users can directly use bk-sdm-tiny-vpred installed effect in huggingface.co for debugging and trial. It also supports api for free installation.

bk-sdm-tiny-vpred install url in huggingface.co:

https://huggingface.co/vivym/bk-sdm-tiny-vpred

Url of bk-sdm-tiny-vpred

bk-sdm-tiny-vpred huggingface.co Url

Provider of bk-sdm-tiny-vpred huggingface.co

vivym
ORGANIZATIONS

Other API from vivym

huggingface.co

Total runs: 76
Run Growth: 40
Growth Rate: 52.63%
Updated:September 27 2024
huggingface.co

Total runs: 4
Run Growth: 2
Growth Rate: 50.00%
Updated:June 17 2024
huggingface.co

Total runs: 0
Run Growth: -3
Growth Rate: 0.00%
Updated:June 18 2024
huggingface.co

Total runs: 0
Run Growth: 0
Growth Rate: 0.00%
Updated:February 27 2024
huggingface.co

Total runs: 0
Run Growth: 0
Growth Rate: 0.00%
Updated:December 13 2024
huggingface.co

Total runs: 0
Run Growth: 0
Growth Rate: 0.00%
Updated:November 14 2022
huggingface.co

Total runs: 0
Run Growth: 0
Growth Rate: 0.00%
Updated:July 21 2023