
zsxkib / blip-3

Blip 3 / XGen-MM, Answers questions about images ({blip3,xgen-mm}-phi3-mini-base-r-v1)

replicate.com
Total runs: 1.2M
24-hour runs: 0
7-day runs: 0
30-day runs: 0
Github
Model's Last Updated: May 13 2024

Introduction of blip-3

Model Details of blip-3

Readme

Readme

Unofficial BLIP-3 (xgen-mm-phi3-mini-instruct-r-v1) demo and API

Note that this is an unofficial implementation of BLIP-3 (previously known as blip3-phi3-mini-base-r-v1) that is not associated with Salesforce.

Usage

BLIP-3 is a model that answers questions about images. To use it, provide an image, and then ask a question about that image. For example, you can provide the following image:
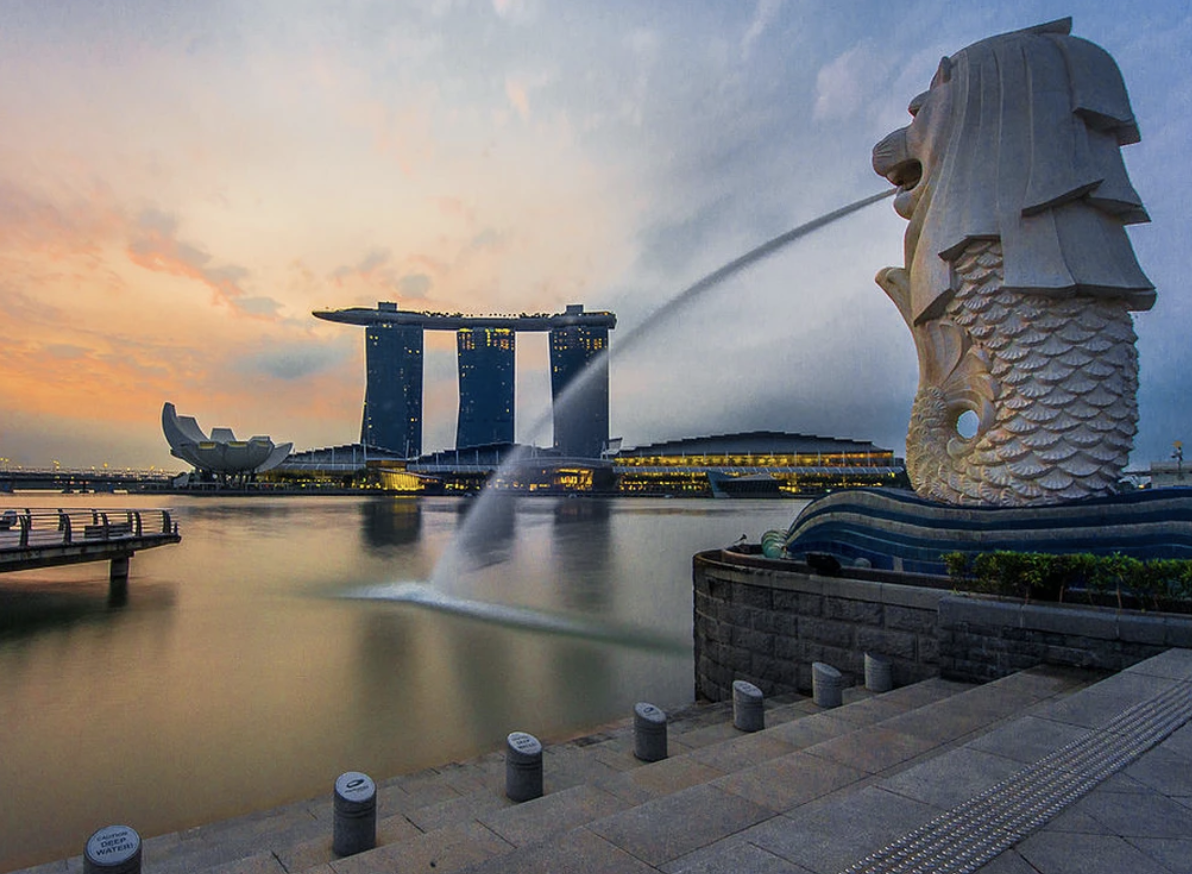
Marina Bay Sands

and then pose the following question:

What is this a picture of?

and get the output:

Marina Bay Sands, Singapore.

BLIP-3 is also capable of captioning images. This works by sending the model a blank prompt, though we have an explicit toggle for image captioning in the UI & API.

You can also provide BLIP-3 with more context when asking a question. For example, given the following image:
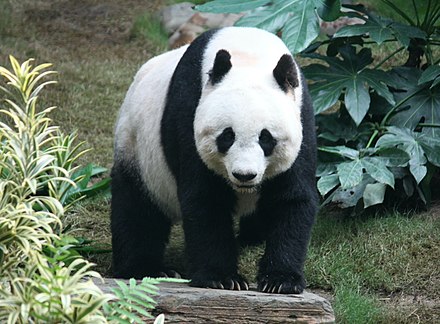
Panda

you can provide the output of a previous Q&A as context in question: … answer: … format like so:

question: What animal is this? answer: A panda

and then pose an additional question:

What country is this animal native to?

and get the output:

China

Model description

XGen-MM (previously known as BLIP-3) is a series of the latest foundational Large Multimodal Models (LMMs) developed by Salesforce AI Research. This series advances upon the successful designs of the BLIP series, incorporating fundamental enhancements that ensure a more robust and superior foundation.

Key features of XGen-MM: - The pretrained foundation model, xgen-mm-phi3-mini-base-r-v1, achieves state-of-the-art performance under 5b parameters and demonstrates strong in-context learning capabilities. - The instruct fine-tuned model, xgen-mm-phi3-mini-instruct-r-v1, achieves state-of-the-art performance among open-source and closed-source VLMs under 5b parameters. - xgen-mm-phi3-mini-instruct-r-v1 supports flexible high-resolution image encoding with efficient visual token sampling.

These models have been trained at scale on high-quality image caption datasets and interleaved image-text data.

Citation

@misc{xgen_mm_phi3_mini, title={xgen-mm-phi3-mini-instruct Model Card}, url={ https://huggingface.co/Salesforce/xgen-mm-phi3-mini-instruct-r-v1 }, author={Salesforce AI Research}, month={May}, year={2024} }
Pricing of blip-3 replicate.com

Run time and cost

This model costs approximately $0.0038 to run on Replicate, or 263 runs per $1, but this varies depending on your inputs. It is also open source and you can run it on your own computer with Docker .

This model runs on Nvidia A100 (80GB) GPU hardware . Predictions typically complete within 3 seconds.

Runs of zsxkib blip-3 on replicate.com

1.2M
Total runs
0
24-hour runs
0
3-day runs
0
7-day runs
0
30-day runs

More Information About blip-3 replicate.com Model

More blip-3 license Visit here:

https://spdx.org/licenses/CC-BY-NC-4.0

blip-3 replicate.com

blip-3 replicate.com is an AI model on replicate.com that provides blip-3's model effect (Blip 3 / XGen-MM, Answers questions about images ({blip3,xgen-mm}-phi3-mini-base-r-v1)), which can be used instantly with this zsxkib blip-3 model. replicate.com supports a free trial of the blip-3 model, and also provides paid use of the blip-3. Support call blip-3 model through api, including Node.js, Python, http.

zsxkib blip-3 online free

blip-3 replicate.com is an online trial and call api platform, which integrates blip-3's modeling effects, including api services, and provides a free online trial of blip-3, you can try blip-3 online for free by clicking the link below.

zsxkib blip-3 online free url in replicate.com:

https://replicate.com/zsxkib/blip-3

blip-3 install

blip-3 is an open source model from GitHub that offers a free installation service, and any user can find blip-3 on GitHub to install. At the same time, replicate.com provides the effect of blip-3 install, users can directly use blip-3 installed effect in replicate.com for debugging and trial. It also supports api for free installation.

blip-3 install url in replicate.com:

https://replicate.com/zsxkib/blip-3

blip-3 install url in github:

https://github.com/zsxkib/cog-blip-3

Url of blip-3

Provider of blip-3 replicate.com

Other API from zsxkib

replicate

📖 PuLID: Pure and Lightning ID Customization via Contrastive Alignment

Total runs: 1.2M
Run Growth: 0
Growth Rate: 0.00%
Updated:May 16 2024
replicate

Make realistic images of real people instantly

Total runs: 848.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:December 11 2024
replicate

Create song covers with any RVC v2 trained AI voice from audio files.

Total runs: 637.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 16 2023
replicate

⚡️FLUX PuLID: FLUX-dev based Pure and Lightning ID Customization via Contrastive Alignment🎭

Total runs: 601.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 16 2024
replicate

🎨 Fill in masked parts of images with FLUX.1-dev 🖌️

Total runs: 349.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 20 2024
replicate

Add sound to video using the MMAudio V2 model. An advanced AI model that synthesizes high-quality audio from video content, enabling seamless video-to-audio transformation.

Total runs: 283.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:April 02 2025
replicate

✍️✨Prompts to auto-magically relights your images

Total runs: 207.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:May 21 2024
replicate

Age prediction using CLIP - Patched version of `https://replicate.com/andreasjansson/clip-age-predictor` that works with the new version of cog!

Total runs: 189.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 07 2023
replicate

✨DiffBIR: Towards Blind Image Restoration with Generative Diffusion Prior

Total runs: 132.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 12 2023
replicate

allenai/Molmo-7B-D-0924, Answers questions and caption about images

Total runs: 88.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 27 2024
replicate

Jina-CLIP v2: 0.9B multimodal embedding model with 89-language multilingual support, 512x512 image resolution, and Matryoshka representations

Total runs: 76.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 28 2024
replicate

🎨 AnimateDiff (w/ MotionLoRAs for Panning, Zooming, etc): Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning

Total runs: 56.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 06 2023
replicate

📽️ Increase Framerate 🎬 ST-MFNet: A Spatio-Temporal Multi-Flow Network for Frame Interpolation

Total runs: 51.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 09 2023
replicate

Hunyuan-Video LoRA Explorer + Trainer

Total runs: 31.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:January 25 2025
replicate

Monster Labs' Controlnet QR Code Monster v2 For SD-1.5 on top of AnimateDiff Prompt Travel (Motion Module SD 1.5 v2)

Total runs: 10.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 01 2023
replicate

🖼️✨Background images + prompts to auto-magically relights your images (+normal maps🗺️)

Total runs: 10.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:May 21 2024
replicate

Real-Time Open-Vocabulary Object Detection

Total runs: 9.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:February 12 2024
replicate

AuraSR v2: Second-gen GAN-based Super-Resolution for real-world applications

Total runs: 9.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 01 2024
replicate

Create your own Realistic Voice Cloning (RVC v2) dataset using a YouTube link

Total runs: 8.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 21 2023
replicate

Text-to-Video + Image-to-Video: Pyramid Flow Autoregressive Video Generation method based on Flow Matching

Total runs: 8.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 11 2024
replicate

🎨 Fill in masked parts of images with FLUX.1-schnell 🖌️

Total runs: 6.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 16 2024
replicate

🎨AnimateDiff Prompt Travel🧭 Seamlessly Navigate and Animate Between Text-to-Image Prompts for Dynamic Visual Narratives

Total runs: 5.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 19 2023
replicate

FlashFace: Human Image Personalization with High-fidelity Identity Preservation

Total runs: 4.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:April 23 2024
replicate

Make realistic images of real people instantly (w/ ip-adapter-plus-face_sdxl_vit-h)

Total runs: 3.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:July 15 2024
replicate

Upscale videos + images with BSRGAN

Total runs: 2.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:January 29 2025
replicate

Transform your portrait photos into any style or setting while preserving your facial identity

Total runs: 2.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:April 03 2025
replicate

MimicMotion: High-quality human motion video generation with pose-guided control

Total runs: 2.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:July 16 2024
replicate

AuraSR: GAN-based Super-Resolution for real-world

Total runs: 2.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 28 2024
replicate

🖼️ Super fast 1.5B Image Captioning/VQA Multimodal LLM (Image-to-Text) 🖋️

Total runs: 2.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:February 02 2024
replicate

Idefics3-8B-Llama3, Answers questions and caption about images

Total runs: 2.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 15 2024
replicate

Qwen 2: A 7 billion parameter language model from Alibaba Cloud, fine tuned for chat completions

Total runs: 1.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 26 2024
replicate

A state-of-the-art text-to-video generation model capable of creating high-quality videos with realistic motion from text descriptions

Total runs: 1.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:December 11 2024
replicate

Cubiq's ComfyUI InstantID node running `instantid_basic.json` example

Total runs: 1.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 20 2024
replicate

🎼FluxMusic Text-to-Music Generation with Rectified Flow Transformer🎶

Total runs: 1.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 26 2024
replicate

✨Stable Diffusion 3 w/ ⚡InstantX's Canny, Pose, and Tile ControlNets🖼️

Total runs: 1.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 22 2024
replicate

Image tagger fine-tuned on WaifuDiffusion w/ (SwinV2, SwinV2, ConvNext, and ViT)

Total runs: 1000
Run Growth: 0
Growth Rate: 0.00%
Updated:May 22 2024
replicate

🫦 Realistic facial expression manipulation (lip-syncing) using audio or video

Total runs: 1000
Run Growth: 0
Growth Rate: 0.00%
Updated:June 12 2024
replicate

Unofficial Re-Trained AnimateAnyone (Image + DWPose Video → Animated Video of Image)

Total runs: 853
Run Growth: 0
Growth Rate: 0.00%
Updated:January 19 2024
replicate

🎙️Hololive text-to-speech and voice-to-voice (Japanese🇯🇵 + English🇬🇧)

Total runs: 850
Run Growth: 0
Growth Rate: 0.00%
Updated:June 04 2024
replicate

MEMO is a state-of-the-art open-weight model for audio-driven talking video generation.

Total runs: 678
Run Growth: 0
Growth Rate: 0.00%
Updated:December 11 2024
replicate

🐲 DragGAN 🐉 - "Drag Your GAN: Interactive Point-based Manipulation on the Generative Image Manifold"

Total runs: 583
Run Growth: 0
Growth Rate: 0.00%
Updated:July 07 2023
replicate

Easily create video datasets with auto-captioning for Hunyuan-Video LoRA finetuning

Total runs: 532
Run Growth: 0
Growth Rate: 0.00%
Updated:April 02 2025
replicate

Surrealist digital art featuring whimsical, anthropomorphic characters with exaggerated textures and vibrant color blocking

Total runs: 480
Run Growth: 0
Growth Rate: 0.00%
Updated:October 09 2024
replicate

Transform your text into a beautiful two-tone color gradient that represents your emotions.

Total runs: 417
Run Growth: 0
Growth Rate: 0.00%
Updated:June 06 2023
replicate

STAR Video Upscaler: Spatial-Temporal Augmentation with Text-to-Video Models for Real-World Video Super-Resolution

Total runs: 382
Run Growth: 0
Growth Rate: 0.00%
Updated:February 01 2025
replicate

Super High Quality Depth Maps 🗺️: An End-to-End Tile-Based Framework 🏗️ for High-Resolution Monocular Metric Depth Estimation 🔍📏

Total runs: 362
Run Growth: 0
Growth Rate: 0.00%
Updated:December 27 2023
replicate

Qwen 2: A 1.5 billion parameter language model from Alibaba Cloud, fine tuned for chat completions

Total runs: 207
Run Growth: 0
Growth Rate: 0.00%
Updated:June 26 2024
replicate

Qwen 2: A 0.5 billion parameter language model from Alibaba Cloud, fine tuned for chat completions

Total runs: 198
Run Growth: 0
Growth Rate: 0.00%
Updated:June 25 2024
replicate

Generates realistic talking face animations from a portrait image and audio using the CVPR 2025 Sonic model

Total runs: 148
Run Growth: 0
Growth Rate: 0.00%
Updated:April 03 2025
replicate

Powerful text-to-video model that generates high-quality videos up to 6 seconds at 15 FPS and 720p resolution from simple text prompt

Total runs: 128
Run Growth: 0
Growth Rate: 0.00%
Updated:October 23 2024
replicate

Convert speech in audio to text w/ `tiny`, `small`, `base`, and `large-v3` models

Total runs: 126
Run Growth: 0
Growth Rate: 0.00%
Updated:July 02 2024
replicate

SAMURAI: Adapting Segment Anything Model for Zero-Shot Visual Tracking with Motion-Aware Memory

Total runs: 100
Run Growth: 0
Growth Rate: 0.00%
Updated:November 28 2024
replicate

Generate high-quality videos from text prompts using StepVideo

Total runs: 93
Run Growth: 0
Growth Rate: 0.00%
Updated:February 25 2025
replicate

🗣️ TalkNet-ASD: Detect who is speaking in a video

Total runs: 92
Run Growth: 0
Growth Rate: 0.00%
Updated:May 02 2024
replicate

A "Hello World" model for me to get to grips with `cog` and Replicate

Total runs: 44
Run Growth: 0
Growth Rate: 0.00%
Updated:June 06 2023
replicate

Cost-optimized MMAudio V2 (T4 GPU): Add sound to video using this version running on T4 hardware for lower cost. Synthesizes high-quality audio from video content.

Total runs: 21
Run Growth: 0
Growth Rate: 0.00%
Updated:April 02 2025
replicate

SAM 2: Segment Anything v2 (for in Images + Videos)

Total runs: 19
Run Growth: 0
Growth Rate: 0.00%
Updated:July 31 2024
replicate

Hibiki: High-Fidelity Simultaneous Speech-To-Speech Translation

Total runs: 12
Run Growth: 0
Growth Rate: 0.00%
Updated:February 11 2025
replicate

Remove background from images using BRIA-RMBG-2.0

Total runs: 2
Run Growth: 0
Growth Rate: 0.00%
Updated:November 25 2024