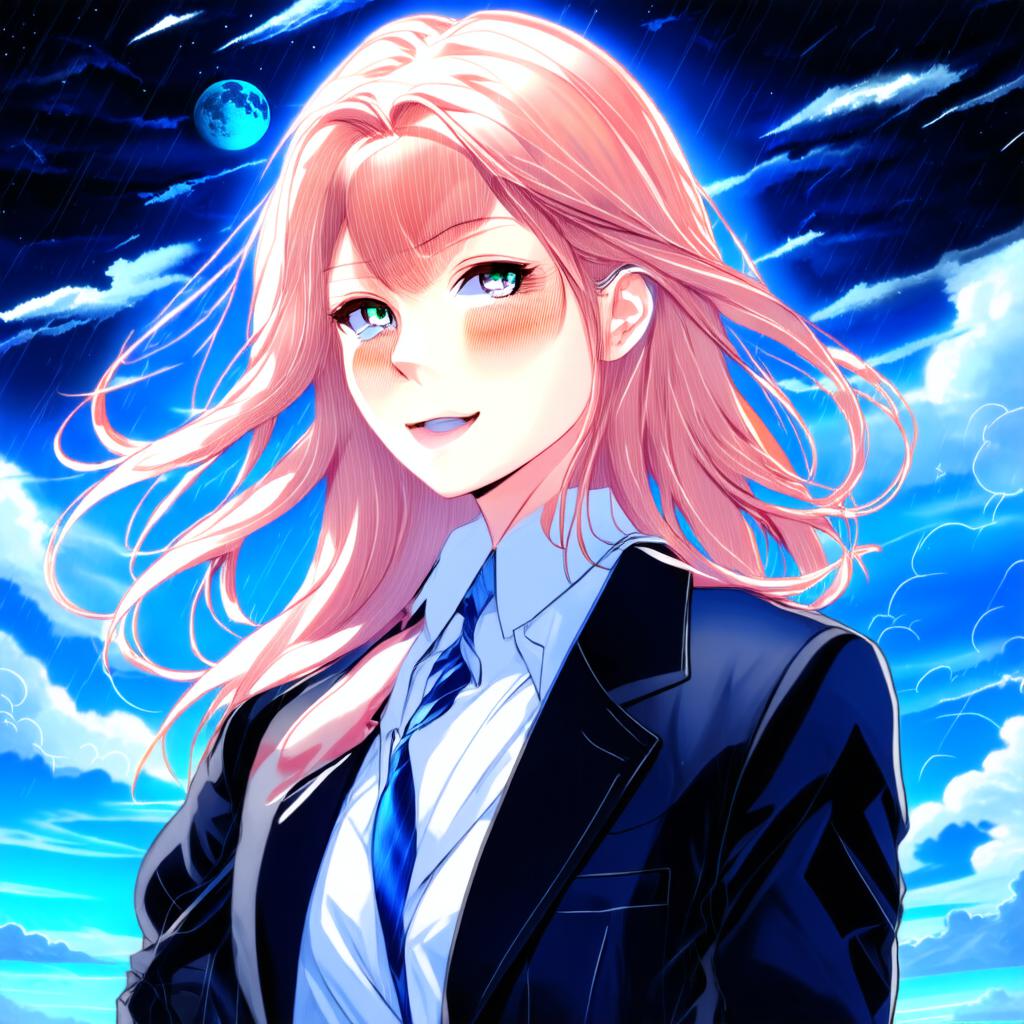
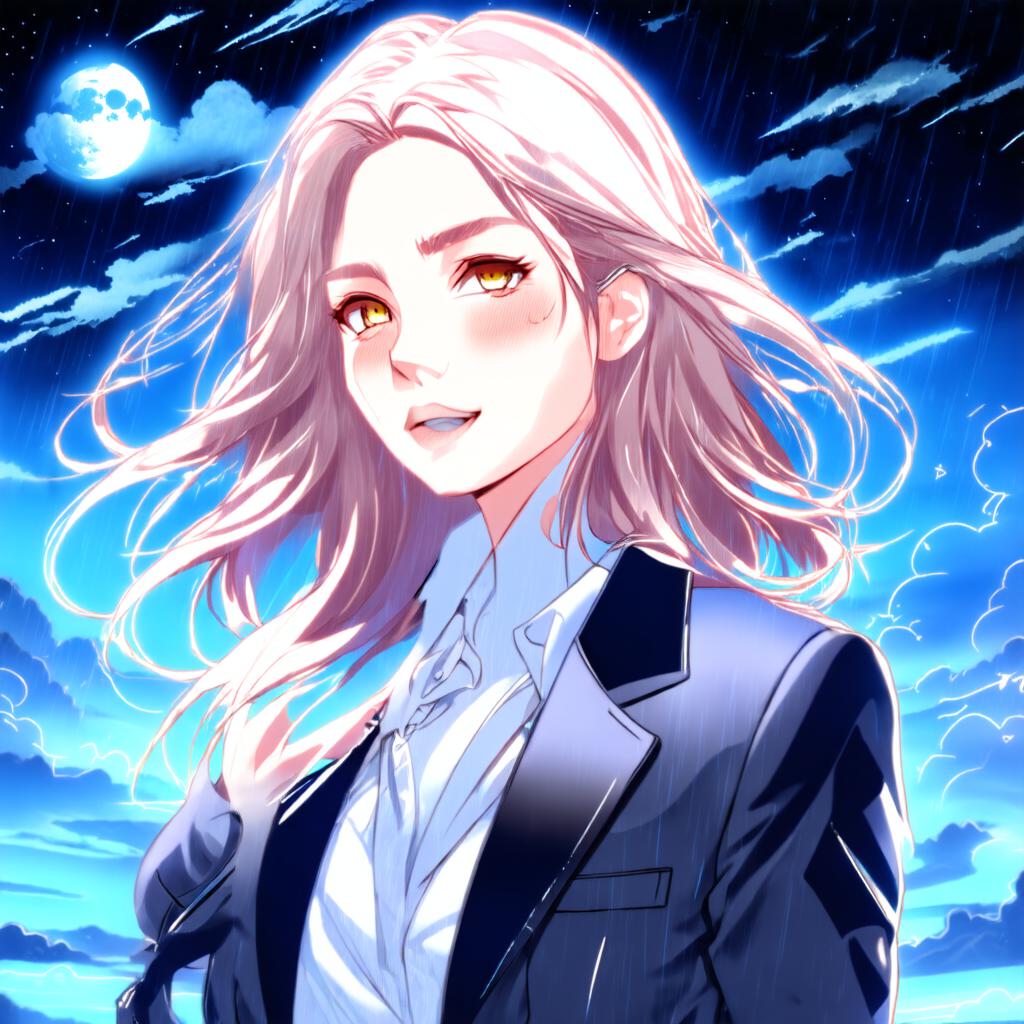
zsxkib / sd3-controlnet

✨Stable Diffusion 3 w/ ⚡InstantX's Canny, Pose, and Tile ControlNets🖼️

replicate.com
Total runs: 1.2K
24-hour runs: 0
7-day runs: 0
30-day runs: 0
Github
Model's Last Updated: June 22 2024

Introduction of sd3-controlnet

Model Details of sd3-controlnet

Readme

✨Stable Diffusion 3 w/ ⚡InstantX’s Canny, Pose, and Tile ControlNets🖼️

About

Implementation of InstantX/SD3-Controlnet-Canny , InstantX/SD3-Controlnet-Pose , and InstantX/SD3-Controlnet-Tile

Changelog
  • Added InstantX/SD3-Controlnet-Canny .
  • PNGs with alpha (transparency) channels are now converted to RGB.
  • Added InstantX/SD3-Controlnet-Pose .
  • Added InstantX/SD3-Controlnet-Tile . Implemented lazy loading for controlnets to manage GPU memory limitations, as loading all three controlnets simultaneously is not feasible.
Examples
Tile

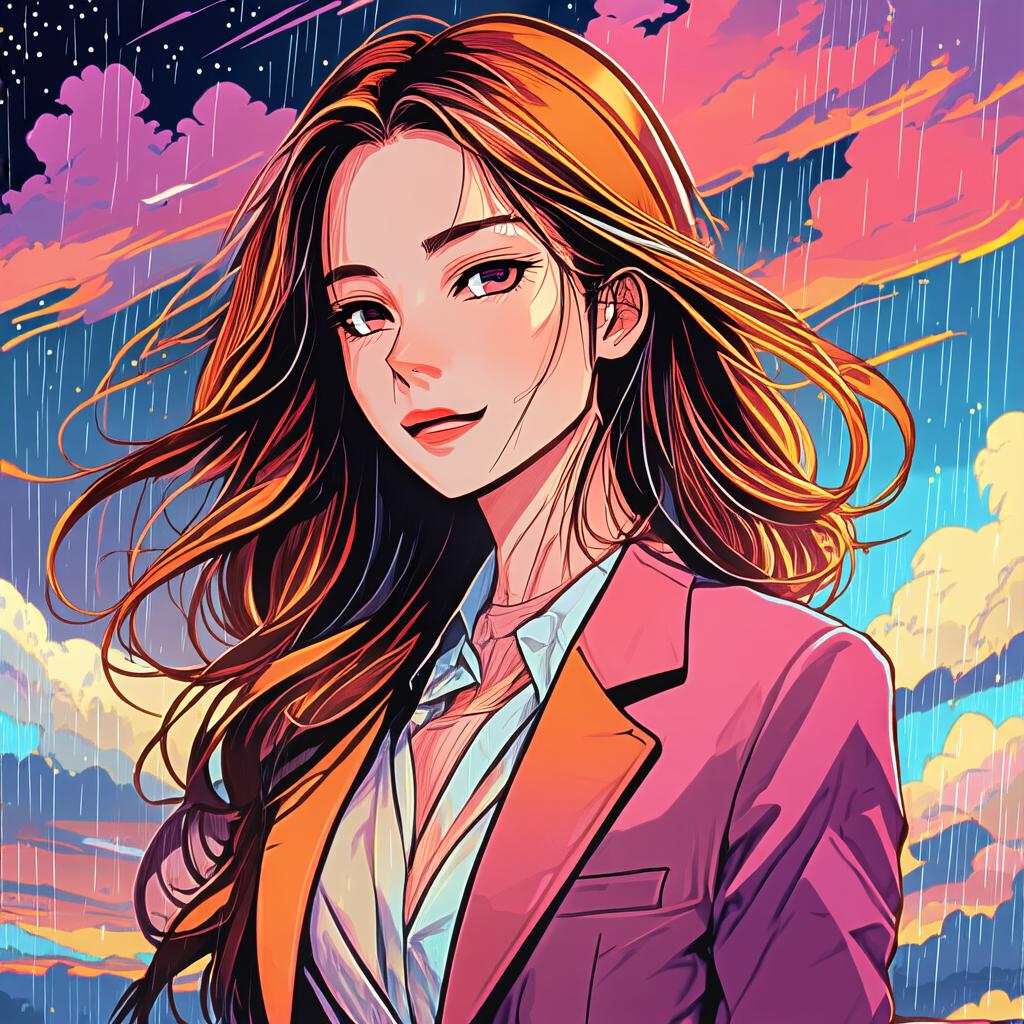
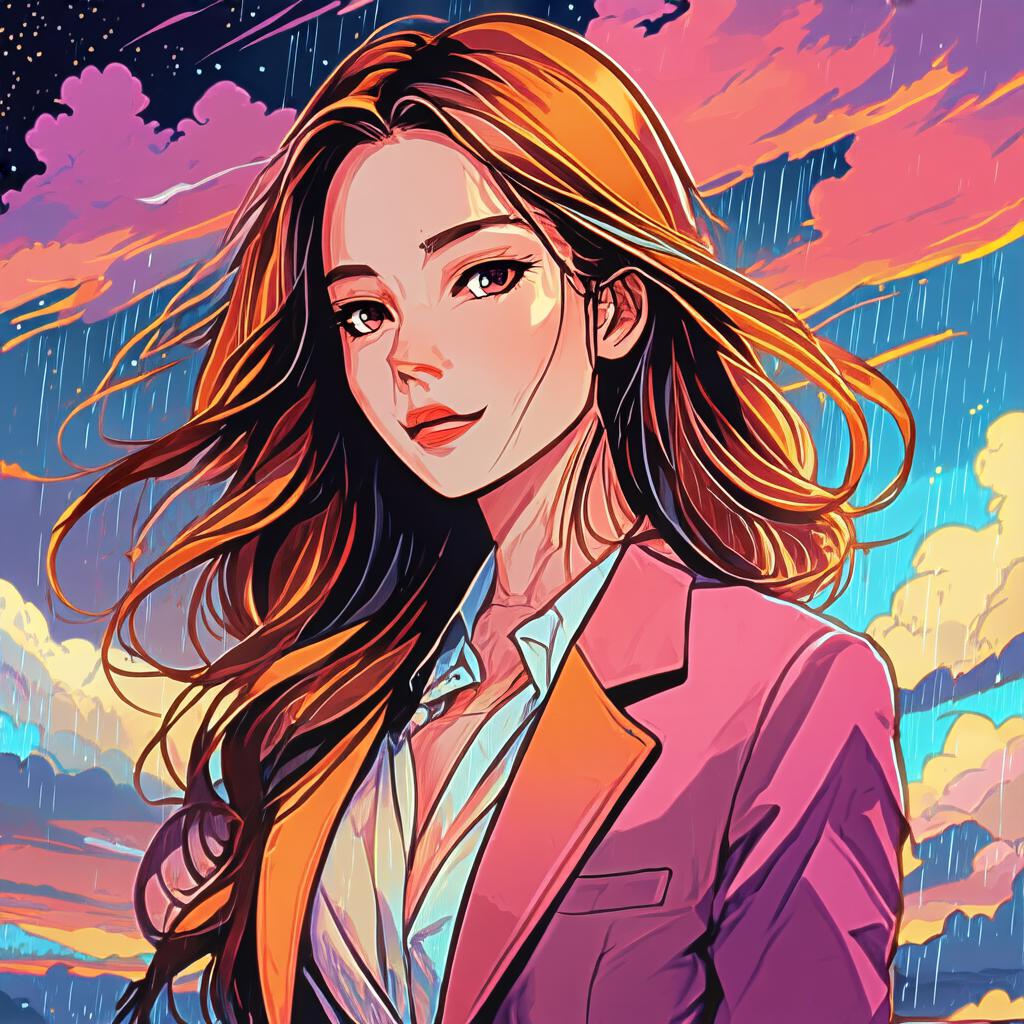
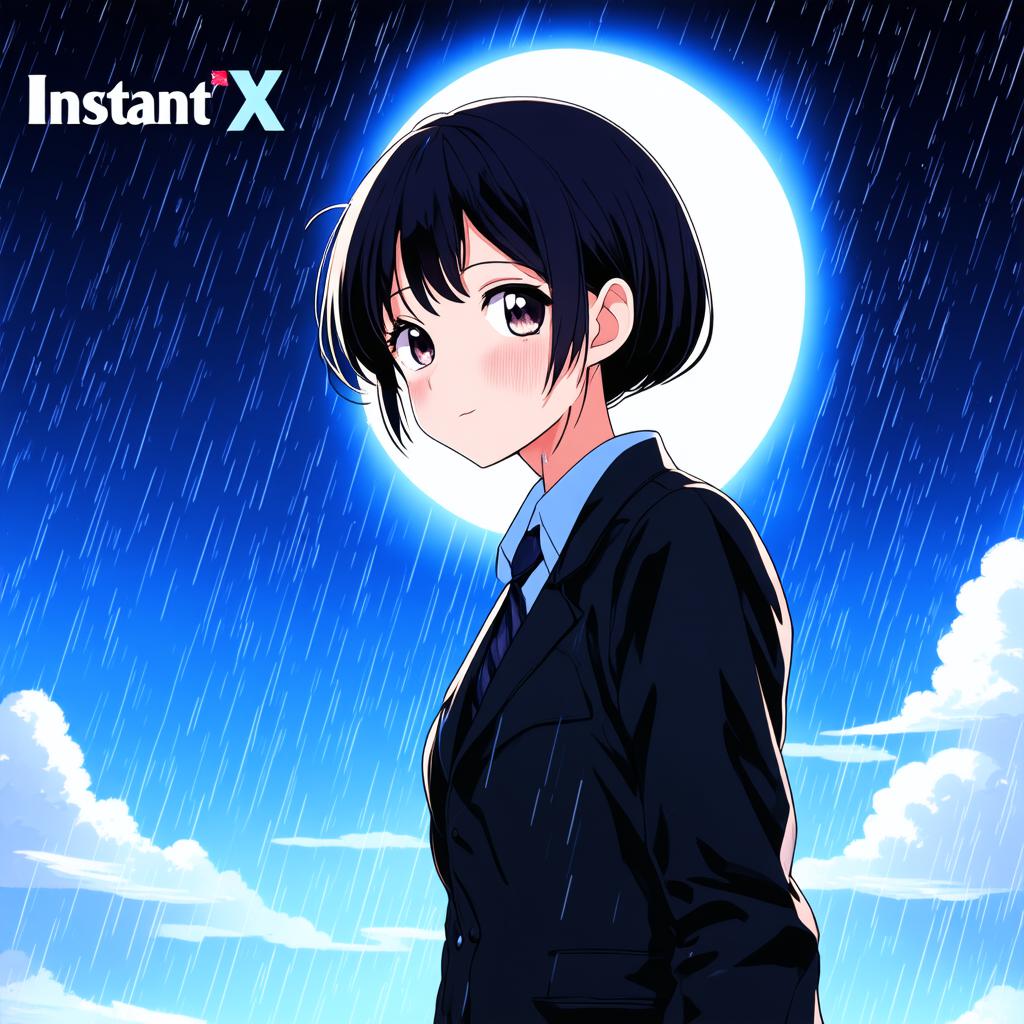
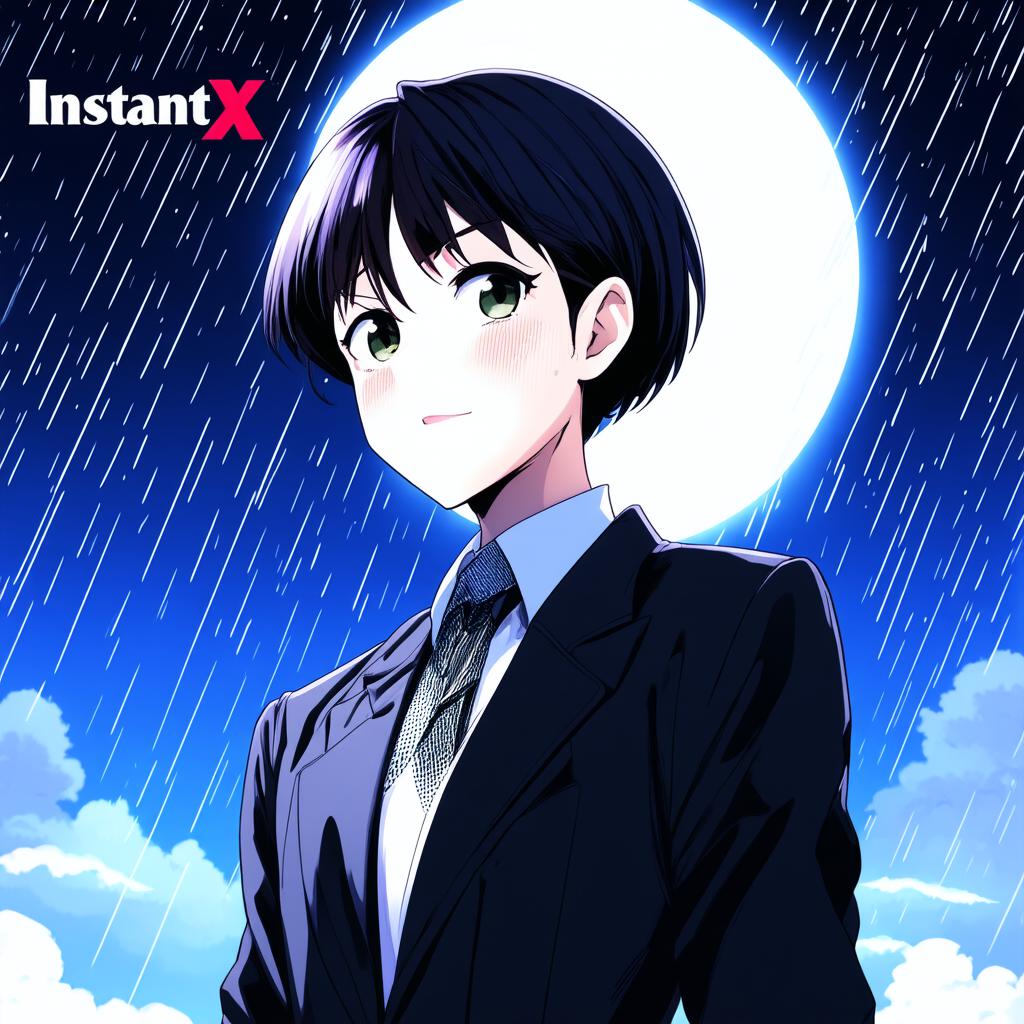
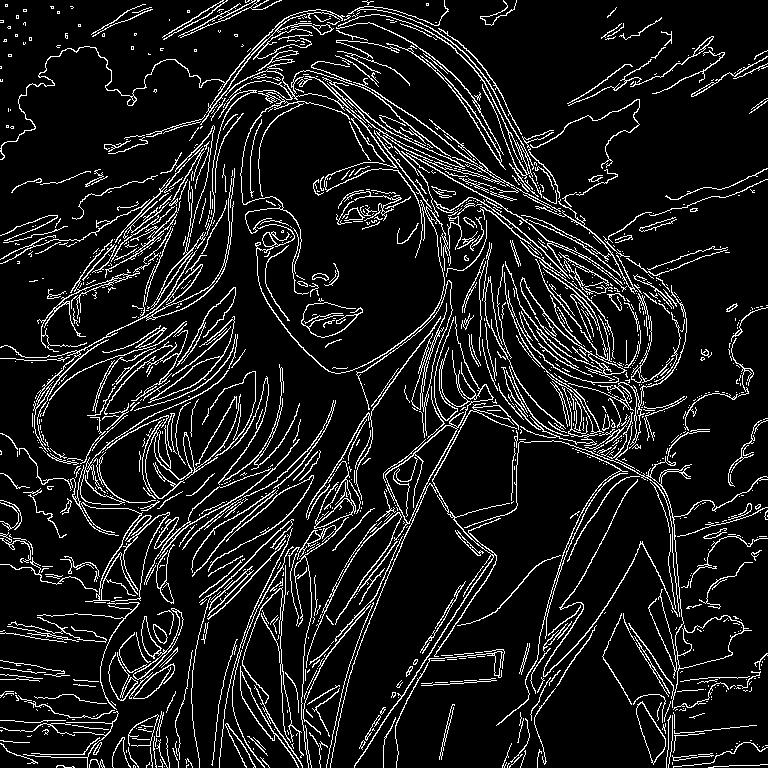
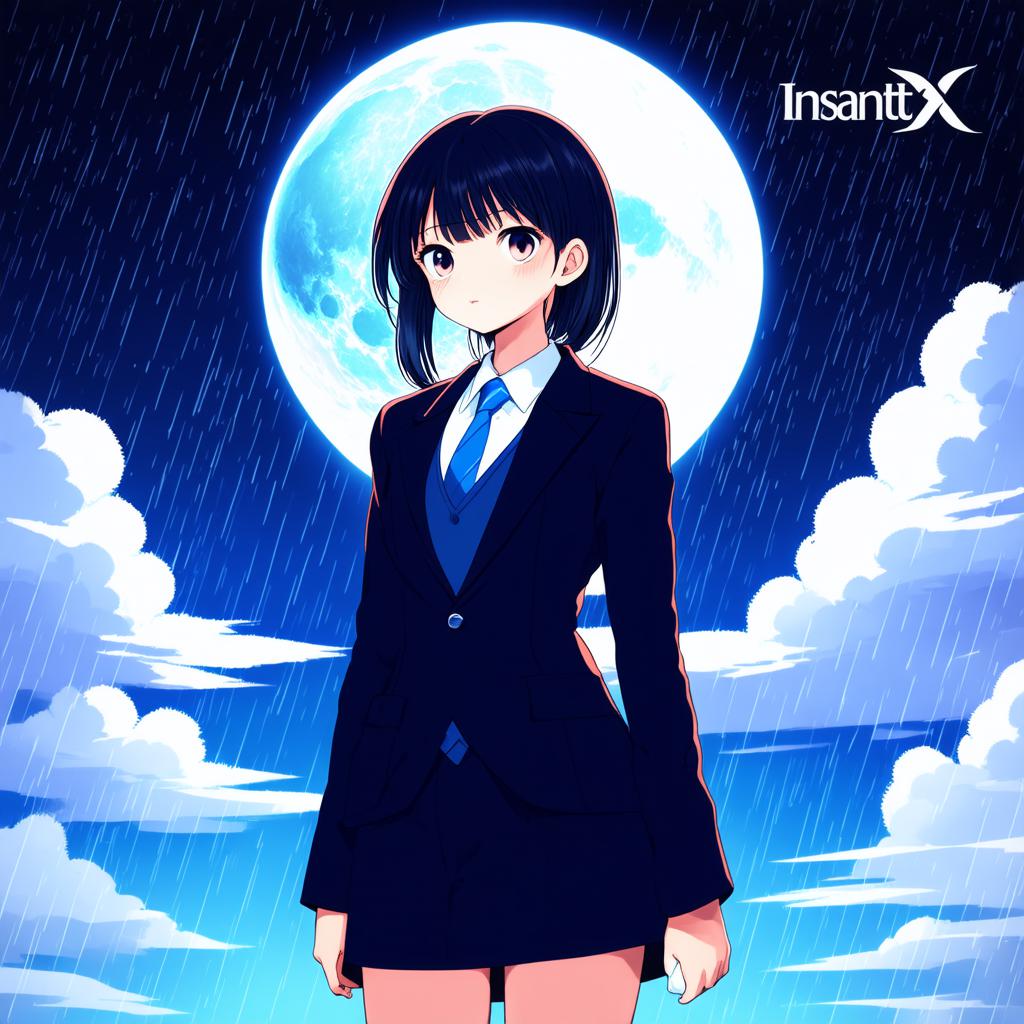
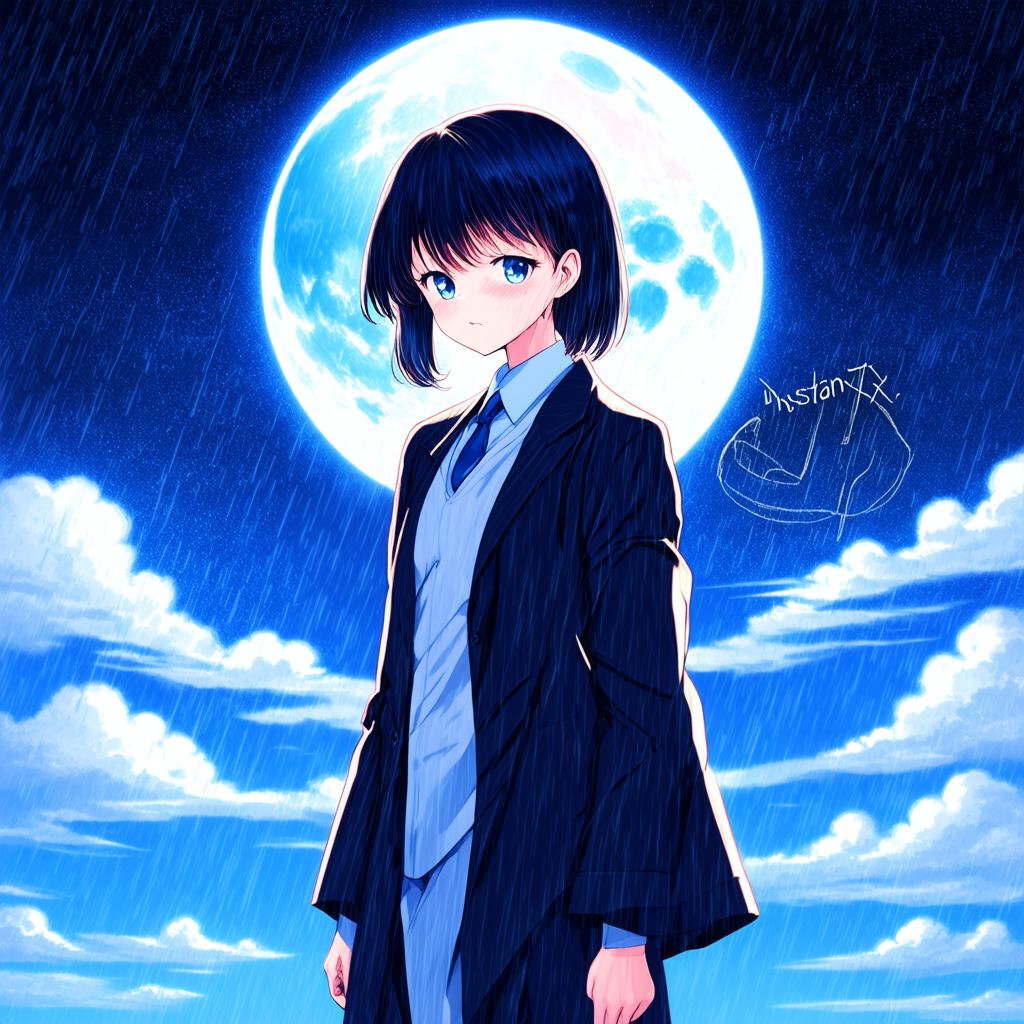
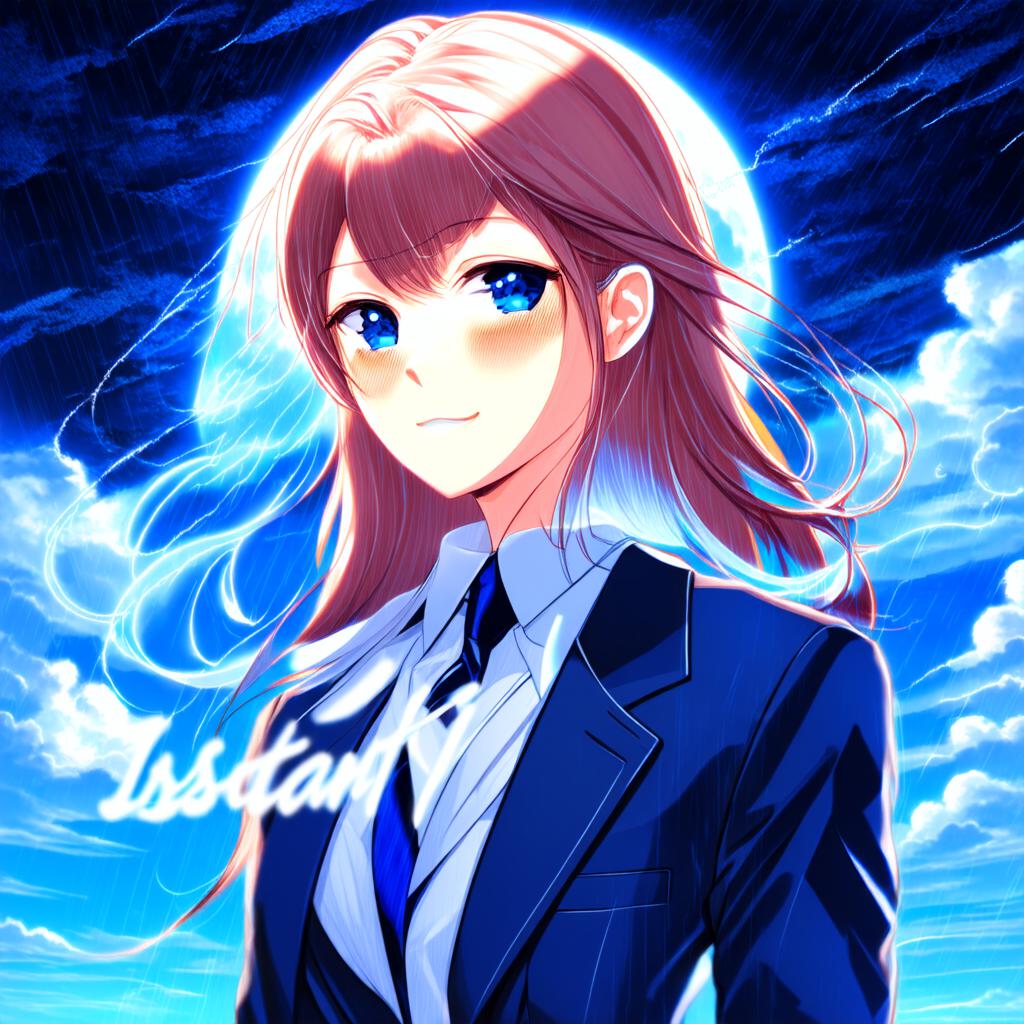
Here are examples of outputs with different weights applied to the control image:

Control Image Weight=0.0 Weight=0.3 Weight=0.5 Weight=0.7 Weight=0.9
Control Image Weight 0.0 Weight 0.3 Weight 0.5 Weight 0.7 Weight 0.9
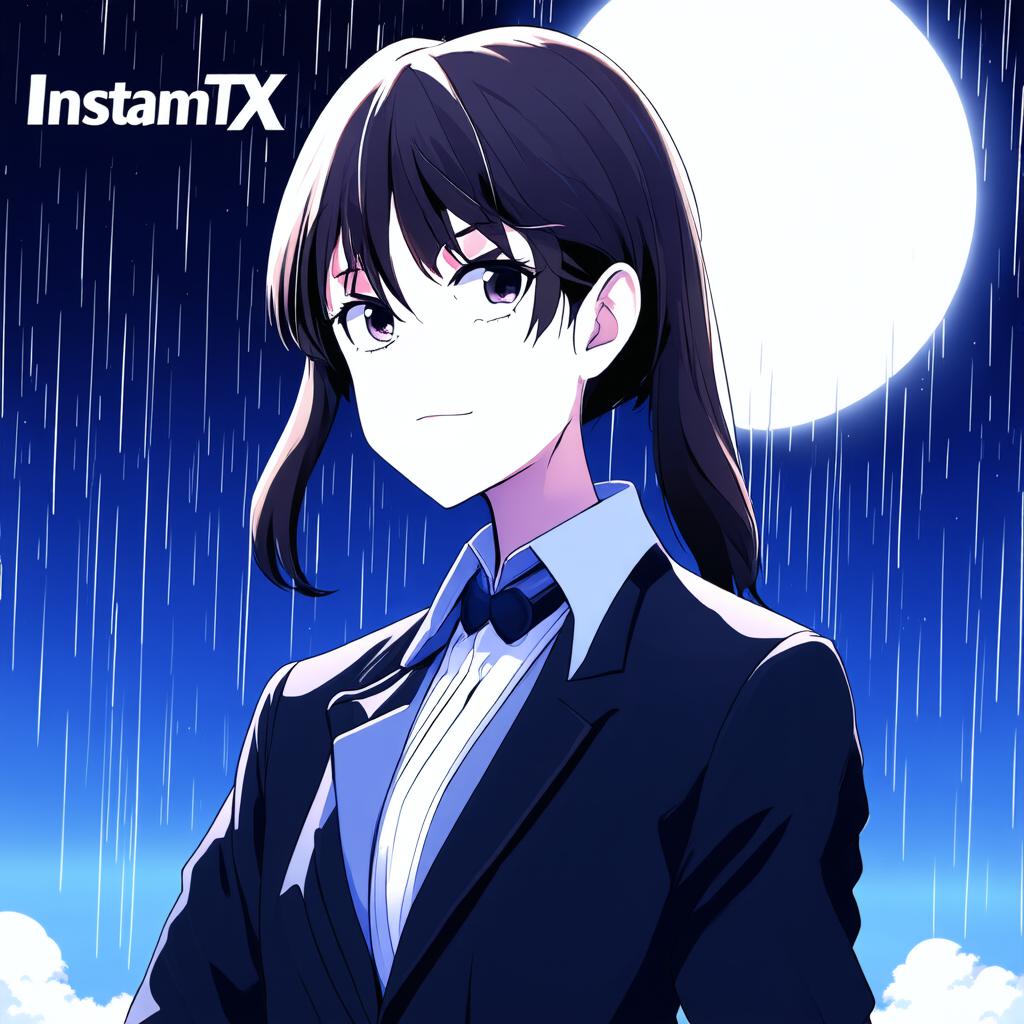
Pose
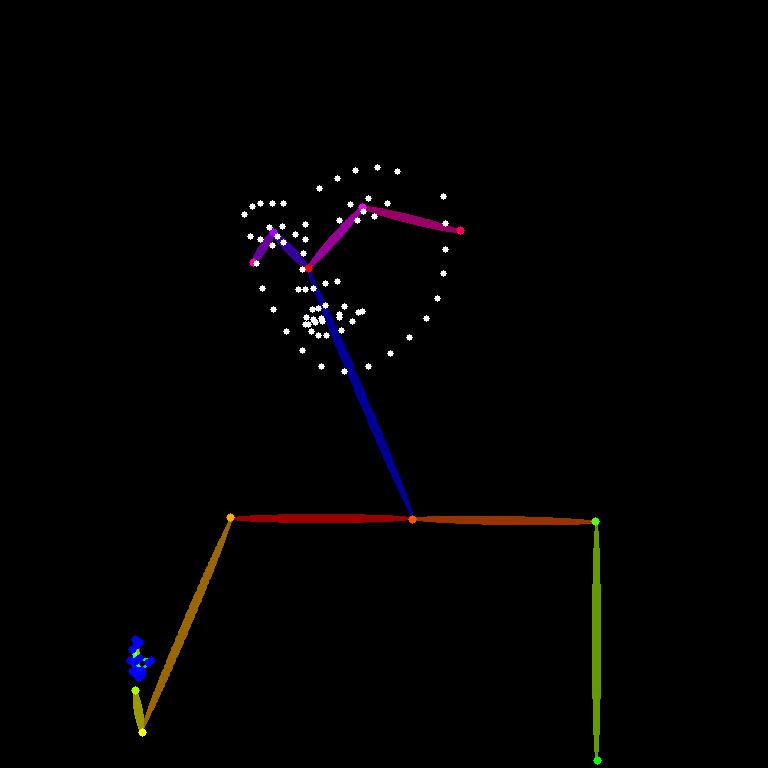
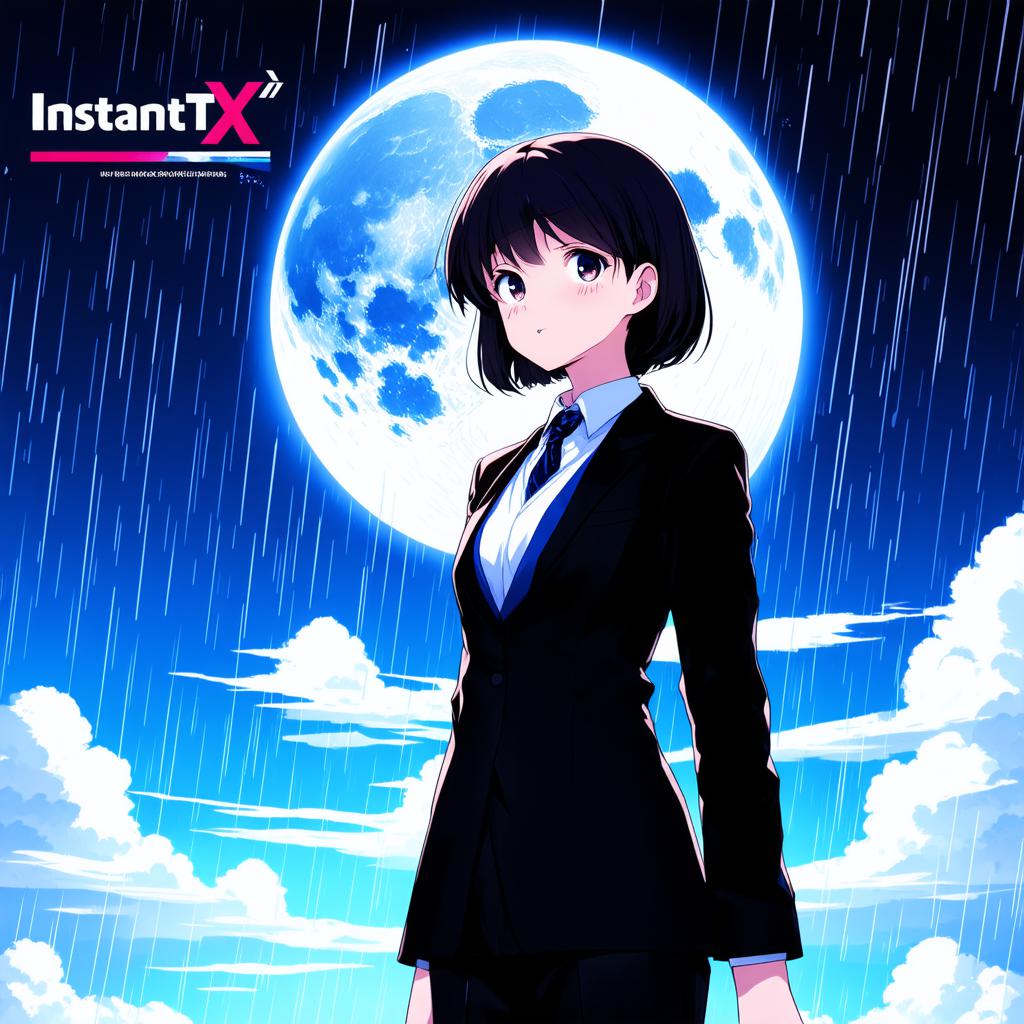
Control Image Weight=0.0 Weight=0.3 Weight=0.5 Weight=0.7 Weight=0.9
Control Image Weight 0.0 Weight 0.3 Weight 0.5 Weight 0.7 Weight 0.9
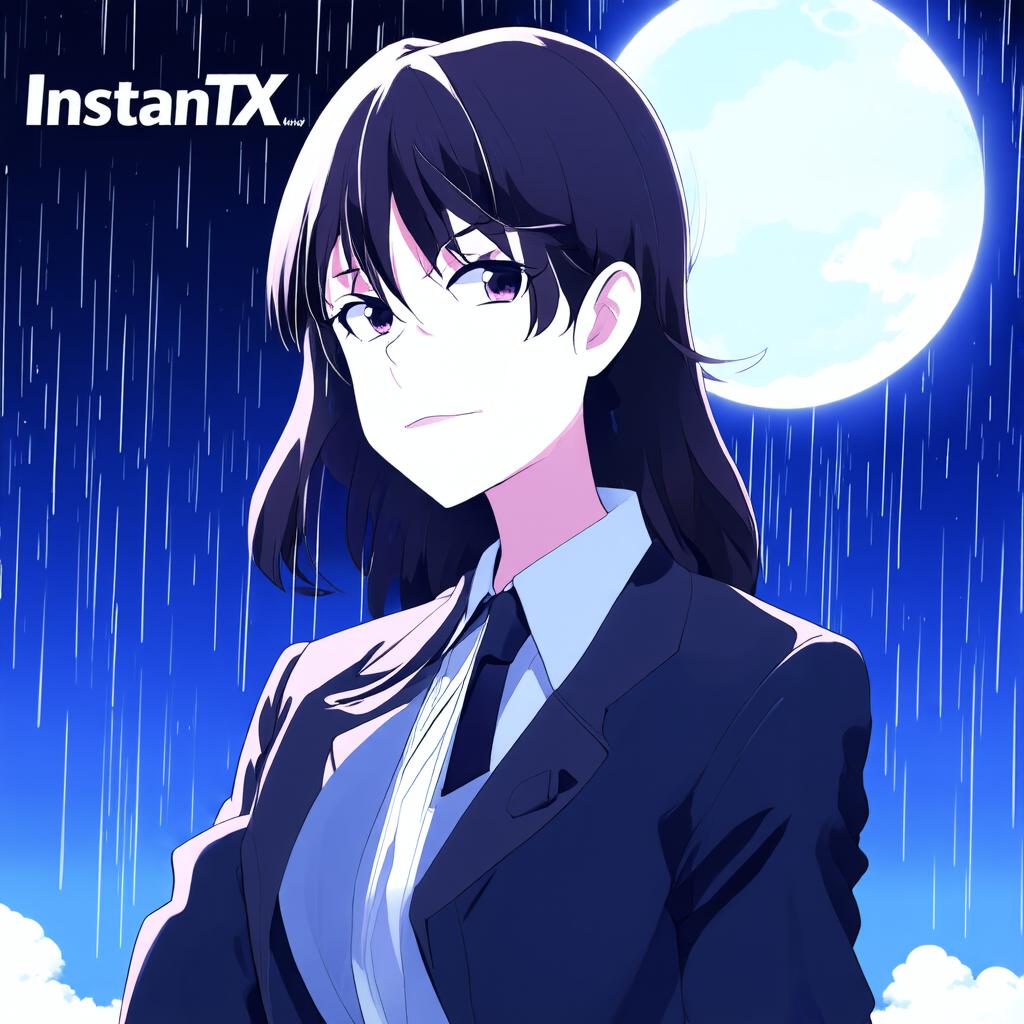
Canny
Control Image Weight=0.0 Weight=0.3 Weight=0.5 Weight=0.7 Weight=0.9
Control Image Weight 0.0 Weight 0.3 Weight 0.5 Weight 0.7 Weight 0.9
Limitations

Due to the fact that only 1024x1024 pixel resolution was used during the training phase, the inference performs best at this size, with other sizes yielding suboptimal results. We will initiate multi-resolution training in the future, and at that time, we will open-source the new weights.

Stable Diffusion 3 Medium is a 2 billion parameter text-to-image model developed by Stability AI . It excels at photorealism, typography, and prompt following.

Stable Diffusion 3 on Replicate can be used for commercial work.

Core Model
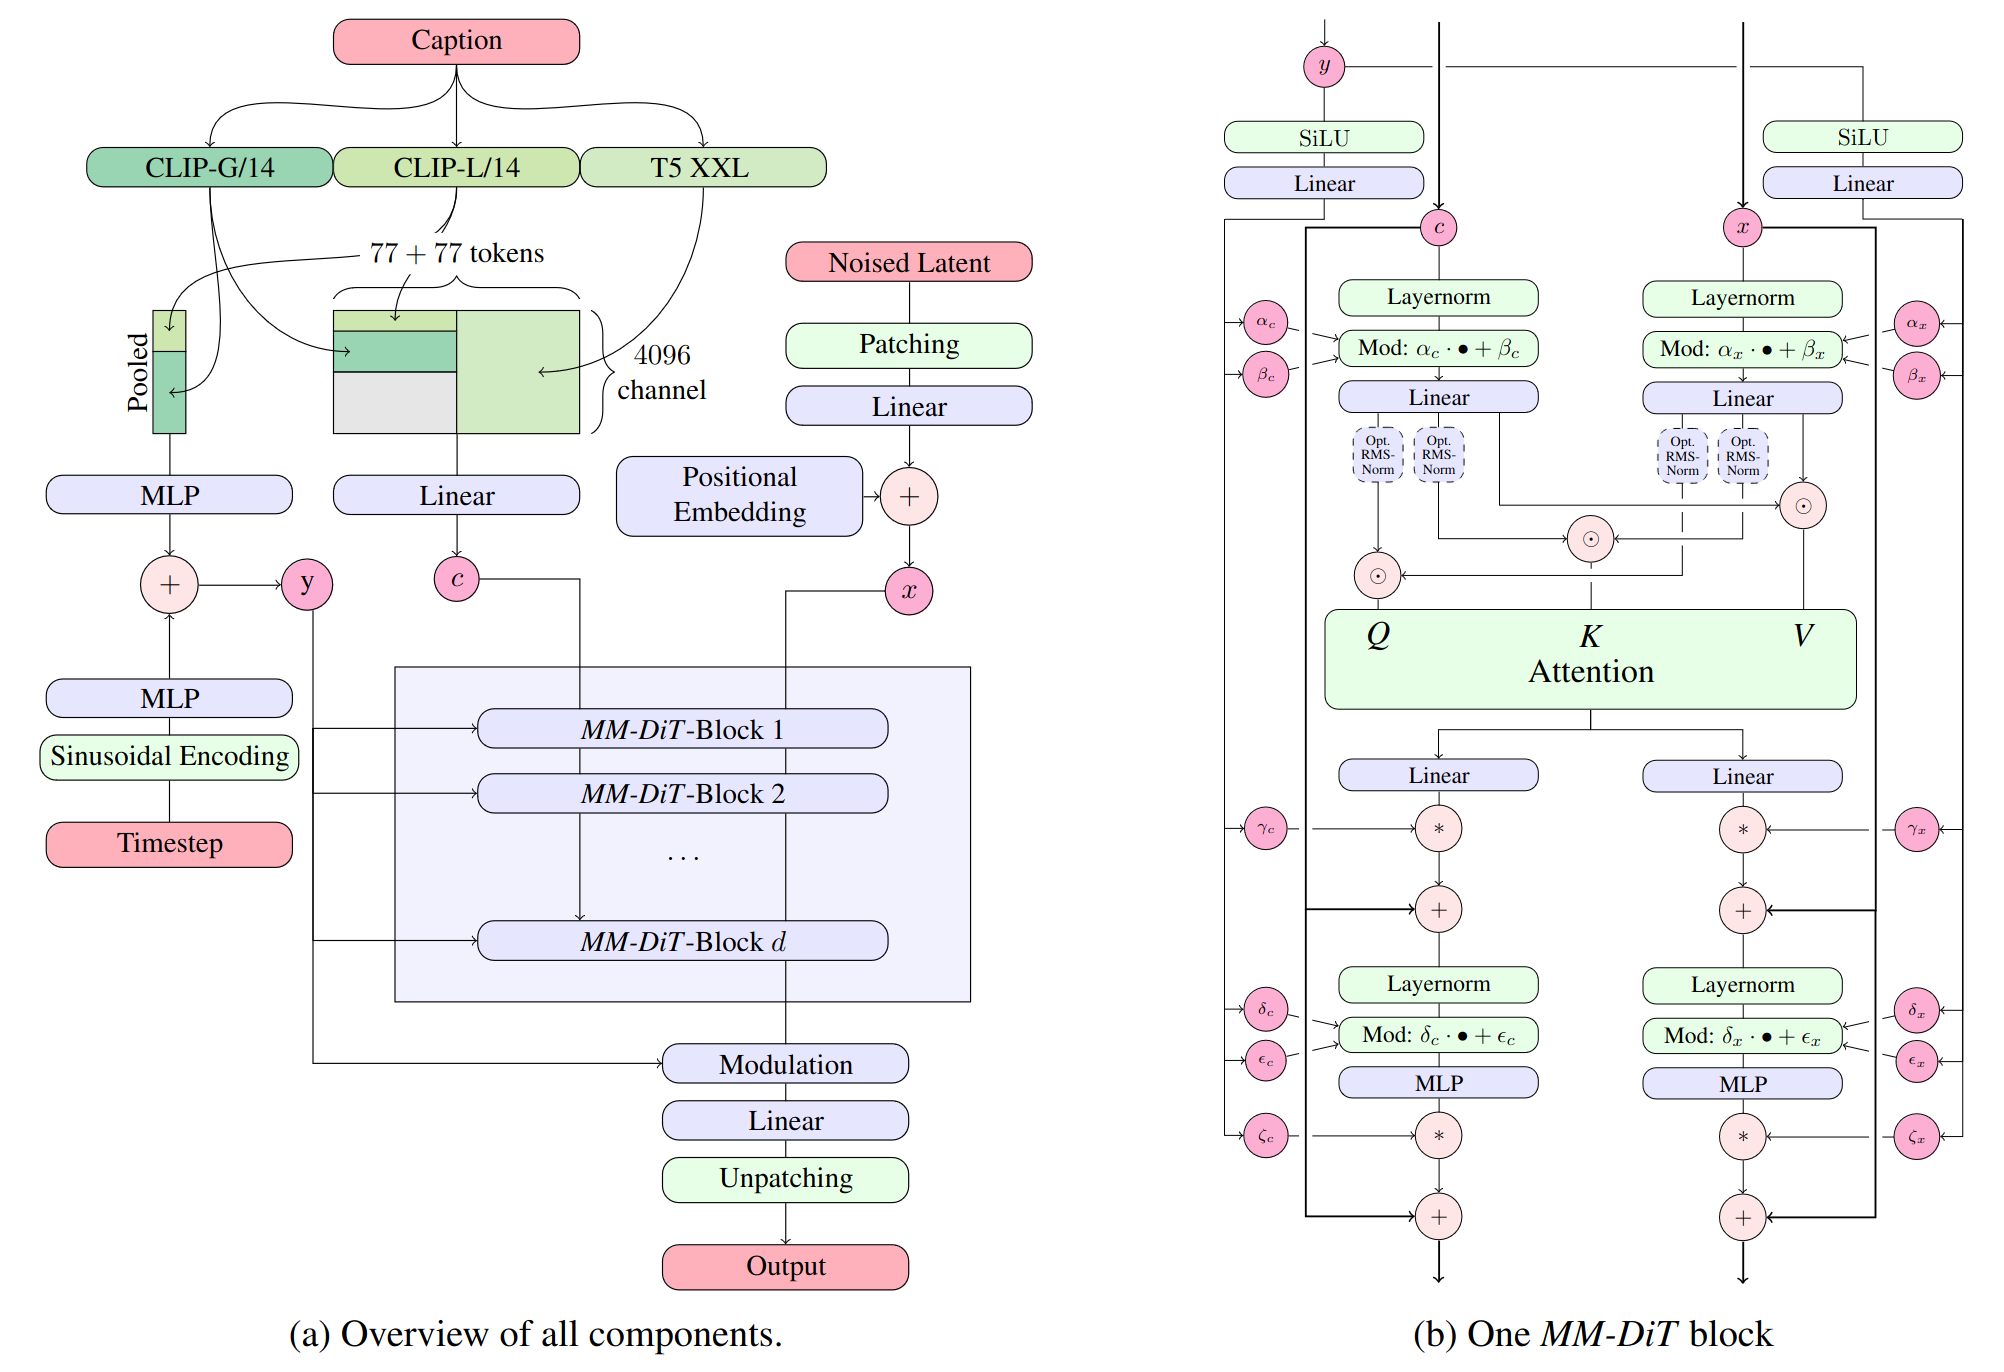
Architecture diagram

Stable Diffusion 3 Medium is a Multimodal Diffusion Transformer (MMDiT) text-to-image model that features greatly improved performance in image quality, typography, complex prompt understanding, and resource-efficiency.

For more technical details, please refer to the Research paper .

Safety

As part of our safety-by-design and responsible AI deployment approach, Stability AI implement safety measures throughout the development of our models, from the time we begin pre-training a model to the ongoing development, fine-tuning, and deployment of each model. We have implemented a number of safety mitigations that are intended to reduce the risk of severe harms, however we recommend that developers conduct their own testing and apply additional mitigations based on their specific use cases.

For more about our approach to Safety, please visit our Safety page .

Support

All credit goes to the InstantX team Give me a follow on Twitter if you like my work! @zsakib_
Pricing of sd3-controlnet replicate.com

Run time and cost

This model costs approximately $0.080 to run on Replicate, or 12 runs per $1, but this varies depending on your inputs. It is also open source and you can run it on your own computer with Docker .

This model runs on Nvidia A40 (Large) GPU hardware . Predictions typically complete within 111 seconds. The predict time for this model varies significantly based on the inputs.

Runs of zsxkib sd3-controlnet on replicate.com

1.2K
Total runs
0
24-hour runs
0
3-day runs
0
7-day runs
0
30-day runs

More Information About sd3-controlnet replicate.com Model

sd3-controlnet replicate.com

sd3-controlnet replicate.com is an AI model on replicate.com that provides sd3-controlnet's model effect (✨Stable Diffusion 3 w/ ⚡InstantX's Canny, Pose, and Tile ControlNets🖼️), which can be used instantly with this zsxkib sd3-controlnet model. replicate.com supports a free trial of the sd3-controlnet model, and also provides paid use of the sd3-controlnet. Support call sd3-controlnet model through api, including Node.js, Python, http.

sd3-controlnet replicate.com Url

https://replicate.com/zsxkib/sd3-controlnet

zsxkib sd3-controlnet online free

sd3-controlnet replicate.com is an online trial and call api platform, which integrates sd3-controlnet's modeling effects, including api services, and provides a free online trial of sd3-controlnet, you can try sd3-controlnet online for free by clicking the link below.

zsxkib sd3-controlnet online free url in replicate.com:

https://replicate.com/zsxkib/sd3-controlnet

sd3-controlnet install

sd3-controlnet is an open source model from GitHub that offers a free installation service, and any user can find sd3-controlnet on GitHub to install. At the same time, replicate.com provides the effect of sd3-controlnet install, users can directly use sd3-controlnet installed effect in replicate.com for debugging and trial. It also supports api for free installation.

sd3-controlnet install url in replicate.com:

https://replicate.com/zsxkib/sd3-controlnet

Url of sd3-controlnet

Provider of sd3-controlnet replicate.com

Other API from zsxkib

replicate

Blip 3 / XGen-MM, Answers questions about images ({blip3,xgen-mm}-phi3-mini-base-r-v1)

Total runs: 1.2M
Run Growth: 0
Growth Rate: 0.00%
Updated:May 13 2024
replicate

📖 PuLID: Pure and Lightning ID Customization via Contrastive Alignment

Total runs: 1.2M
Run Growth: 0
Growth Rate: 0.00%
Updated:May 16 2024
replicate

Make realistic images of real people instantly

Total runs: 848.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:December 11 2024
replicate

Create song covers with any RVC v2 trained AI voice from audio files.

Total runs: 637.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 16 2023
replicate

⚡️FLUX PuLID: FLUX-dev based Pure and Lightning ID Customization via Contrastive Alignment🎭

Total runs: 601.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 16 2024
replicate

🎨 Fill in masked parts of images with FLUX.1-dev 🖌️

Total runs: 349.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 20 2024
replicate

Add sound to video using the MMAudio V2 model. An advanced AI model that synthesizes high-quality audio from video content, enabling seamless video-to-audio transformation.

Total runs: 283.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:April 02 2025
replicate

✍️✨Prompts to auto-magically relights your images

Total runs: 207.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:May 21 2024
replicate

Age prediction using CLIP - Patched version of `https://replicate.com/andreasjansson/clip-age-predictor` that works with the new version of cog!

Total runs: 189.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 07 2023
replicate

✨DiffBIR: Towards Blind Image Restoration with Generative Diffusion Prior

Total runs: 132.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 12 2023
replicate

allenai/Molmo-7B-D-0924, Answers questions and caption about images

Total runs: 88.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 27 2024
replicate

Jina-CLIP v2: 0.9B multimodal embedding model with 89-language multilingual support, 512x512 image resolution, and Matryoshka representations

Total runs: 76.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 28 2024
replicate

🎨 AnimateDiff (w/ MotionLoRAs for Panning, Zooming, etc): Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning

Total runs: 56.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 06 2023
replicate

📽️ Increase Framerate 🎬 ST-MFNet: A Spatio-Temporal Multi-Flow Network for Frame Interpolation

Total runs: 51.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 09 2023
replicate

Hunyuan-Video LoRA Explorer + Trainer

Total runs: 31.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:January 25 2025
replicate

Monster Labs' Controlnet QR Code Monster v2 For SD-1.5 on top of AnimateDiff Prompt Travel (Motion Module SD 1.5 v2)

Total runs: 10.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 01 2023
replicate

🖼️✨Background images + prompts to auto-magically relights your images (+normal maps🗺️)

Total runs: 10.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:May 21 2024
replicate

Real-Time Open-Vocabulary Object Detection

Total runs: 9.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:February 12 2024
replicate

AuraSR v2: Second-gen GAN-based Super-Resolution for real-world applications

Total runs: 9.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 01 2024
replicate

Create your own Realistic Voice Cloning (RVC v2) dataset using a YouTube link

Total runs: 8.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 21 2023
replicate

Text-to-Video + Image-to-Video: Pyramid Flow Autoregressive Video Generation method based on Flow Matching

Total runs: 8.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 11 2024
replicate

🎨 Fill in masked parts of images with FLUX.1-schnell 🖌️

Total runs: 6.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 16 2024
replicate

🎨AnimateDiff Prompt Travel🧭 Seamlessly Navigate and Animate Between Text-to-Image Prompts for Dynamic Visual Narratives

Total runs: 5.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 19 2023
replicate

FlashFace: Human Image Personalization with High-fidelity Identity Preservation

Total runs: 4.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:April 23 2024
replicate

Make realistic images of real people instantly (w/ ip-adapter-plus-face_sdxl_vit-h)

Total runs: 3.8K
Run Growth: 0
Growth Rate: 0.00%
Updated:July 15 2024
replicate

Upscale videos + images with BSRGAN

Total runs: 2.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:January 29 2025
replicate

Transform your portrait photos into any style or setting while preserving your facial identity

Total runs: 2.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:April 03 2025
replicate

MimicMotion: High-quality human motion video generation with pose-guided control

Total runs: 2.4K
Run Growth: 0
Growth Rate: 0.00%
Updated:July 16 2024
replicate

AuraSR: GAN-based Super-Resolution for real-world

Total runs: 2.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 28 2024
replicate

🖼️ Super fast 1.5B Image Captioning/VQA Multimodal LLM (Image-to-Text) 🖋️

Total runs: 2.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:February 02 2024
replicate

Idefics3-8B-Llama3, Answers questions and caption about images

Total runs: 2.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 15 2024
replicate

Qwen 2: A 7 billion parameter language model from Alibaba Cloud, fine tuned for chat completions

Total runs: 1.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 26 2024
replicate

A state-of-the-art text-to-video generation model capable of creating high-quality videos with realistic motion from text descriptions

Total runs: 1.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:December 11 2024
replicate

Cubiq's ComfyUI InstantID node running `instantid_basic.json` example

Total runs: 1.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:August 20 2024
replicate

🎼FluxMusic Text-to-Music Generation with Rectified Flow Transformer🎶

Total runs: 1.3K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 26 2024
replicate

Image tagger fine-tuned on WaifuDiffusion w/ (SwinV2, SwinV2, ConvNext, and ViT)

Total runs: 1000
Run Growth: 0
Growth Rate: 0.00%
Updated:May 22 2024
replicate

🫦 Realistic facial expression manipulation (lip-syncing) using audio or video

Total runs: 1000
Run Growth: 0
Growth Rate: 0.00%
Updated:June 12 2024
replicate

Unofficial Re-Trained AnimateAnyone (Image + DWPose Video → Animated Video of Image)

Total runs: 853
Run Growth: 0
Growth Rate: 0.00%
Updated:January 19 2024
replicate

🎙️Hololive text-to-speech and voice-to-voice (Japanese🇯🇵 + English🇬🇧)

Total runs: 850
Run Growth: 0
Growth Rate: 0.00%
Updated:June 04 2024
replicate

MEMO is a state-of-the-art open-weight model for audio-driven talking video generation.

Total runs: 678
Run Growth: 0
Growth Rate: 0.00%
Updated:December 11 2024
replicate

🐲 DragGAN 🐉 - "Drag Your GAN: Interactive Point-based Manipulation on the Generative Image Manifold"

Total runs: 583
Run Growth: 0
Growth Rate: 0.00%
Updated:July 07 2023
replicate

Easily create video datasets with auto-captioning for Hunyuan-Video LoRA finetuning

Total runs: 532
Run Growth: 0
Growth Rate: 0.00%
Updated:April 02 2025
replicate

Surrealist digital art featuring whimsical, anthropomorphic characters with exaggerated textures and vibrant color blocking

Total runs: 480
Run Growth: 0
Growth Rate: 0.00%
Updated:October 09 2024
replicate

Transform your text into a beautiful two-tone color gradient that represents your emotions.

Total runs: 417
Run Growth: 0
Growth Rate: 0.00%
Updated:June 06 2023
replicate

STAR Video Upscaler: Spatial-Temporal Augmentation with Text-to-Video Models for Real-World Video Super-Resolution

Total runs: 382
Run Growth: 0
Growth Rate: 0.00%
Updated:February 01 2025
replicate

Super High Quality Depth Maps 🗺️: An End-to-End Tile-Based Framework 🏗️ for High-Resolution Monocular Metric Depth Estimation 🔍📏

Total runs: 362
Run Growth: 0
Growth Rate: 0.00%
Updated:December 27 2023
replicate

Qwen 2: A 1.5 billion parameter language model from Alibaba Cloud, fine tuned for chat completions

Total runs: 207
Run Growth: 0
Growth Rate: 0.00%
Updated:June 26 2024
replicate

Qwen 2: A 0.5 billion parameter language model from Alibaba Cloud, fine tuned for chat completions

Total runs: 198
Run Growth: 0
Growth Rate: 0.00%
Updated:June 25 2024
replicate

Generates realistic talking face animations from a portrait image and audio using the CVPR 2025 Sonic model

Total runs: 148
Run Growth: 0
Growth Rate: 0.00%
Updated:April 03 2025
replicate

Powerful text-to-video model that generates high-quality videos up to 6 seconds at 15 FPS and 720p resolution from simple text prompt

Total runs: 128
Run Growth: 0
Growth Rate: 0.00%
Updated:October 23 2024
replicate

Convert speech in audio to text w/ `tiny`, `small`, `base`, and `large-v3` models

Total runs: 126
Run Growth: 0
Growth Rate: 0.00%
Updated:July 02 2024
replicate

SAMURAI: Adapting Segment Anything Model for Zero-Shot Visual Tracking with Motion-Aware Memory

Total runs: 100
Run Growth: 0
Growth Rate: 0.00%
Updated:November 28 2024
replicate

Generate high-quality videos from text prompts using StepVideo

Total runs: 93
Run Growth: 0
Growth Rate: 0.00%
Updated:February 25 2025
replicate

🗣️ TalkNet-ASD: Detect who is speaking in a video

Total runs: 92
Run Growth: 0
Growth Rate: 0.00%
Updated:May 02 2024
replicate

A "Hello World" model for me to get to grips with `cog` and Replicate

Total runs: 44
Run Growth: 0
Growth Rate: 0.00%
Updated:June 06 2023
replicate

Cost-optimized MMAudio V2 (T4 GPU): Add sound to video using this version running on T4 hardware for lower cost. Synthesizes high-quality audio from video content.

Total runs: 21
Run Growth: 0
Growth Rate: 0.00%
Updated:April 02 2025
replicate

SAM 2: Segment Anything v2 (for in Images + Videos)

Total runs: 19
Run Growth: 0
Growth Rate: 0.00%
Updated:July 31 2024
replicate

Hibiki: High-Fidelity Simultaneous Speech-To-Speech Translation

Total runs: 12
Run Growth: 0
Growth Rate: 0.00%
Updated:February 11 2025
replicate

Remove background from images using BRIA-RMBG-2.0

Total runs: 2
Run Growth: 0
Growth Rate: 0.00%
Updated:November 25 2024