






Table of Contents
- Key Points
- Unlocking Text from Images: An Introduction to OCR
- Project Overview: Python, Django, and MySQL Implementation
- How to use the Image to Text Reader
- Accessing the Project: Free Resources and Potential Costs
- Advantages and Disadvantages of OCR Reader
- Related Questions



Unlocking Text from Images: An Introduction to OCR
What is Optical Character Recognition (OCR)?
Optical Character Recognition (OCR) is the technology that enables computers to recognize text within digital images, scanned documents, and other image-based files.
It effectively converts different types of documents, such as scanned paper documents, PDF files or images captured by a digital camera, into editable and searchable data. Imagine being able to take a photo of a handwritten note and convert it into a text document you can edit – that’s the power of OCR.
OCR's Evolution & Impact
From its early days focused on simple character recognition, OCR has evolved dramatically. Advanced OCR systems now leverage artificial intelligence and machine learning to handle various fonts, languages, and even Handwriting with incredible accuracy. This technological leap has had a profound impact on numerous industries.
Key SEO Keywords: Image to Text, OCR, Optical Character Recognition, Text Extraction, Image Conversion
OCR has transformed industries like:
- Healthcare: Converting medical records into digital formats.
- Finance: Automating data entry from invoices and financial statements.
- Legal: Digitizing legal documents for efficient search and retrieval.
- Education: Making textbooks and research Papers accessible through digital transformation.
The Basic Process
At its core, the OCR process involves a series of steps:
- Image Acquisition: The image is captured from a source, either by scanning or digital camera.
- Preprocessing: The image undergoes several enhancements like noise reduction, deskewing (correcting image tilt), and contrast adjustment.
- Segmentation: The image is divided into individual characters.
- Feature Extraction: Key features of each character are extracted, such as lines, curves, and intersections.
- Character Recognition: Machine learning algorithms compare these features against a database of known characters.
- Post-processing: Corrections are made based on context, and the recognized text is formatted.
Advanced OCR techniques uses Machine Learning
Modern OCR engines make great use of Machine Learning (ML), especially Deep Learning. By training models on a bunch of sample images, they get smarter over time and are much better at spotting different fonts, styles, and writing. Using ML to power OCR has greatly reduced errors and has improved output reliability.
Project Overview: Python, Django, and MySQL Implementation
Technical Architecture and Key Components
This project offers a practical illustration of how to integrate OCR technology into a web application. Developed using Python, Django, and MySQL, it creates a robust framework for image-to-text conversion.
Key Technologies Used
- Python:
The backbone of the project, providing a versatile programming language for handling image processing and machine learning tasks.
- Django: A high-level Python web framework used for building the web interface and managing user interactions.
- MySQL: A relational database management system used for storing user data, file metadata, and potentially the extracted text itself.
-
jQuery, JavaScript, HTML, CSS: Used for constructing the front-end of the web application to enable a responsive user experience.
Machine Learning Libraries
To read text from images, machine learning is used. This project most likely takes advantage of libraries such as Tesseract OCR (through its Python wrapper, pytesseract) and OpenCV.
- Tesseract OCR: an open-source OCR engine that converts images to text, and is easy to use and has been around for a long time.
- OpenCV: OpenCV is used to preprocess the images in a way that allows Tesseract OCR to work properly and increase its speed and accuracy.
Libraries and Versions:
| Library | Version | Purpose |
|---|---|---|
| Python | 3.7 | Core programming language |
| Django | 2 | Web framework |
| MySQL Connector Python | N/A | Connect Python to MySQL |
| HTML, CSS, jQuery,JavaScript | Latest | Front-end, web design, Client-side scripting |
The presenter will most likely mention more information about using these dependencies as the content of the project is introduced.
The video presenter also states at that he will provide 'requirements.txt' file for listing all of the dependencies used to build the project so that developers know what libraries will be needed to recreate it.
How to use the Image to Text Reader
Uploading and Processing Images
The primary function of this image to text conversion program, OCR reader, is to take an image and Translate all text in the picture into readable, copy/paste text. The process is Simplified as:
- Admin Login: Access the system via the admin login page.
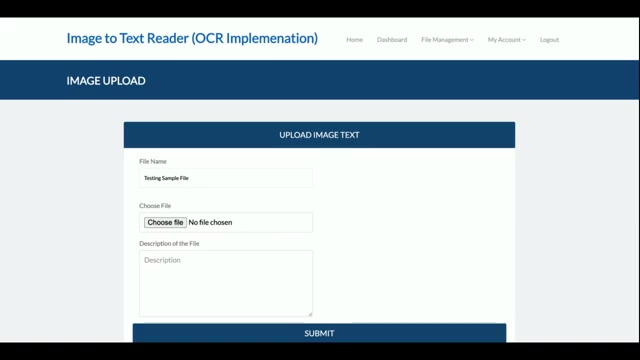
Enter credentials to gain access to the administrative dashboard.
- Image Upload: Navigate to the 'Upload Files' section. This is where the image upload process begins.
- File Naming and Description: Provide a descriptive name for the image. Add any Relevant details in the description box.
- File Selection: Use the 'Choose File' option to select the image you want to process.
-
Submit: Once selected, press the 'Submit' button.
Once you've pressed the button, then the program will take the image and process it by converting text to copy/paste format.







Most people like






























Report
Please select a reason for reporting
- 13 Reasons to Switch from Snapchat to Text Messaging
- 7 Powerful Speech to Text Apps to Boost Productivity
- 10 Best Speech to Text Tools for Effortless Transcription
- 13 Free Tools to Easily Transcribe Audio to Text
- 15 Surprising Ways Google's Speech-to-Text Boosts Productivity
- 7 Best Free Online Audio to Text Transcription Tools
- 9 Tips to Transcribe Speech to Text Faster and Better
- 13 Best Speech to Text Software for Windows 10 in 2023
- 7 Tips for Choosing the Best Transcriber for Audio to Text
- 11 Reasons Why Dragon Speech-to-Text Apps are Game-Changers
- 6 Secrets to Enhance Your Speech to Text Transcription
- 6 Brilliant Ways to Boost Productivity with Talk-to-Text on Your MacBook
- 6 Ways Transcription Software Converts Audio to Text
- 8 Tips to Transcribe Speech to Text Like a Pro
- 6 Reasons IBM Watson Speech to Text is a Game-Changer
- 14 Powerful Ways Talk-to-Text Improves Your Workflow
- 12 Top Windows Speech-to-Text Software for Efficient Transcription
- 12 Game-Changing Benefits of Apple's Speech to Text Technology
- 9 Powerful Use Cases for AWS Speech to Text Technology
- 10 Easy Steps to Transcribe YouTube Videos to Text
- transcription audio en texte
- online audio transcription
- free audio file transcription
- free ai audio transcription
- audio transcription service
- audio transcription online free
- audio transcription free online
- audio to transcription software
- audio and transcript
- ai audio transcription free
- voice recording to text converter
- translate voice recording to text
- record voice to text
- audio recording to text converter
- voice recording and transcription
- chatgpt voice to text
- gmail voice to text
- speech to text reader
- speech to text ai free
- speech to talk
- How SEO and Marketing Dashboards Empower Agencies to Drive Results
- How to Use AI Tools to Find Internal Linking Opportunities Across a Business Website
- Discover Your Perfect Haircut with AI Hairstyle Apps
- Free Reputation Calculator Tools: How They're Adapting to Score AI Visibility, Not Just Rankings
- Design Professional Flyers for Free on Your Phone
- Best Free Flyer Maker Apps for Android: Design Like a Pro
- How to Know If Your Business Is Ready for an AI Customer Service Agent
- Revolutionizing Storytelling: From Novels to Screenplays with AI
- Create Engaging Animated Explainer Videos with a Free AI Tool
- Stop Multi-Subscribing: Benchmark Top AI Visual Models in One Canvas
- ASOMobile Helps Teams Benchmark App Store Screenshots Against Competitors
- How to Match LMS Software With Your Organization's Training Plan
- Revolutionizing Email Marketing Agency with AI
- How to Convert BTC to HNT
- Unleashing the Power of AI: Cognizant's Roadmap for Transformation
- Frame to Video Review: A Practical Look at Turning Two Still Frames Into Motion
- NVIDIA NIM: Revolutionizing Supply Chain Data Analysis with AI
- Top AI Tools That Help Brands Stand Out Offline (Not Just Online)
- Top 5 Cold Email Software: Maximize Your Outreach in 2025
- Magic School AI: Revolutionizing Quiz & Assessment Generation

Copyright ©2026 toolify