






Table of Contents
- Key Points
- What is Statistical Power?
- Factors Affecting Statistical Power
- Calculating Statistical Power: A Practical Overview
- Weighing the Trade-offs: Pros and Cons of Increasing Power
- Frequently Asked Questions about Statistical Power
- Further Exploration: Related Questions on Significance Testing


What is Statistical Power?
Defining Statistical Power
Statistical power, in the context of hypothesis testing, is the probability that a test will correctly reject the null hypothesis when it is, in fact, false. It essentially quantifies the ability of a study to detect a real effect if that effect exists. Power is often expressed as a value between 0 and 1, where a higher value indicates greater power.
Formally, it's defined as the probability of avoiding a Type II error. A Type II error occurs when the null hypothesis is false, but the test fails to reject it. In other words, the study misses a real effect.
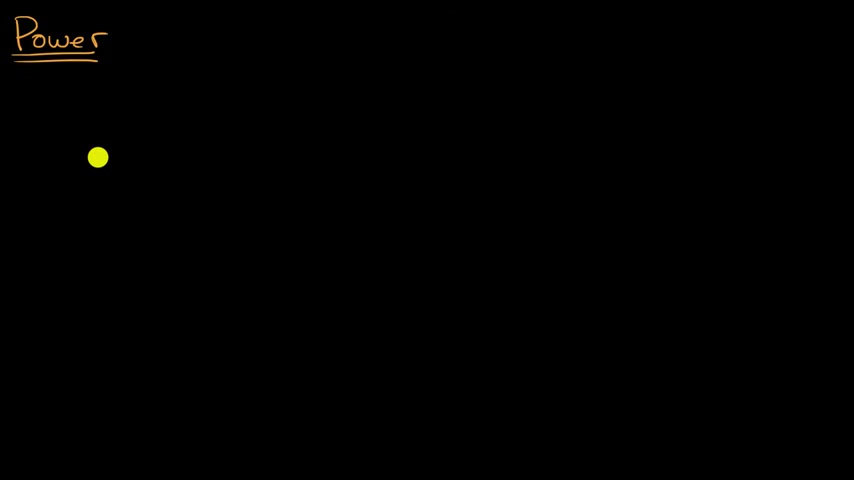
Power is a probability and can be viewed as the probability of doing the right thing when the null hypothesis is not true. In this context, doing the right thing is rejecting the null hypothesis.
Mathematically, power can be expressed as:
Power = P(reject H₀ | H₀ is false)
Where:
- P(reject H₀ | H₀ is false) represents the probability of rejecting the null hypothesis given that the null hypothesis is actually false.
To fully understand power, it's essential to grasp its connection to other key concepts in hypothesis testing, especially Type I and Type II errors.
Power and Type II Errors
The concept of statistical power is intimately linked to Type II errors. A Type II error, also known as a false negative, occurs when a statistical test fails to reject a null hypothesis that is actually false. In other words, you miss detecting a real effect.
The relationship between power and Type II error is inverse. The probability of making a Type II error is often denoted as β. Statistical power is then expressed as:
Power = 1 - β
This means that the higher the power, the lower the probability of a Type II error, and vice versa. A study with a power of 0.8 (or 80%) has a 20% chance of committing a Type II error.
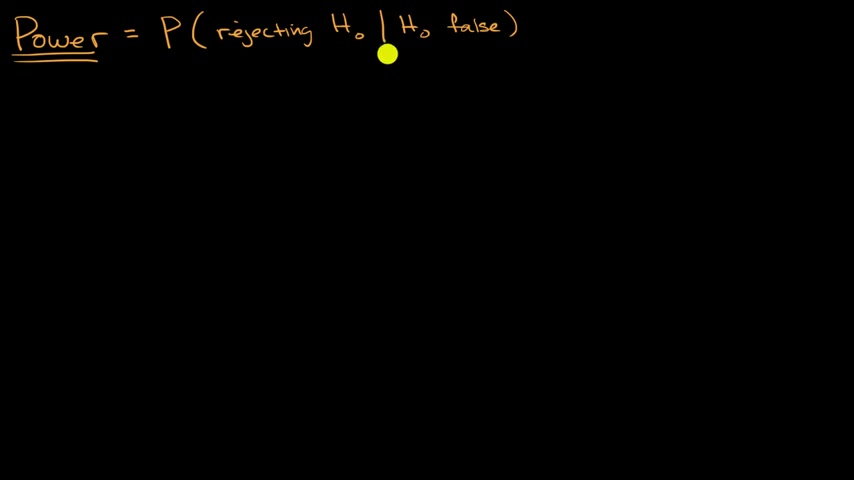
Power is one minus the probability of not rejecting the null hypothesis given that the null hypothesis is false. This is the definition of a Type II error.
Understanding this inverse relationship is critical. When designing research, scientists aim for high power to minimize the risk of overlooking a genuine effect. This is because failing to detect a real effect can have serious consequences, depending on the field of study. For example, in drug development, missing a potentially life-saving medication could have dire implications.
The Importance of Statistical Power
Understanding and striving for adequate statistical power is of utmost importance in research. Here’s why:
- Validating Research Findings: High power lends credibility to research findings. It assures that if an effect is found, it's less likely to be a result of chance variation.
- Reducing False Negatives: Adequate power reduces the risk of overlooking genuine effects. This is especially critical in areas where identifying true effects can have significant practical consequences.
- Ethical Considerations: Conducting underpowered studies can be viewed as unethical. Resources, time, and potentially participant well-being are used without a reasonable chance of detecting a real effect.
- Reproducibility: Studies with sufficient power are more likely to yield reproducible results, strengthening the scientific literature.
- Informed Decision-Making: Statistical power informs decisions on sample size, significance level, and other design elements. This ensures the study is optimized to answer the research question effectively.
Researchers should always strive for a sufficient level of power, typically aiming for 80% or higher, to enhance the reliability and validity of their findings.





Most people like


































Report
Please select a reason for reporting
- 13 Reasons to Switch from Snapchat to Text Messaging
- 7 Powerful Speech to Text Apps to Boost Productivity
- 10 Best Speech to Text Tools for Effortless Transcription
- 13 Free Tools to Easily Transcribe Audio to Text
- 15 Surprising Ways Google's Speech-to-Text Boosts Productivity
- 7 Best Free Online Audio to Text Transcription Tools
- 9 Tips to Transcribe Speech to Text Faster and Better
- 13 Best Speech to Text Software for Windows 10 in 2023
- 7 Tips for Choosing the Best Transcriber for Audio to Text
- 11 Reasons Why Dragon Speech-to-Text Apps are Game-Changers
- 6 Secrets to Enhance Your Speech to Text Transcription
- 6 Brilliant Ways to Boost Productivity with Talk-to-Text on Your MacBook
- 6 Ways Transcription Software Converts Audio to Text
- 8 Tips to Transcribe Speech to Text Like a Pro
- 6 Reasons IBM Watson Speech to Text is a Game-Changer
- 14 Powerful Ways Talk-to-Text Improves Your Workflow
- 12 Top Windows Speech-to-Text Software for Efficient Transcription
- 12 Game-Changing Benefits of Apple's Speech to Text Technology
- 9 Powerful Use Cases for AWS Speech to Text Technology
- 10 Easy Steps to Transcribe YouTube Videos to Text
- transcription audio en texte
- online audio transcription
- free audio file transcription
- free ai audio transcription
- audio transcription service
- audio transcription online free
- audio transcription free online
- audio to transcription software
- audio and transcript
- ai audio transcription free
- voice recording to text converter
- translate voice recording to text
- record voice to text
- audio recording to text converter
- voice recording and transcription
- chatgpt voice to text
- gmail voice to text
- speech to text reader
- speech to text ai free
- speech to talk
- Meshy AI: How to Create 3D Models from Text and Images
- How SEO and Marketing Dashboards Empower Agencies to Drive Results
- How to Use AI Tools to Find Internal Linking Opportunities Across a Business Website
- Discover Your Perfect Haircut with AI Hairstyle Apps
- Free Reputation Calculator Tools: How They're Adapting to Score AI Visibility, Not Just Rankings
- Design Professional Flyers for Free on Your Phone
- Best Free Flyer Maker Apps for Android: Design Like a Pro
- How to Know If Your Business Is Ready for an AI Customer Service Agent
- Revolutionizing Storytelling: From Novels to Screenplays with AI
- Create Engaging Animated Explainer Videos with a Free AI Tool
- Meshy AI: How to Create 3D Models from Text and Images
- ASOMobile Helps Teams Benchmark App Store Screenshots Against Competitors
- How to Match LMS Software With Your Organization's Training Plan
- Revolutionizing Email Marketing Agency with AI
- How to Convert BTC to HNT
- Unleashing the Power of AI: Cognizant's Roadmap for Transformation
- Frame to Video Review: A Practical Look at Turning Two Still Frames Into Motion
- NVIDIA NIM: Revolutionizing Supply Chain Data Analysis with AI
- Top AI Tools That Help Brands Stand Out Offline (Not Just Online)
- Top 5 Cold Email Software: Maximize Your Outreach in 2025

Copyright ©2026 toolify