



Total runs:
108.6K
Run Growth:
-24.5K
Growth Rate:
-22.53%


We introduce Sana , a text-to-image framework that can efficiently generate images up to 4096 × 4096 resolution. Sana can synthesize high-resolution, high-quality images with strong text-image alignment at a remarkably fast speed, deployable on laptop GPU.
Source code is available at https://github.com/NVlabs/Sana .
| Images |
|
|
|
|
|---|---|---|---|---|
| prompt |
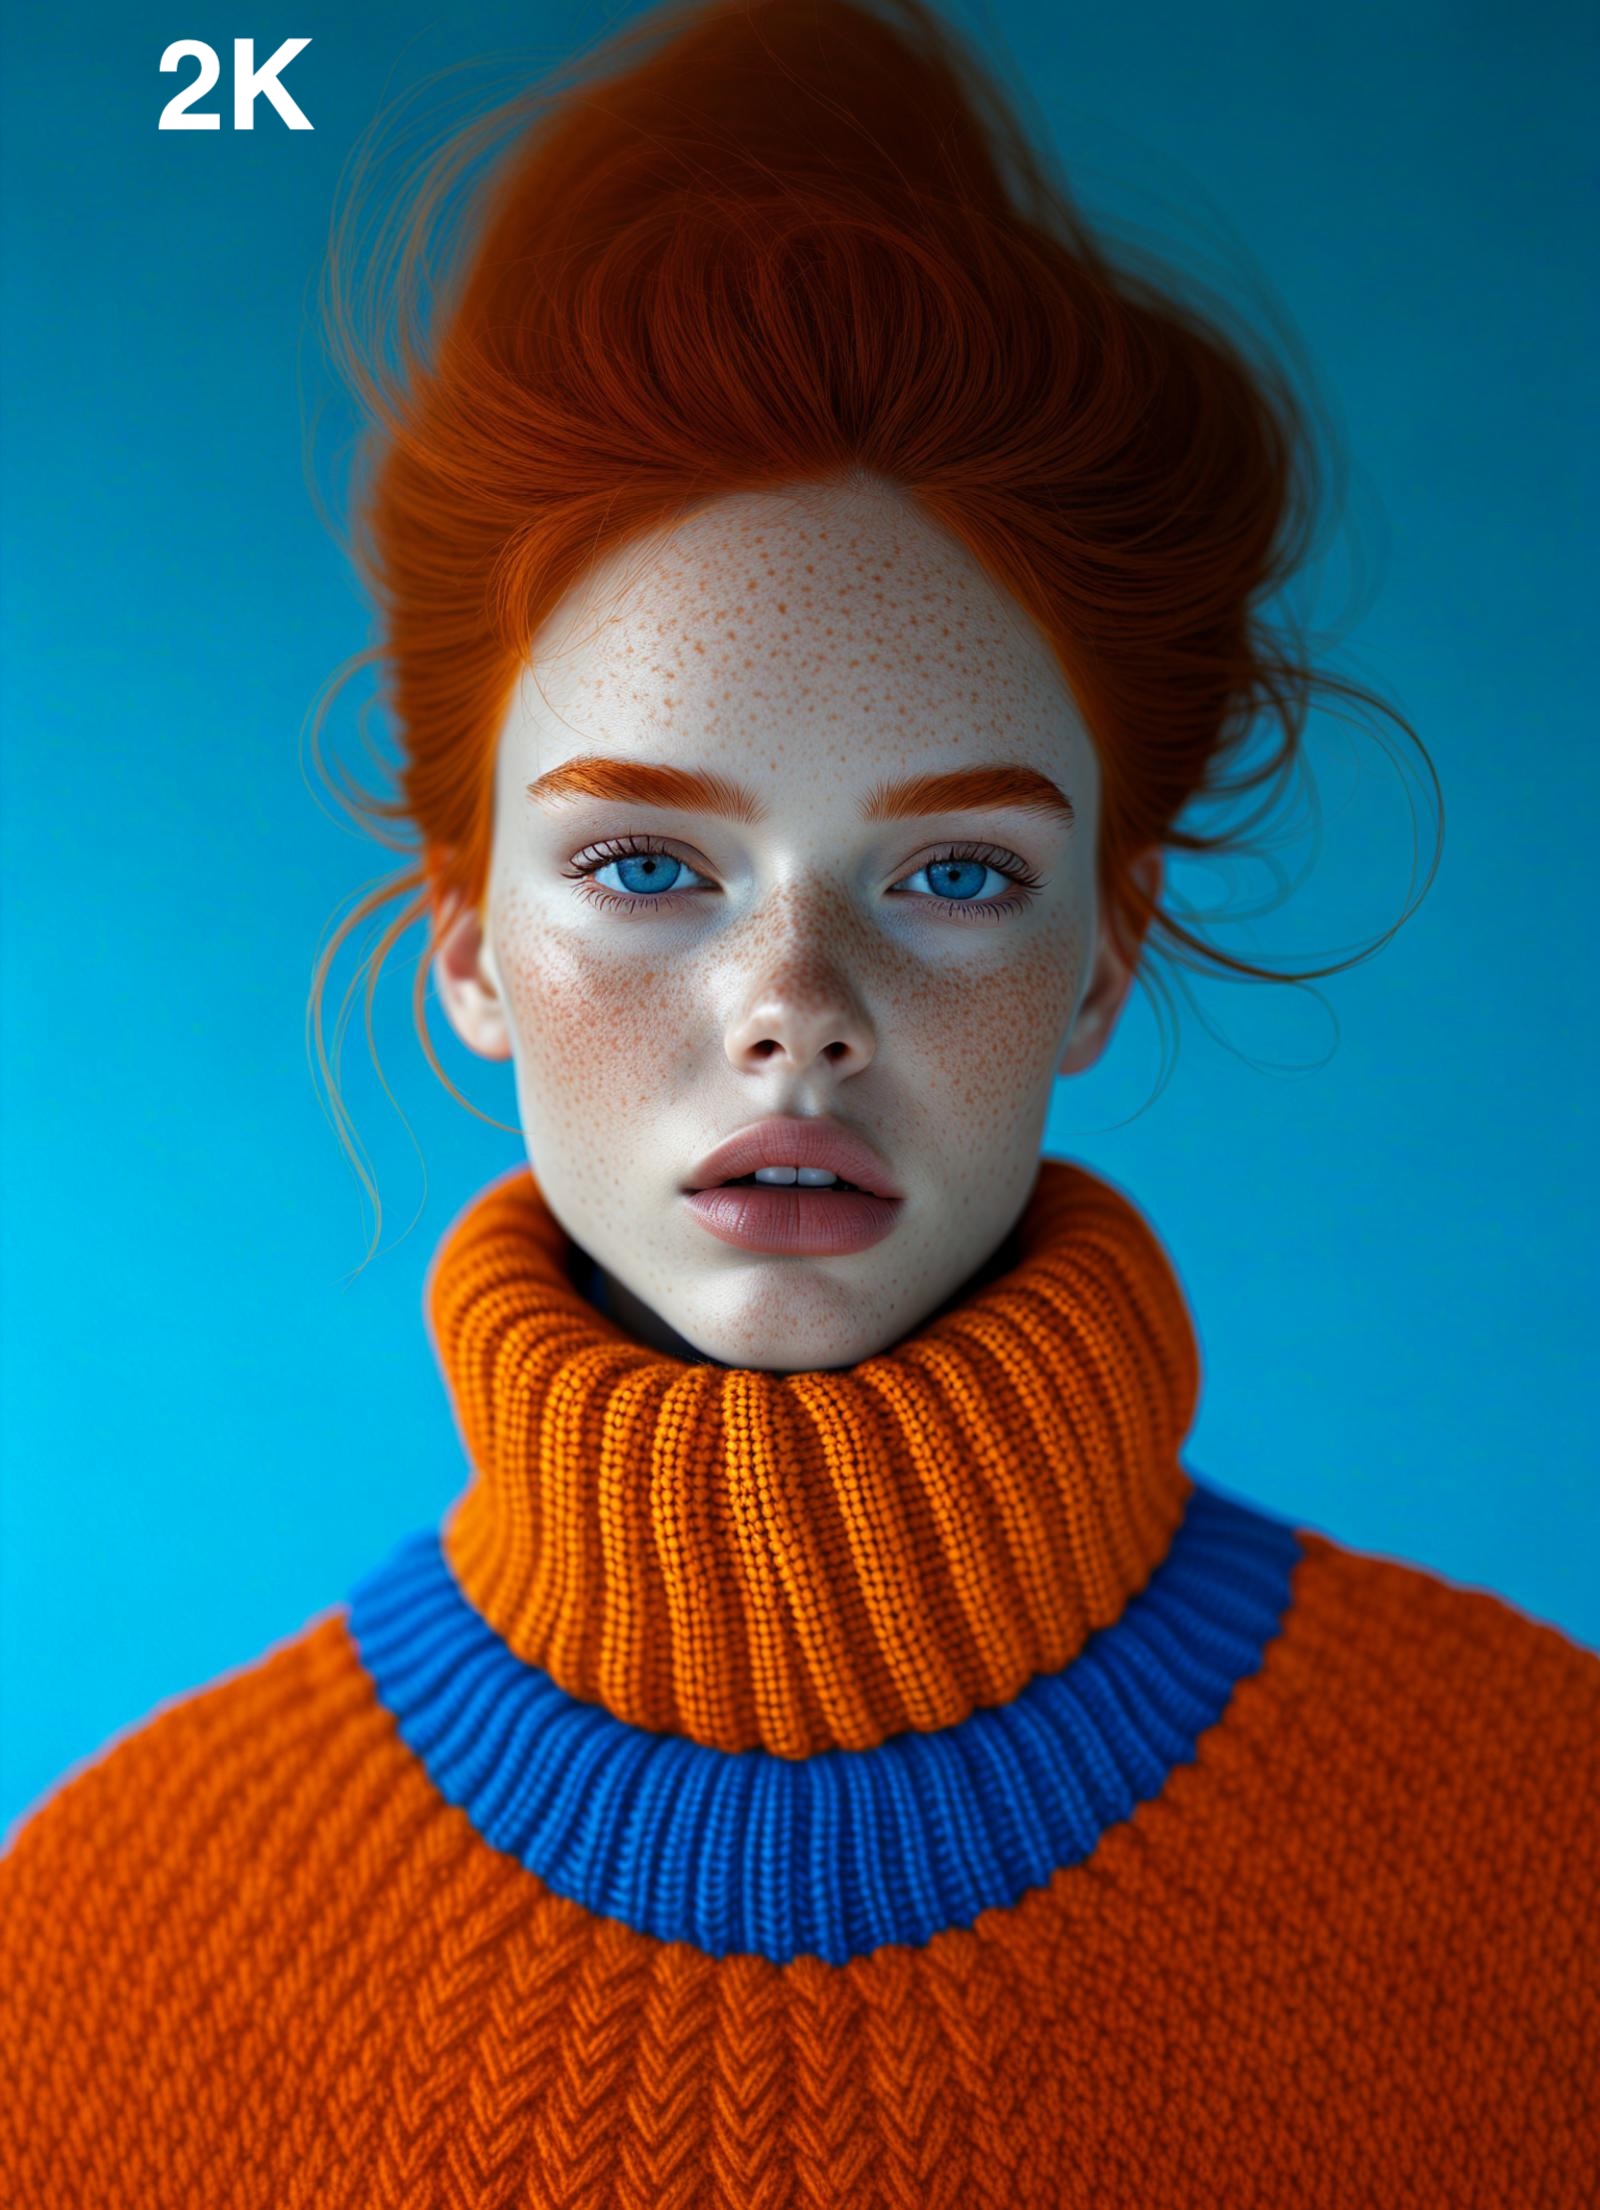
A model wearing an orange and blue sweater with a knitted pattern, detailed face, ginger hair color, blue background, shot in the style of Tim Walker |
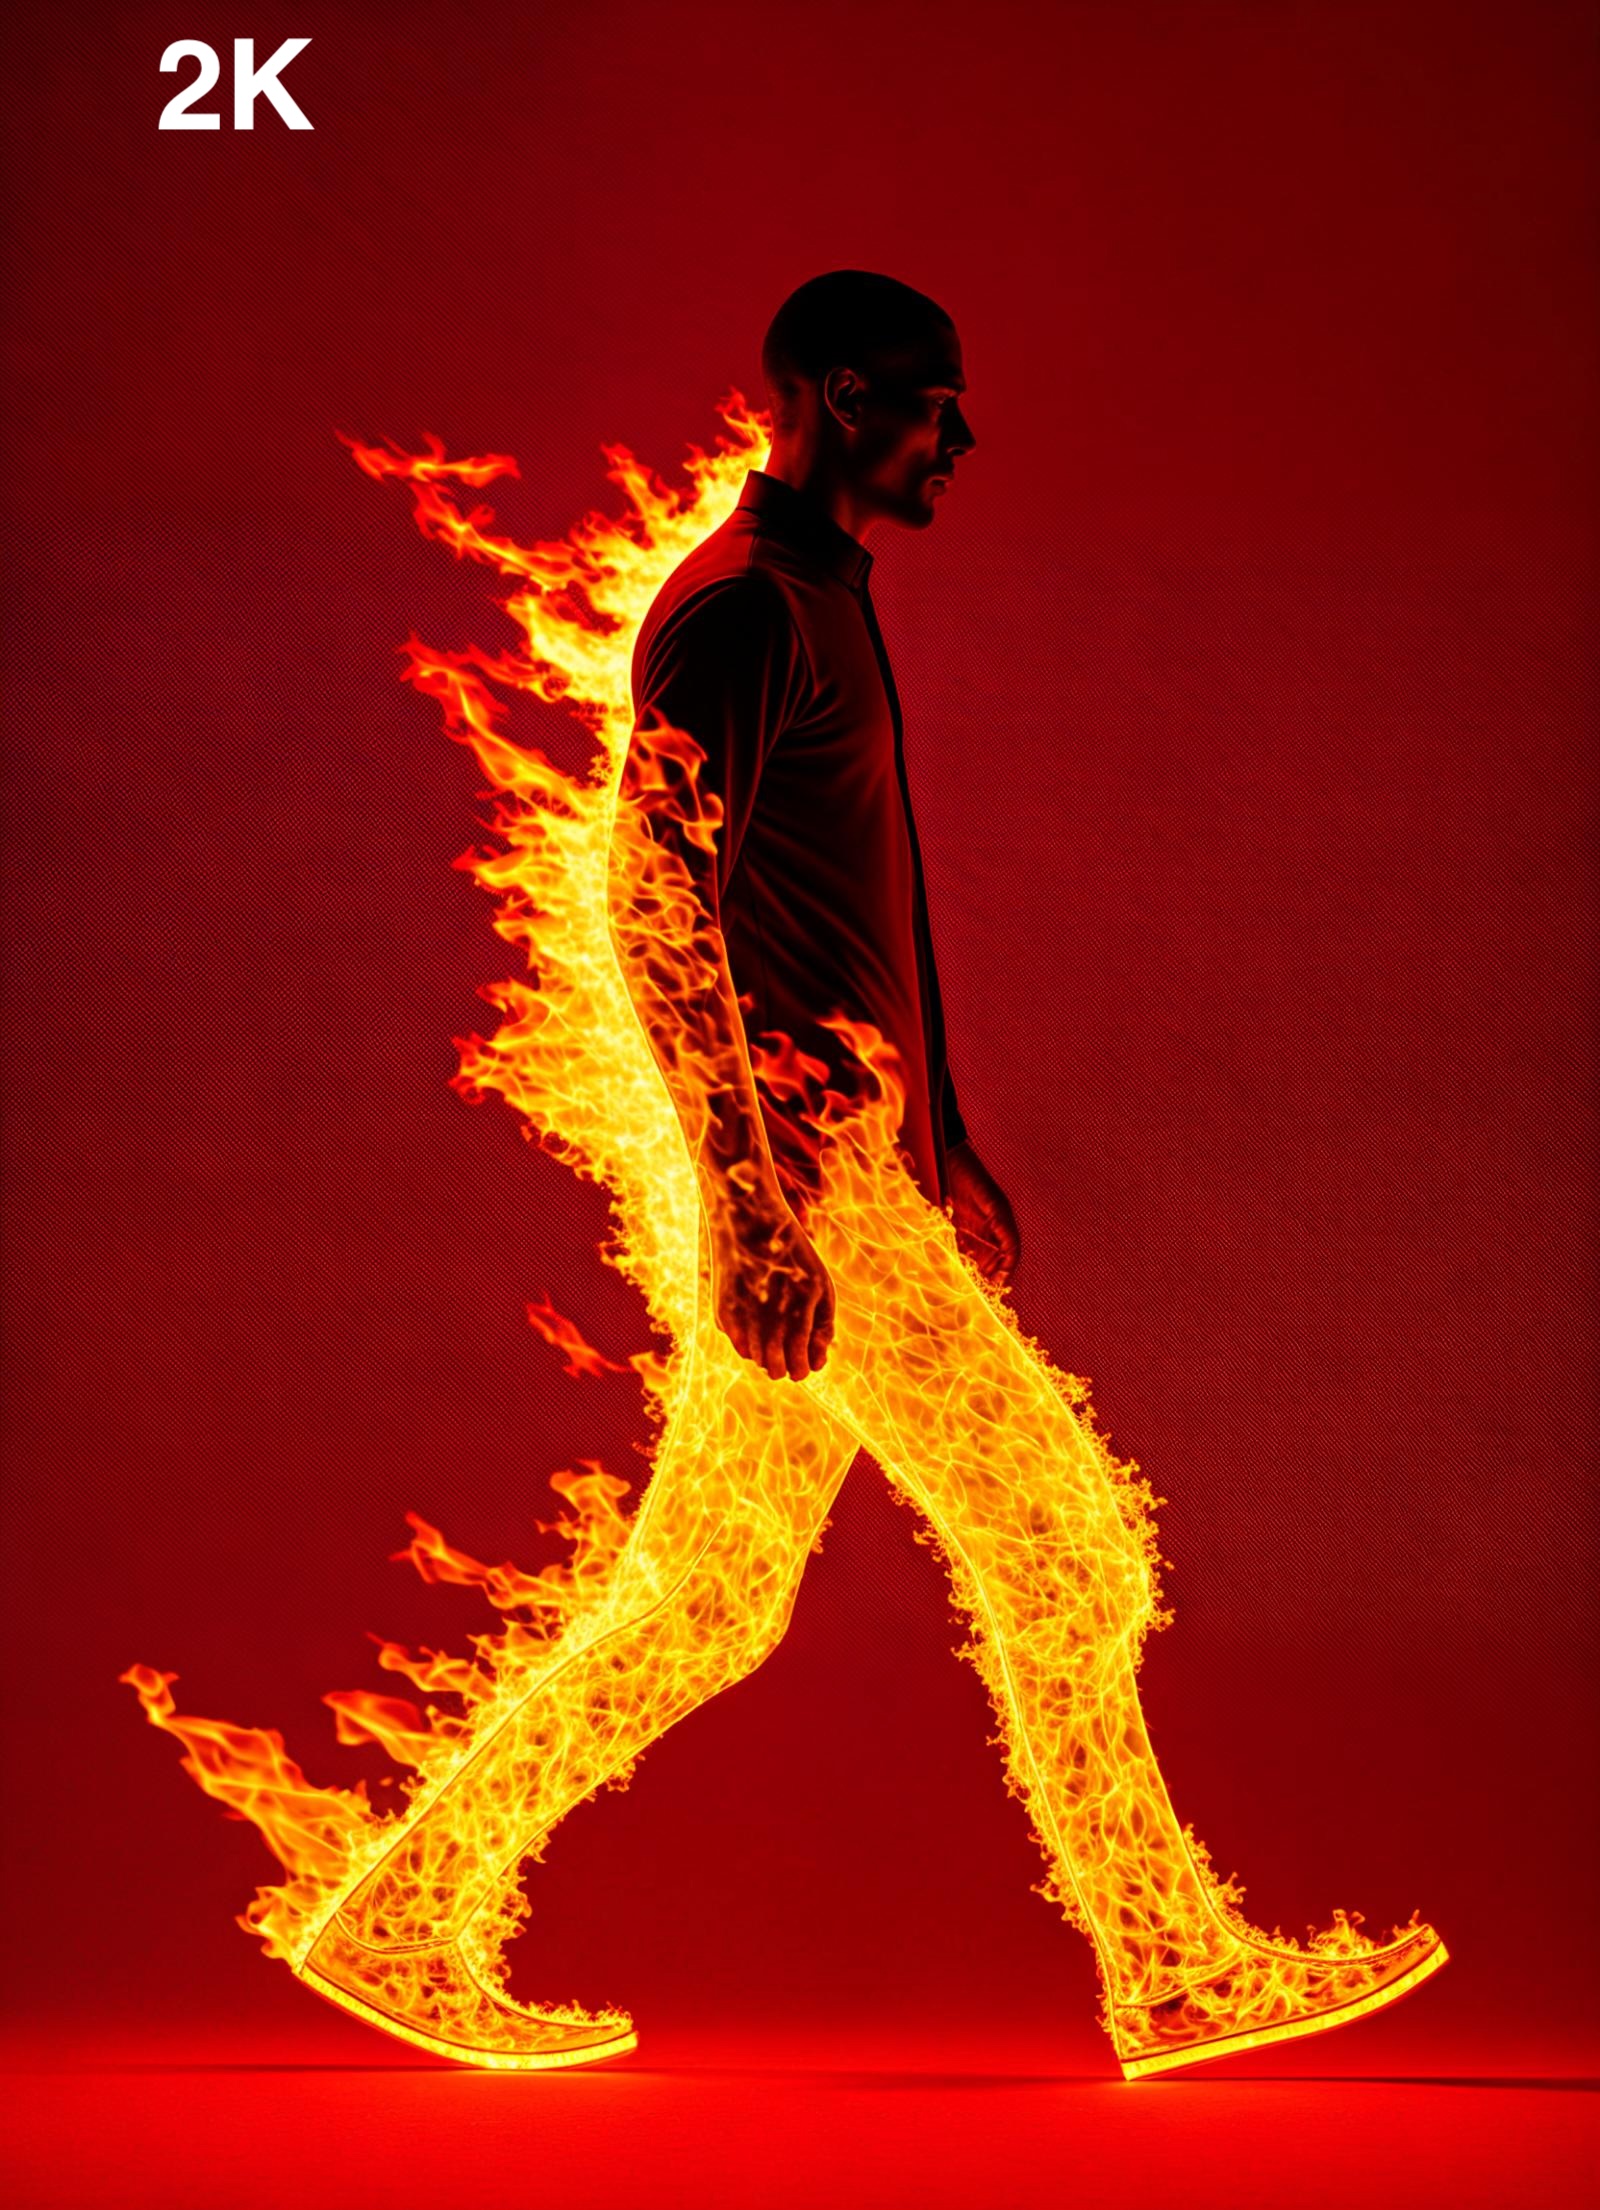
A studio shot of a figure composed of vivid, realistic flames walking in side profile, no face, with flames trailing naturally behind, against an intense red background, Captured by Helmut Newton, with a Hasselblad H6D and an 80mm f/2.8 lens at f/5.6, 1/125s, ISO 400. The flames are intense and detailed, with a natural, realistic texture that emphasizes the movement. HD quality, natural look |
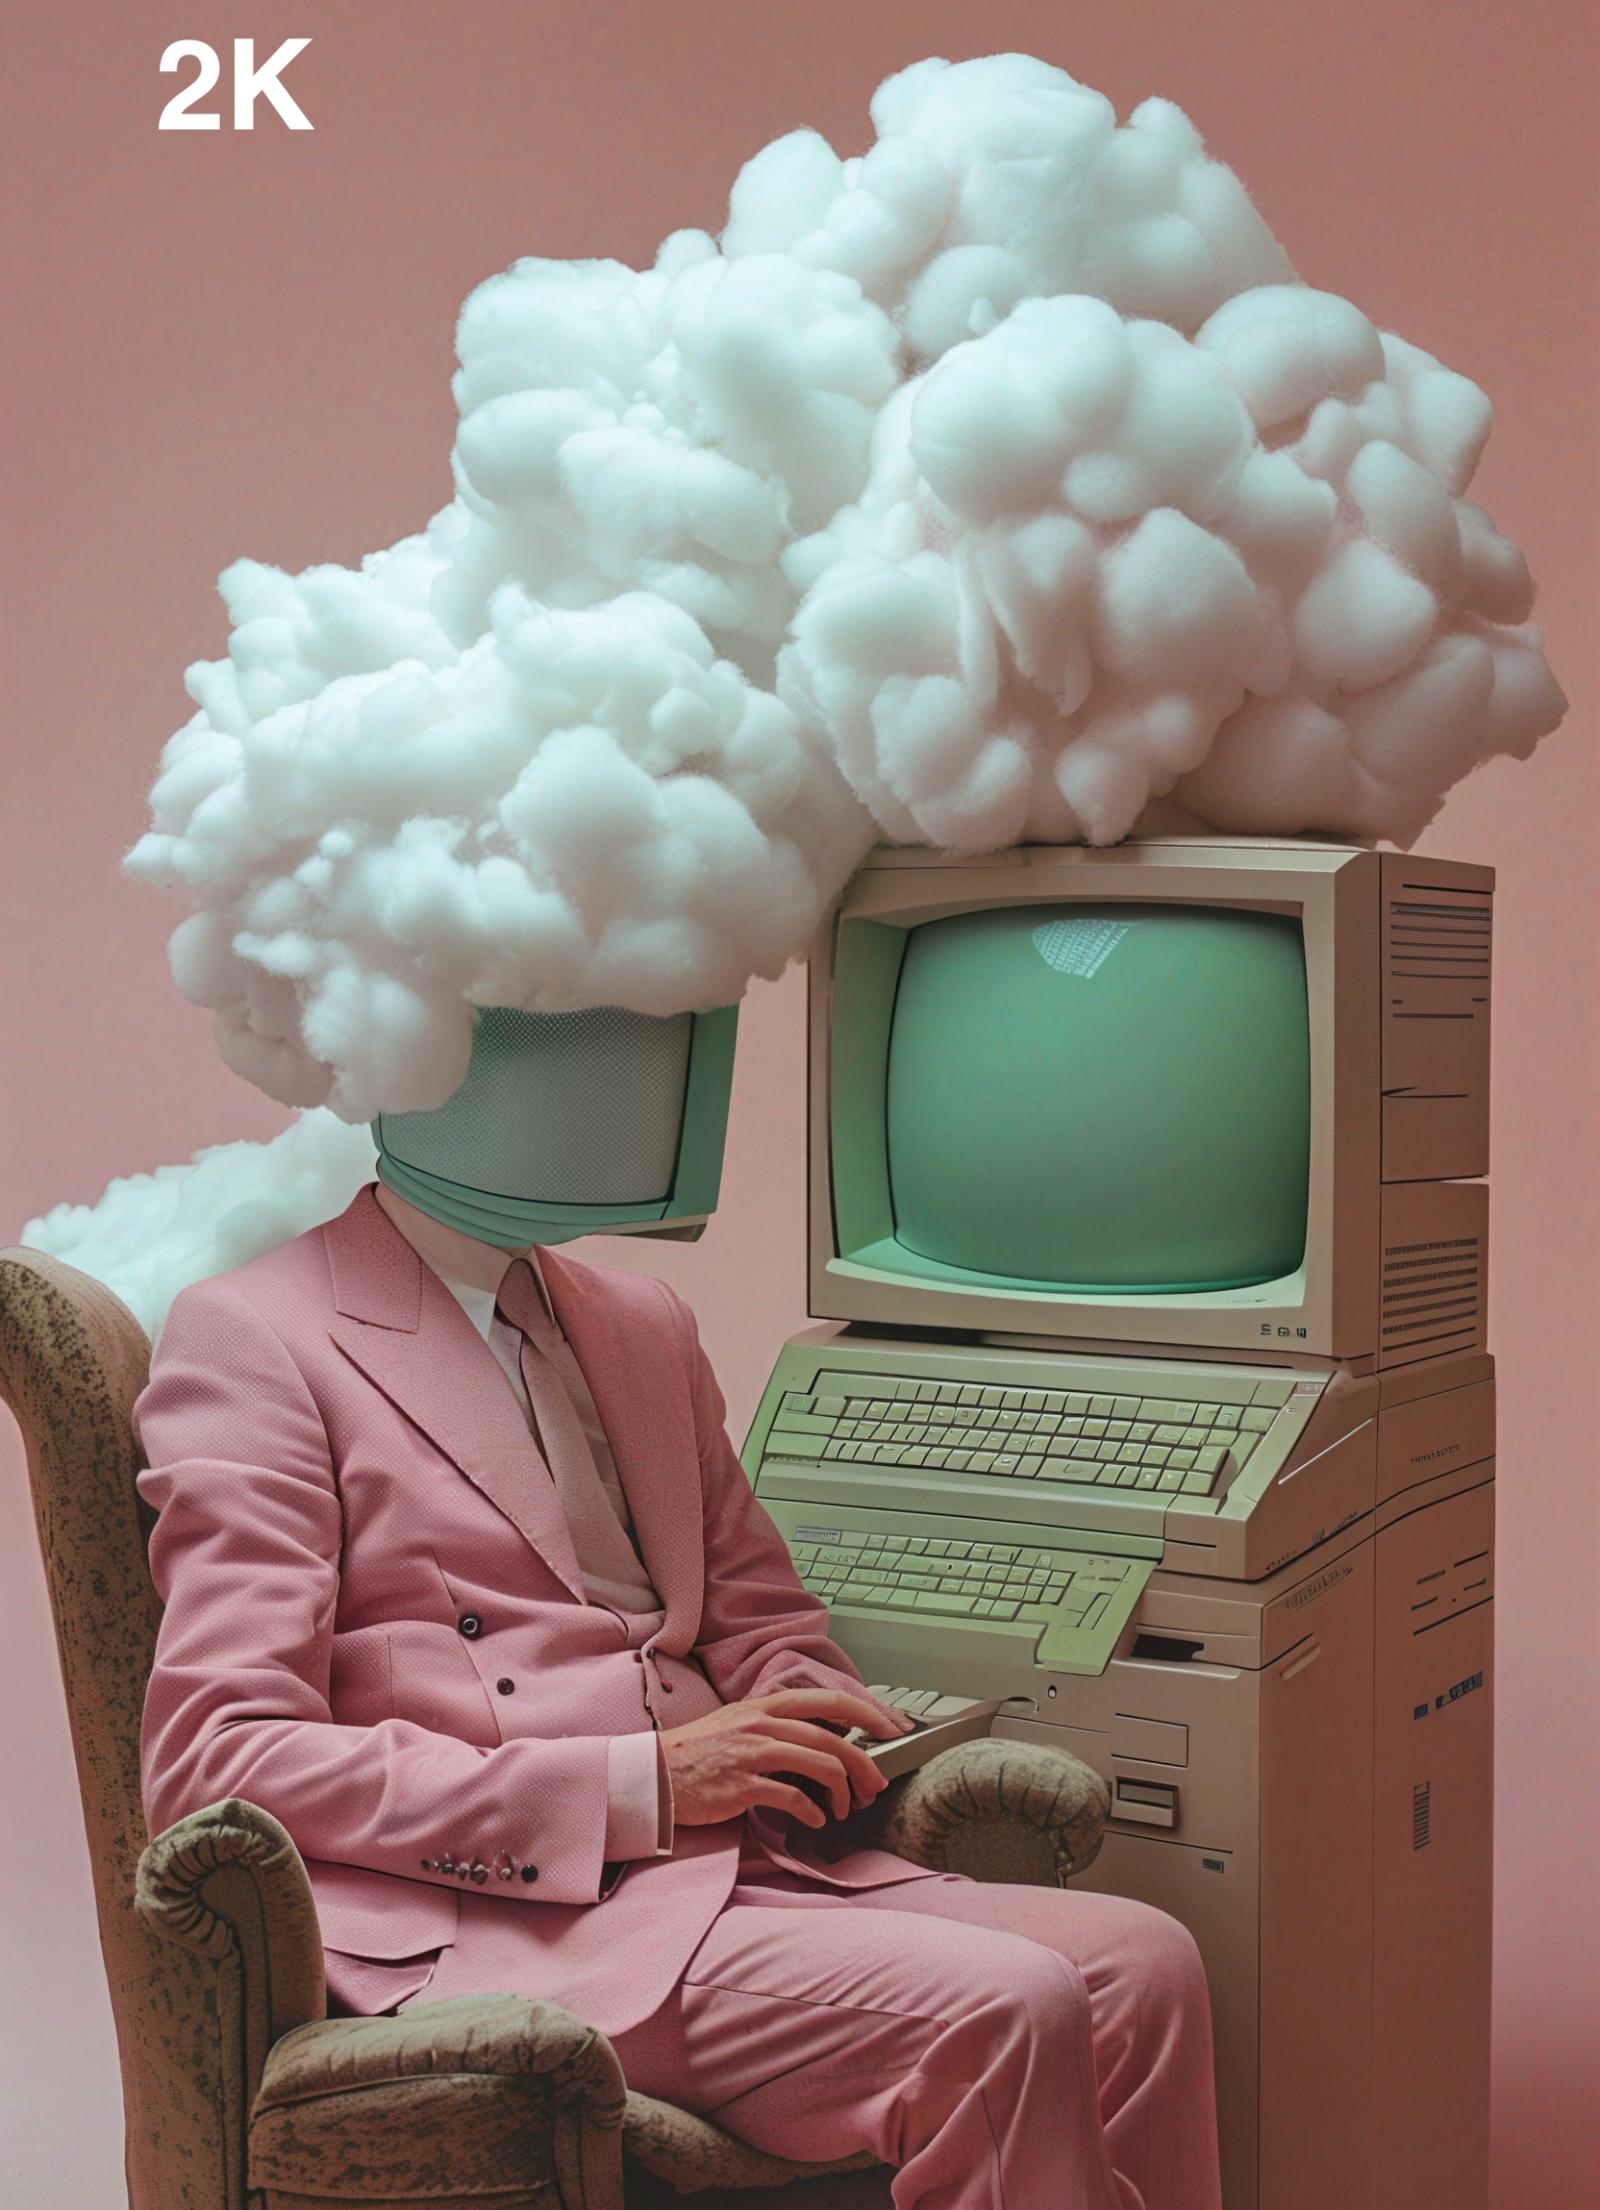
A surreal photograph of a man with his head covered in large, fluffy cotton clouds, sitting in an armchair facing the camera and using an old computer from the early 20th century. The computer has a green screen monitor. He is wearing a pink suit, and the overall scene has a soft, pastel color palette with a retro futuristic, 1970s vibe |
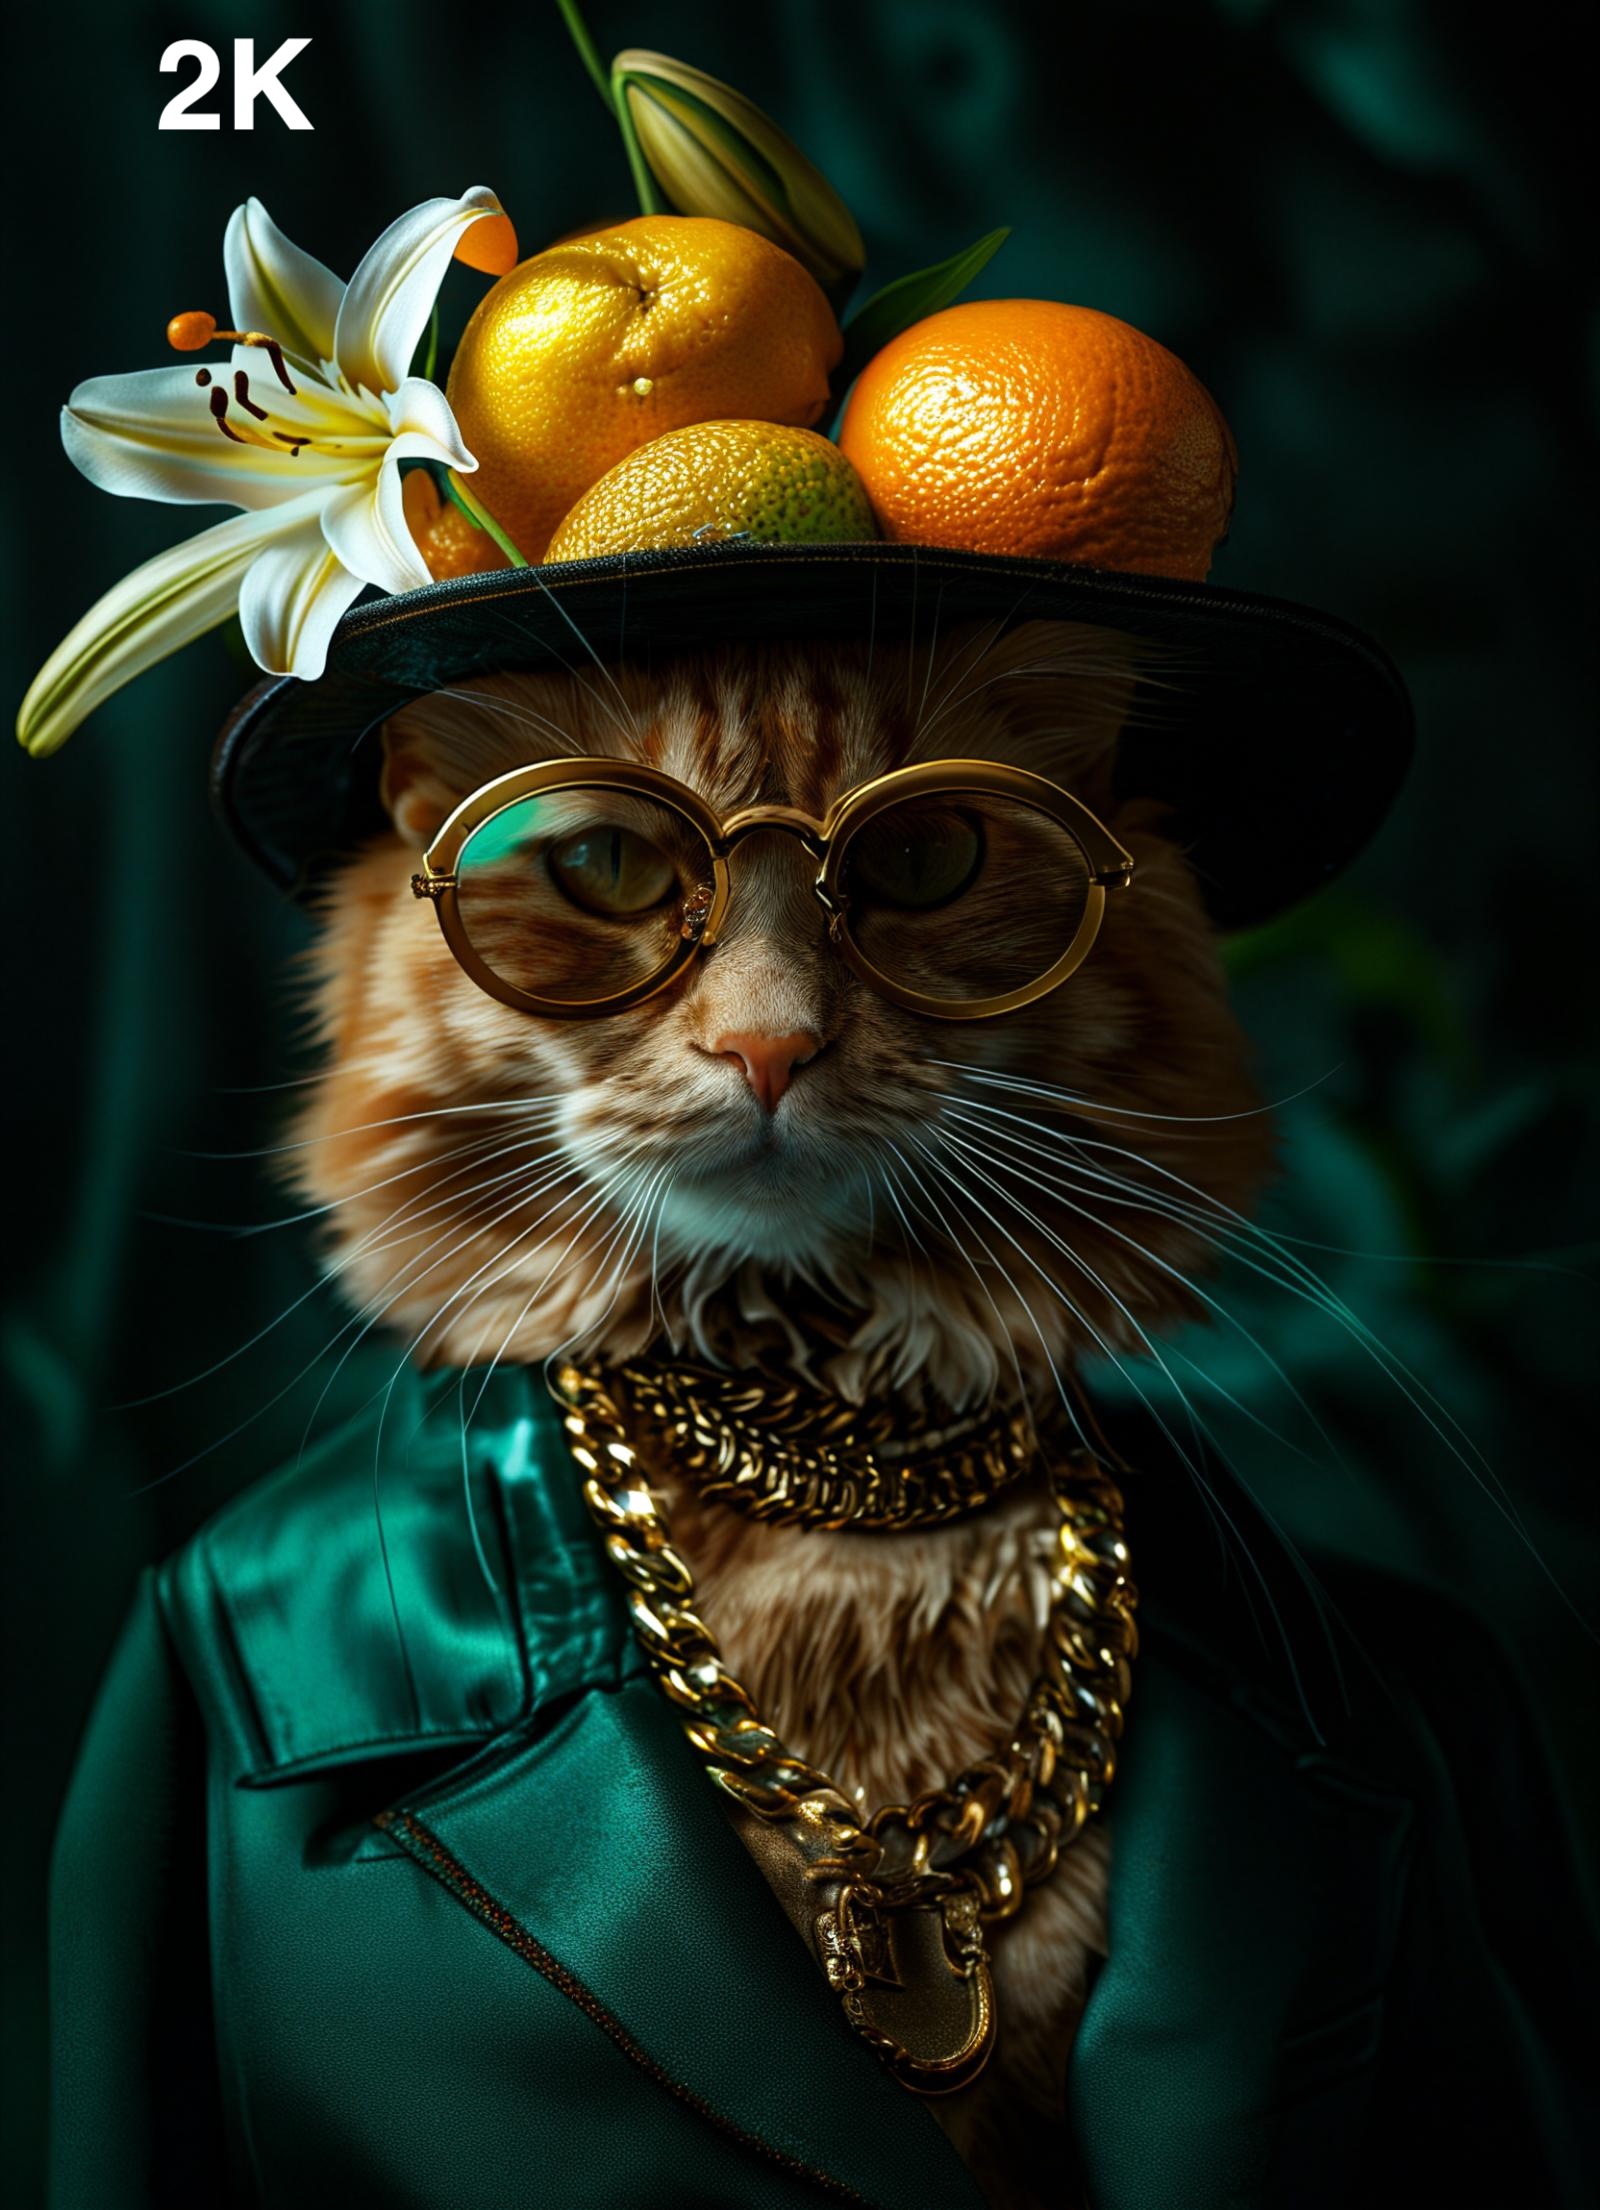
highend portrait of a cool ginger cat, high fashion Style with crazy glasses and stylish clothes and luxury necklace of jeweleries, hat consisting of lilies, oranges and lemons, color: dark green and gold, background: dark and luxury, hyper detailled, stil: raw, cinematic light, canon, expressive and original, canon, 50 mm lens, editorial, look: expensive, mood: motivated and good vibes |
| Images |
|
|
|
|---|---|---|---|
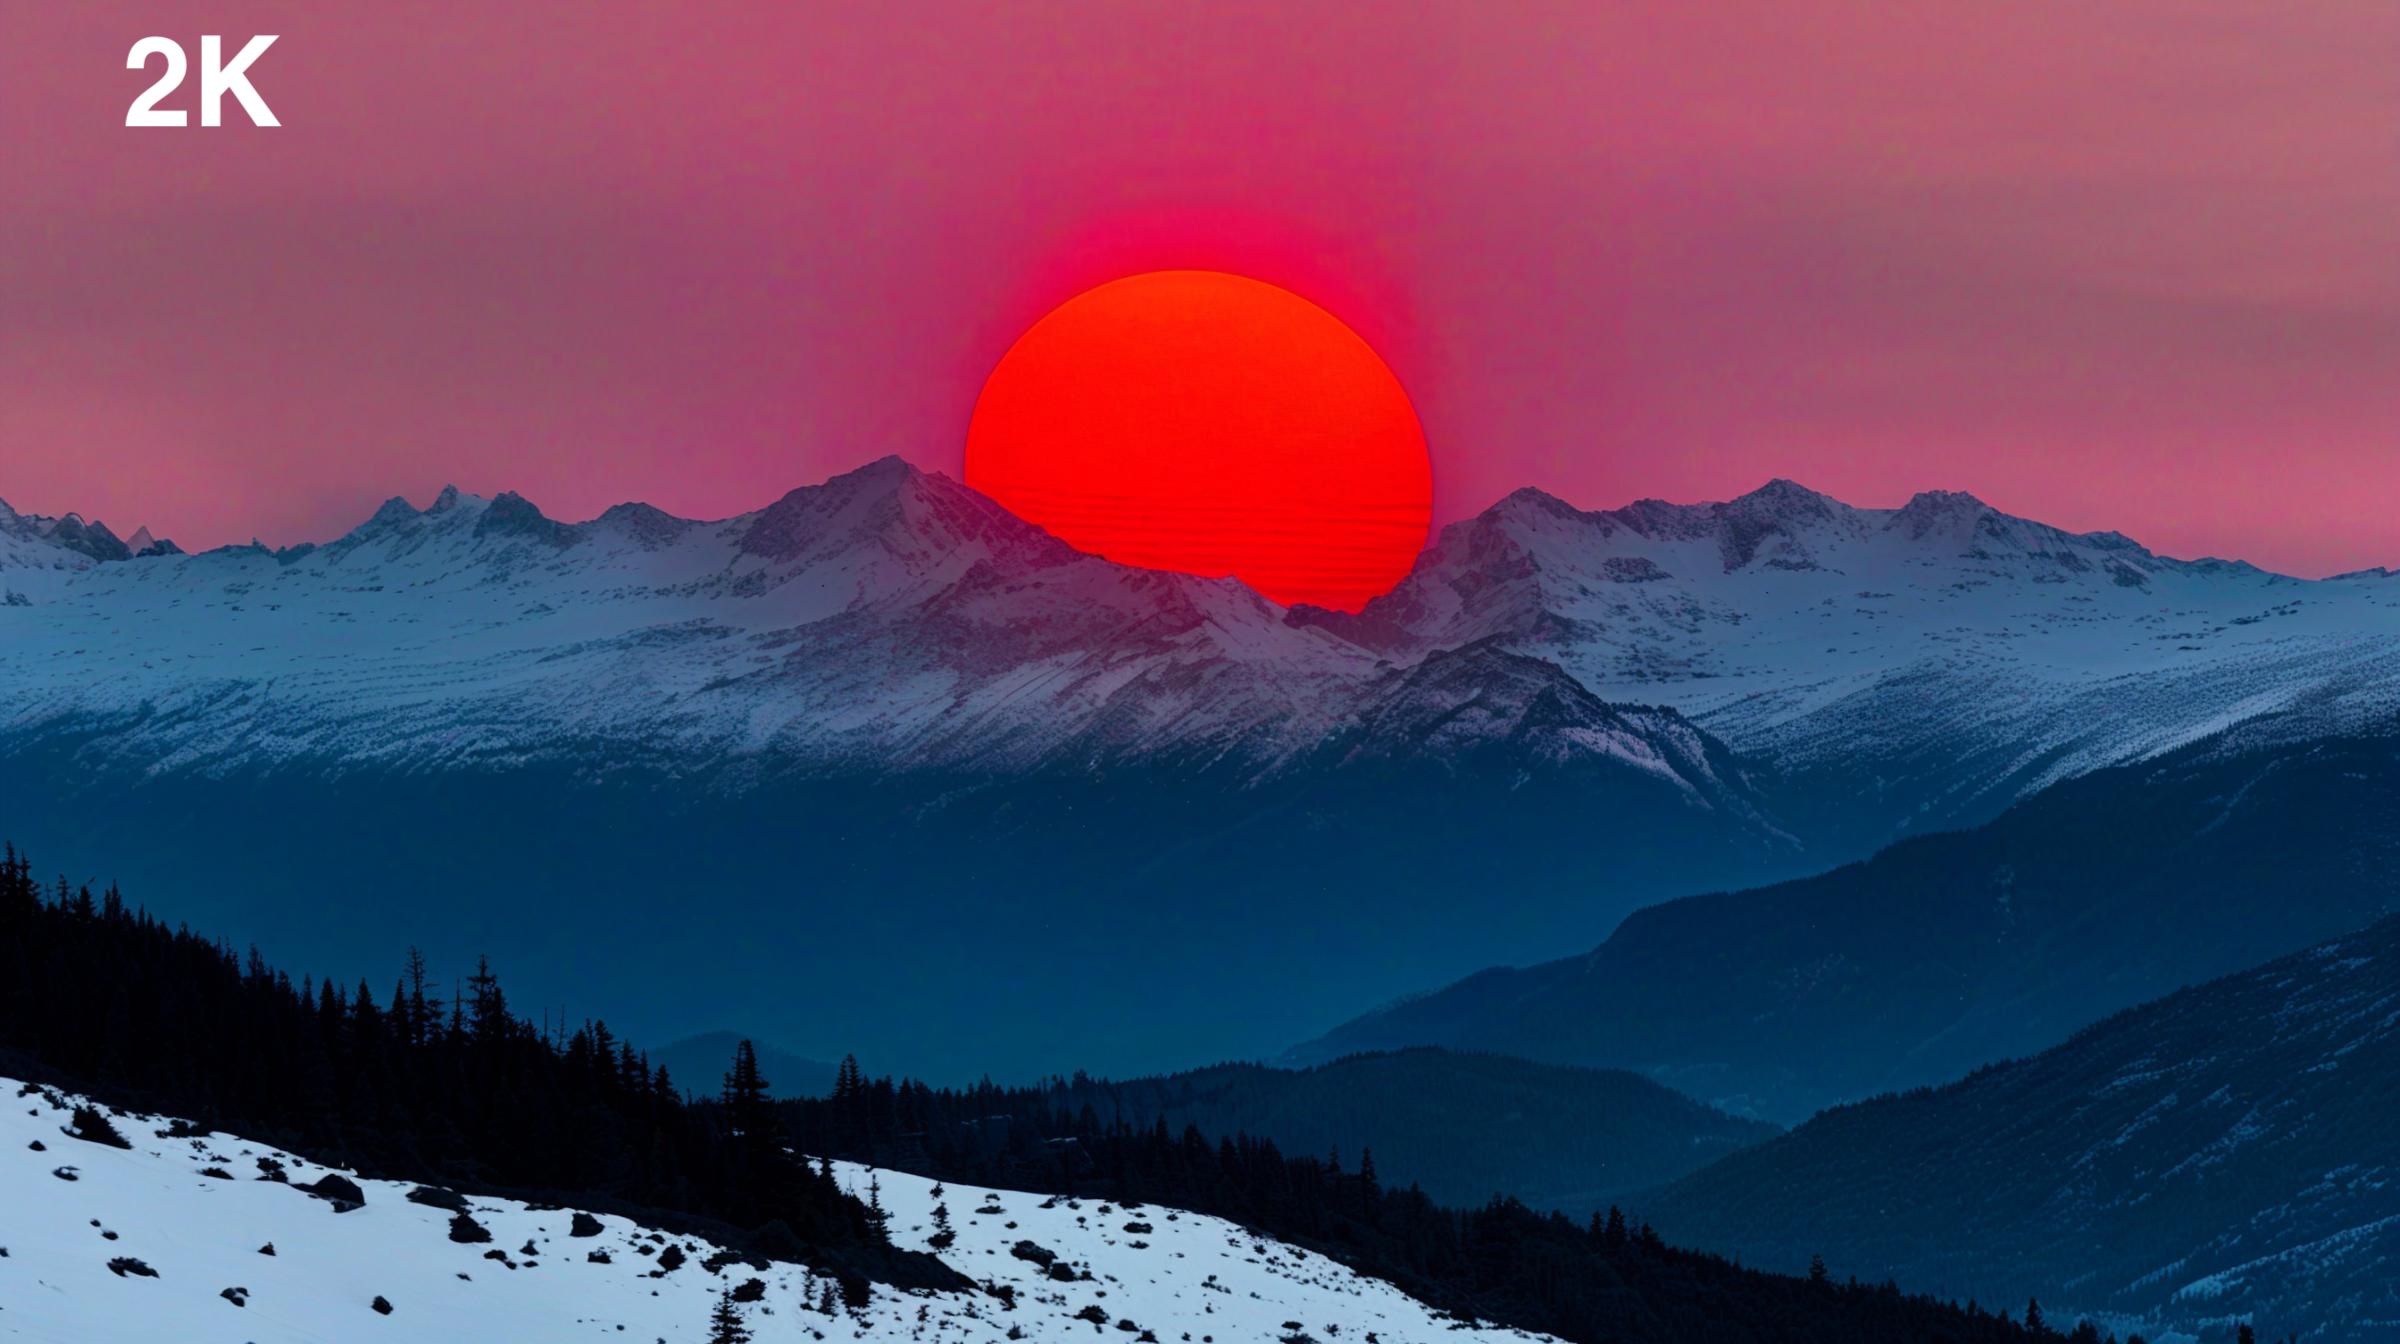
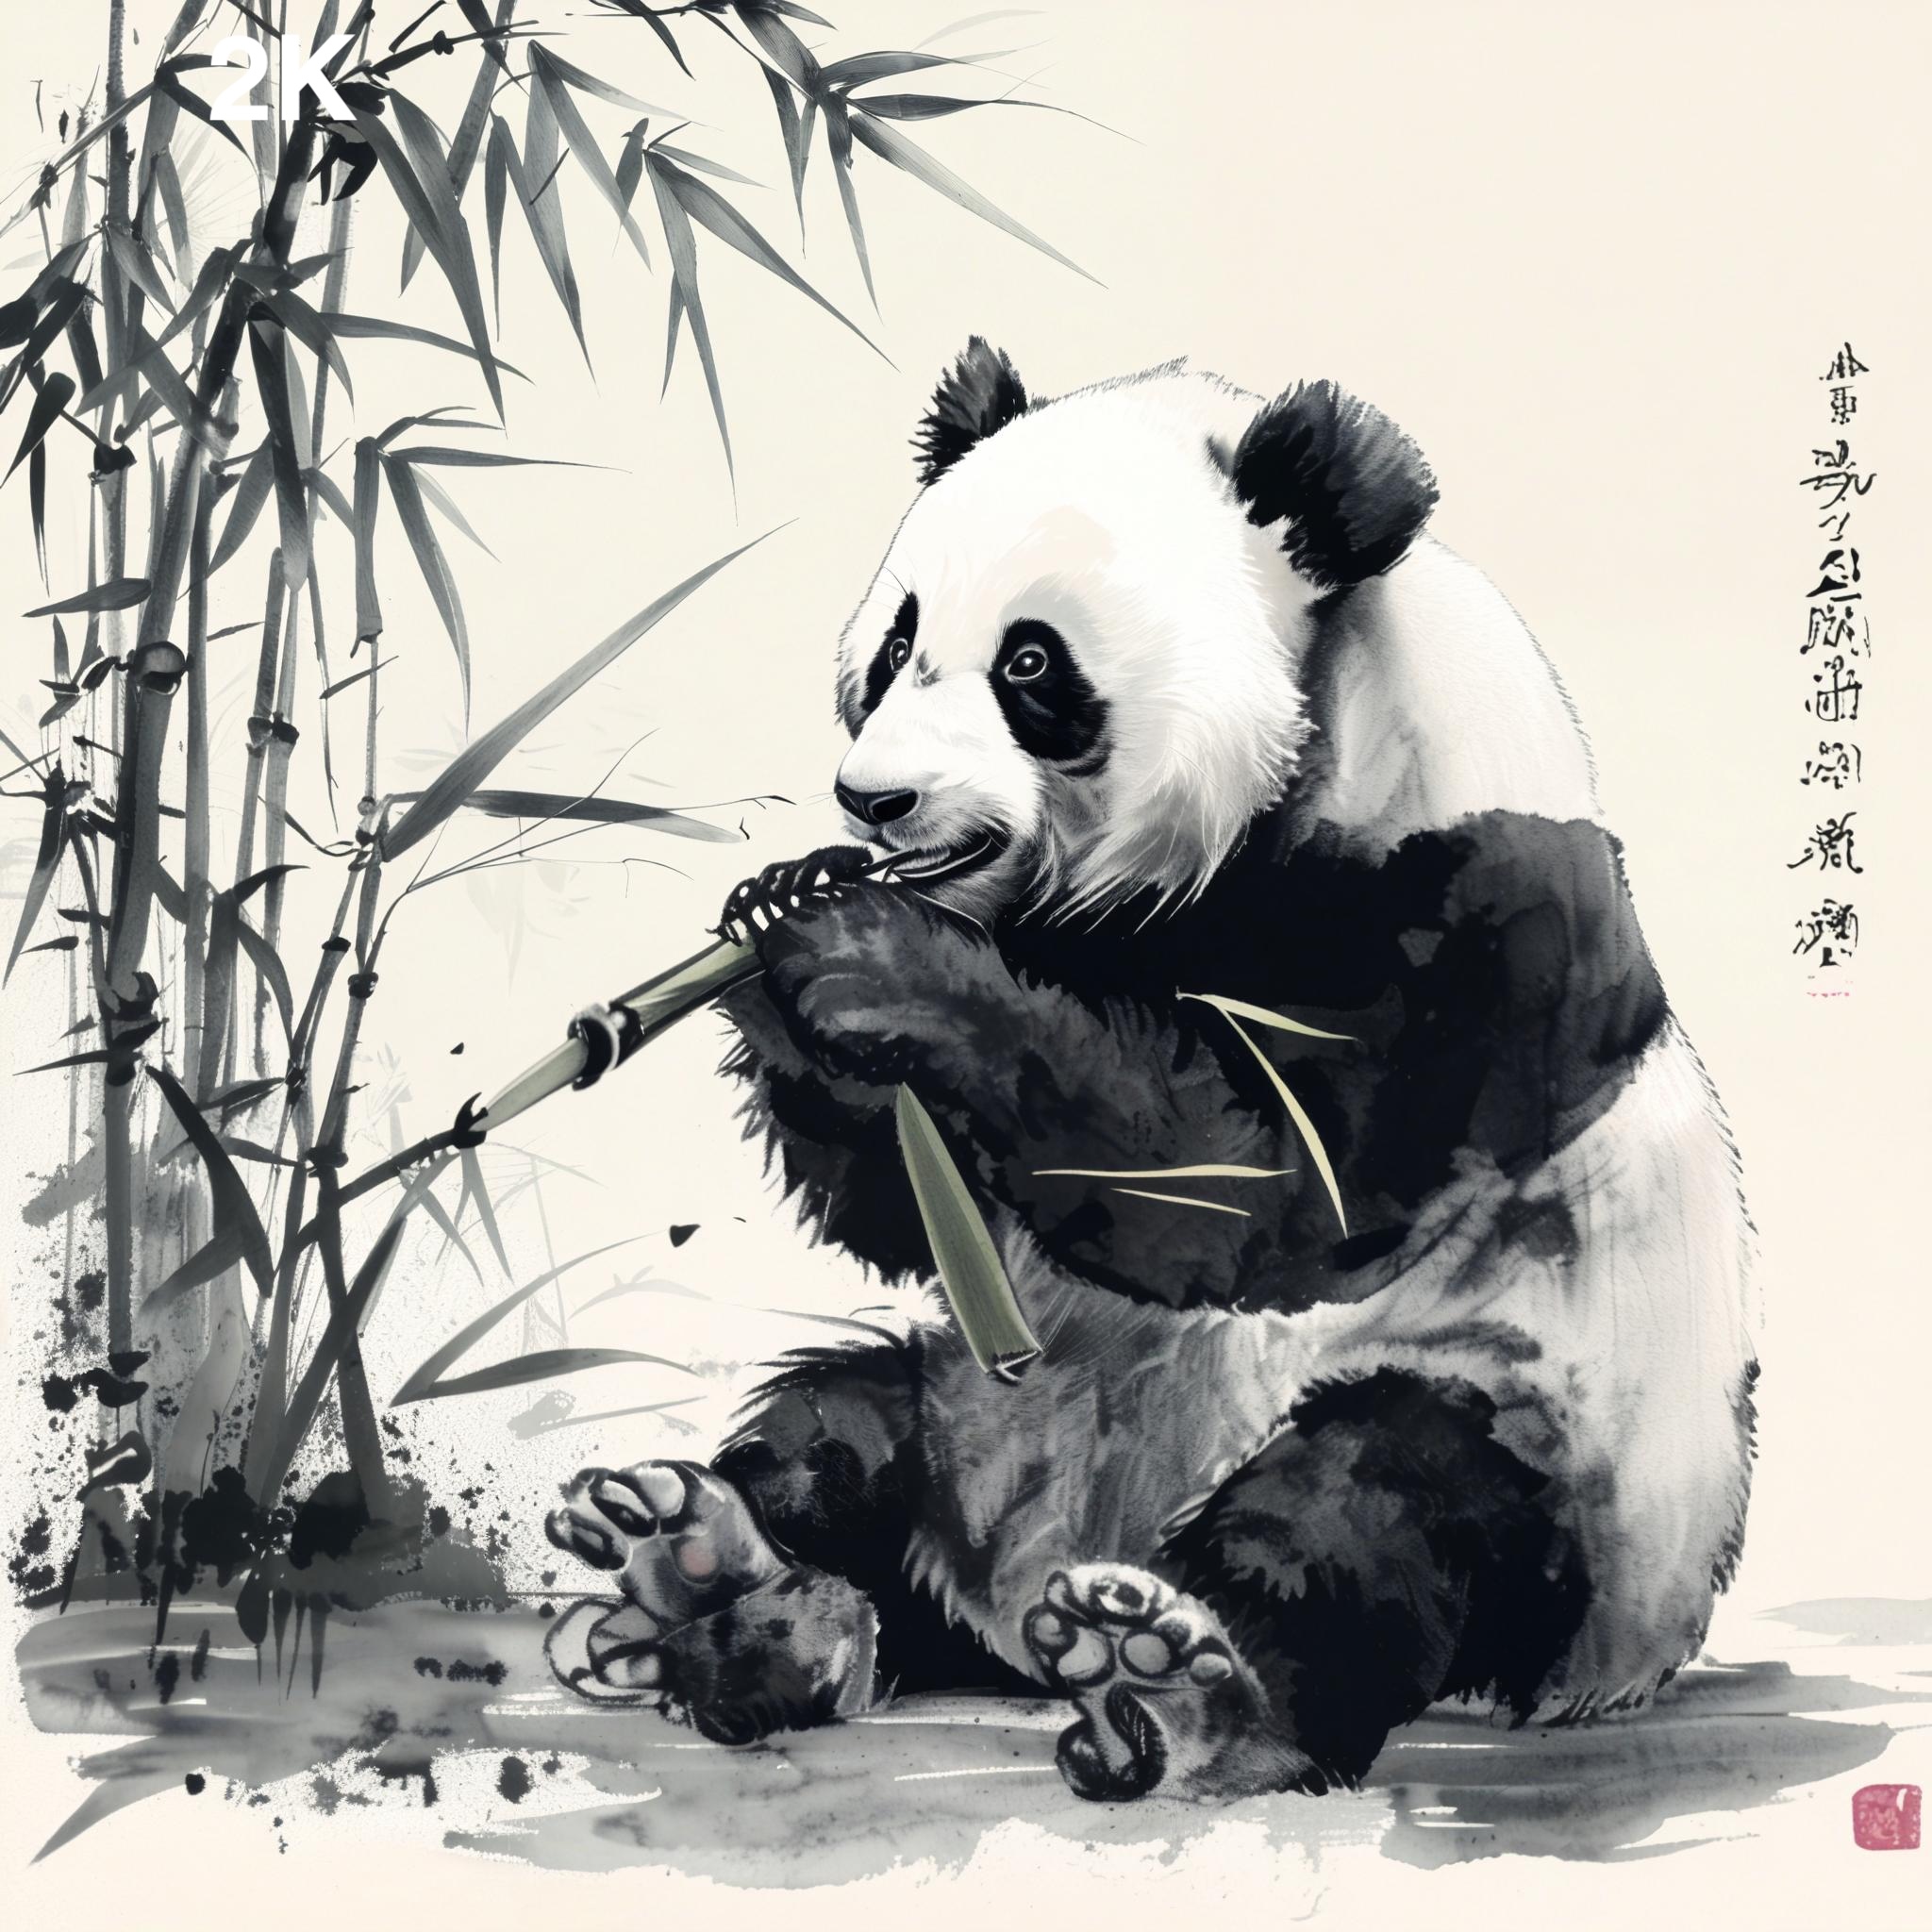
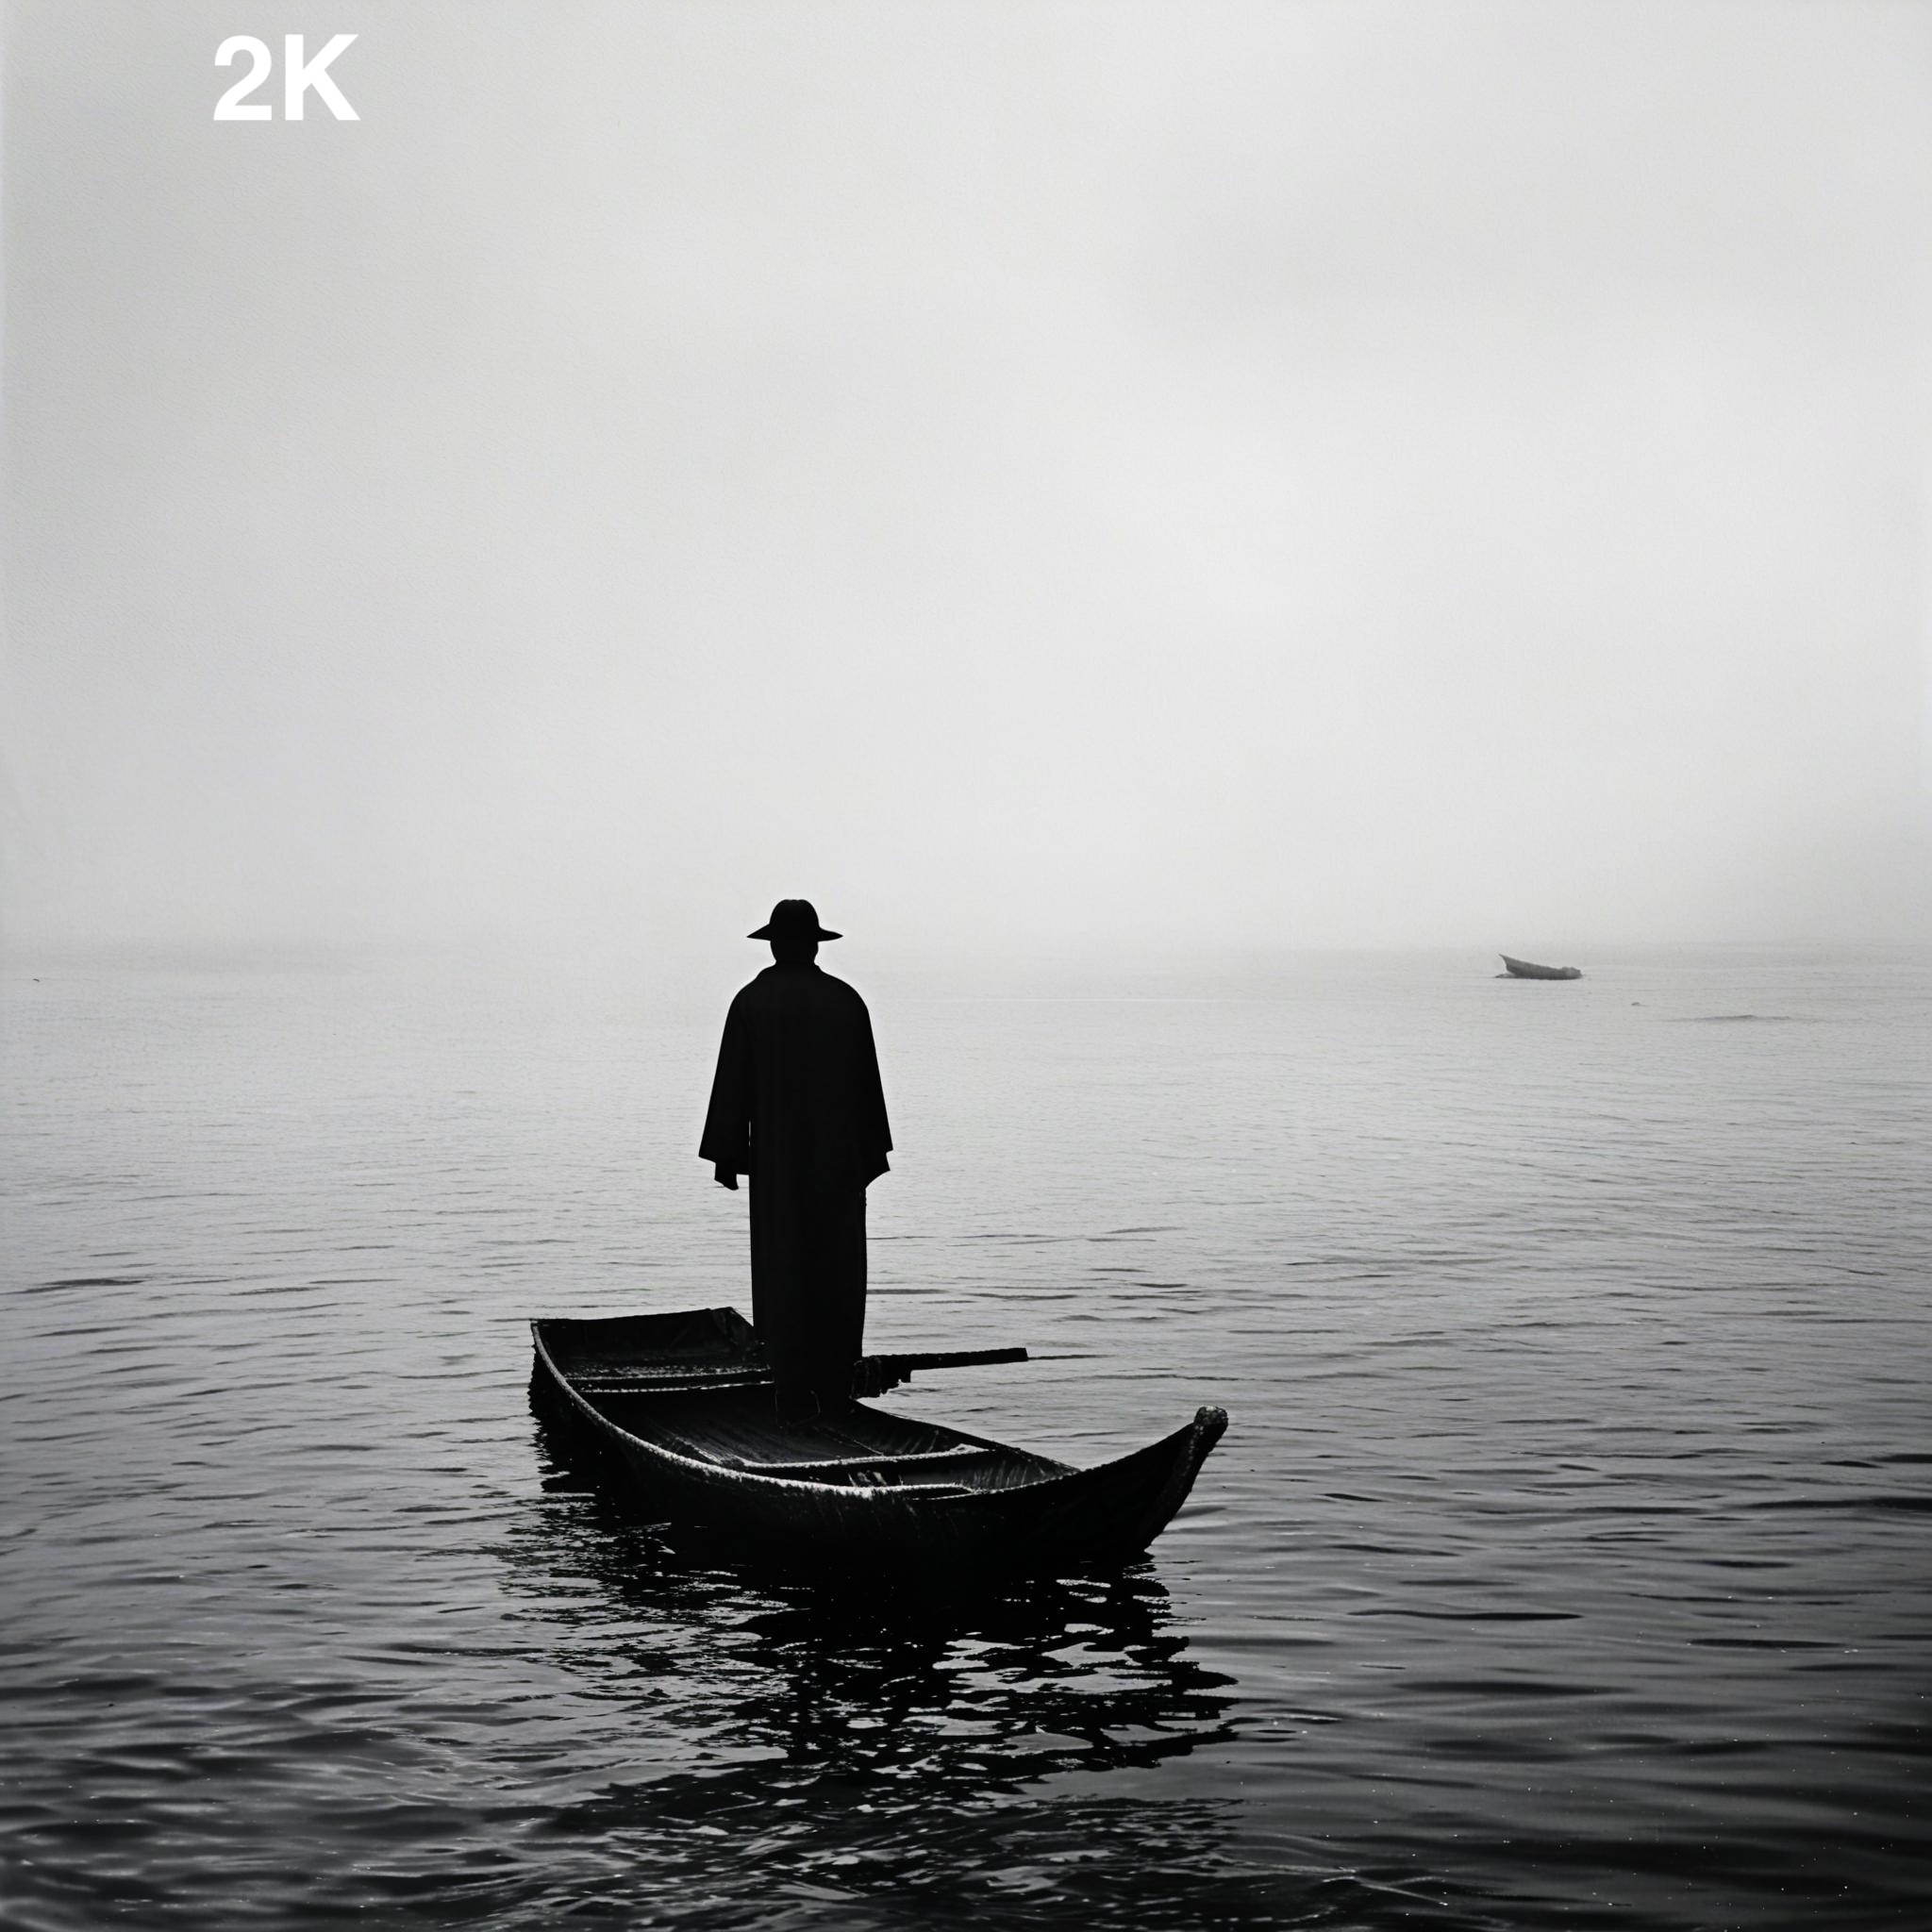
| prompt | 雪山之巅红日东升 | 一只可爱的 🐼 在吃 🎋, 水墨画风格 | 孤舟蓑笠翁 |
| Images |
|
|
|
|---|---|---|---|
| prompt |
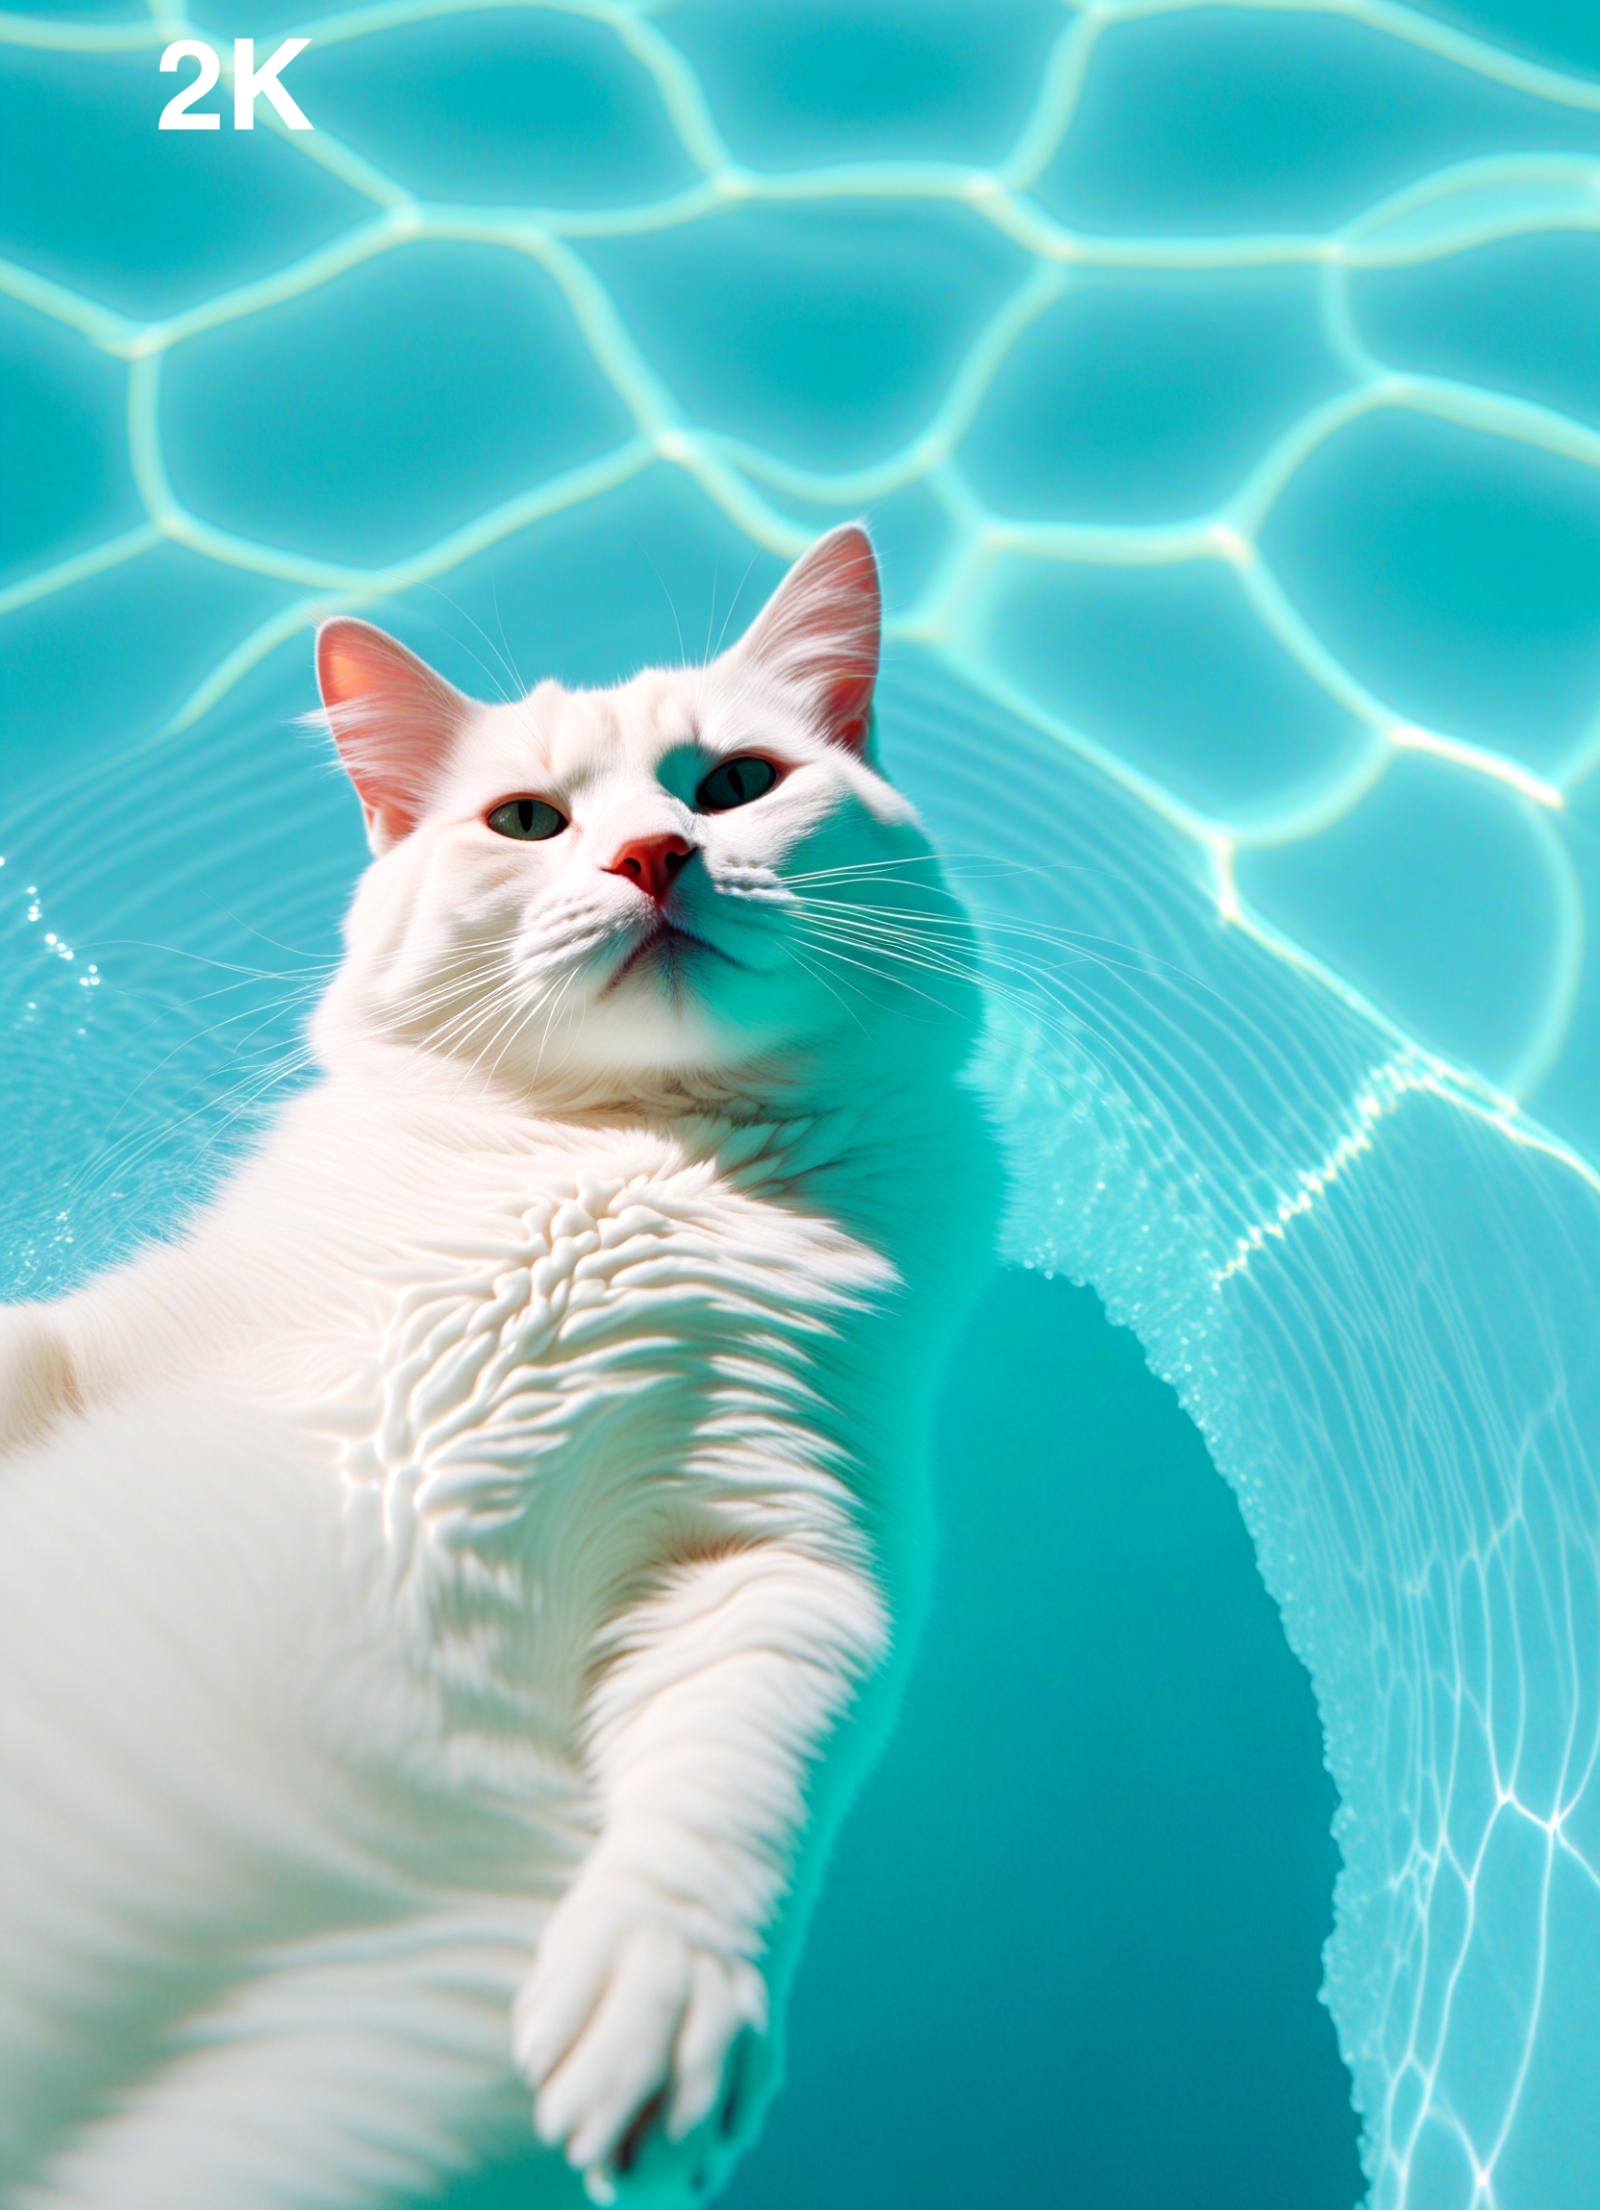
a cat floating in a body of water in the pool, Lean back clear and transparent water, light white, and turquoise, y2k aesthetic, soft and dreamy colors, brightly colored, popular Instagram, highlevel of detail, realistic photo feeling |
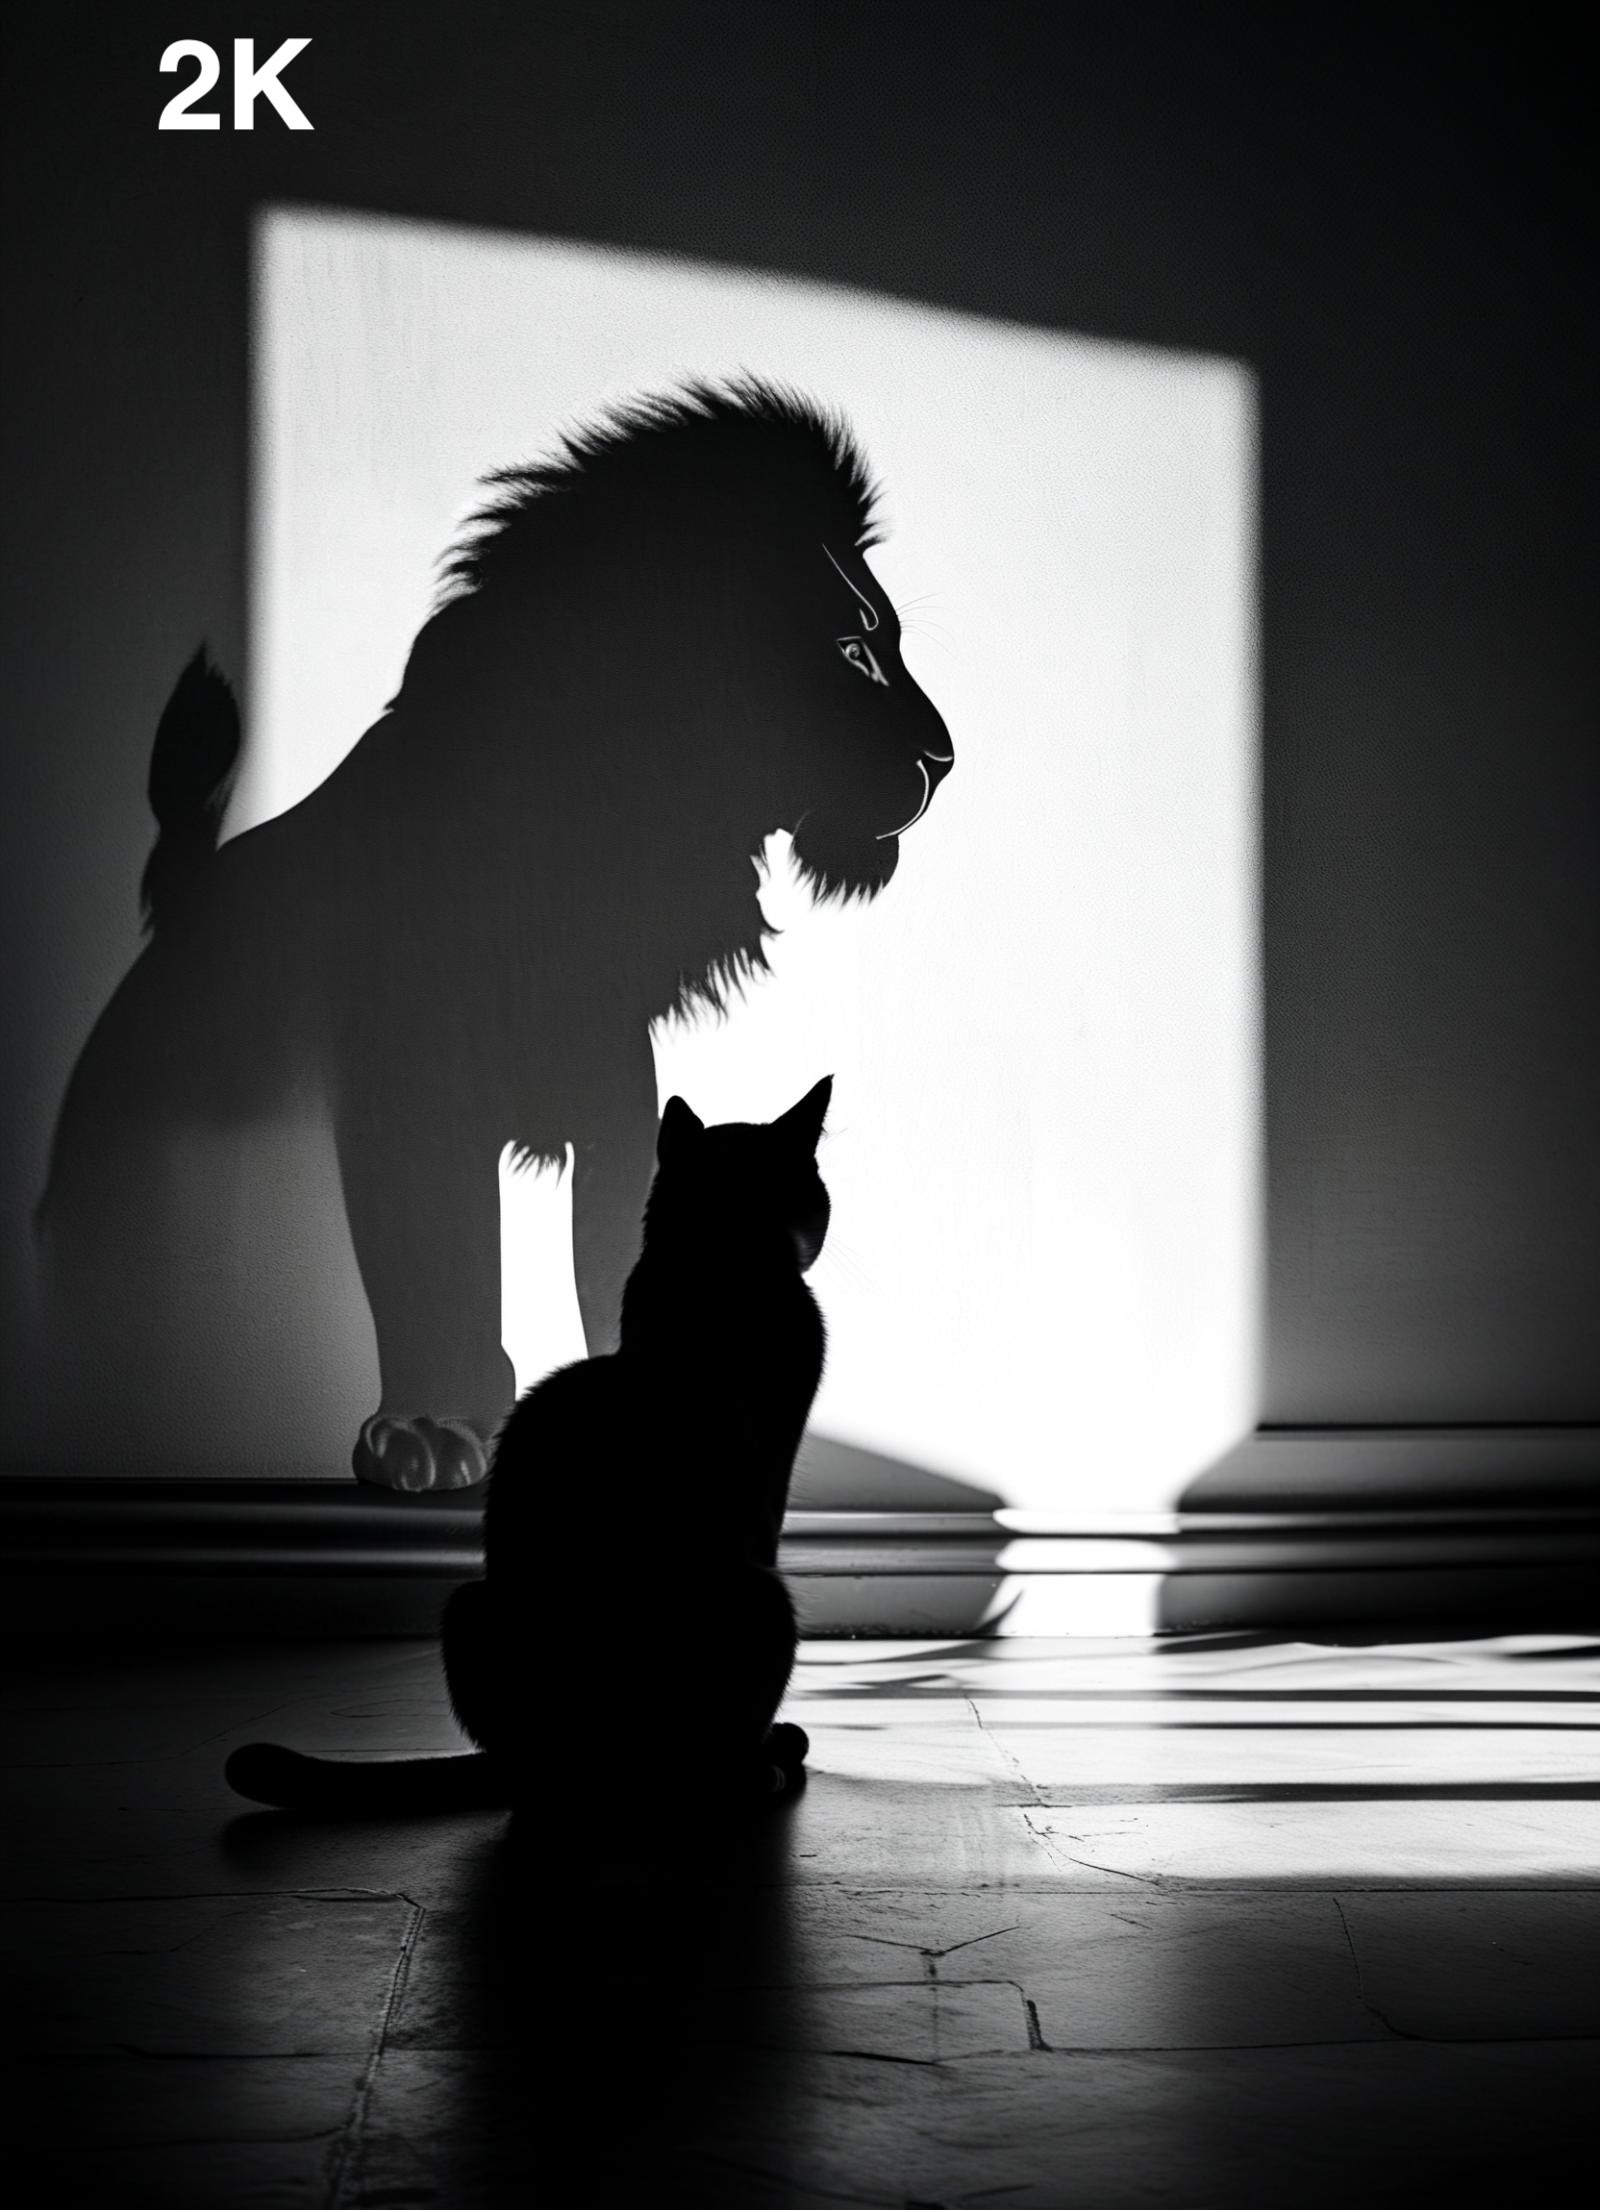
A black cat sits on the ground, facing away from us and casting its shadow in front of it. The silhouette of a majestic lion is projected onto the wall by the light source behind the scene. Black and white photography, soft lighting, high contrast, sharp focus, symmetrical composition, simple background, portrait lens, static posture. |
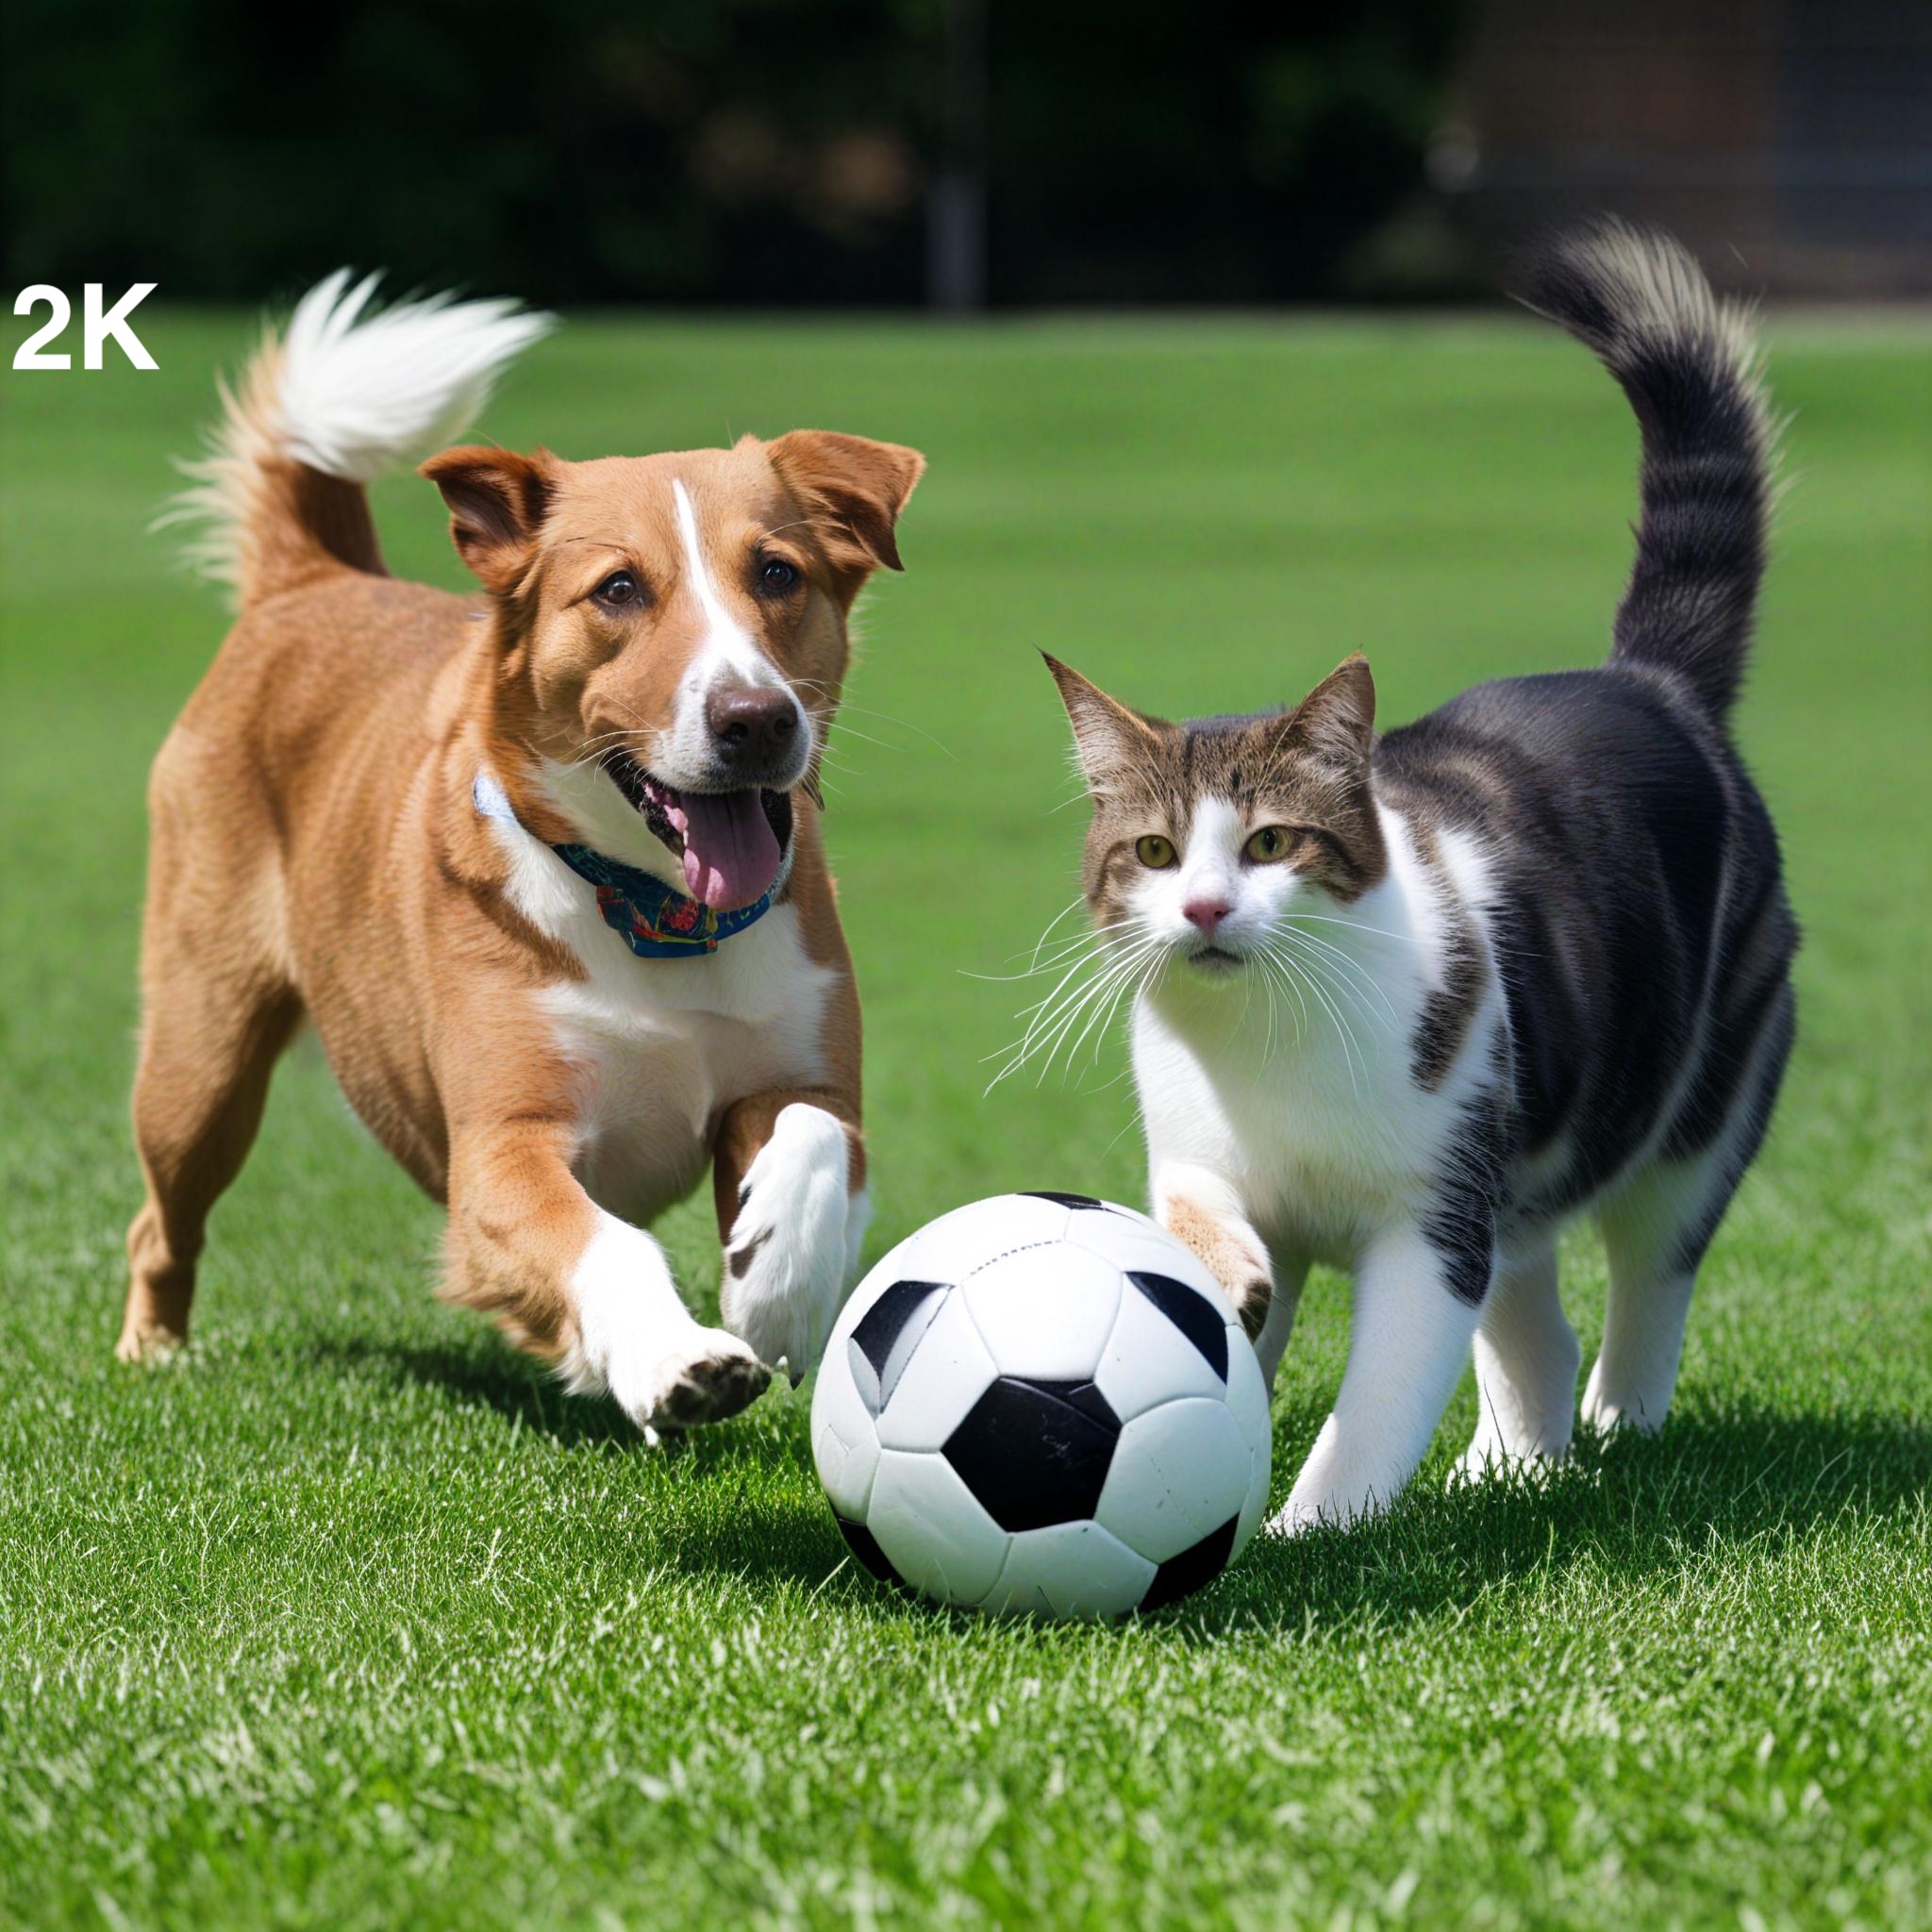
🐶 和 🐱 玩 ⚽ |
For research purposes, we recommend our
generative-models
Github repository (
https://github.com/NVlabs/Sana
),
which is more suitable for both training and inference and for which most advanced diffusion sampler like Flow-DPM-Solver is integrated.
MIT Han-Lab
provides free Sana inference.
Refer to original GitHub guidance to use the .pth model in Sana official code repo:
import torch
from app.sana_pipeline import SanaPipeline
from torchvision.utils import save_image

device = torch.device("cuda:0" if torch.cuda.is_available() else "cpu")
generator = torch.Generator(device=device).manual_seed(42)

sana = SanaPipeline("configs/sana_config/2048ms/Sana_1600M_img2048.yaml")
sana.from_pretrained("hf://Efficient-Large-Model/Sana_1600M_2Kpx_BF16/checkpoints/Sana_1600M_2Kpx_BF16.pth")
prompt = 'a cyberpunk cat with a neon sign that says "Sana"'

image = sana(
    prompt=prompt,
    height=2048,
    width=2048,
    guidance_scale=5.0,
    pag_guidance_scale=2.0,
    num_inference_steps=20,
    generator=generator,
)
save_image(image, 'output/sana.png', nrow=1, normalize=True, value_range=(-1, 1))
The model is intended for research purposes only. Possible research areas and tasks include
Generation of artworks and use in design and other artistic processes.
Applications in educational or creative tools.
Research on generative models.
Safe deployment of models which have the potential to generate harmful content.
Probing and understanding the limitations and biases of generative models.
Excluded uses are described below.
The model was not trained to be factual or true representations of people or events, and therefore using the model to generate such content is out-of-scope for the abilities of this model.
While the capabilities of image generation models are impressive, they can also reinforce or exacerbate social biases.