



Total runs:
55.5K
Run Growth:
-59.7K
Growth Rate:
-107.64%


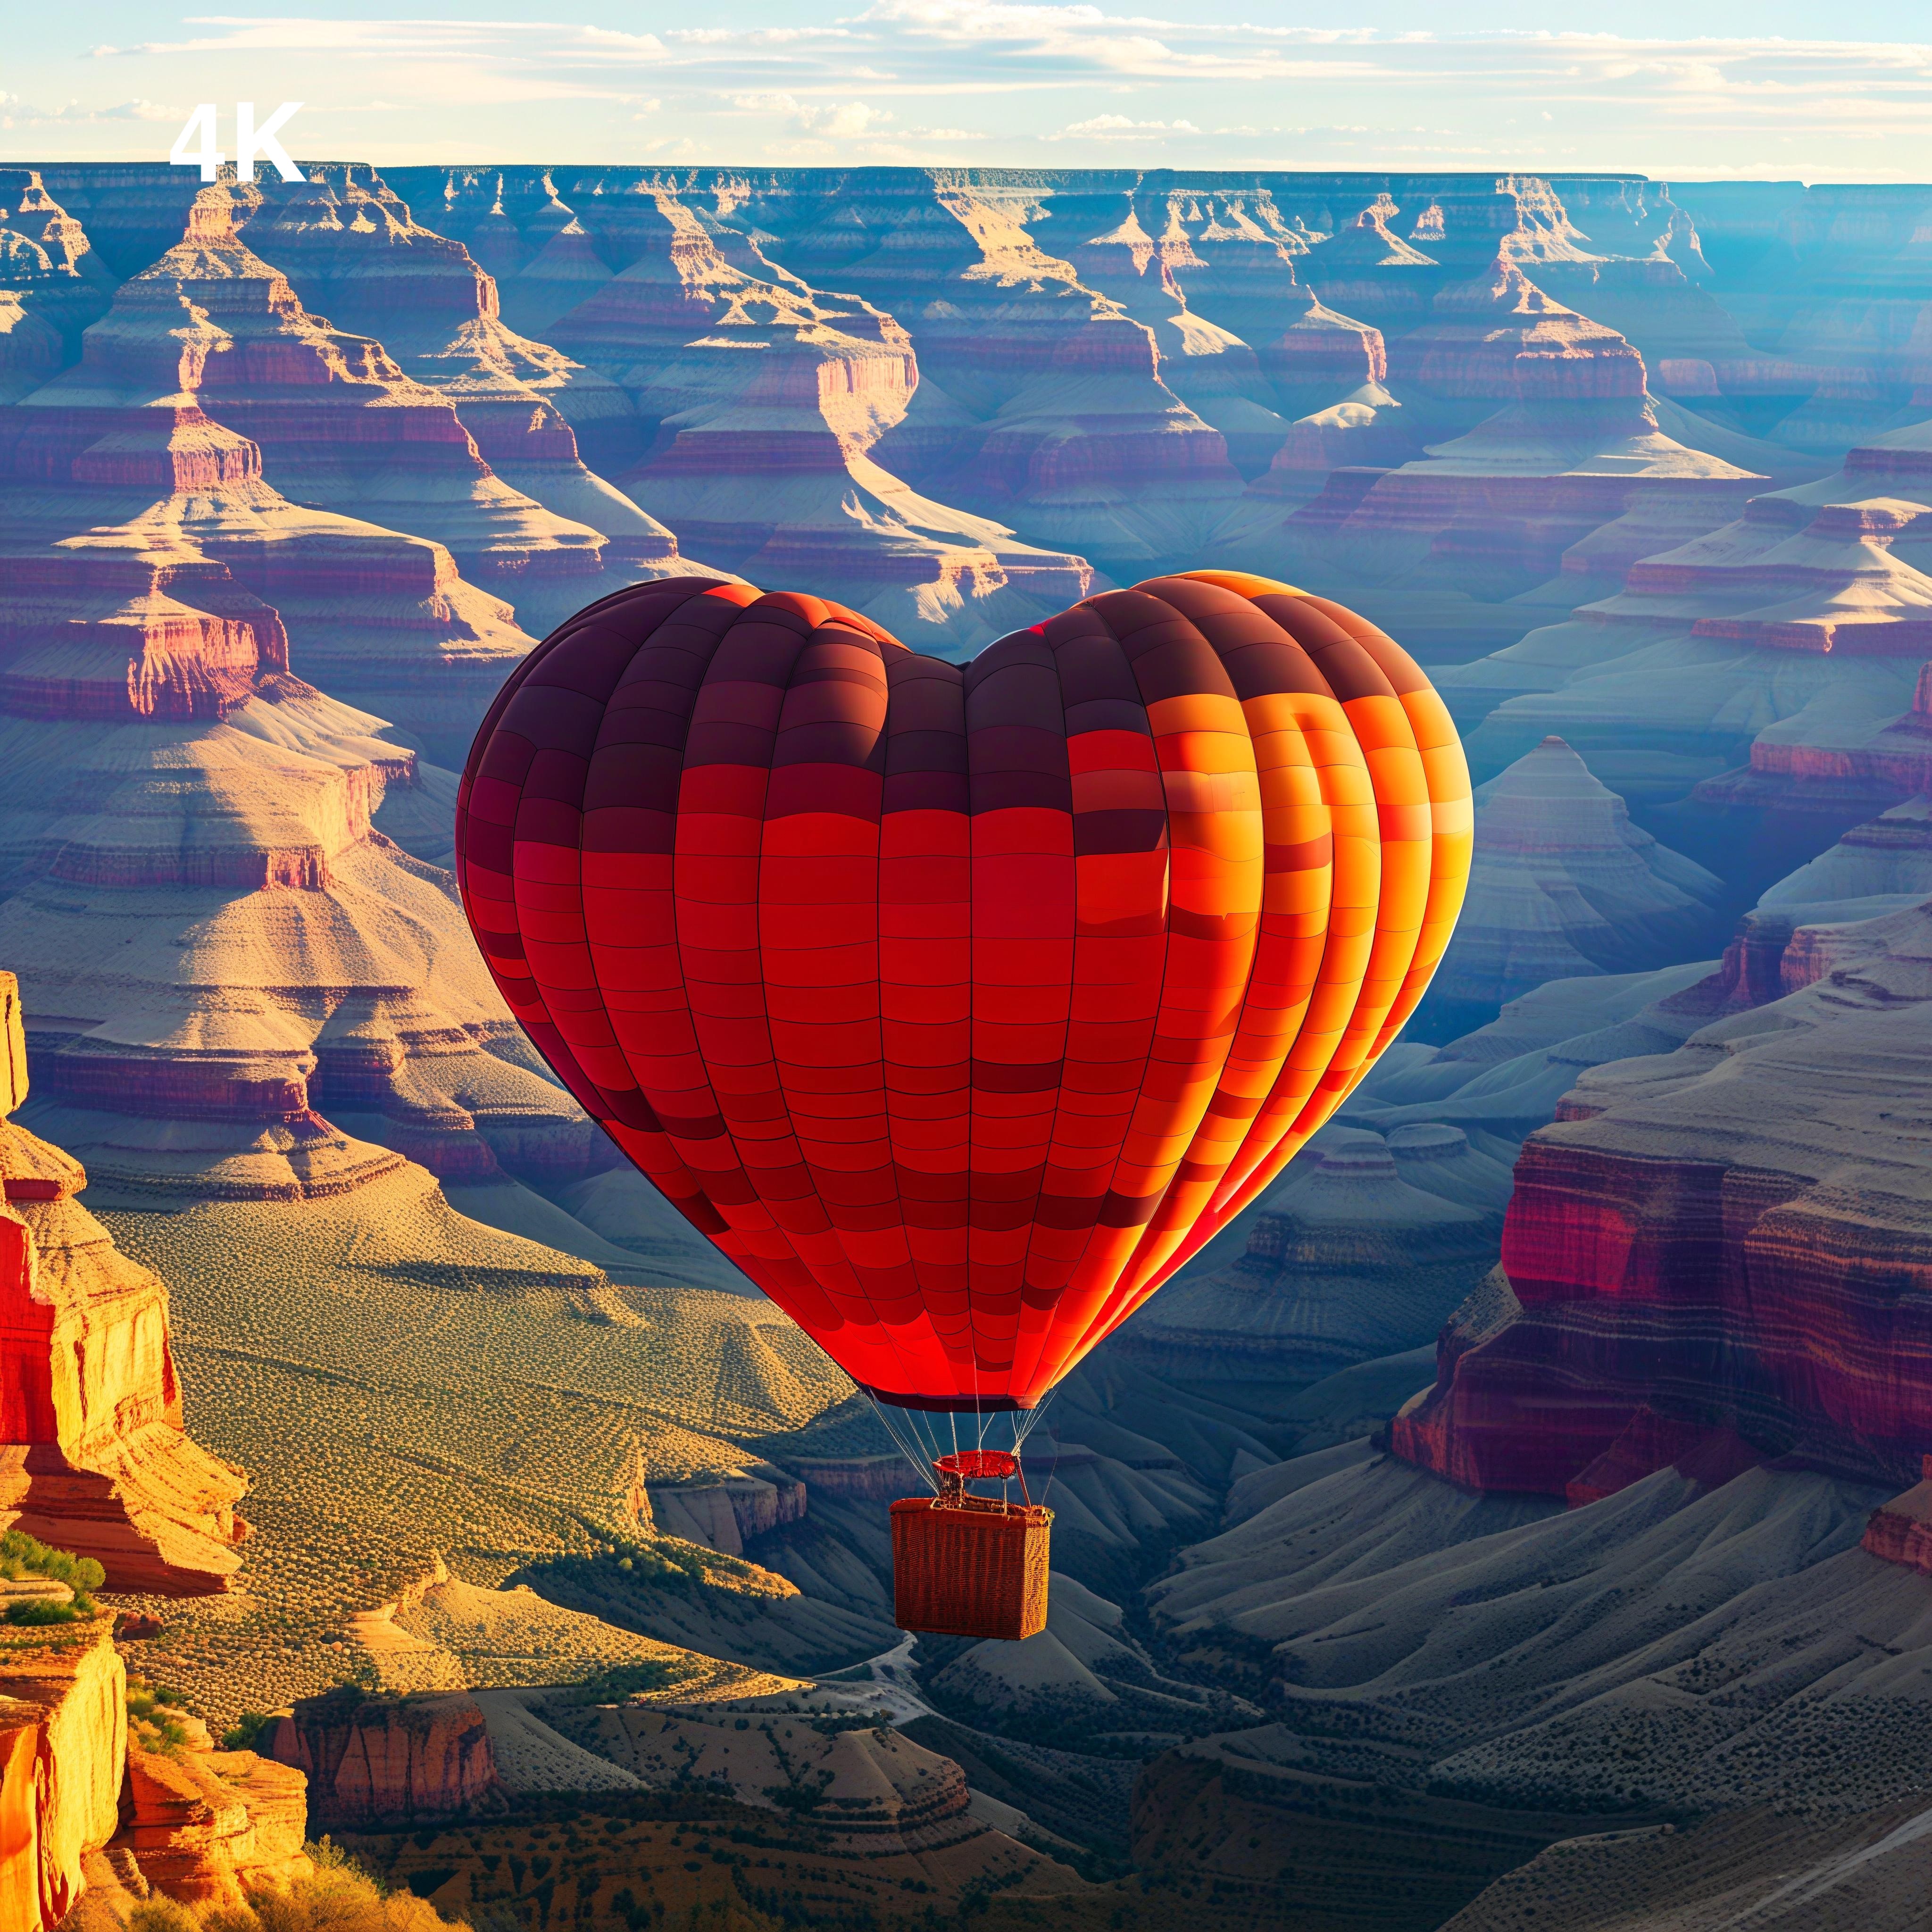
We introduce Sana , a text-to-image framework that can efficiently generate images up to 4096 × 4096 resolution. Sana can synthesize high-resolution, high-quality images with strong text-image alignment at a remarkably fast speed, deployable on laptop GPU.
Source code is available at https://github.com/NVlabs/Sana .
| Images |
|
|
|
|
|---|---|---|---|---|
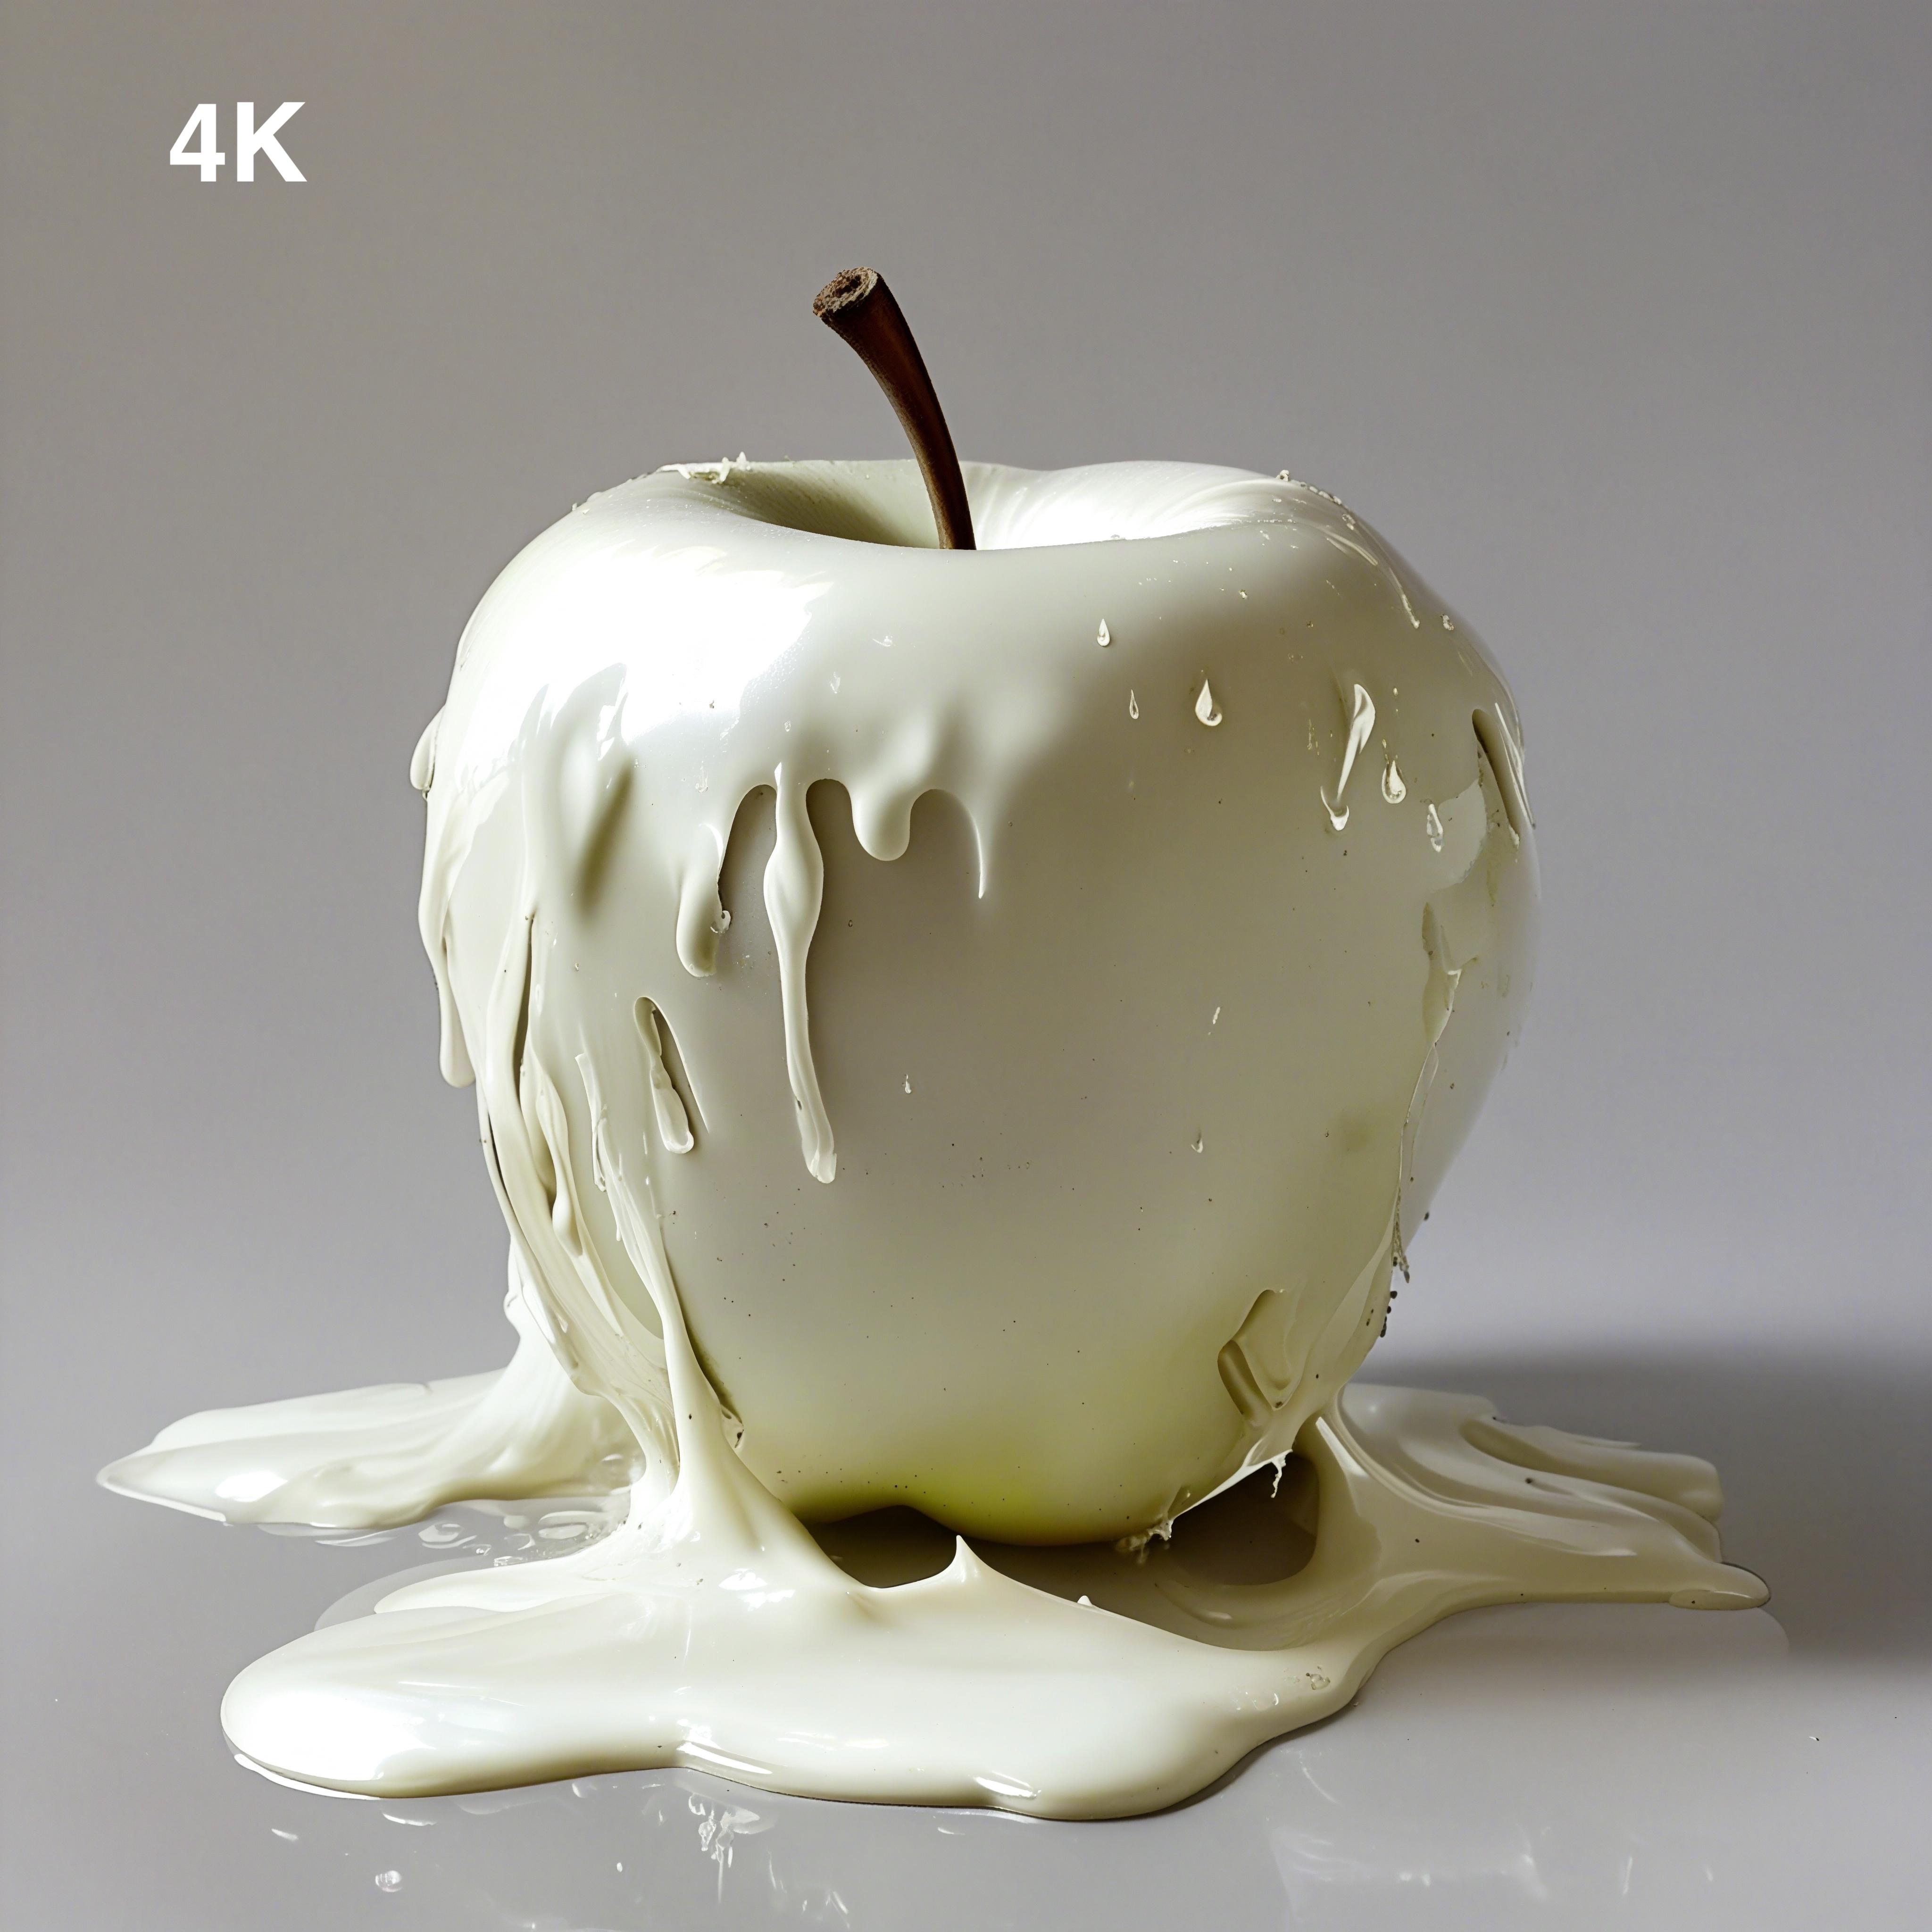
| prompt | A hot air balloon in the shape of a heart. Grand Canyon | a melting apple |
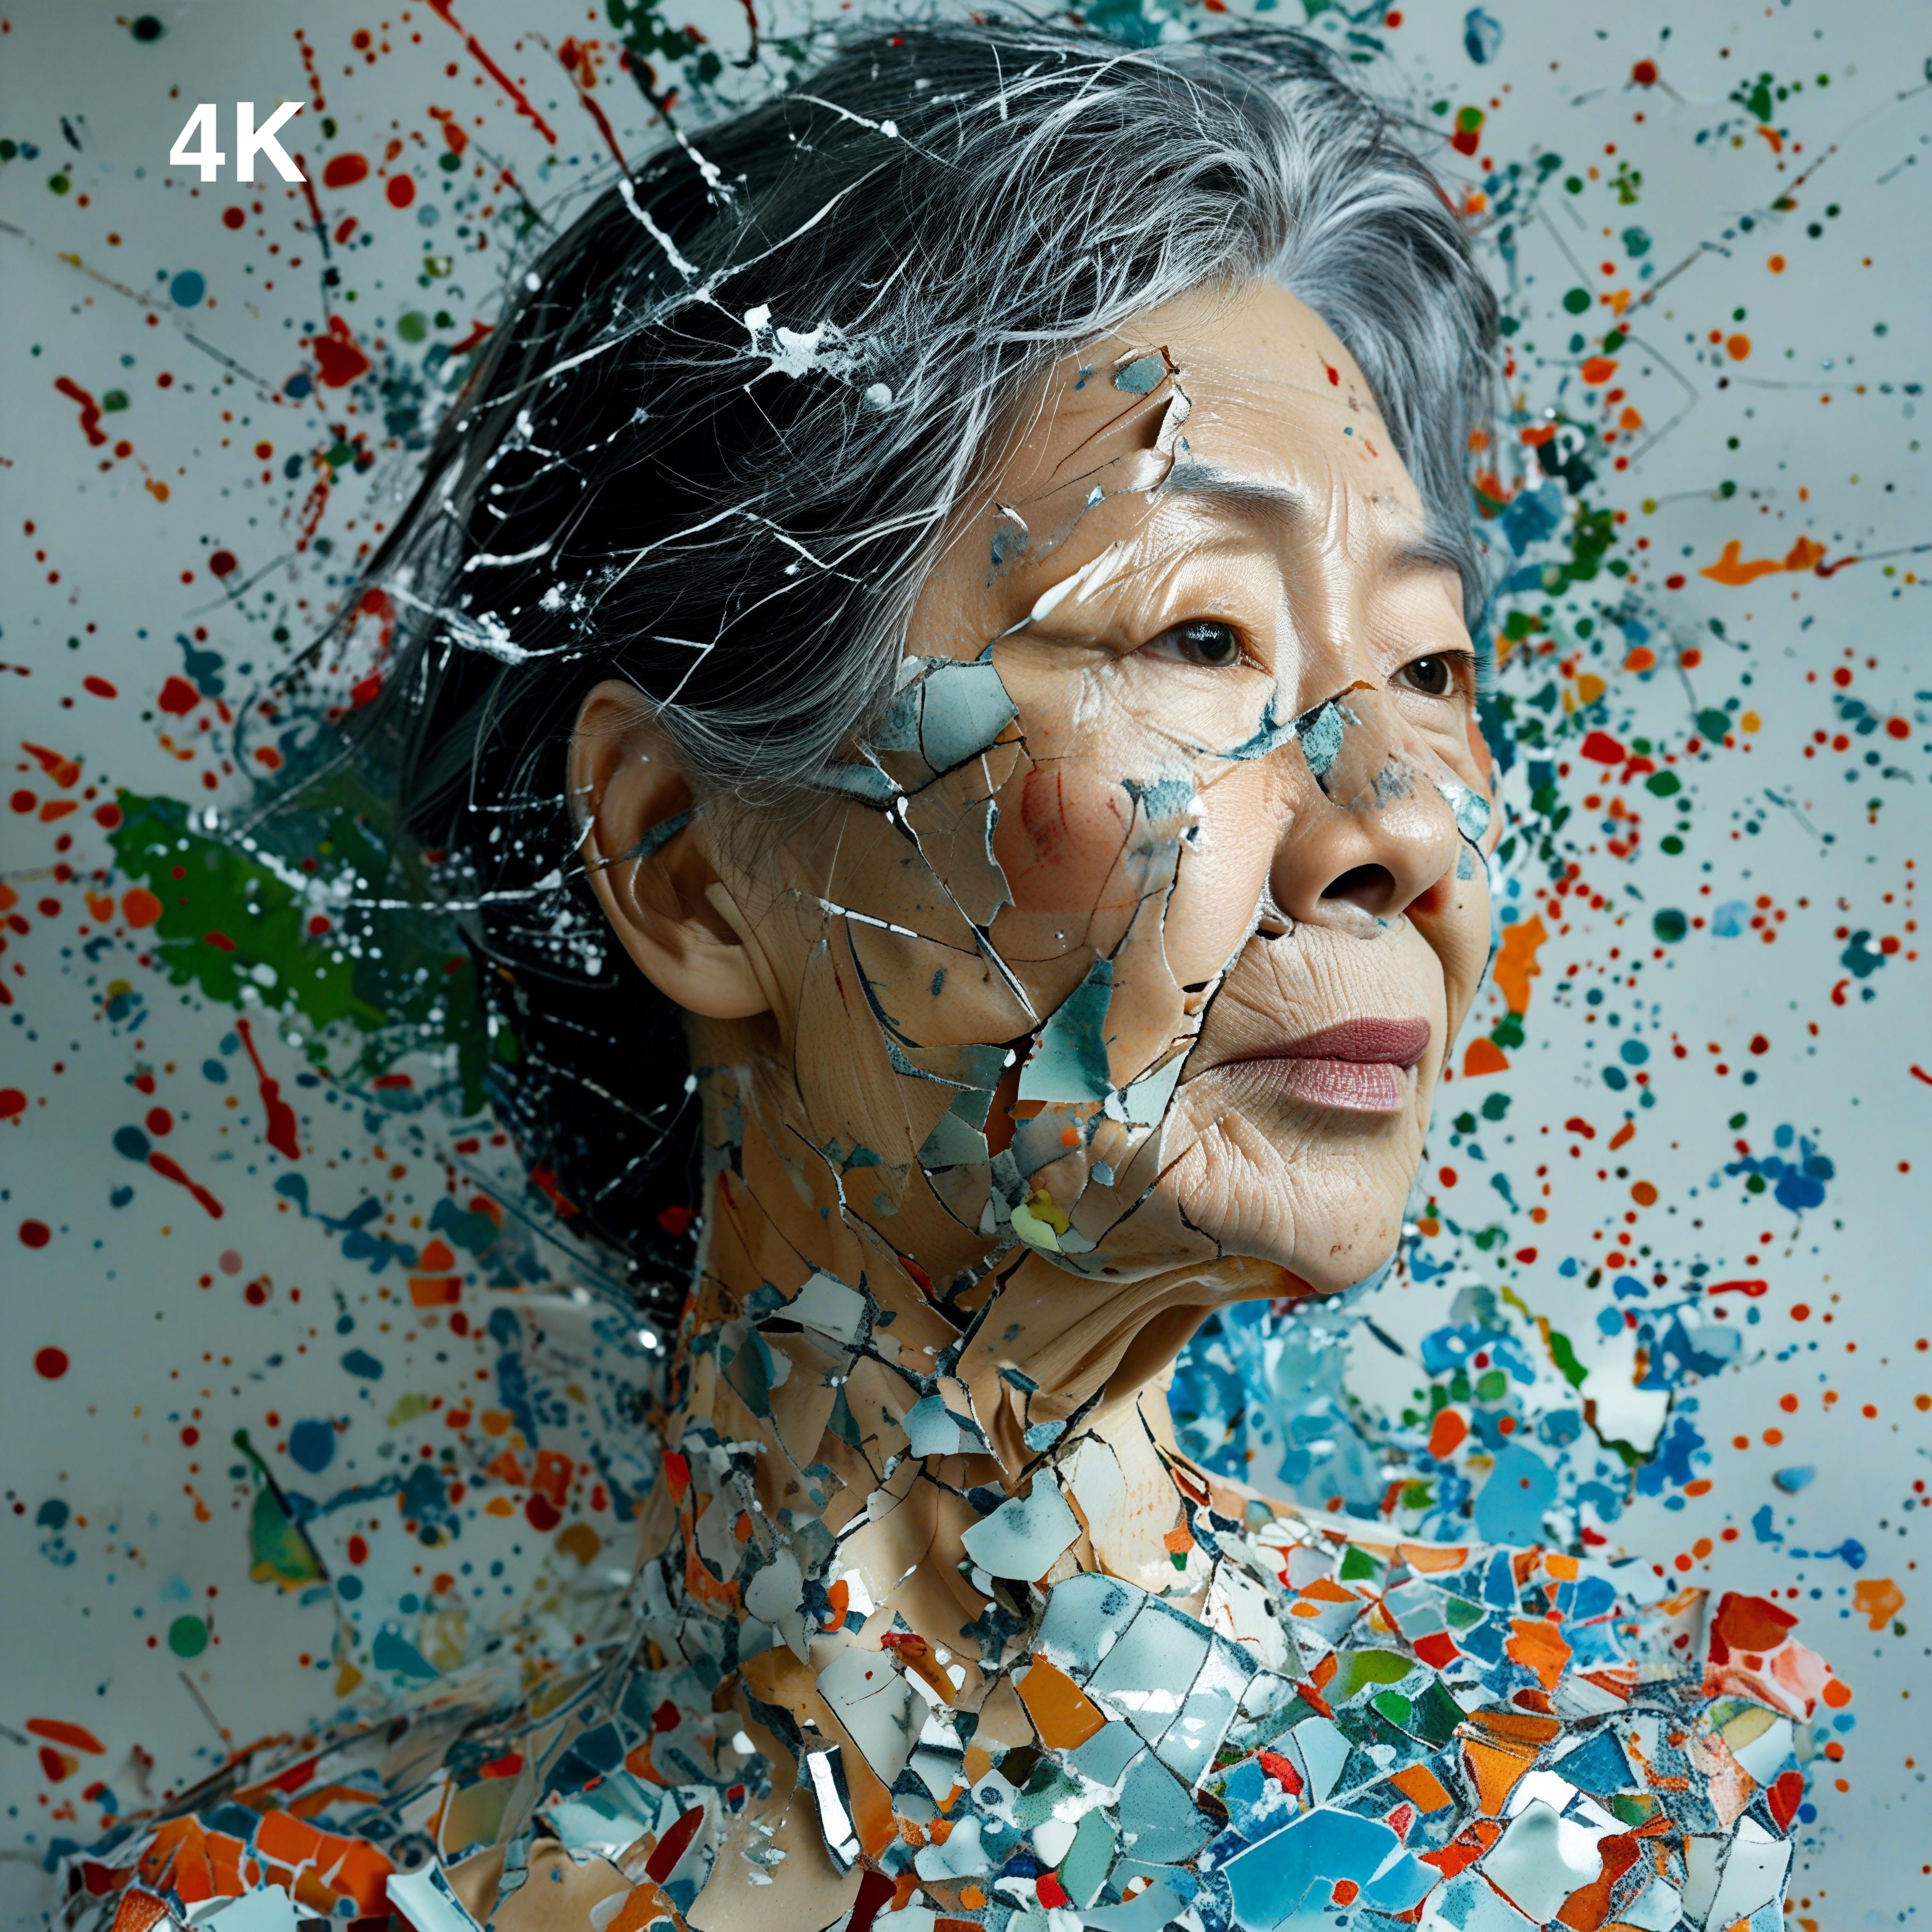
A middle-aged woman of Asian descent, her dark hair streaked with silver, appears fractured and splintered, intricately embedded within a sea of broken porcelain. The porcelain glistens with splatter paint patterns in a harmonious blend of glossy and matte blues, greens, oranges, and reds, capturing her dance in a surreal juxtaposition of movement and stillness. Her skin tone, a light hue like the porcelain, adds an almost mystical quality to her form. |
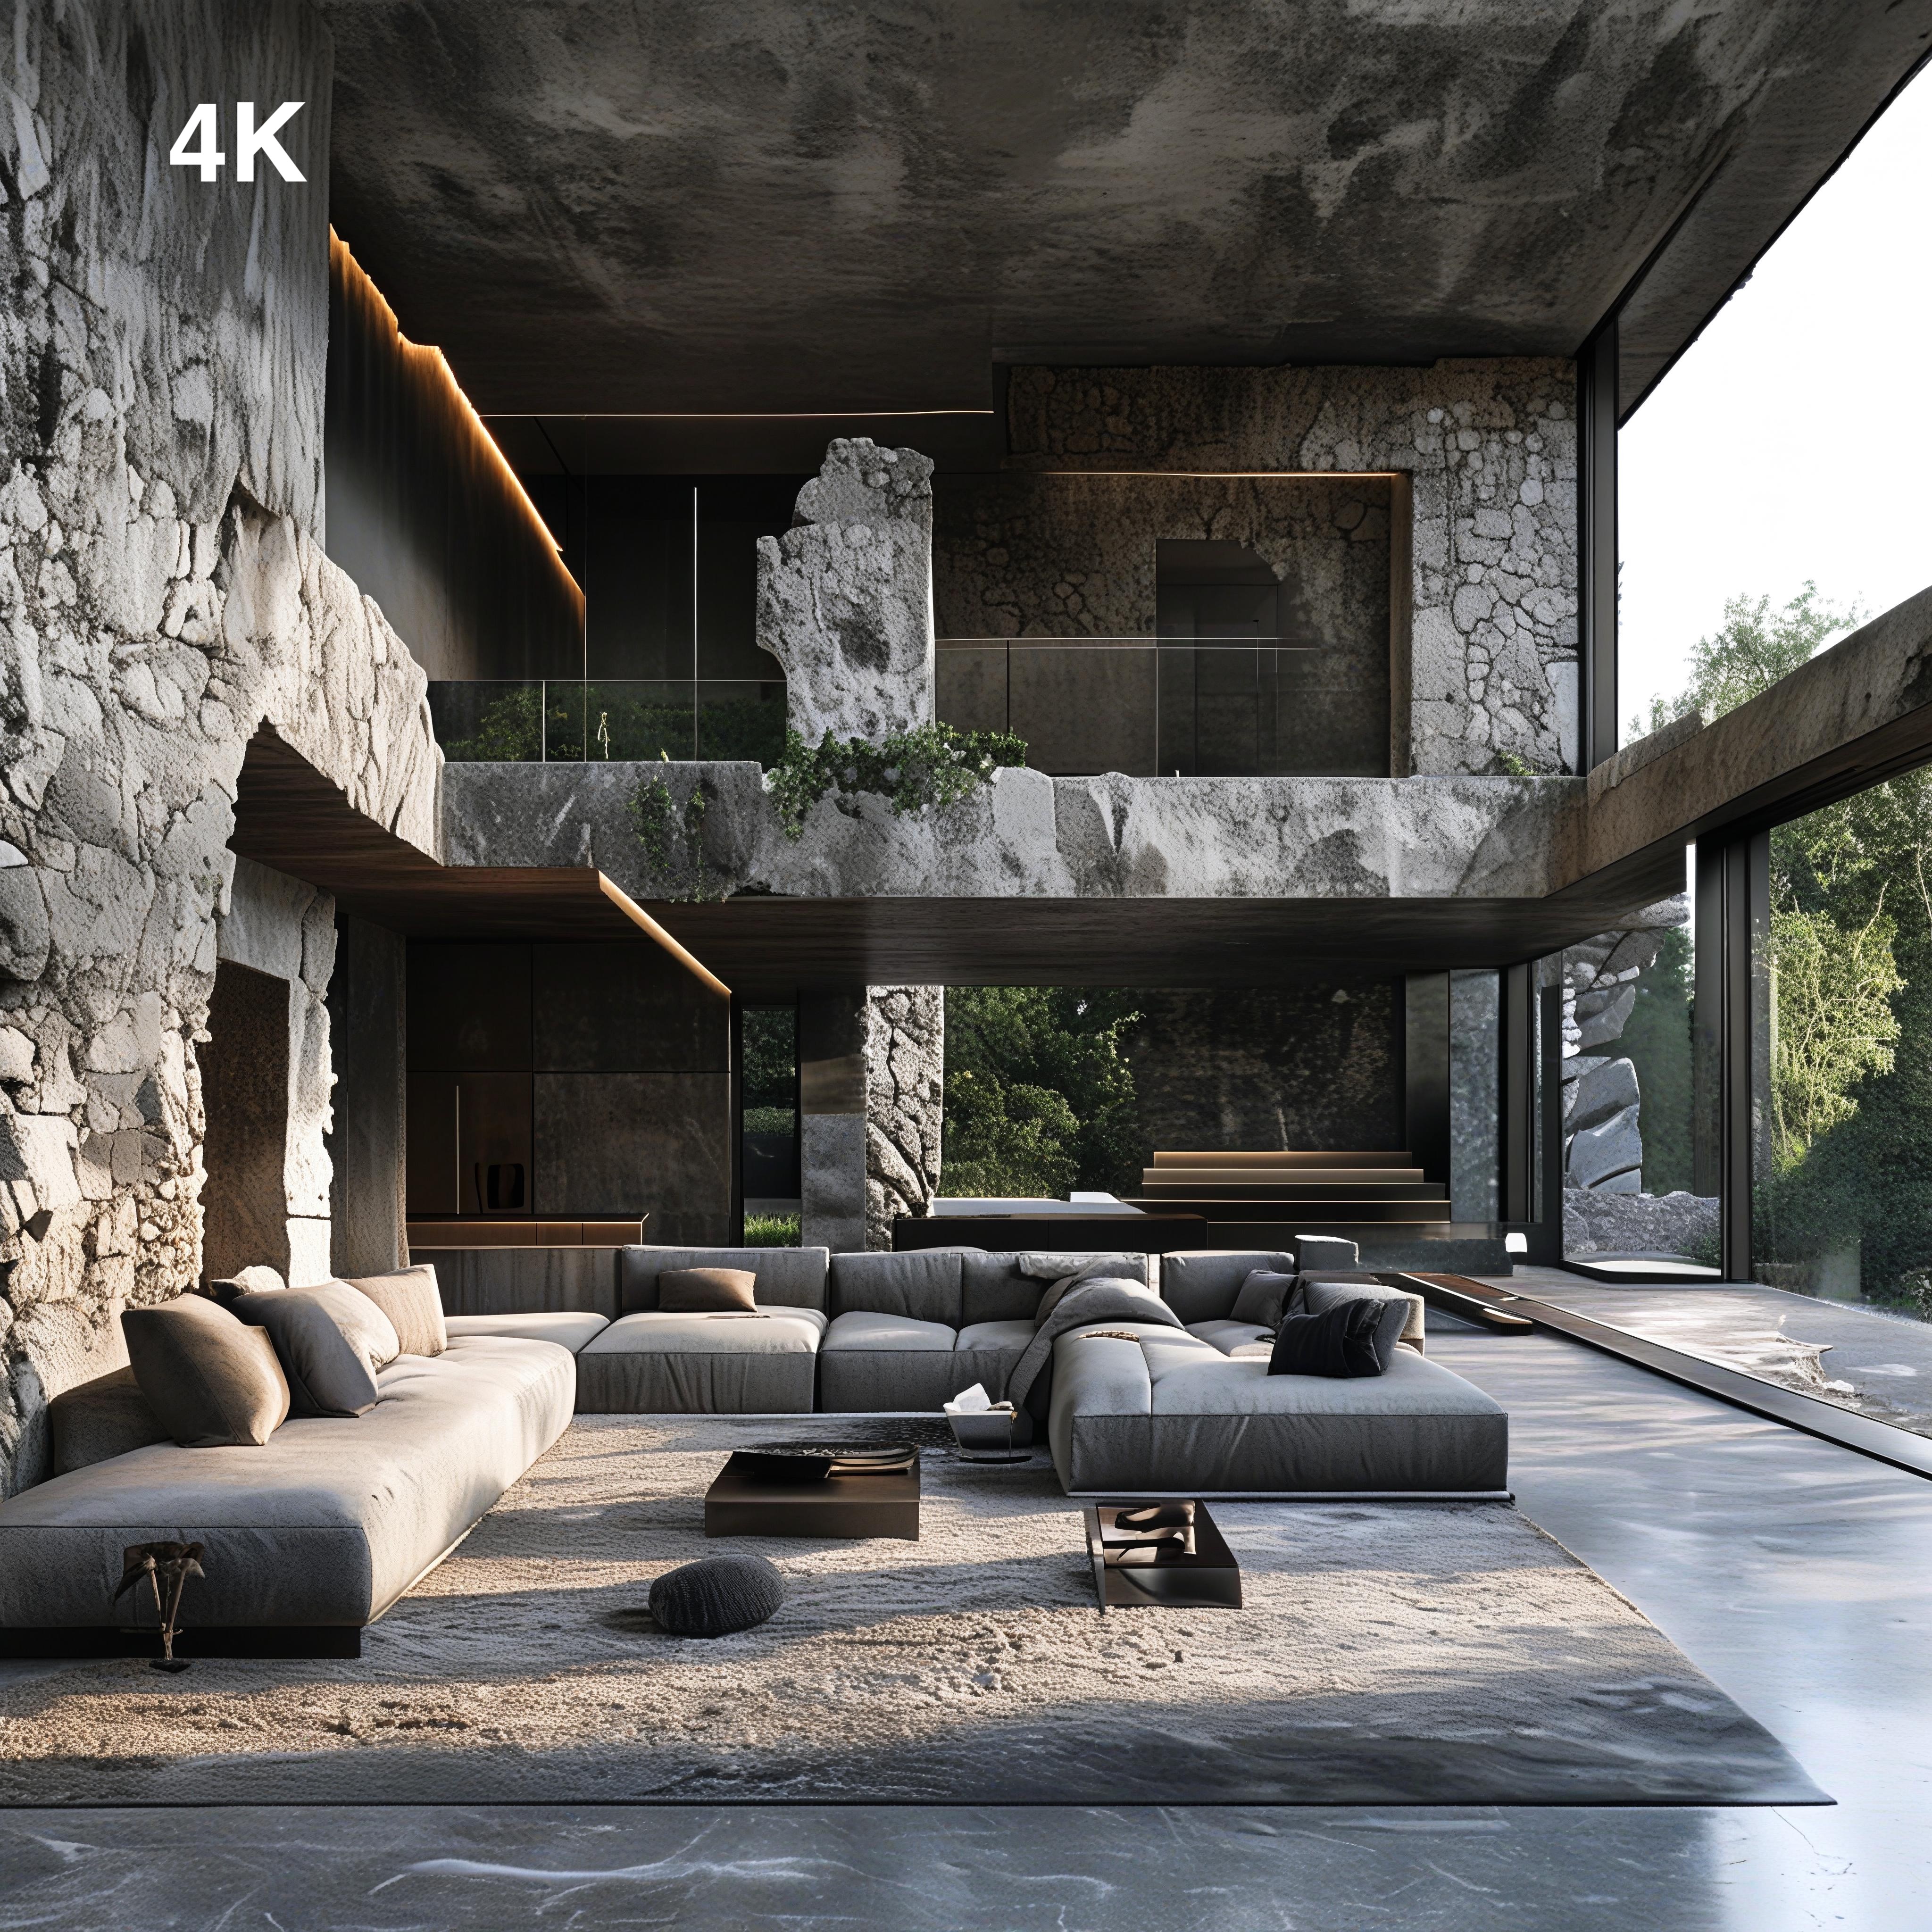
Modern luxury contemporary luxury home interiors house, in the style of mimicking ruined materials, ray tracing, haunting houses, and stone, capture the essence of nature, gray and bronze, dynamic outdoor shots. |
For research purposes, we recommend our
generative-models
Github repository (
https://github.com/NVlabs/Sana
),
which is more suitable for both training and inference and for which most advanced diffusion sampler like Flow-DPM-Solver is integrated.
MIT Han-Lab
provides free Sana inference.
Refer to original GitHub guidance to use the .pth model in Sana official code repo:
import torch
from app.sana_pipeline import SanaPipeline
from torchvision.utils import save_image

device = torch.device("cuda:0" if torch.cuda.is_available() else "cpu")
generator = torch.Generator(device=device).manual_seed(42)

sana = SanaPipeline("configs/sana_config/4096ms/Sana_1600M_img4096_bf16.yaml")
sana.from_pretrained("hf://Efficient-Large-Model/Sana_1600M_4Kpx_BF16/checkpoints/Sana_1600M_4Kpx_BF16.pth")
prompt = 'a cyberpunk cat with a neon sign that says "Sana"'

image = sana(
    prompt=prompt,
    height=4096,
    width=4096,
    guidance_scale=5.0,
    pag_guidance_scale=2.0,
    num_inference_steps=20,
    generator=generator,
)
save_image(image, 'output/sana_4K.png', nrow=1, normalize=True, value_range=(-1, 1))
The model is intended for research purposes only. Possible research areas and tasks include
Generation of artworks and use in design and other artistic processes.
Applications in educational or creative tools.
Research on generative models.
Safe deployment of models which have the potential to generate harmful content.
Probing and understanding the limitations and biases of generative models.
Excluded uses are described below.
The model was not trained to be factual or true representations of people or events, and therefore using the model to generate such content is out-of-scope for the abilities of this model.
While the capabilities of image generation models are impressive, they can also reinforce or exacerbate social biases.