




Total runs:
427.1K
Run Growth:
32.9K
Growth Rate:
7.70%

TheBloke's LLM work is generously supported by a grant from andreessen horowitz (a16z)
This repo contains GGUF format model files for Bud's GenZ 70B .
GGUF is a new format introduced by the llama.cpp team on August 21st 2023. It is a replacement for GGML, which is no longer supported by llama.cpp. GGUF offers numerous advantages over GGML, such as better tokenisation, and support for special tokens. It is also supports metadata, and is designed to be extensible.
Here is an incomplate list of clients and libraries that are known to support GGUF:
### User:
{prompt}

### Assistant:
These quantised GGUFv2 files are compatible with llama.cpp from August 27th onwards, as of commit d0cee0d36d5be95a0d9088b674dbb27354107221
They are also compatible with many third party UIs and libraries - please see the list at the top of this README.
The new methods available are:
Refer to the Provided Files table below to see what files use which methods, and how.
| Name | Quant method | Bits | Size | Max RAM required | Use case |
|---|---|---|---|---|---|
| genz-70b.Q2_K.gguf | Q2_K | 2 | 29.28 GB | 31.78 GB | smallest, significant quality loss - not recommended for most purposes |
| genz-70b.Q3_K_S.gguf | Q3_K_S | 3 | 29.92 GB | 32.42 GB | very small, high quality loss |
| genz-70b.Q3_K_M.gguf | Q3_K_M | 3 | 33.19 GB | 35.69 GB | very small, high quality loss |
| genz-70b.Q3_K_L.gguf | Q3_K_L | 3 | 36.15 GB | 38.65 GB | small, substantial quality loss |
| genz-70b.Q4_0.gguf | Q4_0 | 4 | 38.87 GB | 41.37 GB | legacy; small, very high quality loss - prefer using Q3_K_M |
| genz-70b.Q4_K_S.gguf | Q4_K_S | 4 | 39.07 GB | 41.57 GB | small, greater quality loss |
| genz-70b.Q4_K_M.gguf | Q4_K_M | 4 | 41.42 GB | 43.92 GB | medium, balanced quality - recommended |
| genz-70b.Q5_0.gguf | Q5_0 | 5 | 47.46 GB | 49.96 GB | legacy; medium, balanced quality - prefer using Q4_K_M |
| genz-70b.Q5_K_S.gguf | Q5_K_S | 5 | 47.46 GB | 49.96 GB | large, low quality loss - recommended |
| genz-70b.Q5_K_M.gguf | Q5_K_M | 5 | 48.75 GB | 51.25 GB | large, very low quality loss - recommended |
| genz-70b.Q6_K.gguf | Q6_K | 6 | 56.59 GB | 59.09 GB | very large, extremely low quality loss |
| genz-70b.Q8_0.gguf | Q8_0 | 8 | 73.29 GB | 75.79 GB | very large, extremely low quality loss - not recommended |
Note : the above RAM figures assume no GPU offloading. If layers are offloaded to the GPU, this will reduce RAM usage and use VRAM instead.
Note: HF does not support uploading files larger than 50GB. Therefore I have uploaded the Q6_K and Q8_0 files as split files.
Please download:
genz-70b.Q6_K.gguf-split-a
genz-70b.Q6_K.gguf-split-b
Please download:
genz-70b.Q8_0.gguf-split-a
genz-70b.Q8_0.gguf-split-b
To join the files, do the following:
Linux and macOS:
cat genz-70b.Q6_K.gguf-split-* > genz-70b.Q6_K.gguf && rm genz-70b.Q6_K.gguf-split-*
cat genz-70b.Q8_0.gguf-split-* > genz-70b.Q8_0.gguf && rm genz-70b.Q8_0.gguf-split-*
Windows command line:
COPY /B genz-70b.Q6_K.gguf-split-a + genz-70b.Q6_K.gguf-split-b genz-70b.Q6_K.gguf
del genz-70b.Q6_K.gguf-split-a genz-70b.Q6_K.gguf-split-b

COPY /B genz-70b.Q8_0.gguf-split-a + genz-70b.Q8_0.gguf-split-b genz-70b.Q8_0.gguf
del genz-70b.Q8_0.gguf-split-a genz-70b.Q8_0.gguf-split-b
Note for manual downloaders: You almost never want to clone the entire repo! Multiple different quantisation formats are provided, and most users only want to pick and download a single file.
The following clients/libraries will automatically download models for you, providing a list of available models to choose from:
text-generation-webui
Under Download Model, you can enter the model repo: TheBloke/Genz-70b-GGUF and below it, a specific filename to download, such as: genz-70b.q4_K_M.gguf.
Then click Download.
I recommend using the
huggingface-hub
Python library:
pip3 install huggingface-hub>=0.17.1
Then you can download any individual model file to the current directory, at high speed, with a command like this:
huggingface-cli download TheBloke/Genz-70b-GGUF genz-70b.q4_K_M.gguf --local-dir . --local-dir-use-symlinks False
You can also download multiple files at once with a pattern:
huggingface-cli download TheBloke/Genz-70b-GGUF --local-dir . --local-dir-use-symlinks False --include='*Q4_K*gguf'
For more documentation on downloading with
huggingface-cli
, please see:
HF -> Hub Python Library -> Download files -> Download from the CLI
.
To accelerate downloads on fast connections (1Gbit/s or higher), install
hf_transfer
:
pip3 install hf_transfer
And set environment variable
HF_HUB_ENABLE_HF_TRANSFER
to
1
:
HUGGINGFACE_HUB_ENABLE_HF_TRANSFER=1 huggingface-cli download TheBloke/Genz-70b-GGUF genz-70b.q4_K_M.gguf --local-dir . --local-dir-use-symlinks False
Windows CLI users: Use
set HUGGINGFACE_HUB_ENABLE_HF_TRANSFER=1
before running the download command.
llama.cpp
command
Make sure you are using
llama.cpp
from commit
d0cee0d36d5be95a0d9088b674dbb27354107221
or later.
./main -ngl 32 -m genz-70b.q4_K_M.gguf --color -c 4096 --temp 0.7 --repeat_penalty 1.1 -n -1 -p "### User:\n{prompt}\n\n### Assistant:"
Change
-ngl 32
to the number of layers to offload to GPU. Remove it if you don't have GPU acceleration.
Change
-c 4096
to the desired sequence length. For extended sequence models - eg 8K, 16K, 32K - the necessary RoPE scaling parameters are read from the GGUF file and set by llama.cpp automatically.
If you want to have a chat-style conversation, replace the
-p <PROMPT>
argument with
-i -ins
For other parameters and how to use them, please refer to the llama.cpp documentation
text-generation-webui
Further instructions here: text-generation-webui/docs/llama.cpp.md .
You can use GGUF models from Python using the llama-cpp-python or ctransformers libraries.
# Base ctransformers with no GPU acceleration
pip install ctransformers>=0.2.24
# Or with CUDA GPU acceleration
pip install ctransformers[cuda]>=0.2.24
# Or with ROCm GPU acceleration
CT_HIPBLAS=1 pip install ctransformers>=0.2.24 --no-binary ctransformers
# Or with Metal GPU acceleration for macOS systems
CT_METAL=1 pip install ctransformers>=0.2.24 --no-binary ctransformers
from ctransformers import AutoModelForCausalLM

# Set gpu_layers to the number of layers to offload to GPU. Set to 0 if no GPU acceleration is available on your system.
llm = AutoModelForCausalLM.from_pretrained("TheBloke/Genz-70b-GGUF", model_file="genz-70b.q4_K_M.gguf", model_type="llama", gpu_layers=50)

print(llm("AI is going to"))
Here's guides on using llama-cpp-python or ctransformers with LangChain:
For further support, and discussions on these models and AI in general, join us at:
Thanks to the chirper.ai team!
Thanks to Clay from gpus.llm-utils.org !
I've had a lot of people ask if they can contribute. I enjoy providing models and helping people, and would love to be able to spend even more time doing it, as well as expanding into new projects like fine tuning/training.
If you're able and willing to contribute it will be most gratefully received and will help me to keep providing more models, and to start work on new AI projects.
Donaters will get priority support on any and all AI/LLM/model questions and requests, access to a private Discord room, plus other benefits.
Special thanks to : Aemon Algiz.
Patreon special mentions : Alicia Loh, Stephen Murray, K, Ajan Kanaga, RoA, Magnesian, Deo Leter, Olakabola, Eugene Pentland, zynix, Deep Realms, Raymond Fosdick, Elijah Stavena, Iucharbius, Erik Bjäreholt, Luis Javier Navarrete Lozano, Nicholas, theTransient, John Detwiler, alfie_i, knownsqashed, Mano Prime, Willem Michiel, Enrico Ros, LangChain4j, OG, Michael Dempsey, Pierre Kircher, Pedro Madruga, James Bentley, Thomas Belote, Luke @flexchar, Leonard Tan, Johann-Peter Hartmann, Illia Dulskyi, Fen Risland, Chadd, S_X, Jeff Scroggin, Ken Nordquist, Sean Connelly, Artur Olbinski, Swaroop Kallakuri, Jack West, Ai Maven, David Ziegler, Russ Johnson, transmissions 11, John Villwock, Alps Aficionado, Clay Pascal, Viktor Bowallius, Subspace Studios, Rainer Wilmers, Trenton Dambrowitz, vamX, Michael Levine, 준교 김, Brandon Frisco, Kalila, Trailburnt, Randy H, Talal Aujan, Nathan Dryer, Vadim, 阿明, ReadyPlayerEmma, Tiffany J. Kim, George Stoitzev, Spencer Kim, Jerry Meng, Gabriel Tamborski, Cory Kujawski, Jeffrey Morgan, Spiking Neurons AB, Edmond Seymore, Alexandros Triantafyllidis, Lone Striker, Cap'n Zoog, Nikolai Manek, danny, ya boyyy, Derek Yates, usrbinkat, Mandus, TL, Nathan LeClaire, subjectnull, Imad Khwaja, webtim, Raven Klaugh, Asp the Wyvern, Gabriel Puliatti, Caitlyn Gatomon, Joseph William Delisle, Jonathan Leane, Luke Pendergrass, SuperWojo, Sebastain Graf, Will Dee, Fred von Graf, Andrey, Dan Guido, Daniel P. Andersen, Nitin Borwankar, Elle, Vitor Caleffi, biorpg, jjj, NimbleBox.ai, Pieter, Matthew Berman, terasurfer, Michael Davis, Alex, Stanislav Ovsiannikov
Thank you to all my generous patrons and donaters!
And thank you again to a16z for their generous grant.
Democratizing access to LLMs for the open-source community.
Let's advance AI, together.
Welcome to GenZ , an advanced Large Language Model (LLM) fine-tuned on the foundation of Meta's open-source Llama V2 70B parameter model. At Bud Ecosystem, we believe in the power of open-source collaboration to drive the advancement of technology at an accelerated pace. Our vision is to democratize access to fine-tuned LLMs, and to that end, we will be releasing a series of models across different parameter counts (7B, 13B, and 70B) and quantizations (32-bit and 4-bit) for the open-source community to use, enhance, and build upon.
The smaller quantization version of our models makes them more accessible, enabling their use even on personal computers. This opens up a world of possibilities for developers, researchers, and enthusiasts to experiment with these models and contribute to the collective advancement of language model technology.
GenZ isn't just a powerful text generator—it's a sophisticated AI assistant, capable of understanding and responding to user prompts with high-quality responses. We've taken the robust capabilities of Llama V2 and fine-tuned them to offer a more user-focused experience. Whether you're seeking informative responses or engaging interactions, GenZ is designed to deliver.
And this isn't the end. It's just the beginning of a journey towards creating more advanced, more efficient, and more accessible language models. We invite you to join us on this exciting journey. 🚀
[21 August 2023] GenZ-70B : We're excited to announce the release of our Genz 70BB model. Experience the advancements by downloading the model from HuggingFace .
[27 July 2023] GenZ-13B V2 (ggml) : Announcing our GenZ-13B v2 with ggml. This variant of GenZ can run inferencing using only CPU and without the need of GPU. Download the model from HuggingFace .
[27 July 2023] GenZ-13B V2 (4-bit) : Announcing our GenZ-13B v2 with 4-bit quantisation. Enabling inferencing with much lesser GPU memory than the 32-bit variant. Download the model from HuggingFace .
[26 July 2023] GenZ-13B V2 : We're excited to announce the release of our Genz 13B v2 model, a step forward with improved evaluation results compared to v1. Experience the advancements by downloading the model from HuggingFace .
[20 July 2023] GenZ-13B : We marked an important milestone with the release of the Genz 13B model. The journey began here, and you can partake in it by downloading the model from Hugging Face .
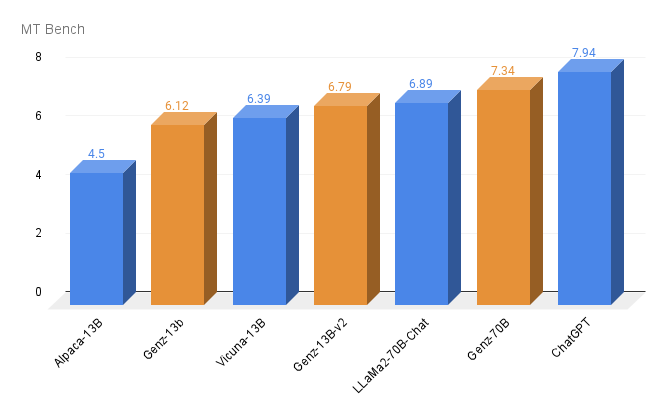
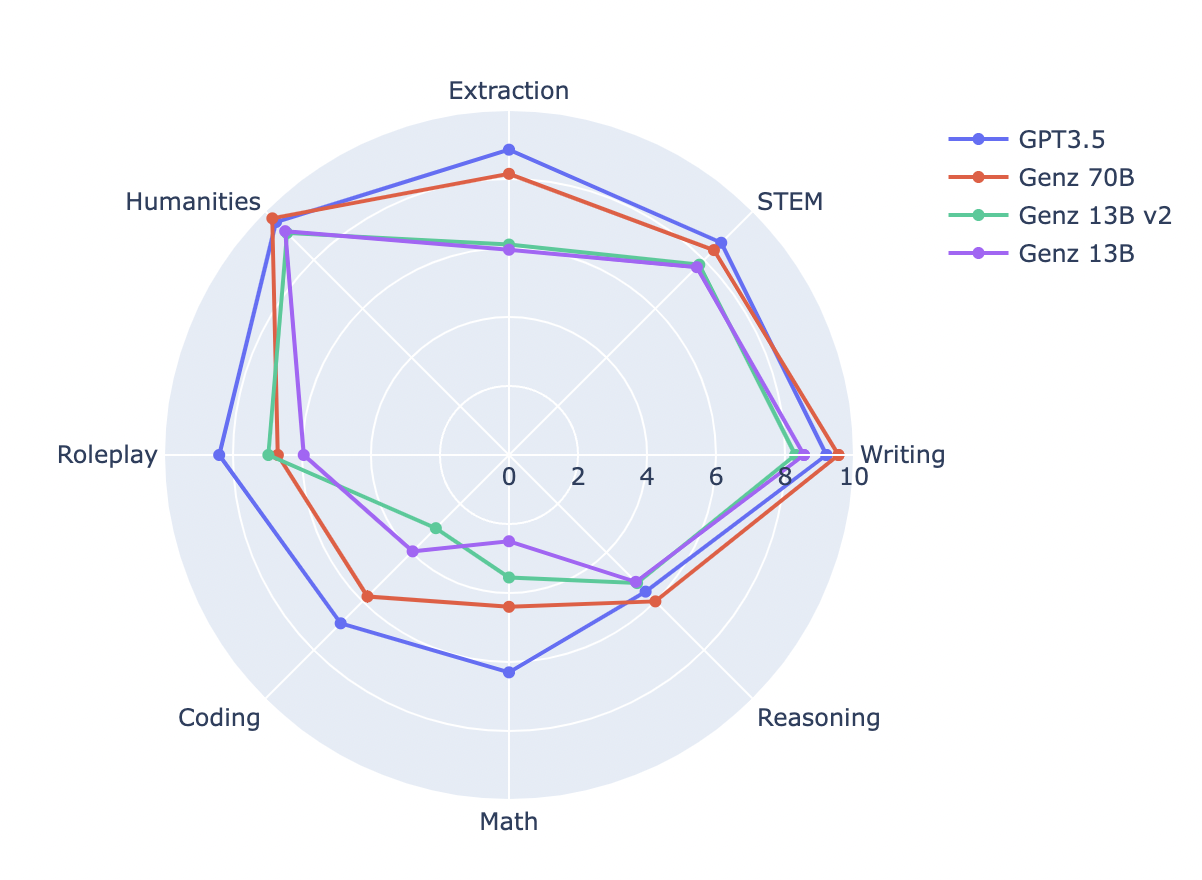
Evaluating our model is a key part of our fine-tuning process. It helps us understand how our model is performing and how it stacks up against other models. Here's a look at some of the key evaluations for GenZ 70B:
We've compared GenZ models to understand the improvements our fine-tuning has achieved.
| Model Name | MT Bench | MMLU | Human Eval | BBH |
|---|---|---|---|---|
| Genz 13B | 6.12 | 53.62 | 17.68 | 37.76 |
| Genz 13B v2 | 6.79 | 53.68 | 21.95 | 38.1 |
| Genz 70B | 7.33 | 70.32 | 37.8 | 54.69 |
A key evaluation metric we use is the MT Bench score. This score provides a comprehensive assessment of our model's performance across a range of tasks.
Getting up and running with our models on Hugging Face is a breeze. Follow these steps:
Start by importing the necessary modules from the ‘transformers’ library and ‘torch’.
import torch
from transformers import AutoTokenizer, AutoModelForCausalLM

tokenizer = AutoTokenizer.from_pretrained("budecosystem/genz-70b", trust_remote_code=True)
model = AutoModelForCausalLM.from_pretrained("budecosystem/genz-70b", torch_dtype=torch.bfloat16, rope_scaling={"type": "dynamic", "factor": 2})

prompt = "### User:\nWrite a python flask code for login management\n\n### Assistant:\n"

inputs = tokenizer(prompt, return_tensors="pt")
sample = model.generate(**inputs, max_length=128)
print(tokenizer.decode(sample[0]))
Want to interact with the model in a more intuitive way? We have a Gradio interface set up for that. Head over to our GitHub page, clone the repository, and run the ‘generate.py’ script to try it out. Happy experimenting! 😄
You might be wondering, "Why should I choose GenZ over a pretrained model?" The answer lies in the extra mile we've gone to fine-tune our models.
While pretrained models are undeniably powerful, GenZ brings something extra to the table. We've fine-tuned it with curated datasets, which means it has additional skills and capabilities beyond what a pretrained model can offer. Whether you need it for a simple task or a complex project, GenZ is up for the challenge.
What's more, we are committed to continuously enhancing GenZ. We believe in the power of constant learning and improvement. That's why we'll be regularly fine-tuning our models with various curated datasets to make them even better. Our goal is to reach the state of the art and beyond - and we're committed to staying the course until we get there.
But don't just take our word for it. We've provided detailed evaluations and performance details in a later section, so you can see the difference for yourself.
Choose GenZ and join us on this journey. Together, we can push the boundaries of what's possible with large language models.
Here's a quick overview of everything you need to know about GenZ 70B.
When we created GenZ 70B, we had a clear vision of how it could be used to push the boundaries of what's possible with large language models. We also understand the importance of using such models responsibly. Here's a brief overview of the intended and out-of-scope uses for GenZ 70B.
GenZ 70B is designed to be a powerful tool for research on large language models. It's also an excellent foundation for further specialization and fine-tuning for specific use cases, such as:
While GenZ 70B is versatile, there are certain uses that are out of scope:
Remember, GenZ 70B, like any large language model, is trained on a large-scale corpora representative of the web, and therefore, may carry the stereotypes and biases commonly encountered online.
We recommend users of GenZ 70B to consider fine-tuning it for the specific set of tasks of interest. Appropriate precautions and guardrails should be taken for any production use. Using GenZ 70B responsibly is key to unlocking its full potential while maintaining a safe and respectful environment.
When fine-tuning GenZ 70B, we took a meticulous approach to ensure we were building on the solid base of the pretrained Llama V2 70B model in the most effective way. Here's a look at the key details of our training process:
For the fine-tuning process, we used a carefully curated mix of datasets. These included data from OpenAssistant, an instruction fine-tuning dataset, and Thought Source for the Chain Of Thought (CoT) approach. This diverse mix of data sources helped us enhance the model's capabilities across a range of tasks.
Here are the hyperparameters we used for fine-tuning:
| Hyperparameter | Value |
|---|---|
| Warmup Ratio | 0.04 |
| Learning Rate Scheduler Type | Cosine |
| Learning Rate | 2e-5 |
| Number of Training Epochs | 3 |
| Per Device Training Batch Size | 4 |
| Gradient Accumulation Steps | 4 |
| Precision | FP16 |
| Optimizer | AdamW |
We're excited about the journey ahead with GenZ. We're committed to continuously improving and enhancing our models, and we're excited to see what the open-source community will build with them. We believe in the power of collaboration, and we can't wait to see what we can achieve together.
Remember, we're just getting started. This is just the beginning of a journey that we believe will revolutionize the world of large language models. We invite you to join us on this exciting journey. Together, we can push the boundaries of what's possible with AI. 🚀
Check the GitHub for the code -> GenZ