




Total runs:
427.1K
Run Growth:
32.9K
Growth Rate:
7.70%

TheBloke's LLM work is generously supported by a grant from andreessen horowitz (a16z)
This repo contains GGUF format model files for OpenOrca's Mistral 7B OpenOrca .
GGUF is a new format introduced by the llama.cpp team on August 21st 2023. It is a replacement for GGML, which is no longer supported by llama.cpp.
Here is an incomplate list of clients and libraries that are known to support GGUF:
<|im_start|>system
{system_message}<|im_end|>
<|im_start|>user
{prompt}<|im_end|>
<|im_start|>assistant
These quantised GGUFv2 files are compatible with llama.cpp from August 27th onwards, as of commit d0cee0d
They are also compatible with many third party UIs and libraries - please see the list at the top of this README.
The new methods available are:
Refer to the Provided Files table below to see what files use which methods, and how.
| Name | Quant method | Bits | Size | Max RAM required | Use case |
|---|---|---|---|---|---|
| mistral-7b-openorca.Q2_K.gguf | Q2_K | 2 | 3.08 GB | 5.58 GB | smallest, significant quality loss - not recommended for most purposes |
| mistral-7b-openorca.Q3_K_S.gguf | Q3_K_S | 3 | 3.16 GB | 5.66 GB | very small, high quality loss |
| mistral-7b-openorca.Q3_K_M.gguf | Q3_K_M | 3 | 3.52 GB | 6.02 GB | very small, high quality loss |
| mistral-7b-openorca.Q3_K_L.gguf | Q3_K_L | 3 | 3.82 GB | 6.32 GB | small, substantial quality loss |
| mistral-7b-openorca.Q4_0.gguf | Q4_0 | 4 | 4.11 GB | 6.61 GB | legacy; small, very high quality loss - prefer using Q3_K_M |
| mistral-7b-openorca.Q4_K_S.gguf | Q4_K_S | 4 | 4.14 GB | 6.64 GB | small, greater quality loss |
| mistral-7b-openorca.Q4_K_M.gguf | Q4_K_M | 4 | 4.37 GB | 6.87 GB | medium, balanced quality - recommended |
| mistral-7b-openorca.Q5_0.gguf | Q5_0 | 5 | 5.00 GB | 7.50 GB | legacy; medium, balanced quality - prefer using Q4_K_M |
| mistral-7b-openorca.Q5_K_S.gguf | Q5_K_S | 5 | 5.00 GB | 7.50 GB | large, low quality loss - recommended |
| mistral-7b-openorca.Q5_K_M.gguf | Q5_K_M | 5 | 5.13 GB | 7.63 GB | large, very low quality loss - recommended |
| mistral-7b-openorca.Q6_K.gguf | Q6_K | 6 | 5.94 GB | 8.44 GB | very large, extremely low quality loss |
| mistral-7b-openorca.Q8_0.gguf | Q8_0 | 8 | 7.70 GB | 10.20 GB | very large, extremely low quality loss - not recommended |
Note : the above RAM figures assume no GPU offloading. If layers are offloaded to the GPU, this will reduce RAM usage and use VRAM instead.
Note for manual downloaders: You almost never want to clone the entire repo! Multiple different quantisation formats are provided, and most users only want to pick and download a single file.
The following clients/libraries will automatically download models for you, providing a list of available models to choose from:
text-generation-webui
Under Download Model, you can enter the model repo: TheBloke/Mistral-7B-OpenOrca-GGUF and below it, a specific filename to download, such as: mistral-7b-openorca.Q4_K_M.gguf.
Then click Download.
I recommend using the
huggingface-hub
Python library:
pip3 install huggingface-hub
Then you can download any individual model file to the current directory, at high speed, with a command like this:
huggingface-cli download TheBloke/Mistral-7B-OpenOrca-GGUF mistral-7b-openorca.Q4_K_M.gguf --local-dir . --local-dir-use-symlinks False
You can also download multiple files at once with a pattern:
huggingface-cli download TheBloke/Mistral-7B-OpenOrca-GGUF --local-dir . --local-dir-use-symlinks False --include='*Q4_K*gguf'
For more documentation on downloading with
huggingface-cli
, please see:
HF -> Hub Python Library -> Download files -> Download from the CLI
.
To accelerate downloads on fast connections (1Gbit/s or higher), install
hf_transfer
:
pip3 install hf_transfer
And set environment variable
HF_HUB_ENABLE_HF_TRANSFER
to
1
:
HF_HUB_ENABLE_HF_TRANSFER=1 huggingface-cli download TheBloke/Mistral-7B-OpenOrca-GGUF mistral-7b-openorca.Q4_K_M.gguf --local-dir . --local-dir-use-symlinks False
Windows Command Line users: You can set the environment variable by running
set HF_HUB_ENABLE_HF_TRANSFER=1
before the download command.
llama.cpp
command
Make sure you are using
llama.cpp
from commit
d0cee0d
or later.
./main -ngl 32 -m mistral-7b-openorca.Q4_K_M.gguf --color -c 2048 --temp 0.7 --repeat_penalty 1.1 -n -1 -p "<|im_start|>system\n{system_message}<|im_end|>\n<|im_start|>user\n{prompt}<|im_end|>\n<|im_start|>assistant"
Change
-ngl 32
to the number of layers to offload to GPU. Remove it if you don't have GPU acceleration.
Change
-c 2048
to the desired sequence length. For extended sequence models - eg 8K, 16K, 32K - the necessary RoPE scaling parameters are read from the GGUF file and set by llama.cpp automatically.
If you want to have a chat-style conversation, replace the
-p <PROMPT>
argument with
-i -ins
For other parameters and how to use them, please refer to the llama.cpp documentation
text-generation-webui
Further instructions here: text-generation-webui/docs/llama.cpp.md .
You can use GGUF models from Python using the llama-cpp-python or ctransformers libraries.
Run one of the following commands, according to your system:
# Base ctransformers with no GPU acceleration
pip install ctransformers
# Or with CUDA GPU acceleration
pip install ctransformers[cuda]
# Or with AMD ROCm GPU acceleration (Linux only)
CT_HIPBLAS=1 pip install ctransformers --no-binary ctransformers
# Or with Metal GPU acceleration for macOS systems only
CT_METAL=1 pip install ctransformers --no-binary ctransformers
from ctransformers import AutoModelForCausalLM

# Set gpu_layers to the number of layers to offload to GPU. Set to 0 if no GPU acceleration is available on your system.
llm = AutoModelForCausalLM.from_pretrained("TheBloke/Mistral-7B-OpenOrca-GGUF", model_file="mistral-7b-openorca.Q4_K_M.gguf", model_type="mistral", gpu_layers=50)

print(llm("AI is going to"))
Here are guides on using llama-cpp-python and ctransformers with LangChain:
For further support, and discussions on these models and AI in general, join us at:
Thanks to the chirper.ai team!
Thanks to Clay from gpus.llm-utils.org !
I've had a lot of people ask if they can contribute. I enjoy providing models and helping people, and would love to be able to spend even more time doing it, as well as expanding into new projects like fine tuning/training.
If you're able and willing to contribute it will be most gratefully received and will help me to keep providing more models, and to start work on new AI projects.
Donaters will get priority support on any and all AI/LLM/model questions and requests, access to a private Discord room, plus other benefits.
Special thanks to : Aemon Algiz.
Patreon special mentions : Pierre Kircher, Stanislav Ovsiannikov, Michael Levine, Eugene Pentland, Andrey, 준교 김, Randy H, Fred von Graf, Artur Olbinski, Caitlyn Gatomon, terasurfer, Jeff Scroggin, James Bentley, Vadim, Gabriel Puliatti, Harry Royden McLaughlin, Sean Connelly, Dan Guido, Edmond Seymore, Alicia Loh, subjectnull, AzureBlack, Manuel Alberto Morcote, Thomas Belote, Lone Striker, Chris Smitley, Vitor Caleffi, Johann-Peter Hartmann, Clay Pascal, biorpg, Brandon Frisco, sidney chen, transmissions 11, Pedro Madruga, jinyuan sun, Ajan Kanaga, Emad Mostaque, Trenton Dambrowitz, Jonathan Leane, Iucharbius, usrbinkat, vamX, George Stoitzev, Luke Pendergrass, theTransient, Olakabola, Swaroop Kallakuri, Cap'n Zoog, Brandon Phillips, Michael Dempsey, Nikolai Manek, danny, Matthew Berman, Gabriel Tamborski, alfie_i, Raymond Fosdick, Tom X Nguyen, Raven Klaugh, LangChain4j, Magnesian, Illia Dulskyi, David Ziegler, Mano Prime, Luis Javier Navarrete Lozano, Erik Bjäreholt, 阿明, Nathan Dryer, Alex, Rainer Wilmers, zynix, TL, Joseph William Delisle, John Villwock, Nathan LeClaire, Willem Michiel, Joguhyik, GodLy, OG, Alps Aficionado, Jeffrey Morgan, ReadyPlayerEmma, Tiffany J. Kim, Sebastain Graf, Spencer Kim, Michael Davis, webtim, Talal Aujan, knownsqashed, John Detwiler, Imad Khwaja, Deo Leter, Jerry Meng, Elijah Stavena, Rooh Singh, Pieter, SuperWojo, Alexandros Triantafyllidis, Stephen Murray, Ai Maven, ya boyyy, Enrico Ros, Ken Nordquist, Deep Realms, Nicholas, Spiking Neurons AB, Elle, Will Dee, Jack West, RoA, Luke @flexchar, Viktor Bowallius, Derek Yates, Subspace Studios, jjj, Toran Billups, Asp the Wyvern, Fen Risland, Ilya, NimbleBox.ai, Chadd, Nitin Borwankar, Emre, Mandus, Leonard Tan, Kalila, K, Trailburnt, S_X, Cory Kujawski
Thank you to all my generous patrons and donaters!
And thank you again to a16z for their generous grant.
We have used our own OpenOrca dataset to fine-tune on top of Mistral 7B . This dataset is our attempt to reproduce the dataset generated for Microsoft Research's Orca Paper . We use OpenChat packing, trained with Axolotl .
This release is trained on a curated filtered subset of most of our GPT-4 augmented data. It is the same subset of our data as was used in our OpenOrcaxOpenChat-Preview2-13B model .
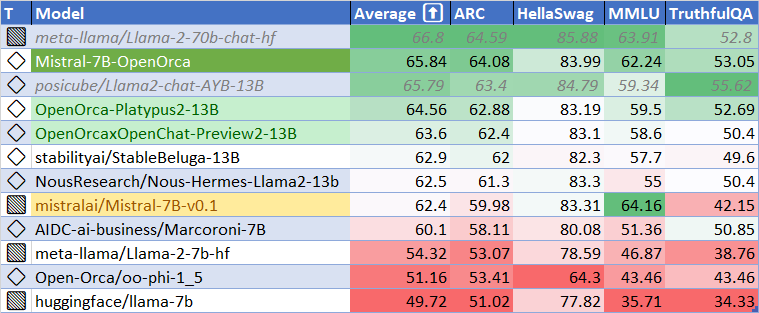
HF Leaderboard evals place this model as #2 for all models smaller than 30B at release time, outperforming all but one 13B model.
This release provides a first: a fully open model with class-breaking performance, capable of running fully accelerated on even moderate consumer GPUs. Our thanks to the Mistral team for leading the way here.
We affectionately codename this model: " MistralOrca "
If you'd like to try the model now, we have it running on fast GPUs unquantized: https://huggingface.co/spaces/Open-Orca/Mistral-7B-OpenOrca
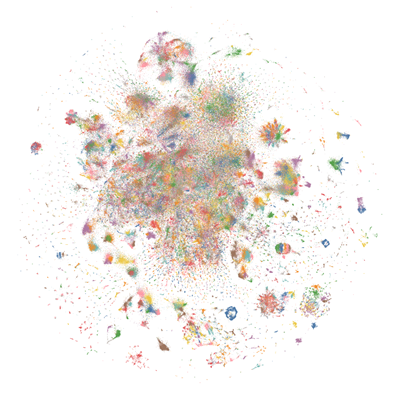
Want to visualize our full (pre-filtering) dataset? Check out our Nomic Atlas Map .
We are in-process with training more models, so keep a look out on our org for releases coming soon with exciting partners.
We will also give sneak-peak announcements on our Discord, which you can find here:
or check the OpenAccess AI Collective Discord for more information about Axolotl trainer here:
Quantized versions of this model are generously made available by TheBloke .
We used
OpenAI's Chat Markup Language (ChatML)
format, with
<|im_start|>
and
<|im_end|>
tokens added to support this.
<|im_start|>system
You are MistralOrca, a large language model trained by Alignment Lab AI. Write out your reasoning step-by-step to be sure you get the right answers!
<|im_end|>
<|im_start|>user
How are you?<|im_end|>
<|im_start|>assistant
I am doing well!<|im_end|>
<|im_start|>user
Please tell me about how mistral winds have attracted super-orcas.<|im_end|>
We have evaluated using the methodology and tools for the HuggingFace Leaderboard, and find that we have dramatically improved upon the base model. We find 105% of the base model's performance on HF Leaderboard evals, averaging 65.33 .
At release time, this beats all 7B models, and all but one 13B.
| Metric | Value |
|---|---|
| MMLU (5-shot) | 61.73 |
| ARC (25-shot) | 63.57 |
| HellaSwag (10-shot) | 83.79 |
| TruthfulQA (0-shot) | 52.24 |
| Avg. | 65.33 |
We use Language Model Evaluation Harness to run the benchmark tests above, using the same version as the HuggingFace LLM Leaderboard.
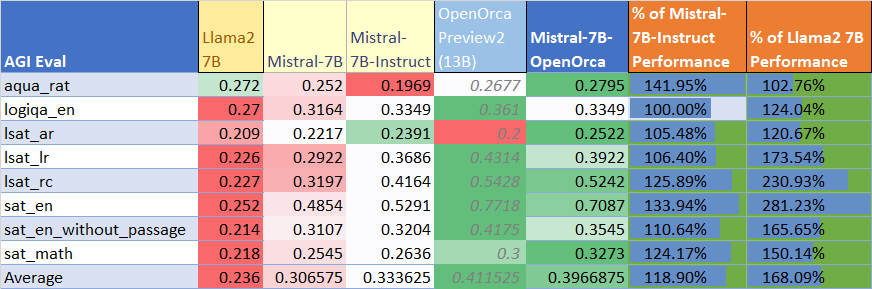
We compare our results to the base Mistral-7B model (using LM Evaluation Harness).
We find
129%
of the base model's performance on AGI Eval, averaging
0.397
.
As well, we significantly improve upon the official
mistralai/Mistral-7B-Instruct-v0.1
finetuning, achieving
119%
of their performance.
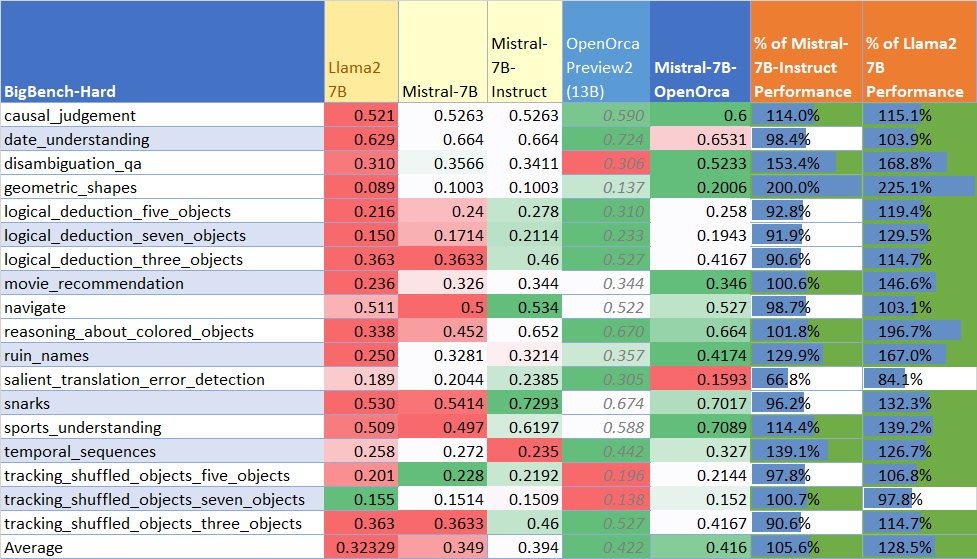
We find 119% of the base model's performance on BigBench-Hard, averaging 0.416 .
We used a curated, filtered selection of most of the GPT-4 augmented data from our OpenOrca dataset, which aims to reproduce the Orca Research Paper dataset.
We trained with 8x A6000 GPUs for 62 hours, completing 4 epochs of full fine tuning on our dataset in one training run. Commodity cost was ~$400.
@software{lian2023mistralorca1
  title = {MistralOrca: Mistral-7B Model Instruct-tuned on Filtered OpenOrcaV1 GPT-4 Dataset},
  author = {Wing Lian and Bleys Goodson and Guan Wang and Eugene Pentland and Austin Cook and Chanvichet Vong and "Teknium"},
  year = {2023},
  publisher = {HuggingFace},
  journal = {HuggingFace repository},
  howpublished = {\url{https://huggingface.co/Open-Orca/Mistral-7B-OpenOrca},
}
@misc{mukherjee2023orca,
      title={Orca: Progressive Learning from Complex Explanation Traces of GPT-4},
      author={Subhabrata Mukherjee and Arindam Mitra and Ganesh Jawahar and Sahaj Agarwal and Hamid Palangi and Ahmed Awadallah},
      year={2023},
      eprint={2306.02707},
      archivePrefix={arXiv},
      primaryClass={cs.CL}
}
@misc{longpre2023flan,
      title={The Flan Collection: Designing Data and Methods for Effective Instruction Tuning},
      author={Shayne Longpre and Le Hou and Tu Vu and Albert Webson and Hyung Won Chung and Yi Tay and Denny Zhou and Quoc V. Le and Barret Zoph and Jason Wei and Adam Roberts},
      year={2023},
      eprint={2301.13688},
      archivePrefix={arXiv},
      primaryClass={cs.AI}
}