




Total runs:
100.8K
Run Growth:
61.8K
Growth Rate:
61.30%
TLDR: this is a reasoning reward model that supports text-to-image generation, from the following paper.


RationalRewards is a reasoning-based reward model and toolkit for visual generation. Instead of reducing preference into one opaque scalar, it generates explicit multi-dimensional critiques before scoring, turning reward models from passive evaluators into active optimization interfaces.
About the name: "Rational" means being reasonable, sensible, in Chinese, 理性的
RationalRewards supports optimization in complementary spaces :
Instantiated via PARROT on a Qwen3-VL-Instruct-8B backbone, RationalRewards achieves state-of-the-art preference prediction among open-source reward models and remains competitive with Gemini-2.5-Pro. As an RL reward, it consistently improves generators beyond scalar baselines across both text-to-image and image-editing tasks. Most interestingly, RationalRewards' test-time prompt tuning, requiring no parameter updates, matches or exceeds RL-based fine-tuning on several benchmarks.
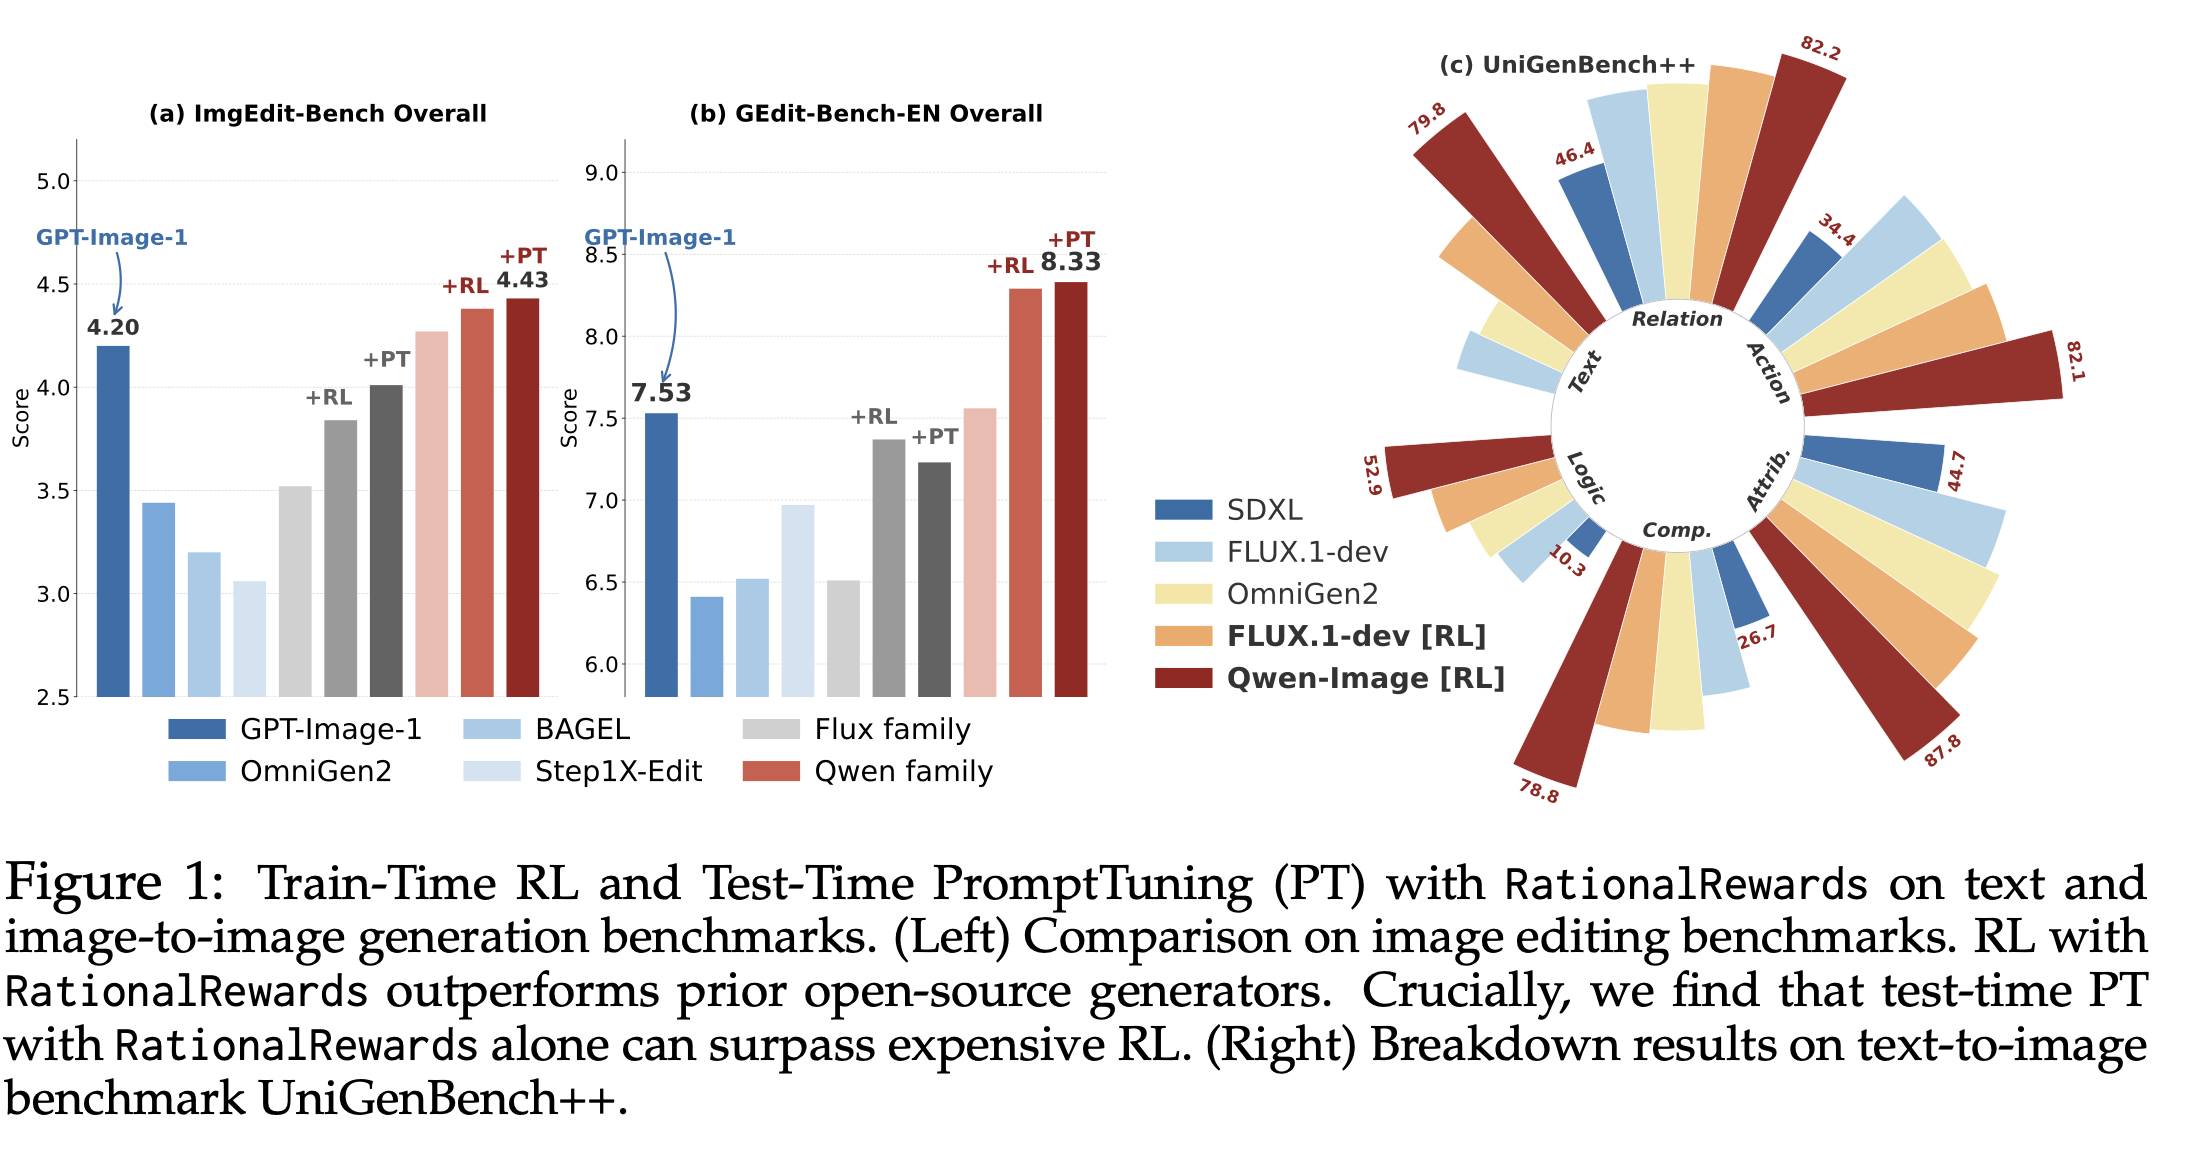
Train-time RL and test-time prompt tuning with RationalRewards across visual generation benchmarks.
Most reward models collapse instruction following, visual quality, composition, and plausibility into one scalar. This removes the structure of human judgment and often leads to brittle optimization. RationalRewards keeps those dimensions explicit so generators receive semantically grounded feedback about what to fix and why.
Scalar rewards are vulnerable to reward hacking because they collapse rich judgment into one number that can rise even when outputs do not truly improve. RationalRewards introduces an implicit regularization: before giving scores, it must produce coherent, multi-dimensional critiques tied to concrete evaluation axes. This constrains optimization to evidence-backed reasoning and improves the monotonic relationship between reward and observed quality during RL.
Generic VLM judges can be strong analysts, but as reward functions they often show high-variance pointwise scoring across semantically similar samples. That variance becomes optimization noise in RL. PARROT trains RationalRewards directly for preference discrimination, yielding lower-variance, preference-aligned scores. The practical outcome is more stable optimization steps and better reward reliability, even with a smaller model footprint.
Reasoning feedback can be reused after generation, not only during training. In a Generate-Critique-Refine loop, RationalRewards critiques the produced image, identifies concrete deficiencies, and proposes targeted prompt updates. Unlike pre-hoc prompt enhancement that rewrites blindly, this is post-hoc and reactive to actual failures. That makes test-time compute more effective at eliciting latent generator capability, often approaching or surpassing RL fine-tuning gains without parameter updates.
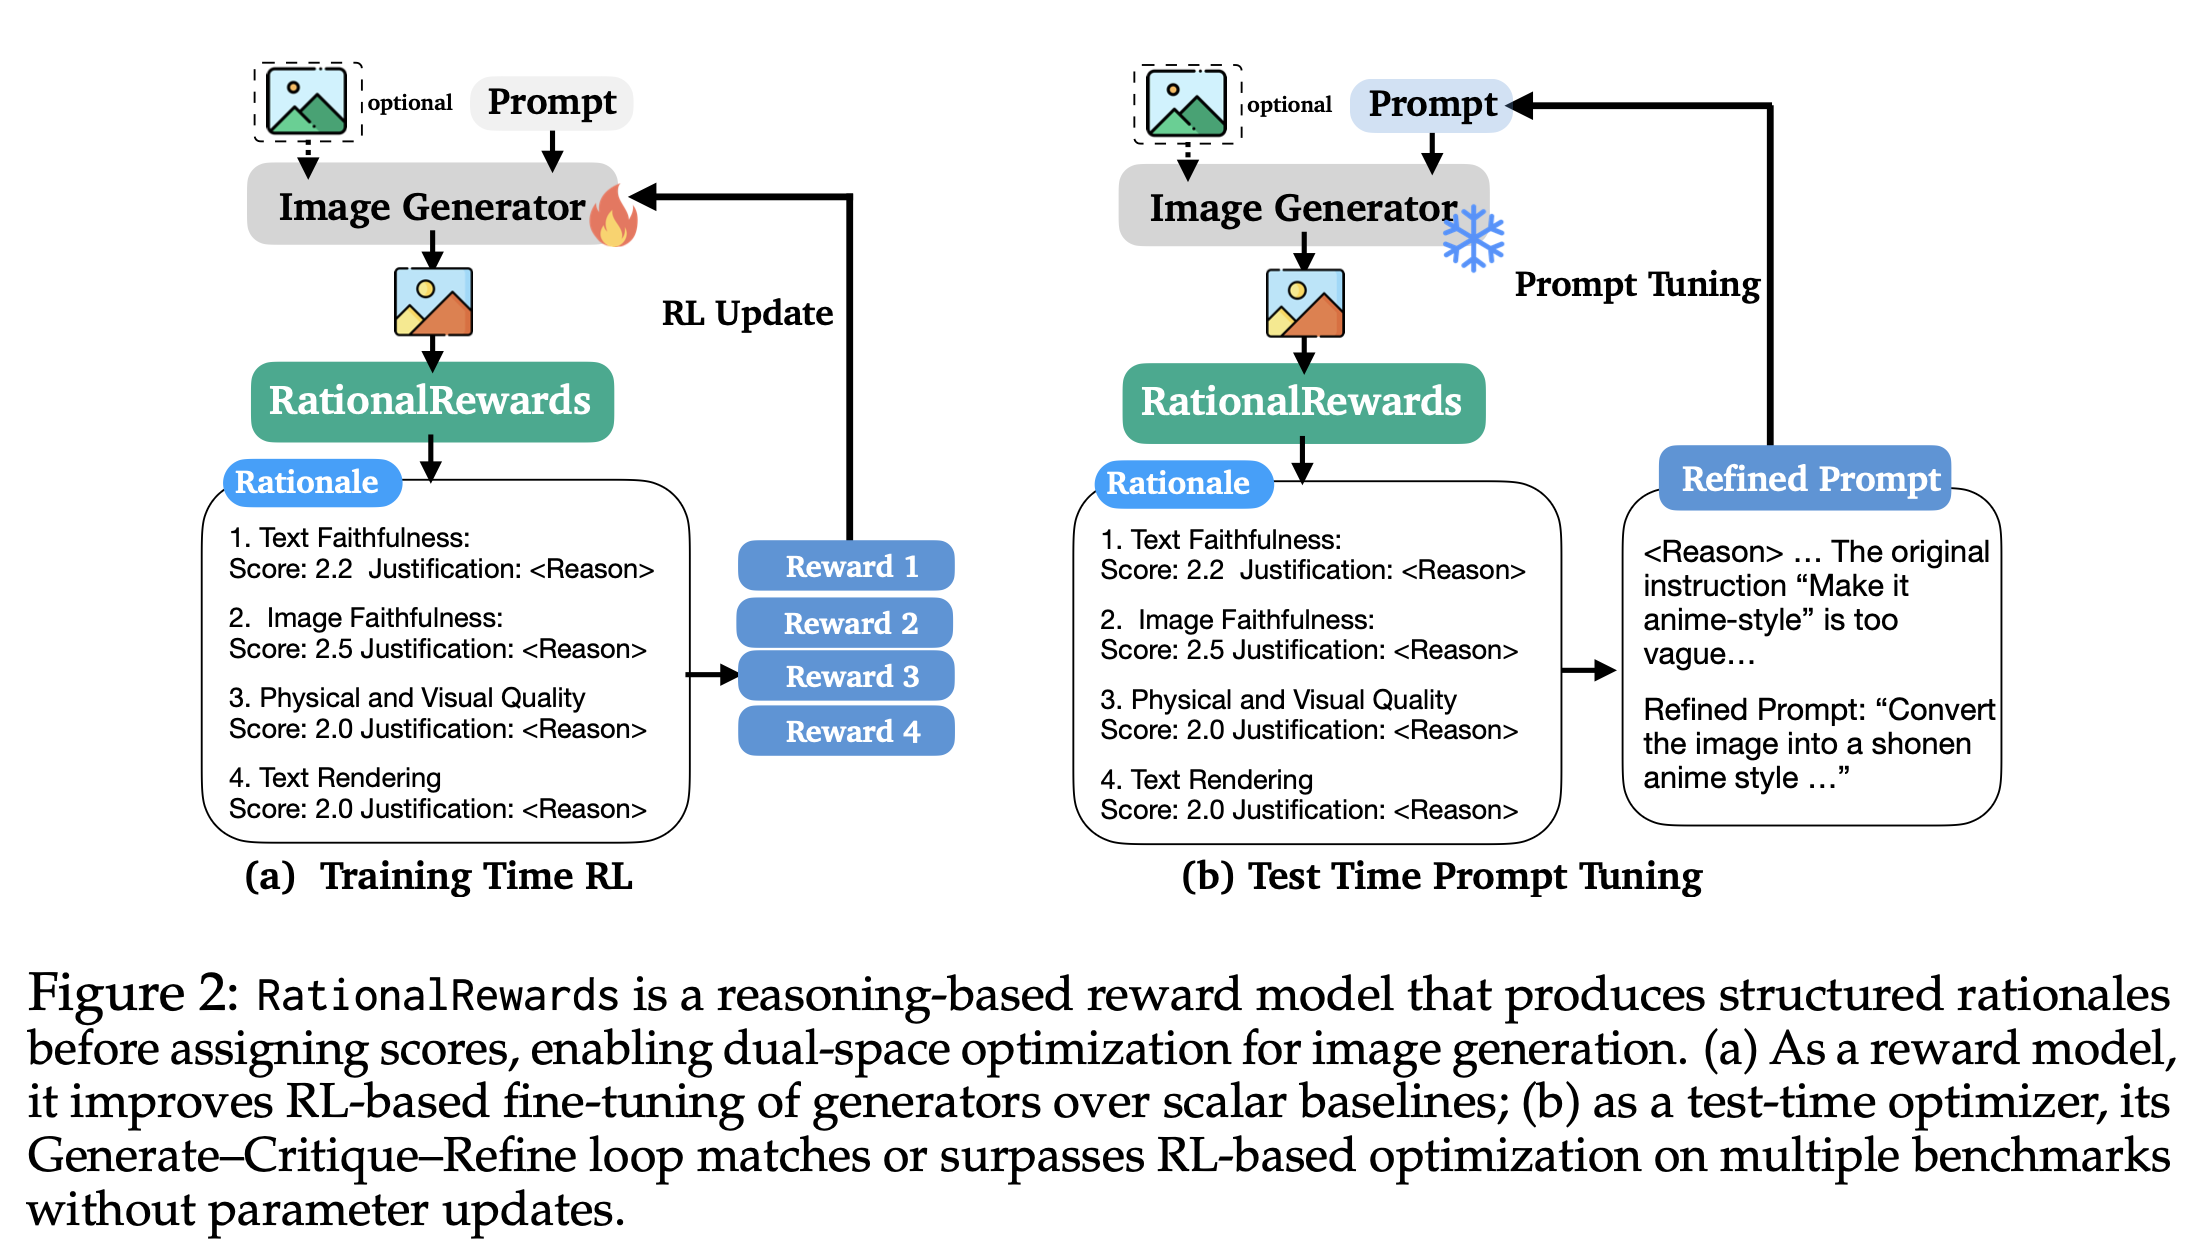
RationalRewards supports optimization in both parameter space (RL) and prompt space (test-time refinement).
Human rationale annotation is expensive. PARROT recovers high-quality rationale supervision from preference-only data in three phases:
This gives a practical path from abundant preference datasets to scalable reasoning supervision.
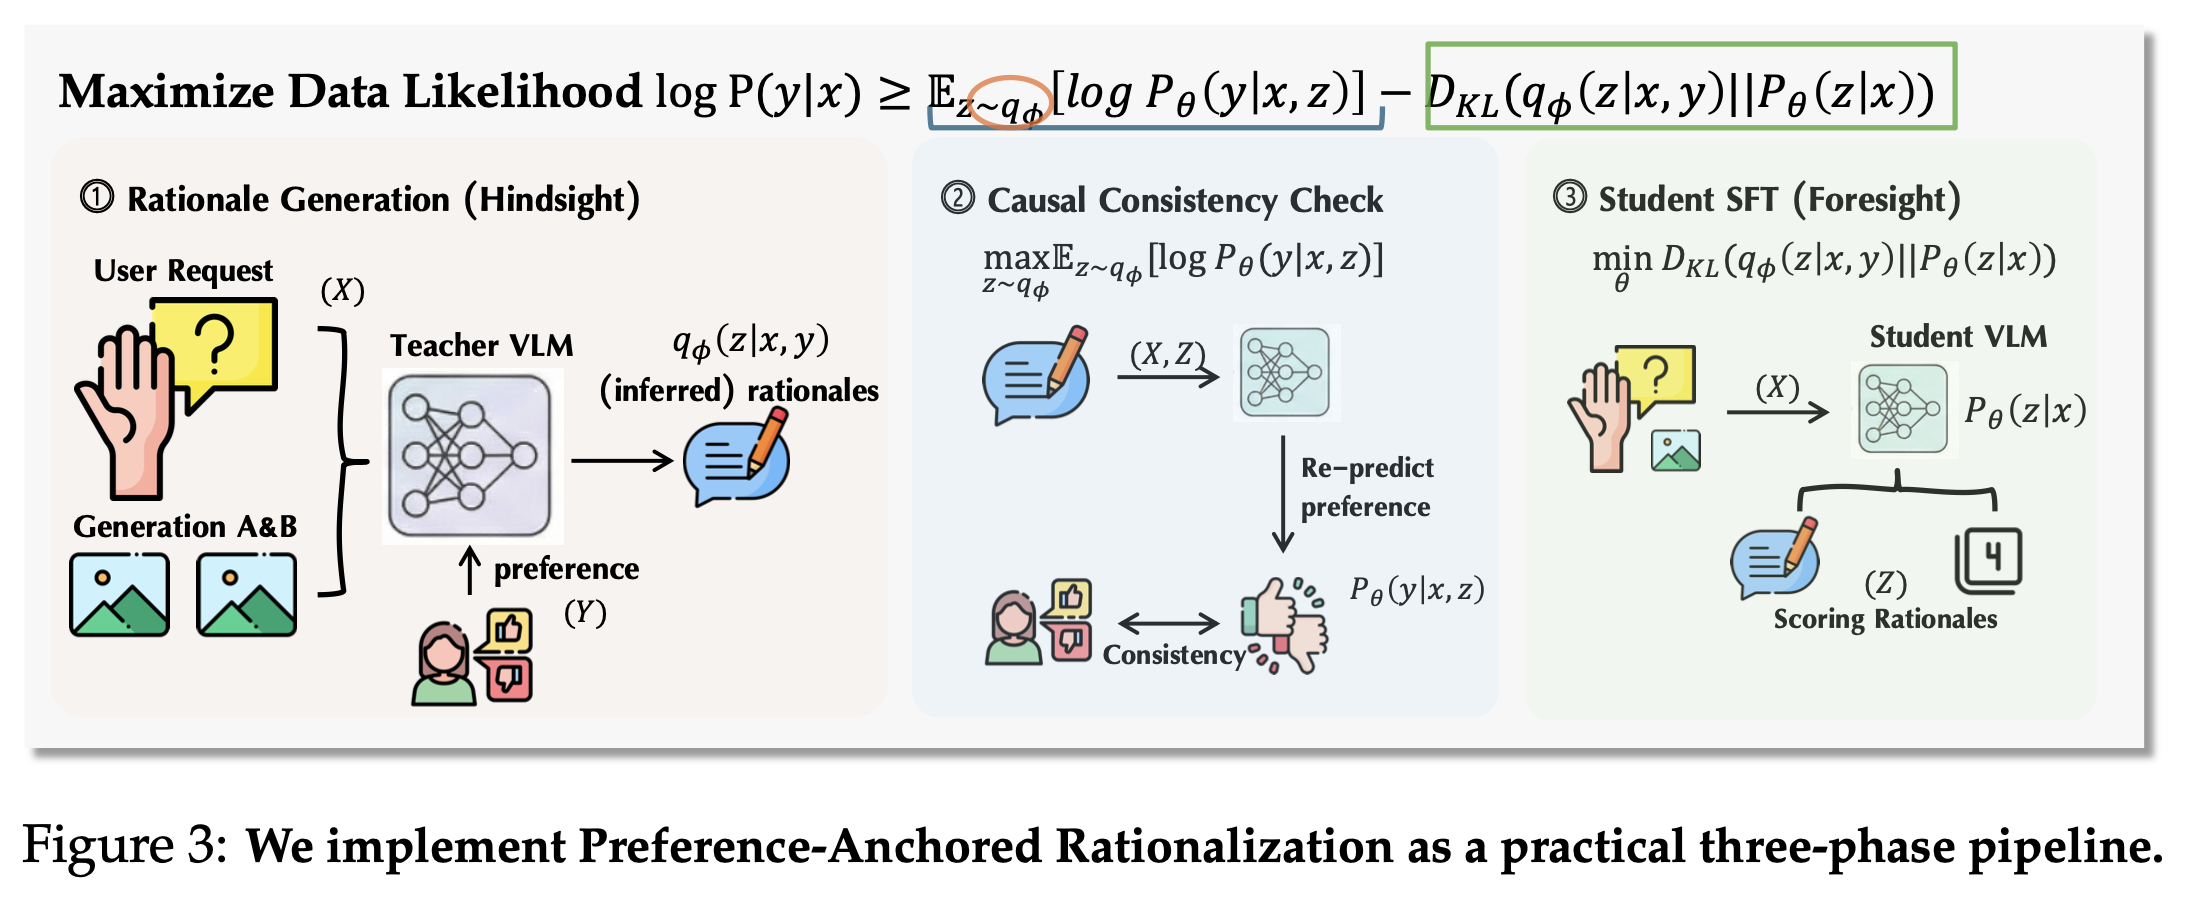
PARROT pipeline: anchored rationale generation, consistency filtering, and distillation.
RationalRewards strengthens both alignment quality and downstream optimization.
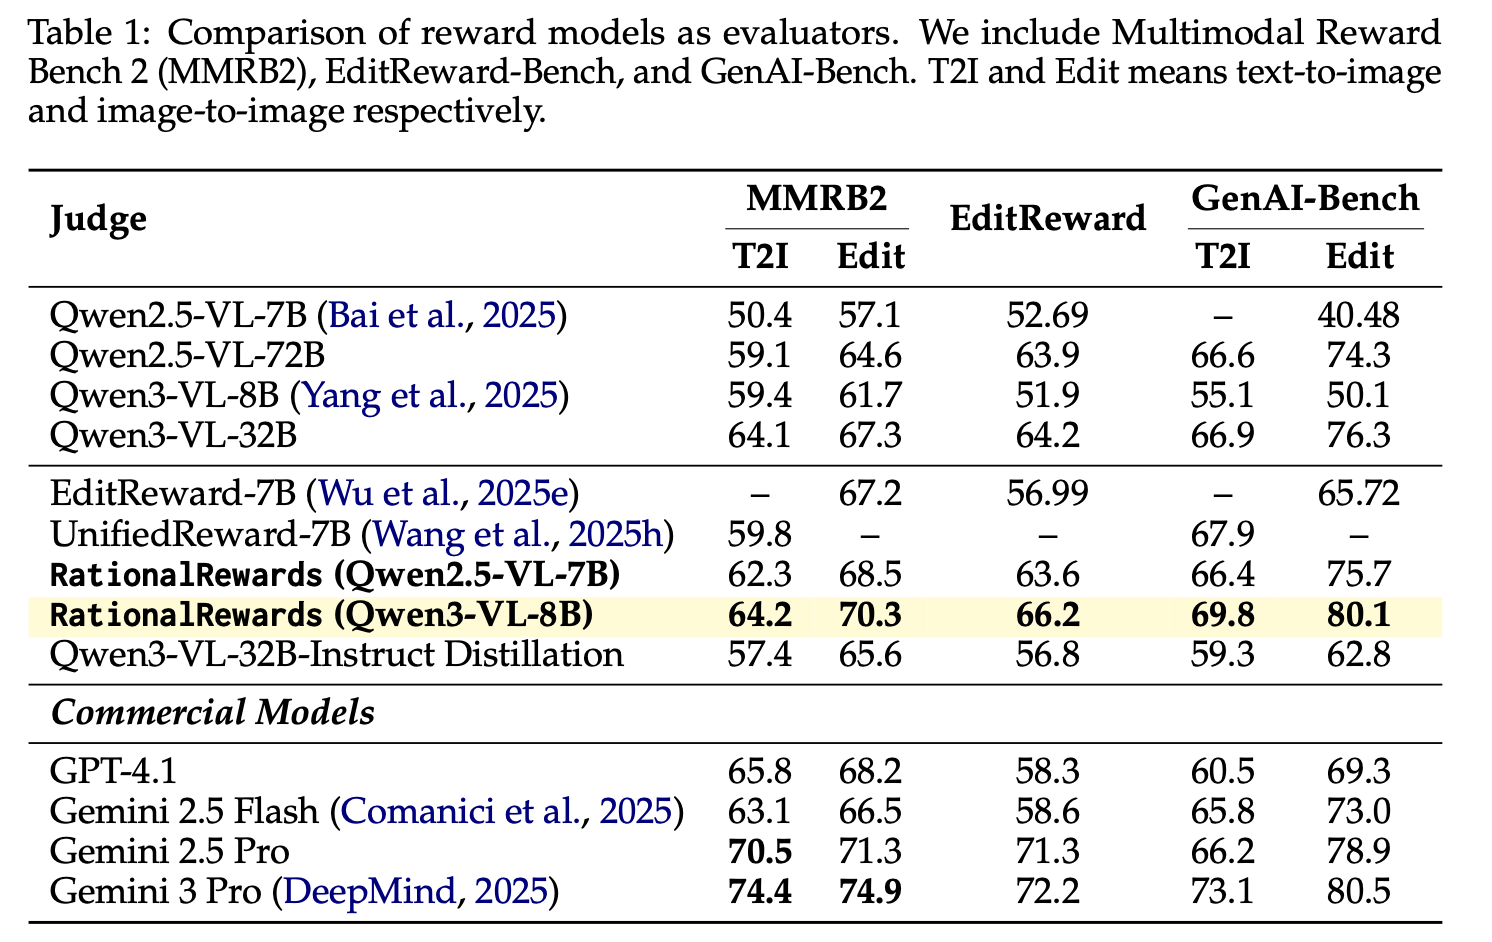
State-of-the-art preference prediction among open-source reward models.
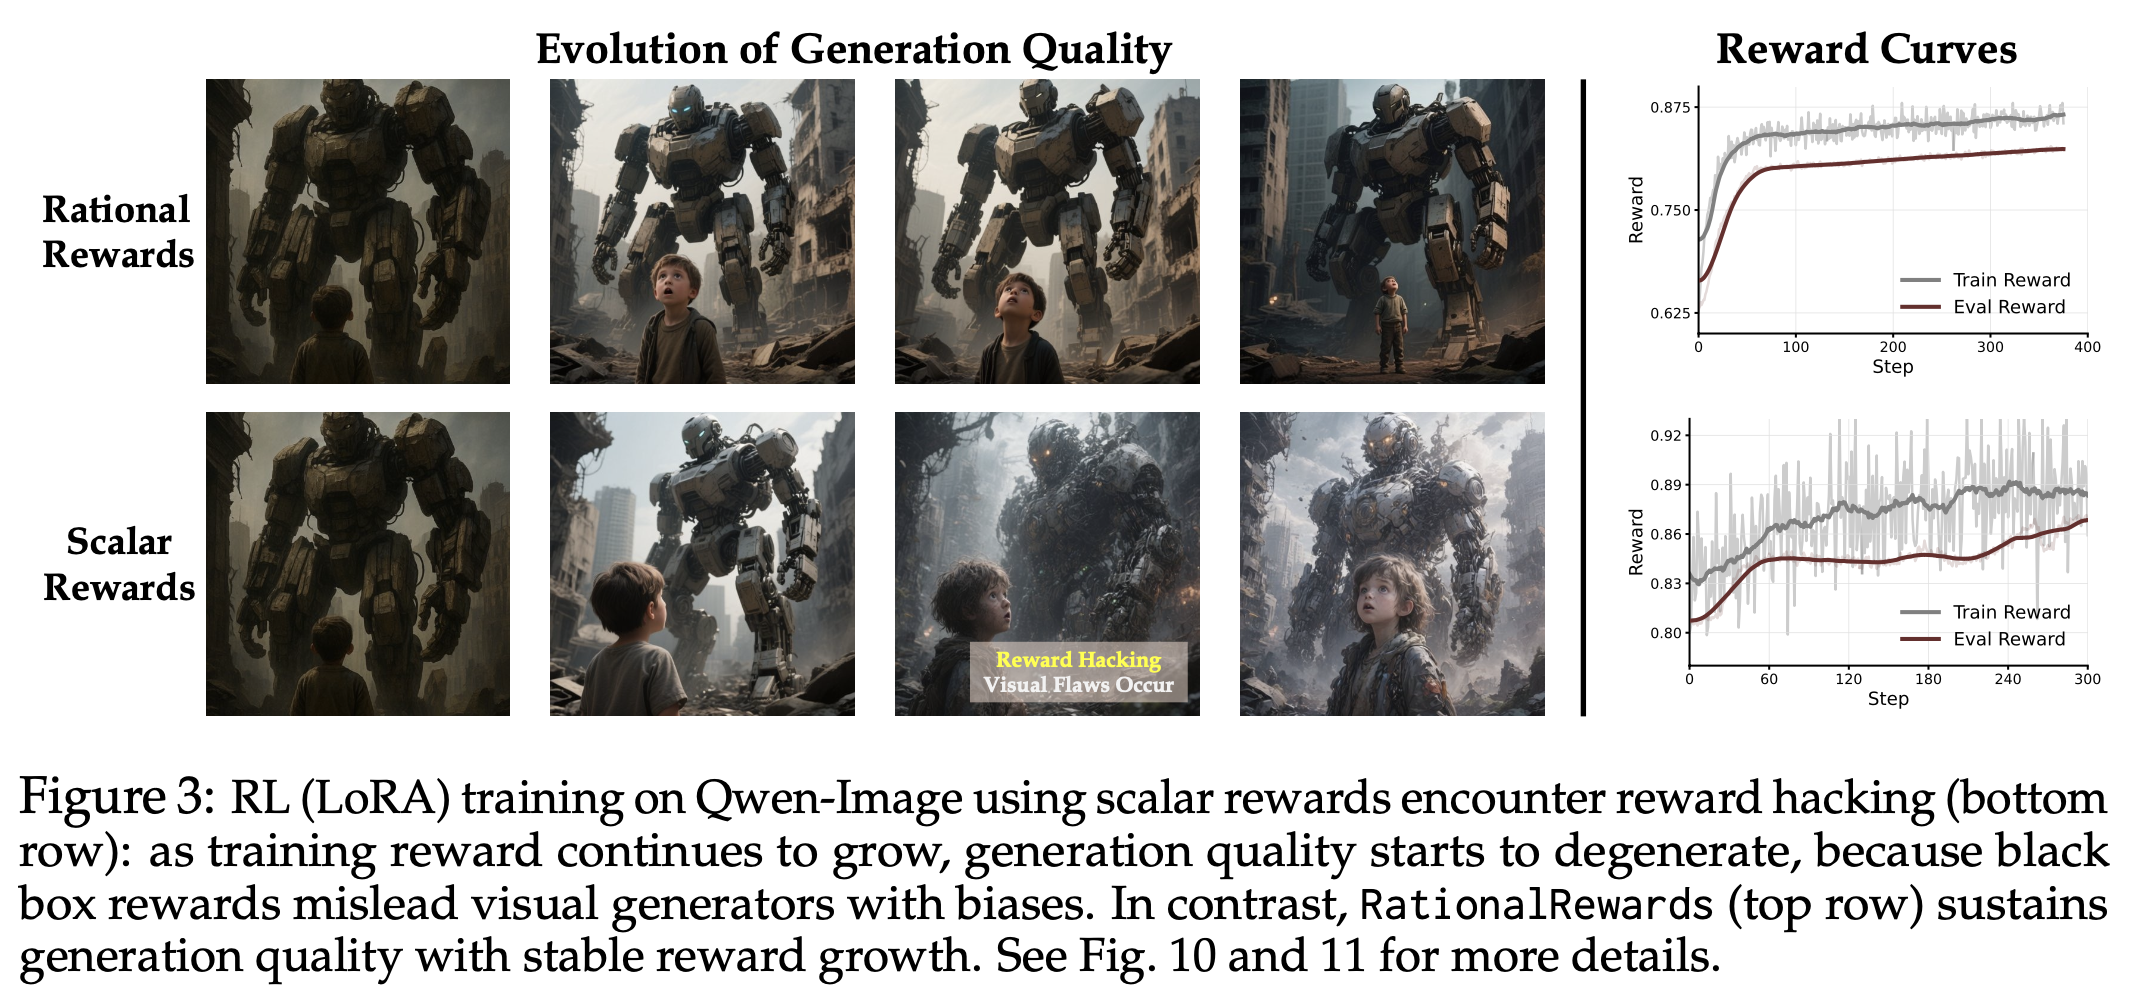
Structured critique channels reduce shortcut exploitation compared with scalar-only rewards.
To better show optimization behavior, we also include diffusion RL training evolution results. The figure below visualizes how RationalRewards-guided training improves over time, illustrating that benefits are not only visible at the final checkpoint but emerge consistently throughout training. This constrast sharply with scalar rewards suffering reward hacking, as we demonstrate in Figure 12 in the paper.
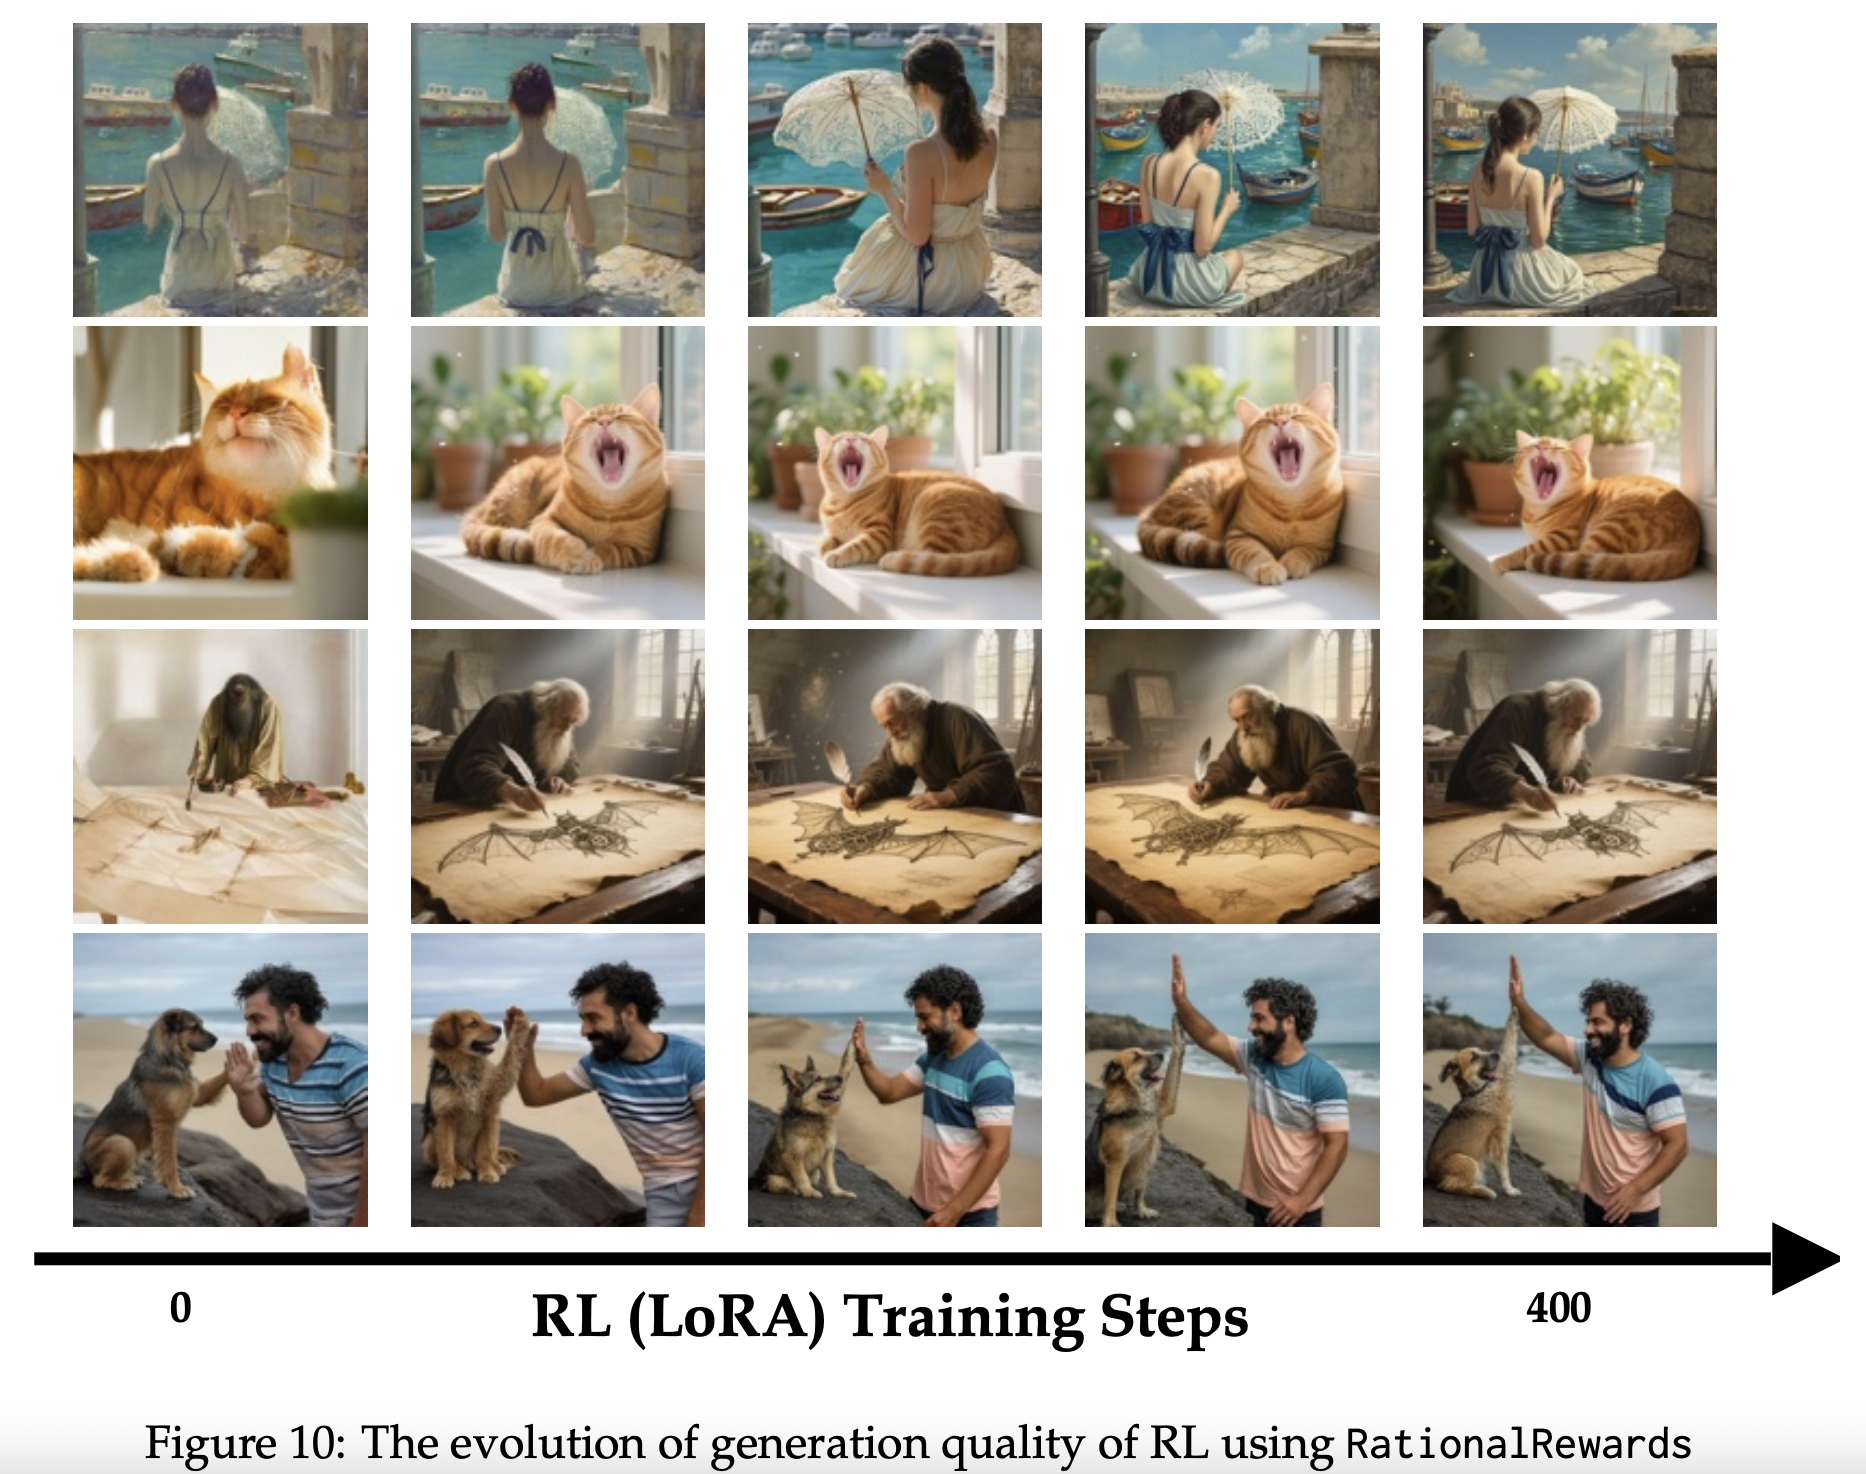
Evolution of diffusion RL performance under RationalRewards-guided optimization.
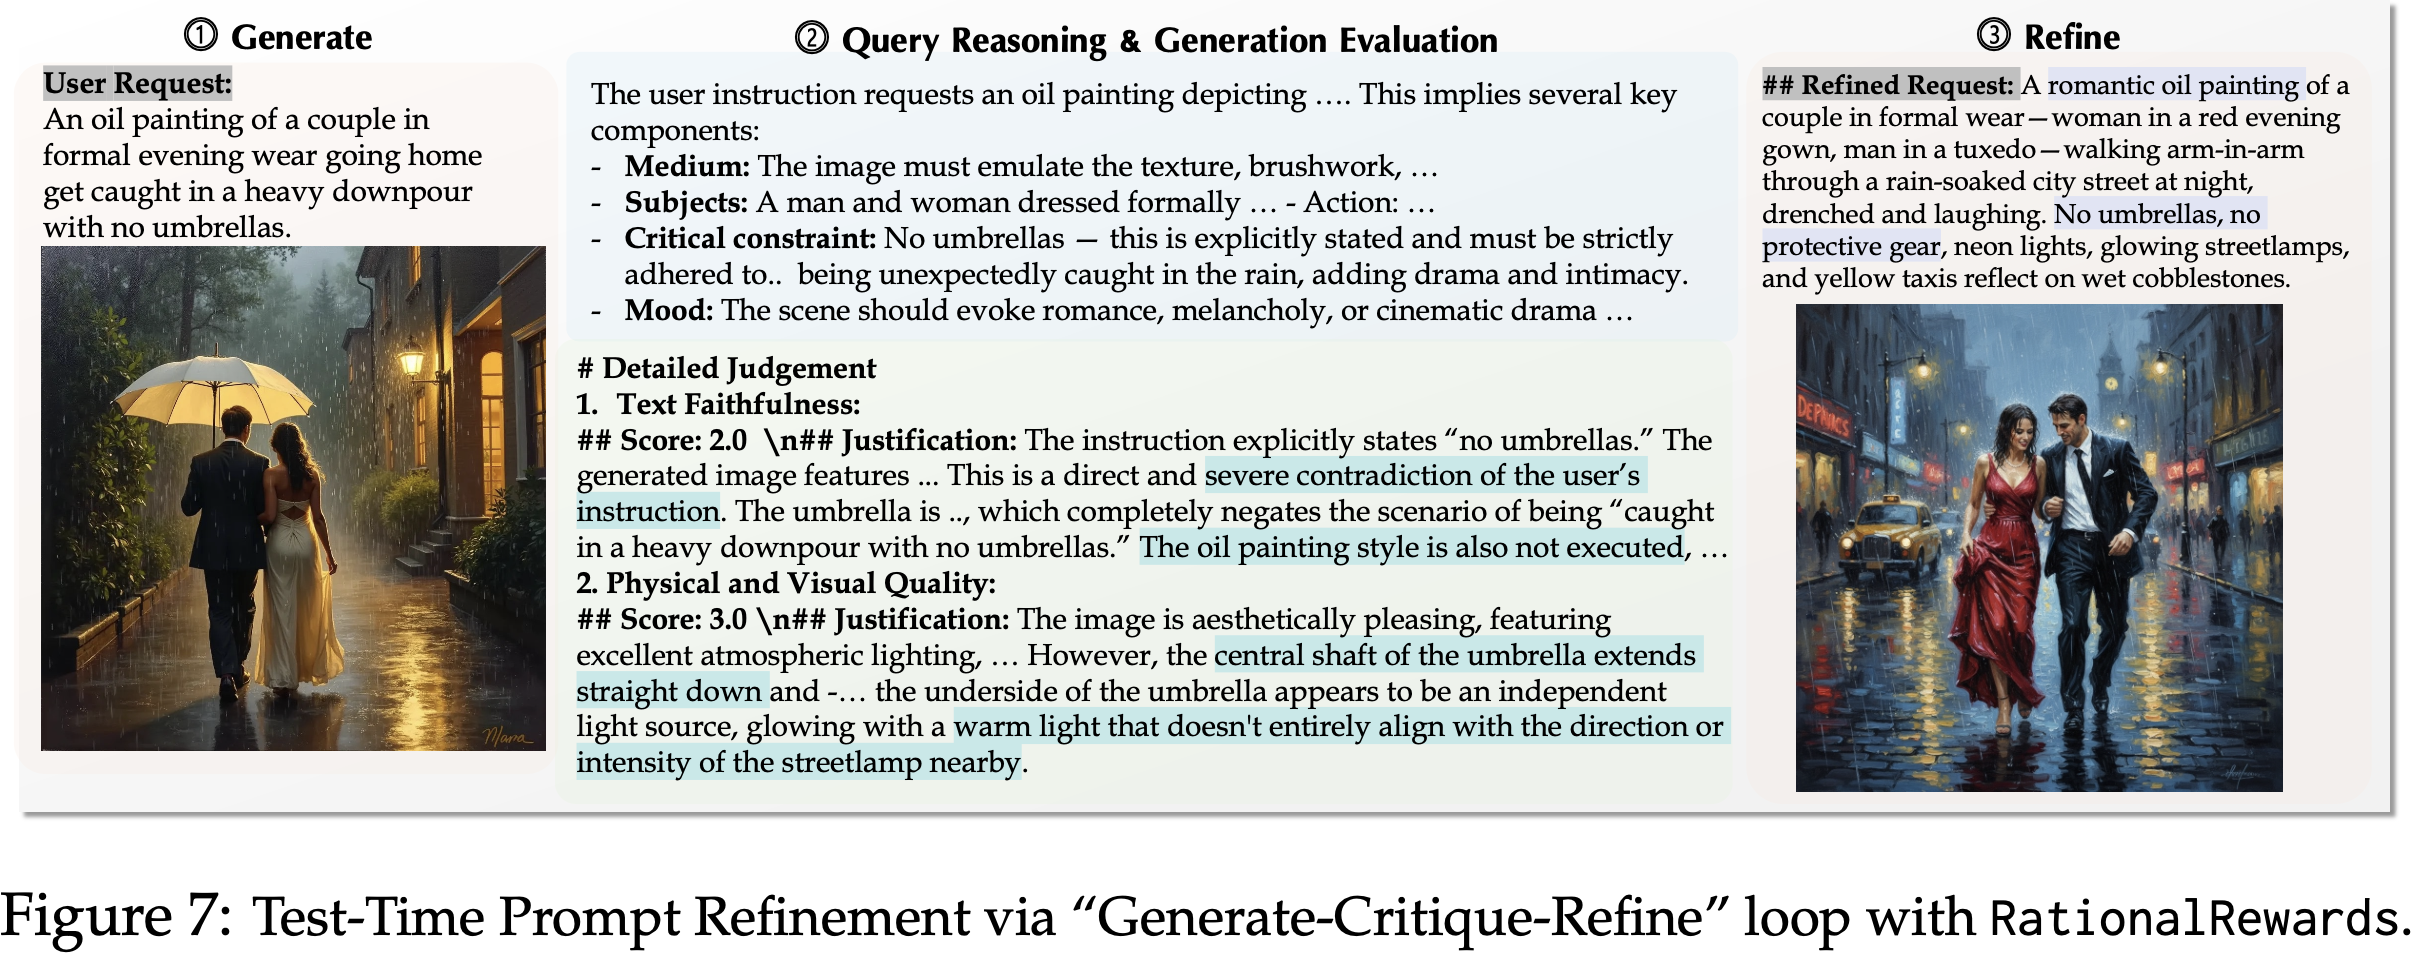
Generate-Critique-Refine at test time can match or exceed RL fine-tuning on several benchmarks.
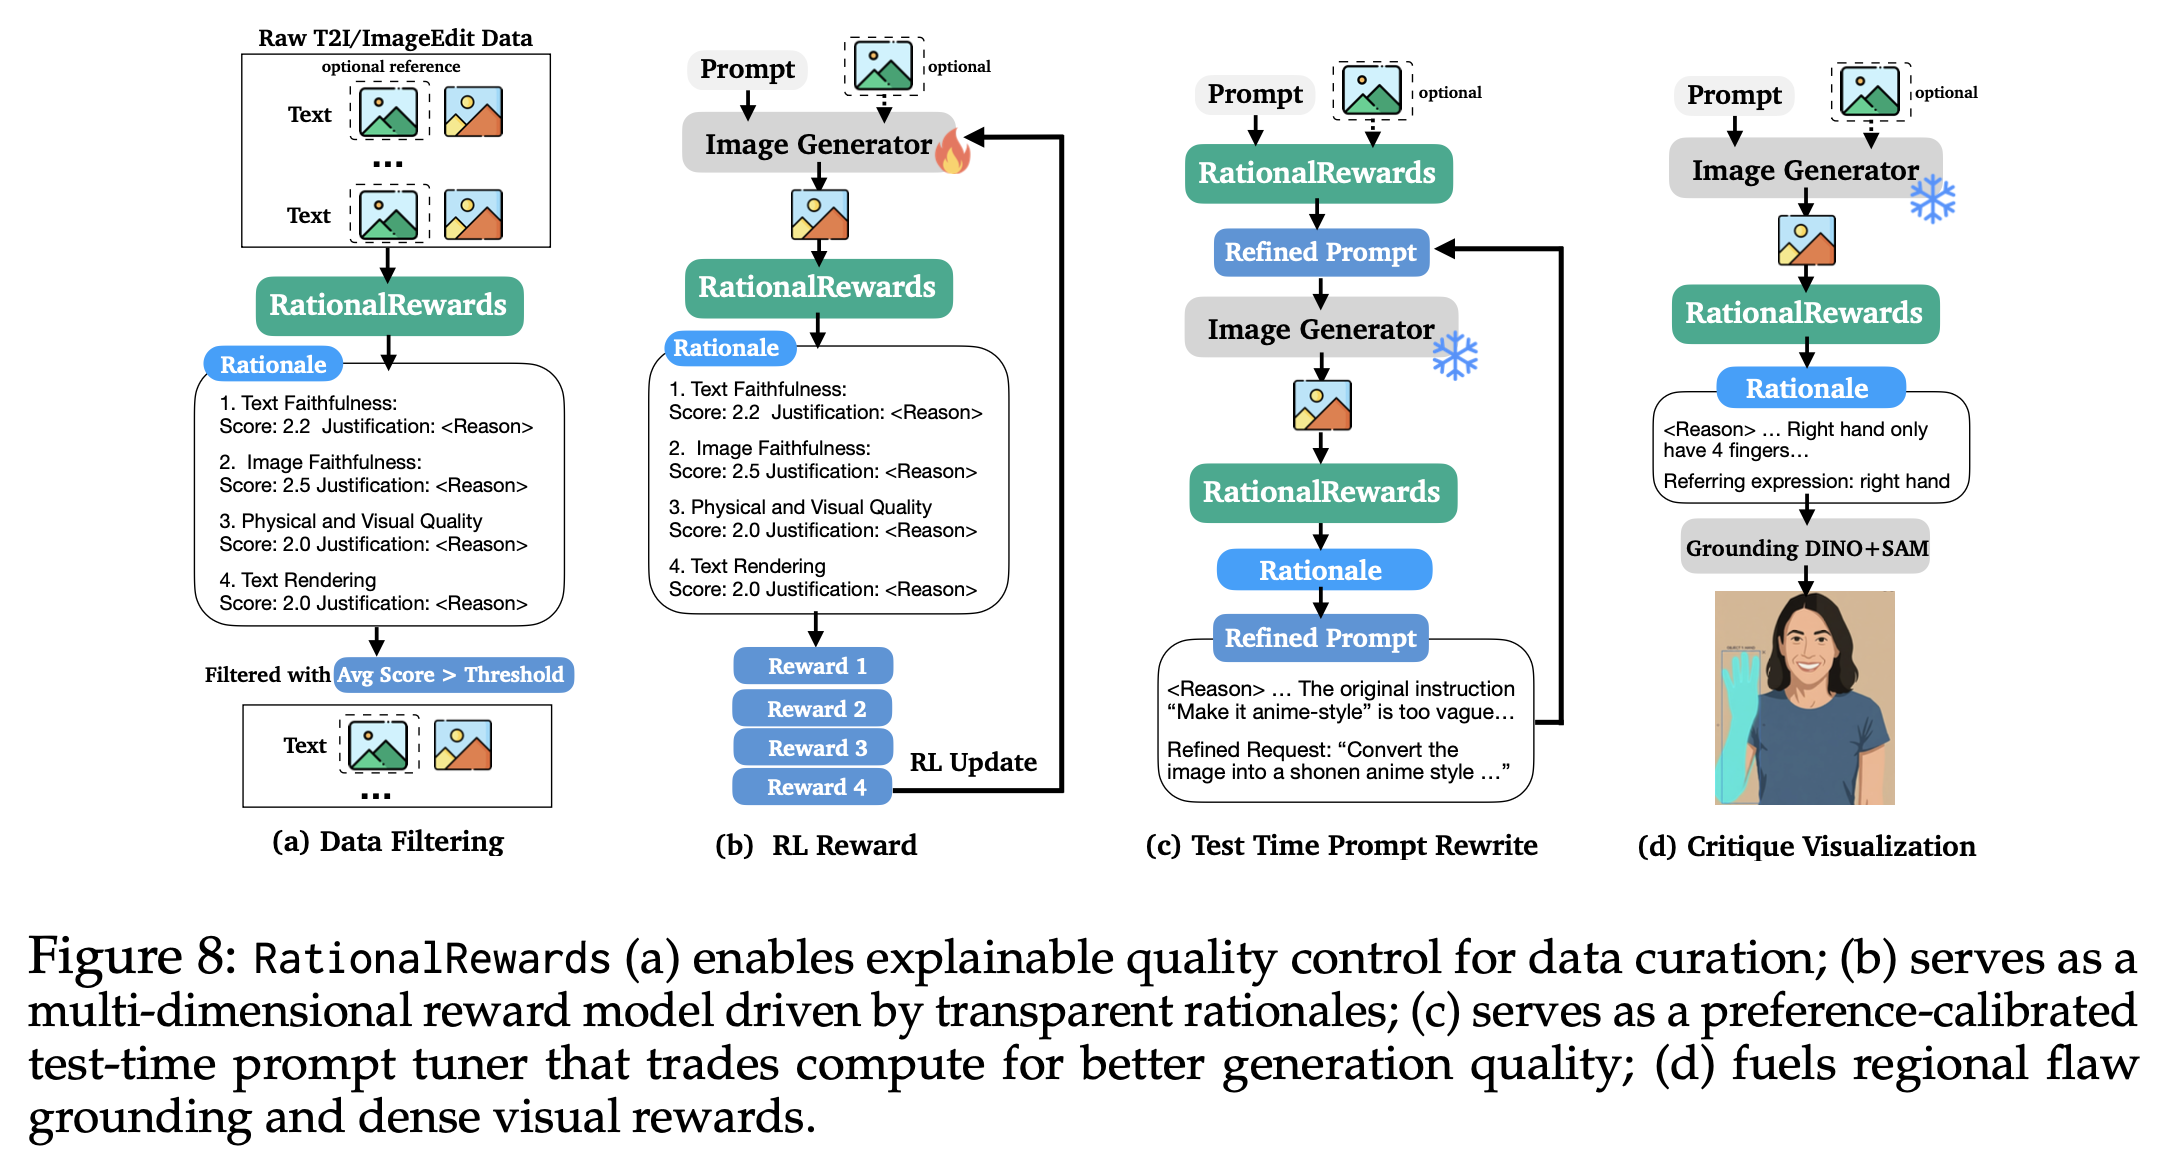
Additional qualitative use cases enabled by explicit reasoning feedback.
@article{rationalrewards2026,
  title   = {RationalRewards: Reasoning Rewards Scale Visual Generation Both Training and Test Time},
  author  = {Haozhe Wang and Cong Wei and Weiming Ren and Jiaming Liu and Fangzhen Lin and Wenhu Chen},
  journal = {arXiv preprint},
  year    = {2026}
}