




Table of Contents
- Key Points
- Understanding Bidirectional Search
- Bidirectional Search and Tree Traversal
- Implementing Bidirectional Search
- Pricing (Not Applicable)
- Advantages and Disadvantages of Bidirectional Search
- Core Features (Algorithm Specifics)
- Effective Use Cases for Bidirectional Search
- Frequently Asked Questions
- Related Questions


Understanding Bidirectional Search
What is Bidirectional Search?
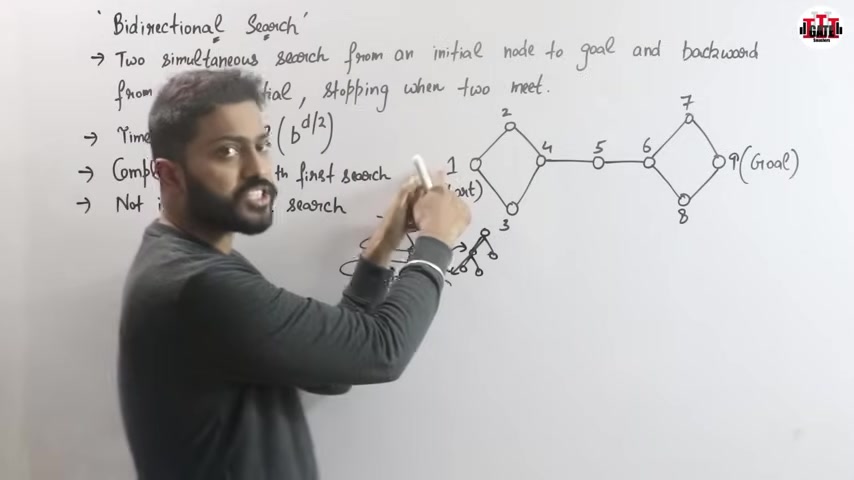
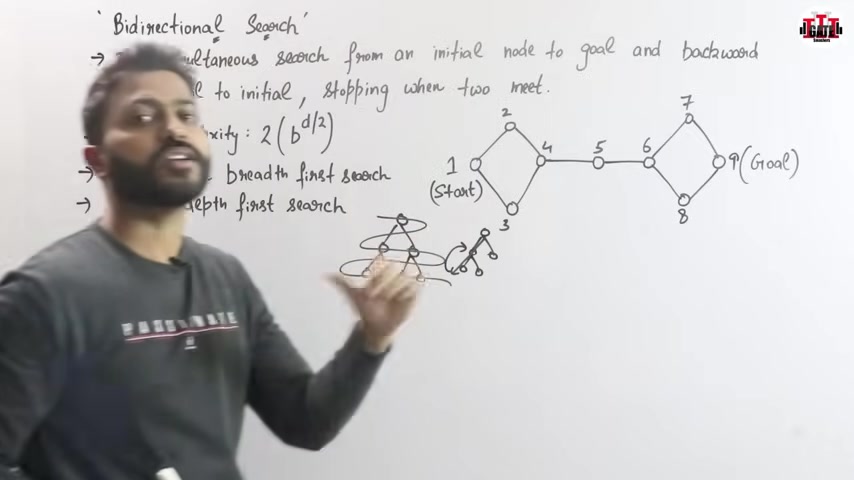
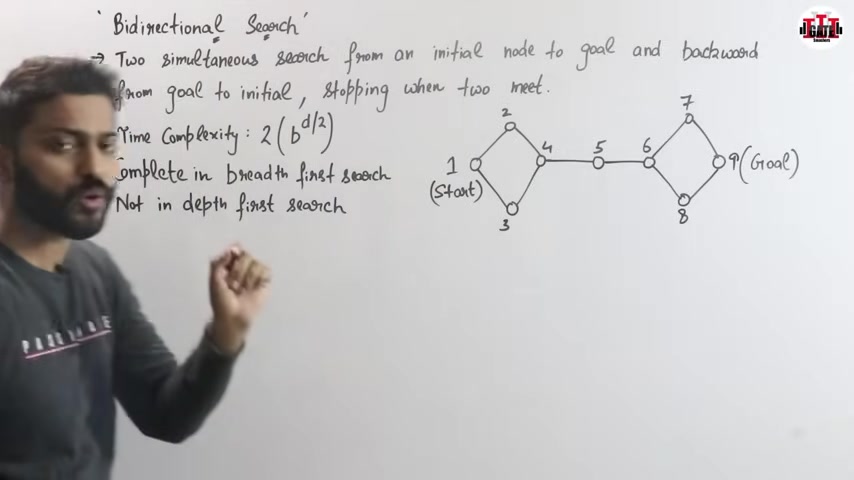
Bidirectional search is a graph search algorithm that simultaneously explores the graph from both the initial node and the goal node
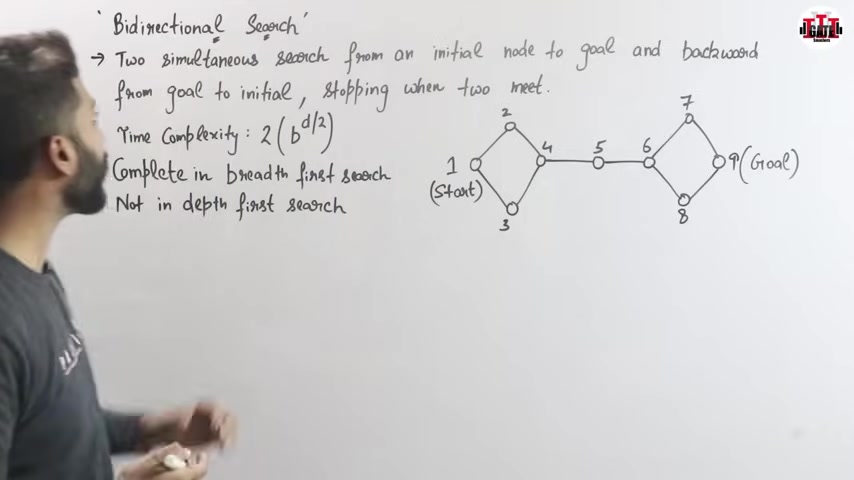
. It operates under the principle that searching from both ends can lead to a faster discovery of the path compared to searching from just one end. Imagine two teams working together to dig a tunnel. One team starts from one side and the other from the opposite side. They are much more likely to meet quicker than one team digging alone for a longer period of time.
The core idea is to reduce the overall search space by meeting in the middle. This method is particularly beneficial when the branching factor (the number of children per node) is high, as the search space expands exponentially with each level. By cutting the search depth in half, we can dramatically reduce the number of nodes that need to be explored.
This approach is especially effective when both the start and goal states are clearly defined and accessible. The time saved becomes significantly more pronounced in problems where finding the successors and predecessors of a node is relatively straightforward.
How Bidirectional Search Works
The bidirectional search algorithm operates in a specific manner, ensuring efficient path discovery:
- Initialization: Start two separate searches: a forward search from the initial state and a backward search from the goal state.
- Simultaneous Exploration: Expand nodes simultaneously from both search frontiers. This expansion can follow a Breadth-First Search or other search strategy, but BFS is generally preferred for completeness.
- Meeting in the Middle: The algorithm continuously expands nodes from both ends until the two search frontiers intersect
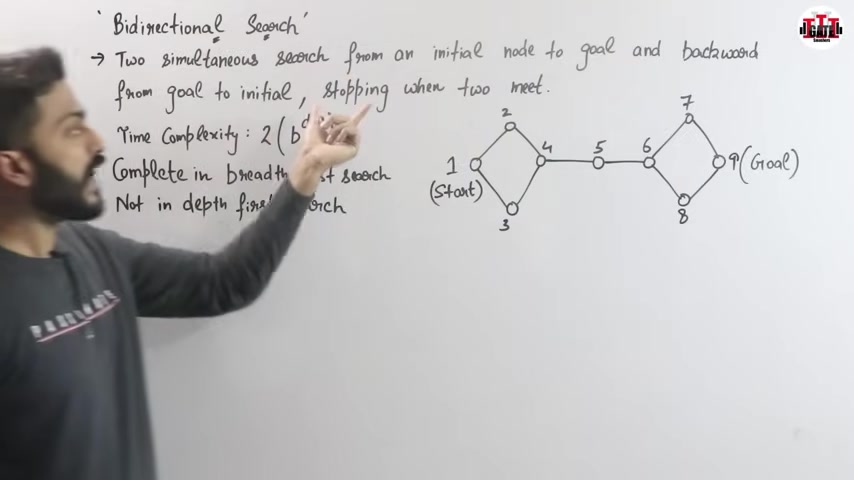
. The intersection signifies a path has been found.
- Path Reconstruction: Once the frontiers meet, the path is constructed by combining the path from the initial state to the meeting node and the reversed path from the goal state to the meeting node.
- Termination: The algorithm terminates when a common node is found in both the forward and backward search frontiers. This meeting point is crucial for reconstructing the complete path.
The beauty of this technique lies in its ability to reduce the depth of the search. By halving the search depth, the number of explored nodes can be significantly reduced, leading to substantial time savings.
Completeness and Optimality
Completeness refers to the algorithm's ability to find a solution if one exists. Optimality, on the other hand, refers to its ability to find the best possible solution (e.g., the shortest path).
Bidirectional search is complete if the search strategy used in both the forward and backward searches is complete. For instance, if Breadth-First Search is employed in both directions, the bidirectional search is guaranteed to find a solution if it exists. However, if Depth-First Search is used, completeness is not guaranteed, as DFS can get lost in infinite loops.
To ensure optimality, bidirectional search requires some additional considerations, especially when the edge costs are not uniform. In such cases, care must be taken to ensure that the path found is indeed the shortest or least costly. One common approach is to continue the search even after the frontiers meet, until the cost of all other possible paths is greater than the cost of the path found so far.
Bidirectional Search and Tree Traversal
Visualizing Breadth-First Search (BFS) in Tree Traversal
Breadth-First Search (BFS) is a fundamental tree traversal technique that explores all the nodes at the present depth prior to moving on to the nodes at the next depth level
. This level-by-level approach ensures that the algorithm finds the shortest path from the root node to any other node in the tree, making it optimal for pathfinding problems where all edges have equal weight.
- Level-by-Level Exploration: BFS systematically visits all nodes at each level before proceeding to the next level.
- Queue Data Structure: BFS utilizes a queue to maintain the order of nodes to be visited. The root node is enqueued first, and then, in each iteration, the node at the front of the queue is dequeued, visited, and its children are enqueued.
- Optimality in Pathfinding: BFS guarantees the shortest path in unweighted graphs, as it explores all possible paths of length 'k' before exploring any path of length 'k+1'.
This methodical exploration makes BFS a cornerstone of many search and optimization algorithms. BFS ensures that the algorithm explores all possible paths at a given depth before moving deeper into the tree.
Visualizing Depth-First Search (DFS) in Tree Traversal
Depth-First Search (DFS) is another essential tree traversal technique that explores as far as possible along each branch before backtracking
. This approach prioritizes depth over breadth, making it suitable for problems where the goal is to find any solution, even if it's not the shortest.
- Branch Exploration: DFS explores each branch to its maximum depth before moving to the next branch.
- Stack Data Structure: DFS utilizes a stack (or recursion) to keep track of the nodes to be visited. The root node is pushed onto the stack, and in each iteration, the node at the top of the stack is popped, visited, and its unvisited children are pushed onto the stack.
- Suitable for Specific Problems: DFS is advantageous in scenarios where the goal node is known to be deep in the tree, or when memory usage is a concern due to its lower memory footprint compared to BFS.
However, DFS does not guarantee the shortest path and may get stuck in infinite loops if the graph contains cycles. DFS does not guarantee finding the optimal solution and may not even find a solution at all if it explores an infinite branch. Therefore, DFS is most effective when used in conjunction with techniques like iterative deepening to prevent infinite loops and to find the shortest path.
Core Features (Algorithm Specifics)
Core Features (Algorithm Specifics)
The "core features" of Bidirectional Search are algorithm-specific, not product-related:
- Simultaneous Forward and Backward Search: Expands nodes from both the start and goal states concurrently.
- Meeting Point Termination: Halts execution once the search frontiers meet, signifying a path has been discovered.
- Breadth-First Search Foundation: Completeness is guaranteed in breadth-first search, which the bidirectional approach extends
.
- Optimized Search: Reduces the search space by meeting in the middle, improving efficiency.
- Adaptability: Compatible with various search problems and graph structures.







Most people like





















Report
Please select a reason for reporting
- 13 Reasons to Switch from Snapchat to Text Messaging
- 7 Powerful Speech to Text Apps to Boost Productivity
- 10 Best Speech to Text Tools for Effortless Transcription
- 13 Free Tools to Easily Transcribe Audio to Text
- 15 Surprising Ways Google's Speech-to-Text Boosts Productivity
- 7 Best Free Online Audio to Text Transcription Tools
- 9 Tips to Transcribe Speech to Text Faster and Better
- 13 Best Speech to Text Software for Windows 10 in 2023
- 7 Tips for Choosing the Best Transcriber for Audio to Text
- 11 Reasons Why Dragon Speech-to-Text Apps are Game-Changers
- 6 Secrets to Enhance Your Speech to Text Transcription
- 6 Brilliant Ways to Boost Productivity with Talk-to-Text on Your MacBook
- 6 Ways Transcription Software Converts Audio to Text
- 8 Tips to Transcribe Speech to Text Like a Pro
- 6 Reasons IBM Watson Speech to Text is a Game-Changer
- 14 Powerful Ways Talk-to-Text Improves Your Workflow
- 12 Top Windows Speech-to-Text Software for Efficient Transcription
- 12 Game-Changing Benefits of Apple's Speech to Text Technology
- 9 Powerful Use Cases for AWS Speech to Text Technology
- 10 Easy Steps to Transcribe YouTube Videos to Text
- transcription audio en texte
- online audio transcription
- free audio file transcription
- free ai audio transcription
- audio transcription service
- audio transcription online free
- audio transcription free online
- audio to transcription software
- audio and transcript
- ai audio transcription free
- voice recording to text converter
- translate voice recording to text
- record voice to text
- audio recording to text converter
- voice recording and transcription
- chatgpt voice to text
- gmail voice to text
- speech to text reader
- speech to text ai free
- speech to talk
- How to Use AI Tools to Find Internal Linking Opportunities Across a Business Website
- Discover Your Perfect Haircut with AI Hairstyle Apps
- Free Reputation Calculator Tools: How They're Adapting to Score AI Visibility, Not Just Rankings
- Design Professional Flyers for Free on Your Phone
- Best Free Flyer Maker Apps for Android: Design Like a Pro
- How to Know If Your Business Is Ready for an AI Customer Service Agent
- Revolutionizing Storytelling: From Novels to Screenplays with AI
- Create Engaging Animated Explainer Videos with a Free AI Tool
- Stop Multi-Subscribing: Benchmark Top AI Visual Models in One Canvas
- Best Seedance 2.5 API Provider: Every Price on the Market, Checked at Source
- Top AI Social Media Management Tools: Automate Your Content Strategy
- Free AI Text to Video Generator: Create Stunning Videos from Text
- Discover 17 ChatGPT Alternatives: A Comprehensive Comparison
- Character.AI vs. Janitor AI: Which AI Chat Platform Reigns Supreme?
- Top Virtual Assistant Companies in 2026: Reviews, Pricing, and Plans Compared
- Unveiling FaceCheck.ID: Revolutionizing Reverse Image Searches with AI
- 11 Best AI Dialers in 2026: Features, Pricing, Pros and Cons
- How I Direct Consistent AI Clips: A Hands-On Guide to Multi-Model Generation
- A Realistic Review of the Photo Generator Image Tool
- Playwright MCP Server: Automated Web Testing with Agent Mode
Copyright ©2026 toolify