
chenxwh / hart

Efficient Visual Generation with Hybrid Autoregressive Transformer

replicate.com
Total runs: 121
24-hour runs: 0
7-day runs: 0
30-day runs: 0
Github
Model's Last Updated: October 19 2024

Introduction of hart

Model Details of hart

Readme

HART: Efficient Visual Generation with Hybrid Autoregressive Transformer
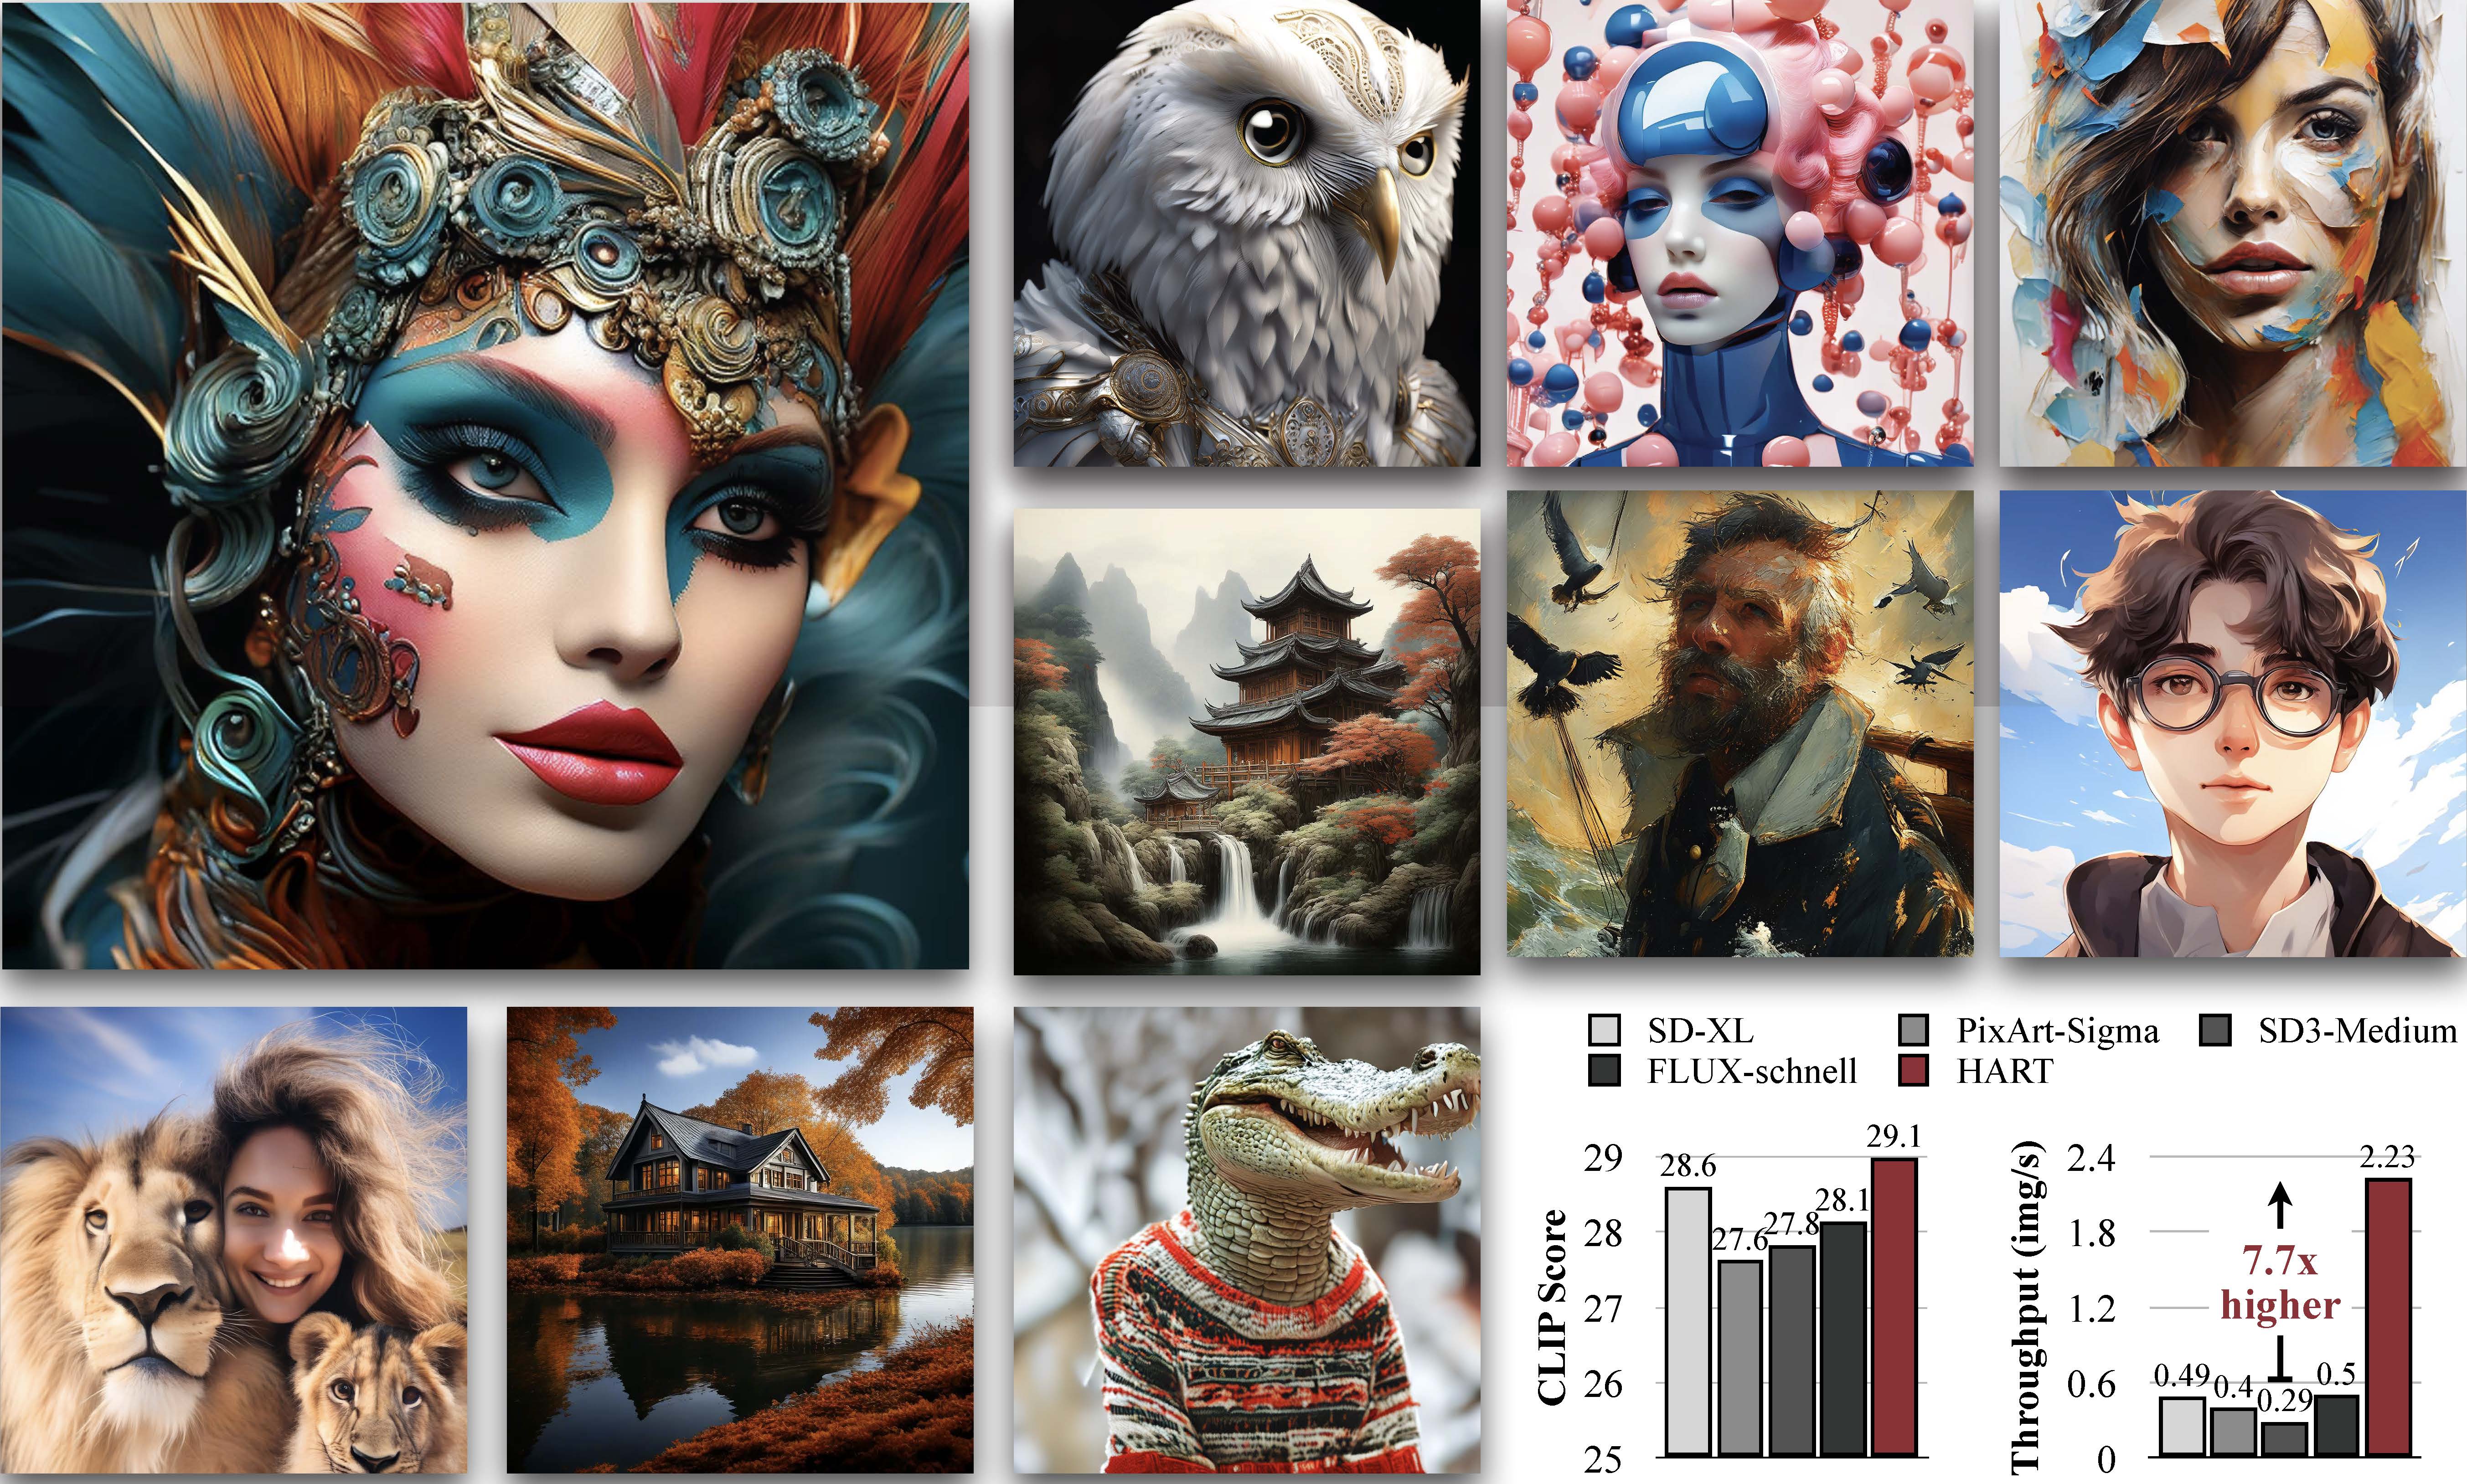
teaser_Page1

Abstract

We introduce Hybrid Autoregressive Transformer (HART), an autoregressive (AR) visual generation model capable of directly generating 1024x1024 images, rivaling diffusion models in image generation quality. Existing AR models face limitations due to the poor image reconstruction quality of their discrete tokenizers and the prohibitive training costs associated with generating 1024px images. To address these challenges, we present the hybrid tokenizer, which decomposes the continuous latents from the autoencoder into two components: discrete tokens representing the big picture and continuous tokens representing the residual components that cannot be represented by the discrete tokens. The discrete component is modeled by a scalable-resolution discrete AR model, while the continuous component is learned with a lightweight residual diffusion module with only 37M parameters. Compared with the discrete-only VAR tokenizer, our hybrid approach improves reconstruction FID from 2.11 to 0.30 on MJHQ-30K, leading to a 31% generation FID improvement from 7.85 to 5.38 . HART also outperforms state-of-the-art diffusion models in both FID and CLIP score, with 4.5-7.7x higher throughput and 6.9-13.4x lower MACs.

Acknowledgements

Our codebase is inspired by amazing open source research projects such as VAR and MAR . The authors would like to thank Tianhong Li from MIT, Lijun Yu from Google DeepMind, Kaiwen Zha from MIT and Yunhao Fang from UCSD for helpful discussions; and Paul Palei, Mike Hobbs, Chris Hill, Michel Erb from MIT for setting up the online demo and maintaining the server.

Citation
@article{tang2024hart,
  title={HART: Efficient Visual Generation with Hybrid Autoregressive Transformer},
  author={Tang, Haotian and Wu, Yecheng and Yang, Shang and Xie, Enze and Chen, Junsong and Chen, Junyu and Zhang, Zhuoyang and Cai, Han and Lu, Yao and Han, Song},
  journal={arXiv preprint},
  year={2024}
}
Runs of chenxwh hart on replicate.com

121
Total runs
0
24-hour runs
0
3-day runs
0
7-day runs
0
30-day runs

More Information About hart replicate.com Model

hart replicate.com

hart replicate.com is an AI model on replicate.com that provides hart's model effect (Efficient Visual Generation with Hybrid Autoregressive Transformer), which can be used instantly with this chenxwh hart model. replicate.com supports a free trial of the hart model, and also provides paid use of the hart. Support call hart model through api, including Node.js, Python, http.

chenxwh hart online free

hart replicate.com is an online trial and call api platform, which integrates hart's modeling effects, including api services, and provides a free online trial of hart, you can try hart online for free by clicking the link below.

chenxwh hart online free url in replicate.com:

https://replicate.com/chenxwh/hart

hart install

hart is an open source model from GitHub that offers a free installation service, and any user can find hart on GitHub to install. At the same time, replicate.com provides the effect of hart install, users can directly use hart installed effect in replicate.com for debugging and trial. It also supports api for free installation.

hart install url in replicate.com:

https://replicate.com/chenxwh/hart

hart install url in github:

https://github.com/chenxwh/hart

Url of hart

Provider of hart replicate.com

Other API from chenxwh

replicate

Fast sdxl with higher quality

Total runs: 729.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:May 27 2024
replicate

CogVLM2: Visual Language Models for Image and Video Understanding

Total runs: 650.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 25 2024
replicate

Depth estimation with faster inference speed, fewer parameters, and higher depth accuracy.

Total runs: 194.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 30 2024
replicate

Updated to OpenVoice v2: Versatile Instant Voice Cloning

Total runs: 55.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:May 18 2024
replicate

Audio-based Lip Synchronization for Talking Head Video

Total runs: 28.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:January 16 2024
replicate

Fast and High-Quality Text-to-video Generation

Total runs: 4.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 01 2024
replicate

OmniGen: Unified Image Generation

Total runs: 4.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 04 2024
replicate

Scalable Streaming Speech Synthesis with Large Language Models

Total runs: 3.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:December 26 2024
replicate

DiT-based video generation model for generating high-quality videos in real-time

Total runs: 2.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 24 2024
replicate

Convert LLM's coding to image generation

Total runs: 1.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 03 2024
replicate

Sharp Monocular Metric Depth in Less Than a Second

Total runs: 1.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 13 2024
replicate

Minimal and Universal Control for Diffusion Transformer - demo for Subject-driven generation

Total runs: 1.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:January 01 2025
replicate

Mixture-of-Experts Vision-Language Models for Advanced Multimodal Understanding

Total runs: 1.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:December 29 2024
replicate

CogVLM2: Visual Language Models for Image and Video Understanding

Total runs: 573
Run Growth: 0
Growth Rate: 0.00%
Updated:September 25 2024
replicate

Efficient High-Resolution Image Synthesis with Linear Diffusion Transformer

Total runs: 358
Run Growth: 0
Growth Rate: 0.00%
Updated:November 24 2024
replicate

A Powerful Multi-Resolution Diffusion Transformer with Fine-Grained Chinese Understanding

Total runs: 333
Run Growth: 0
Growth Rate: 0.00%
Updated:May 24 2024
replicate

Extended video synthesis model that generates 128 frames

Total runs: 203
Run Growth: 0
Growth Rate: 0.00%
Updated:July 01 2024
replicate

Depth Any Video with Scalable Synthetic Data

Total runs: 150
Run Growth: 0
Growth Rate: 0.00%
Updated:October 20 2024
replicate

High-Fidelity Single-Step Diffusion through Dynamic Adversarial Training

Total runs: 147
Run Growth: 0
Growth Rate: 0.00%
Updated:December 07 2024
replicate

Generating Consistent Long Depth Sequences for Open-world Videos

Total runs: 141
Run Growth: 0
Growth Rate: 0.00%
Updated:October 01 2024
replicate

One Diffusion to Generate Them All

Total runs: 135
Run Growth: 0
Growth Rate: 0.00%
Updated:December 31 2024
replicate

Diffusion-based Visual Foundation Model for High-quality Dense Prediction

Total runs: 131
Run Growth: 0
Growth Rate: 0.00%
Updated:October 07 2024
replicate

Minimal and Universal Control for Diffusion Transformer - demo for Spatially aligned control

Total runs: 96
Run Growth: 0
Growth Rate: 0.00%
Updated:January 01 2025
replicate

Image-to-Video Diffusion Models with An Expert Transformer

Total runs: 74
Run Growth: 0
Growth Rate: 0.00%
Updated:September 22 2024
replicate

Finer and Faster Text-to-Image Generation via Relay Diffusion

Total runs: 44
Run Growth: 0
Growth Rate: 0.00%
Updated:October 15 2024
replicate

Text-to-Video Diffusion Models with An Expert Transformer

Total runs: 42
Run Growth: 0
Growth Rate: 0.00%
Updated:September 21 2024
replicate

Revitalizing Masked Generative Transformers for Efficient High-Resolution Text-to-Image Synthesis

Total runs: 36
Run Growth: 0
Growth Rate: 0.00%
Updated:October 21 2024
replicate

Autoregressive Video Generation without Vector Quantization

Total runs: 32
Run Growth: 0
Growth Rate: 0.00%
Updated:December 27 2024
replicate

Emu3-Gen for image generation

Total runs: 27
Run Growth: 0
Growth Rate: 0.00%
Updated:September 30 2024
replicate

Temporal-Consistent Diffusion Model for Real-World Video Super-Resolution

Total runs: 20
Run Growth: 0
Growth Rate: 0.00%
Updated:September 22 2024
replicate

Emu3-Chat for vision-language understanding

Total runs: 18
Run Growth: 0
Growth Rate: 0.00%
Updated:September 30 2024
replicate

Autoregressive Image Generation without Vector Quantization

Total runs: 14
Run Growth: 0
Growth Rate: 0.00%
Updated:December 27 2024
replicate

Let Vision Language Models Reason Step-by-Step

Total runs: 13
Run Growth: 0
Growth Rate: 0.00%
Updated:December 02 2024
replicate

Enhancing Video Model Post-Training through Data, Reward, and Conditional Guidance Design

Total runs: 10
Run Growth: 0
Growth Rate: 0.00%
Updated:October 14 2024
replicate

Text-to-Video Diffusion Models with An Expert Transformer

Total runs: 4
Run Growth: 0
Growth Rate: 0.00%
Updated:September 21 2024