
chenxwh / sana

Efficient High-Resolution Image Synthesis with Linear Diffusion Transformer

replicate.com
Total runs: 358
24-hour runs: 0
7-day runs: 0
30-day runs: 0
Github
Model's Last Updated: November 24 2024

Introduction of sana

Model Details of sana

Readme

⚡️Sana: Efficient High-Resolution Image Synthesis with Linear Diffusion Transformer
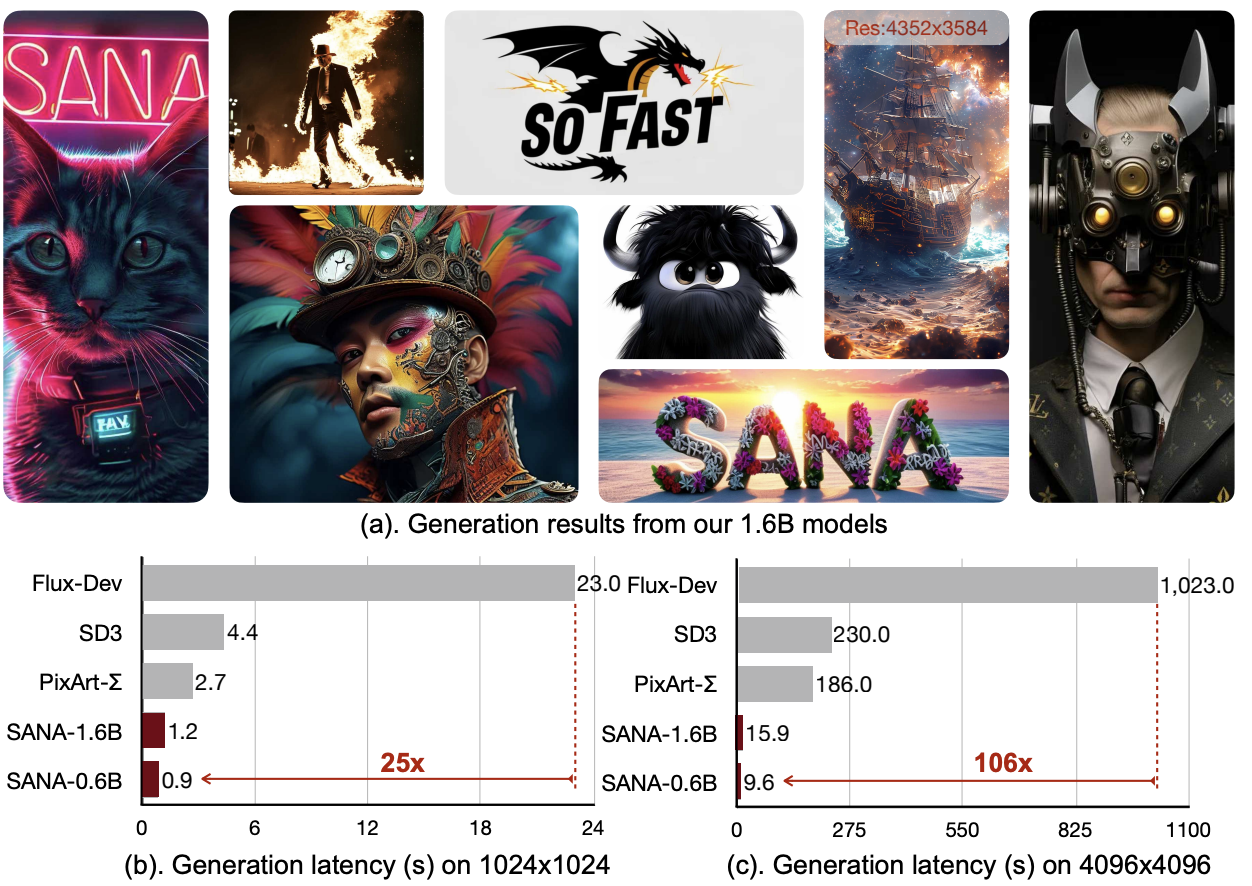
teaser_page1

💡 Introduction

We introduce Sana, a text-to-image framework that can efficiently generate images up to 4096 × 4096 resolution. Sana can synthesize high-resolution, high-quality images with strong text-image alignment at a remarkably fast speed, deployable on laptop GPU. Core designs include:

(1) DC-AE : unlike traditional AEs, which compress images only 8×, we trained an AE that can compress images 32×, effectively reducing the number of latent tokens. \ (2) Linear DiT : we replace all vanilla attention in DiT with linear attention, which is more efficient at high resolutions without sacrificing quality. \ (3) Decoder-only text encoder : we replaced T5 with modern decoder-only small LLM as the text encoder and designed complex human instruction with in-context learning to enhance the image-text alignment. \ (4) Efficient training and sampling : we propose Flow-DPM-Solver to reduce sampling steps, with efficient caption labeling and selection to accelerate convergence.

As a result, Sana-0.6B is very competitive with modern giant diffusion model (e.g. Flux-12B), being 20 times smaller and 100+ times faster in measured throughput. Moreover, Sana-0.6B can be deployed on a 16GB laptop GPU, taking less than 1 second to generate a 1024 × 1024 resolution image. Sana enables content creation at low cost.
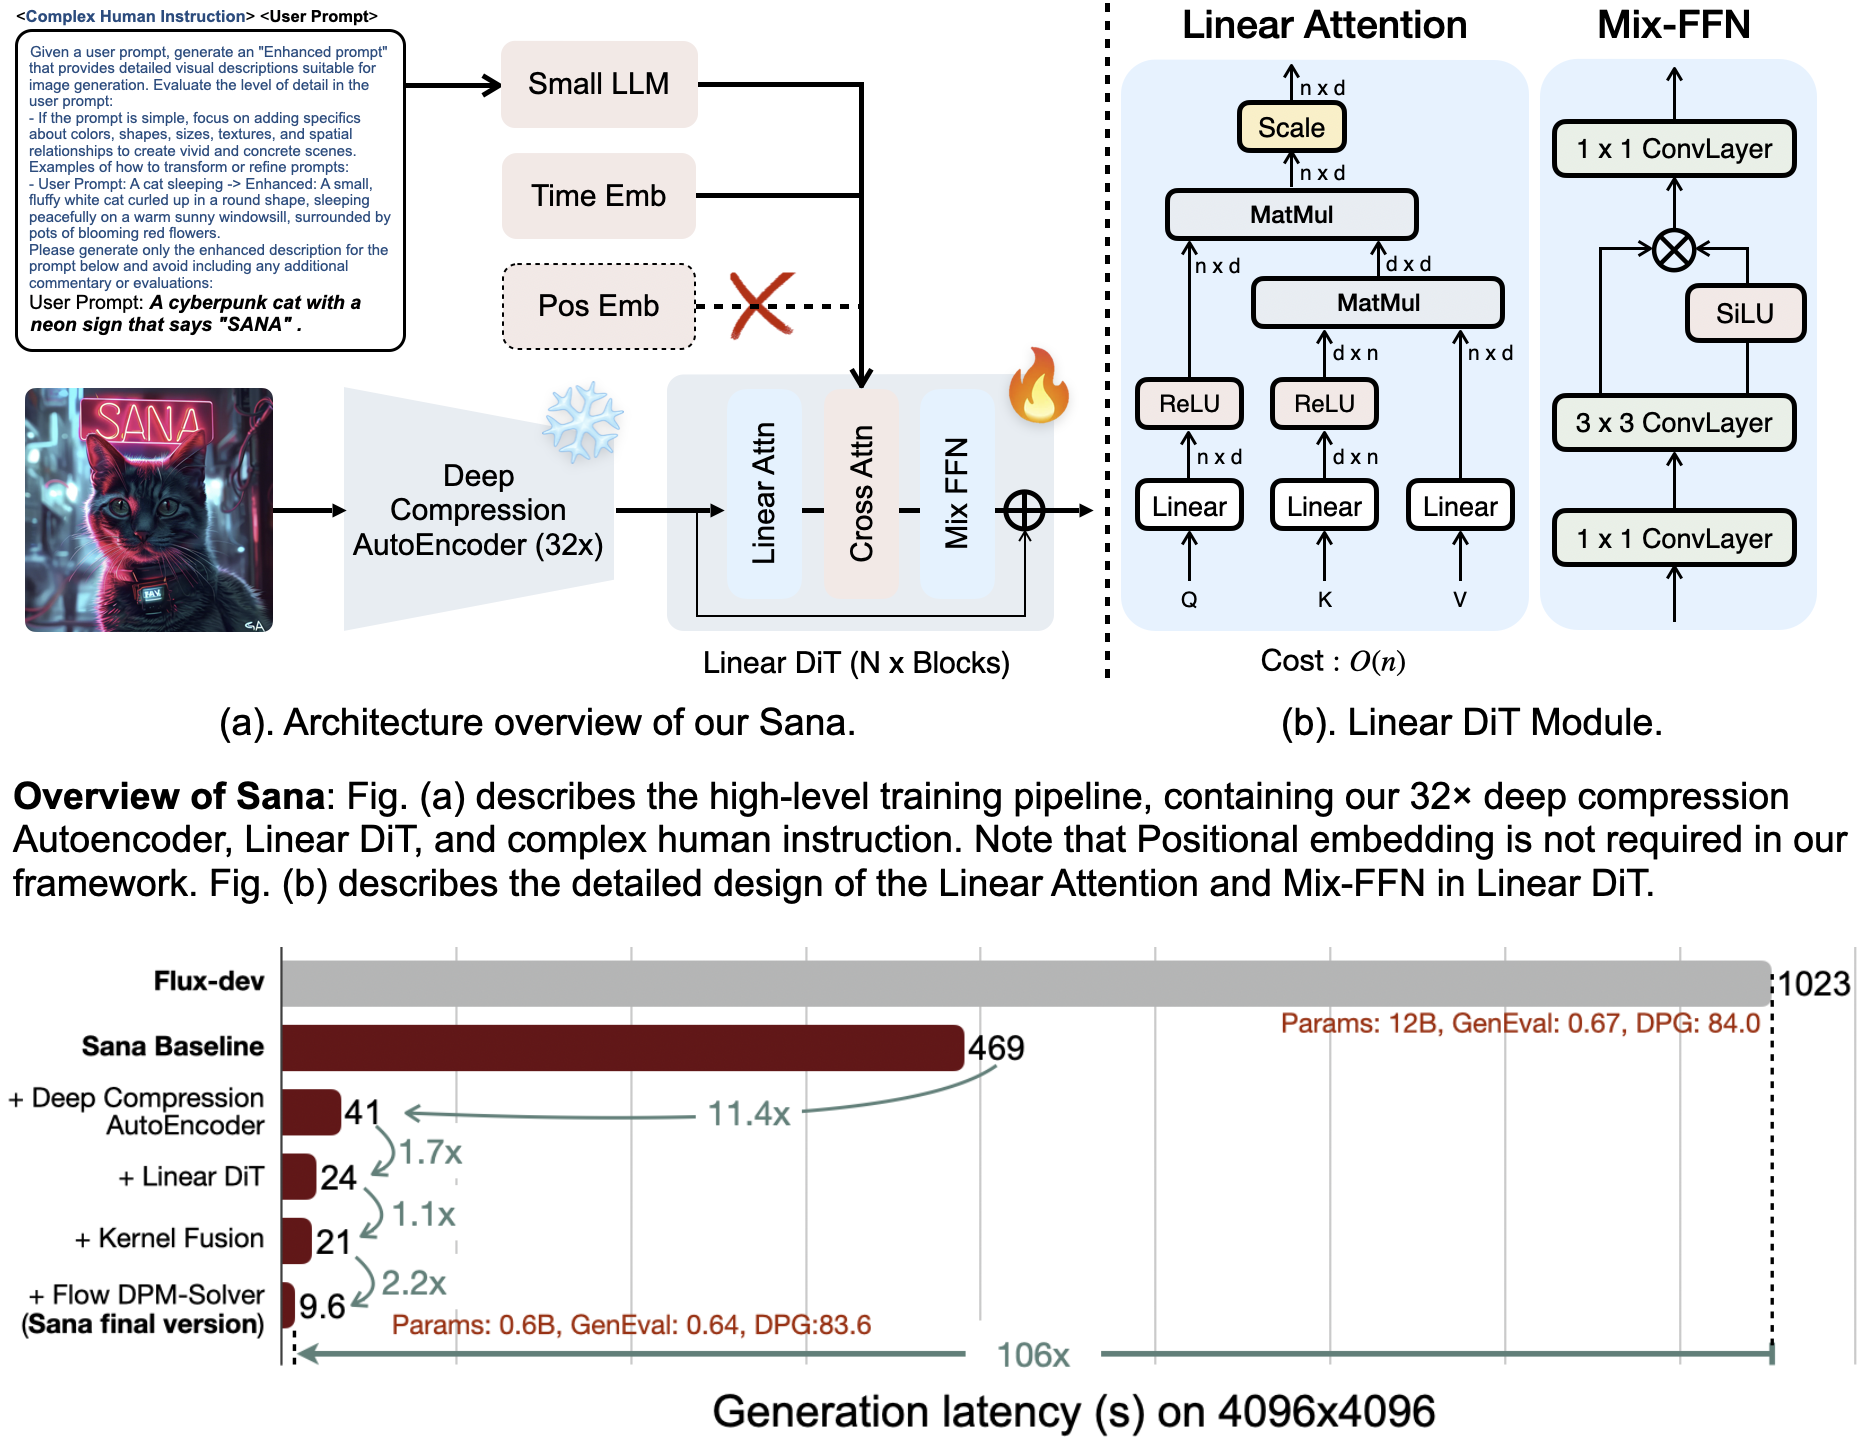
teaser_page2

🤗Acknowledgements

📖BibTeX

@misc{xie2024sana,
      title={Sana: Efficient High-Resolution Image Synthesis with Linear Diffusion Transformer},
      author={Enze Xie and Junsong Chen and Junyu Chen and Han Cai and Haotian Tang and Yujun Lin and Zhekai Zhang and Muyang Li and Ligeng Zhu and Yao Lu and Song Han},
      year={2024},
      eprint={2410.10629},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2410.10629},
    }
Runs of chenxwh sana on replicate.com

358
Total runs
0
24-hour runs
0
3-day runs
0
7-day runs
0
30-day runs

More Information About sana replicate.com Model

sana replicate.com

sana replicate.com is an AI model on replicate.com that provides sana's model effect (Efficient High-Resolution Image Synthesis with Linear Diffusion Transformer), which can be used instantly with this chenxwh sana model. replicate.com supports a free trial of the sana model, and also provides paid use of the sana. Support call sana model through api, including Node.js, Python, http.

chenxwh sana online free

sana replicate.com is an online trial and call api platform, which integrates sana's modeling effects, including api services, and provides a free online trial of sana, you can try sana online for free by clicking the link below.

chenxwh sana online free url in replicate.com:

https://replicate.com/chenxwh/sana

sana install

sana is an open source model from GitHub that offers a free installation service, and any user can find sana on GitHub to install. At the same time, replicate.com provides the effect of sana install, users can directly use sana installed effect in replicate.com for debugging and trial. It also supports api for free installation.

sana install url in replicate.com:

https://replicate.com/chenxwh/sana

sana install url in github:

https://github.com/chenxwh/Sana

Url of sana

Provider of sana replicate.com

Other API from chenxwh

replicate

Fast sdxl with higher quality

Total runs: 729.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:May 27 2024
replicate

CogVLM2: Visual Language Models for Image and Video Understanding

Total runs: 650.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 25 2024
replicate

Depth estimation with faster inference speed, fewer parameters, and higher depth accuracy.

Total runs: 194.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 30 2024
replicate

Updated to OpenVoice v2: Versatile Instant Voice Cloning

Total runs: 55.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:May 18 2024
replicate

Audio-based Lip Synchronization for Talking Head Video

Total runs: 28.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:January 16 2024
replicate

Fast and High-Quality Text-to-video Generation

Total runs: 4.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 01 2024
replicate

OmniGen: Unified Image Generation

Total runs: 4.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 04 2024
replicate

Scalable Streaming Speech Synthesis with Large Language Models

Total runs: 3.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:December 26 2024
replicate

DiT-based video generation model for generating high-quality videos in real-time

Total runs: 2.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 24 2024
replicate

Convert LLM's coding to image generation

Total runs: 1.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 03 2024
replicate

Sharp Monocular Metric Depth in Less Than a Second

Total runs: 1.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 13 2024
replicate

Minimal and Universal Control for Diffusion Transformer - demo for Subject-driven generation

Total runs: 1.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:January 01 2025
replicate

Mixture-of-Experts Vision-Language Models for Advanced Multimodal Understanding

Total runs: 1.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:December 29 2024
replicate

CogVLM2: Visual Language Models for Image and Video Understanding

Total runs: 573
Run Growth: 0
Growth Rate: 0.00%
Updated:September 25 2024
replicate

A Powerful Multi-Resolution Diffusion Transformer with Fine-Grained Chinese Understanding

Total runs: 333
Run Growth: 0
Growth Rate: 0.00%
Updated:May 24 2024
replicate

Extended video synthesis model that generates 128 frames

Total runs: 203
Run Growth: 0
Growth Rate: 0.00%
Updated:July 01 2024
replicate

Depth Any Video with Scalable Synthetic Data

Total runs: 150
Run Growth: 0
Growth Rate: 0.00%
Updated:October 20 2024
replicate

High-Fidelity Single-Step Diffusion through Dynamic Adversarial Training

Total runs: 147
Run Growth: 0
Growth Rate: 0.00%
Updated:December 07 2024
replicate

Generating Consistent Long Depth Sequences for Open-world Videos

Total runs: 141
Run Growth: 0
Growth Rate: 0.00%
Updated:October 01 2024
replicate

One Diffusion to Generate Them All

Total runs: 135
Run Growth: 0
Growth Rate: 0.00%
Updated:December 31 2024
replicate

Diffusion-based Visual Foundation Model for High-quality Dense Prediction

Total runs: 131
Run Growth: 0
Growth Rate: 0.00%
Updated:October 07 2024
replicate

Efficient Visual Generation with Hybrid Autoregressive Transformer

Total runs: 121
Run Growth: 0
Growth Rate: 0.00%
Updated:October 19 2024
replicate

Minimal and Universal Control for Diffusion Transformer - demo for Spatially aligned control

Total runs: 96
Run Growth: 0
Growth Rate: 0.00%
Updated:January 01 2025
replicate

Image-to-Video Diffusion Models with An Expert Transformer

Total runs: 74
Run Growth: 0
Growth Rate: 0.00%
Updated:September 22 2024
replicate

Finer and Faster Text-to-Image Generation via Relay Diffusion

Total runs: 44
Run Growth: 0
Growth Rate: 0.00%
Updated:October 15 2024
replicate

Text-to-Video Diffusion Models with An Expert Transformer

Total runs: 42
Run Growth: 0
Growth Rate: 0.00%
Updated:September 21 2024
replicate

Revitalizing Masked Generative Transformers for Efficient High-Resolution Text-to-Image Synthesis

Total runs: 36
Run Growth: 0
Growth Rate: 0.00%
Updated:October 21 2024
replicate

Autoregressive Video Generation without Vector Quantization

Total runs: 32
Run Growth: 0
Growth Rate: 0.00%
Updated:December 27 2024
replicate

Emu3-Gen for image generation

Total runs: 27
Run Growth: 0
Growth Rate: 0.00%
Updated:September 30 2024
replicate

Temporal-Consistent Diffusion Model for Real-World Video Super-Resolution

Total runs: 20
Run Growth: 0
Growth Rate: 0.00%
Updated:September 22 2024
replicate

Emu3-Chat for vision-language understanding

Total runs: 18
Run Growth: 0
Growth Rate: 0.00%
Updated:September 30 2024
replicate

Autoregressive Image Generation without Vector Quantization

Total runs: 14
Run Growth: 0
Growth Rate: 0.00%
Updated:December 27 2024
replicate

Let Vision Language Models Reason Step-by-Step

Total runs: 13
Run Growth: 0
Growth Rate: 0.00%
Updated:December 02 2024
replicate

Enhancing Video Model Post-Training through Data, Reward, and Conditional Guidance Design

Total runs: 10
Run Growth: 0
Growth Rate: 0.00%
Updated:October 14 2024
replicate

Text-to-Video Diffusion Models with An Expert Transformer

Total runs: 4
Run Growth: 0
Growth Rate: 0.00%
Updated:September 21 2024