
chenxwh / video-retalking

Audio-based Lip Synchronization for Talking Head Video

replicate.com
Total runs: 28.9K
24-hour runs: 0
7-day runs: 0
30-day runs: 0
Github
Model's Last Updated: January 16 2024

Introduction of video-retalking

Model Details of video-retalking

Readme
VideoReTalking: Audio-based Lip Synchronization for Talking Head Video Editing in the Wild
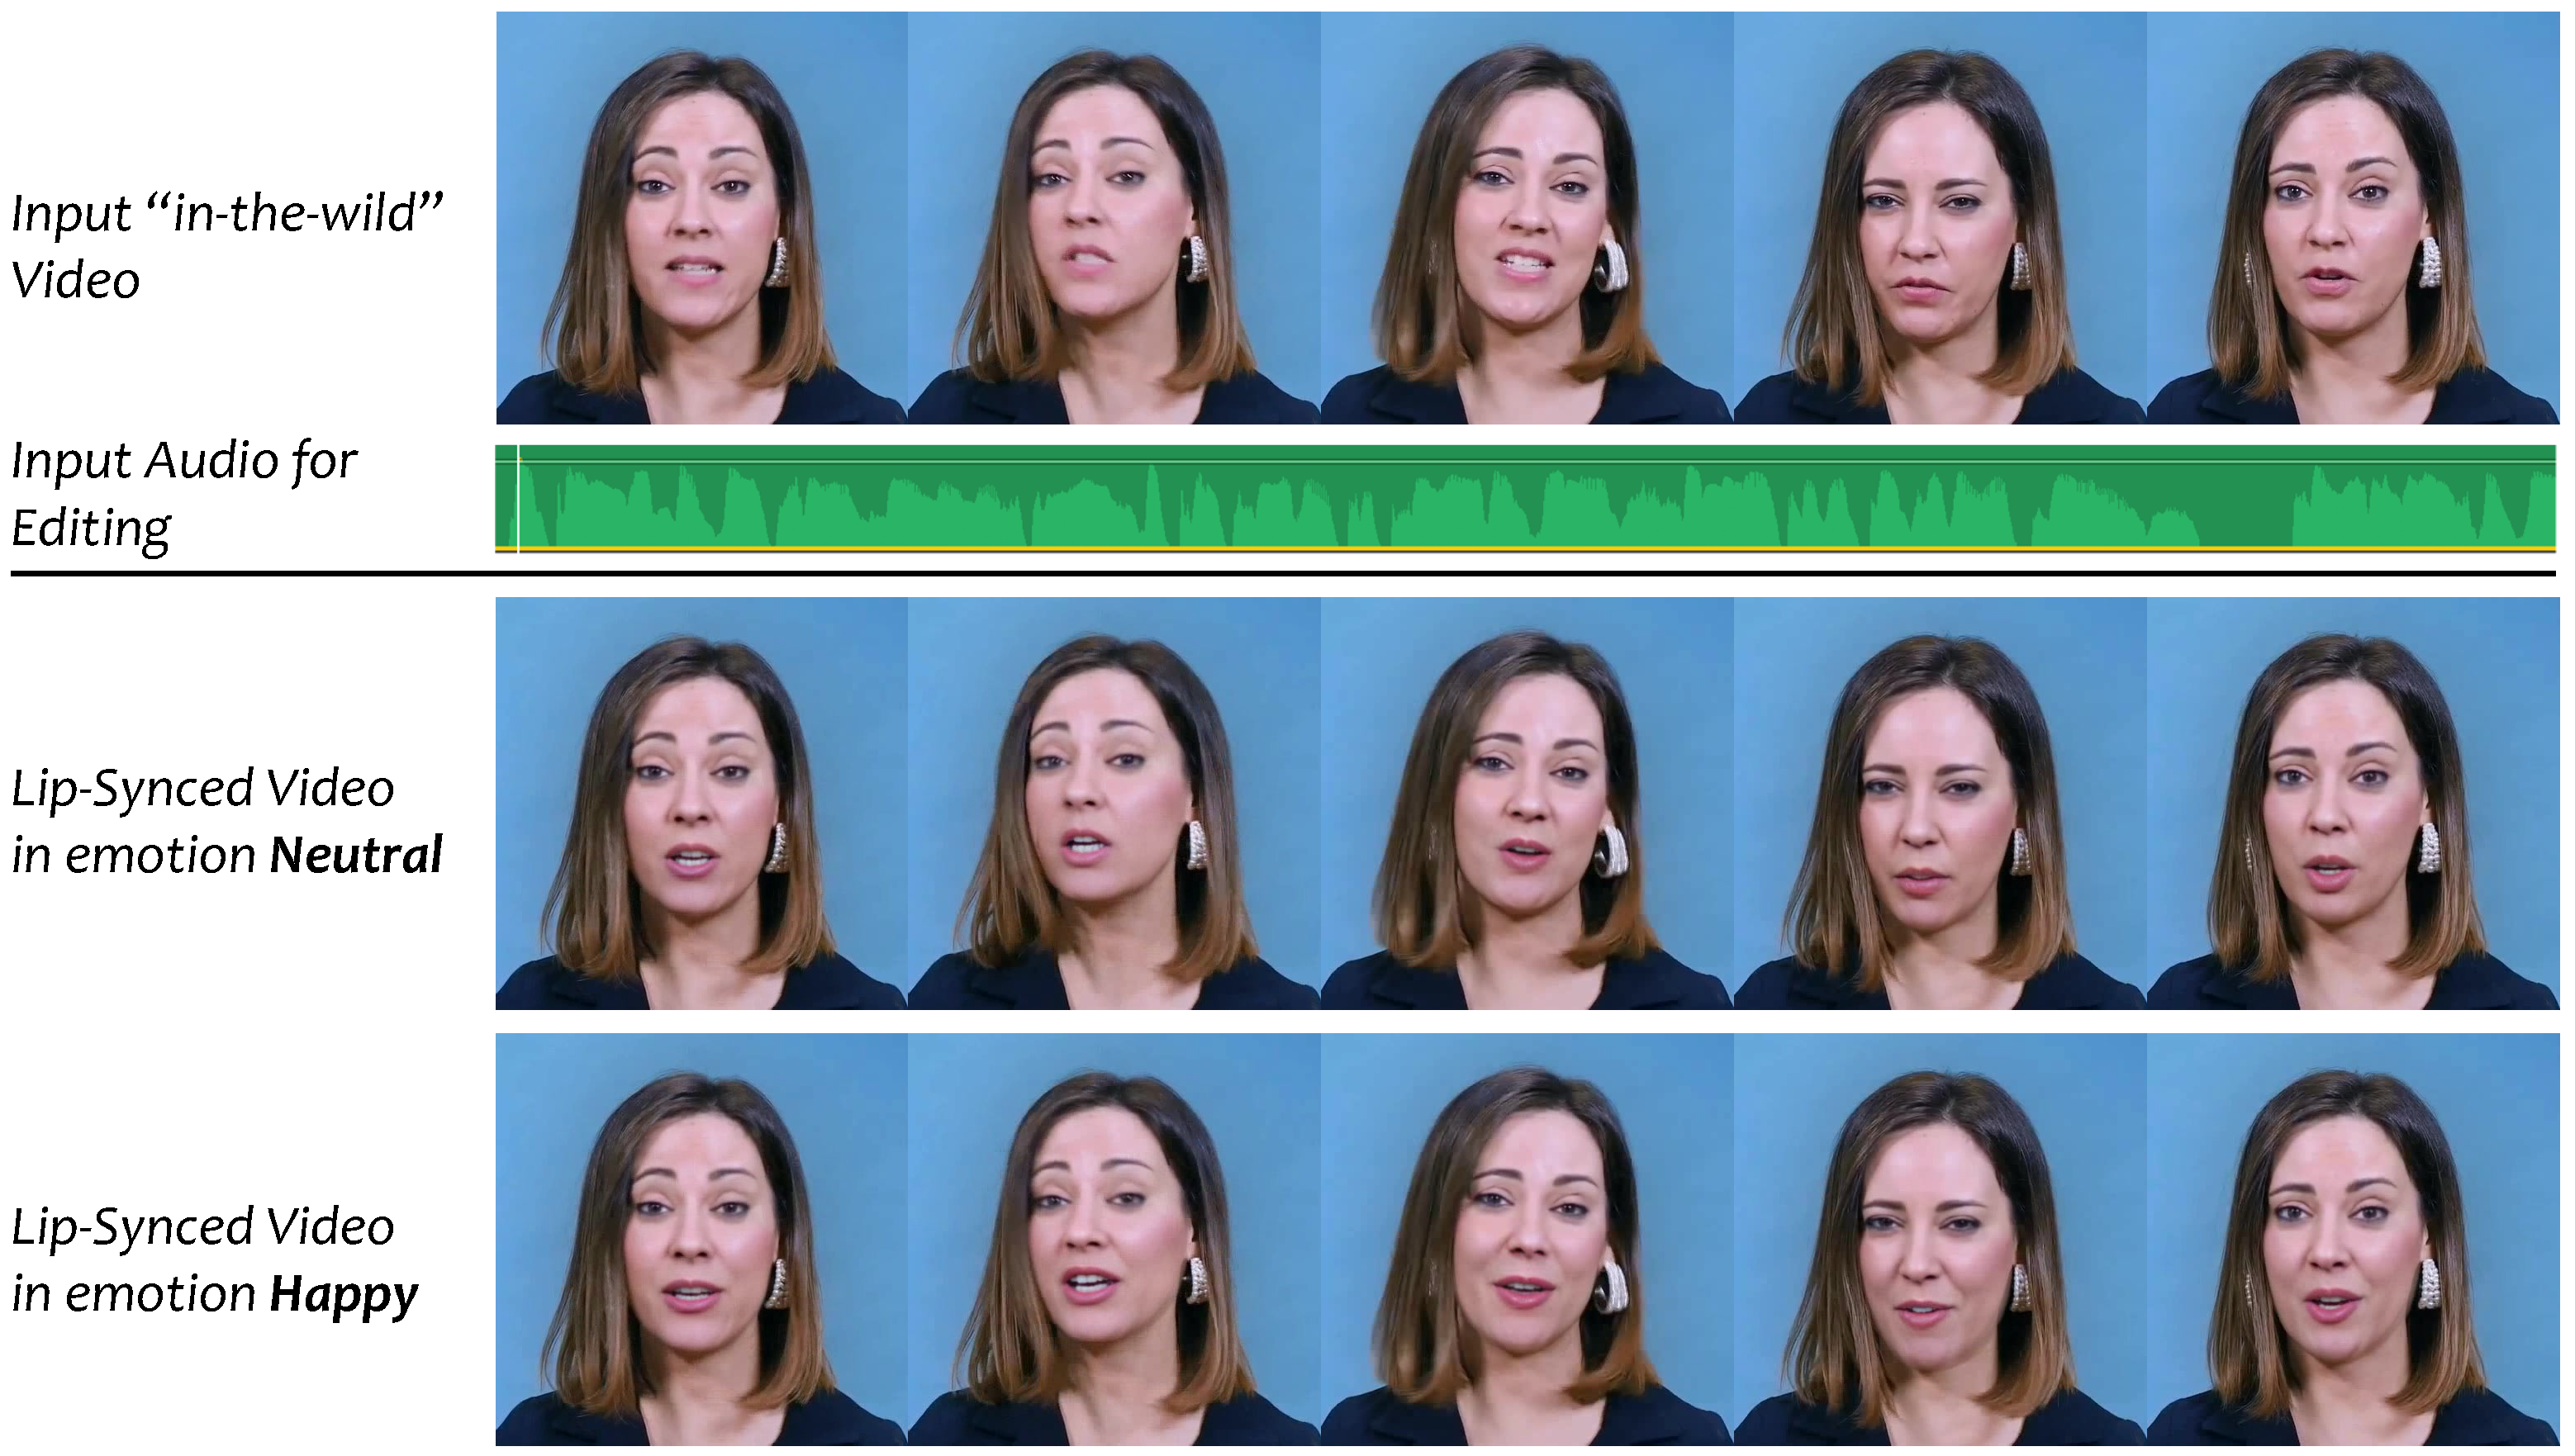
We present VideoReTalking, a new system to edit the faces of a real-world talking head video according to input audio, producing a high-quality and lip-syncing output video even with a different emotion. Our system disentangles this objective into three sequential tasks:

(1) face video generation with a canonical expression
(2) audio-driven lip-sync and
(3) face enhancement for improving photo-realism.

Given a talking-head video, we first modify the expression of each frame according to the same expression template using the expression editing network, resulting in a video with the canonical expression. This video, together with the given audio, is then fed into the lip-sync network to generate a lip-syncing video. Finally, we improve the photo-realism of the synthesized faces through an identity-aware face enhancement network and post-processing. We use learning-based approaches for all three steps and all our modules can be tackled in a sequential pipeline without any user intervention.

Citation

If you find our work useful in your research, please consider citing:

@misc{cheng2022videoretalking,
        title={VideoReTalking: Audio-based Lip Synchronization for Talking Head Video Editing In the Wild}, 
        author={Kun Cheng and Xiaodong Cun and Yong Zhang and Menghan Xia and Fei Yin and Mingrui Zhu and Xuan Wang and Jue Wang and Nannan Wang},
        year={2022},
        eprint={2211.14758},
        archivePrefix={arXiv},
        primaryClass={cs.CV}
  }
Acknowledgement

Thanks to Wav2Lip , PIRenderer , GFP-GAN , GPEN , ganimation_replicate , STIT for sharing their code.

Related Work
Disclaimer

This is not an official product of Tencent.

1. Please carefully read and comply with the open-source license applicable to this code before using it. 
2. Please carefully read and comply with the intellectual property declaration applicable to this code before using it.
3. This open-source code runs completely offline and does not collect any personal information or other data. If you use this code to provide services to end-users and collect related data, please take necessary compliance measures according to applicable laws and regulations (such as publishing privacy policies, adopting necessary data security strategies, etc.). If the collected data involves personal information, user consent must be obtained (if applicable). Any legal liabilities arising from this are unrelated to Tencent.
4. Without Tencent's written permission, you are not authorized to use the names or logos legally owned by Tencent, such as "Tencent." Otherwise, you may be liable for your legal responsibilities.
5. This open-source code does not have the ability to directly provide services to end-users. If you need to use this code for further model training or demos, as part of your product to provide services to end-users, or for similar use, please comply with applicable laws and regulations for your product or service. Any legal liabilities arising from this are unrelated to Tencent.
6. It is prohibited to use this open-source code for activities that harm the legitimate rights and interests of others (including but not limited to fraud, deception, infringement of others' portrait rights, reputation rights, etc.), or other behaviors that violate applicable laws and regulations or go against social ethics and good customs (including providing incorrect or false information, spreading pornographic, terrorist, and violent information, etc.). Otherwise, you may be liable for your legal responsibilities.
Pricing of video-retalking replicate.com

Run time and cost

This model costs approximately $0.22 to run on Replicate, or 4 runs per $1, but this varies depending on your inputs. It is also open source and you can run it on your own computer with Docker .

This model runs on Nvidia A40 (Large) GPU hardware . Predictions typically complete within 6 minutes. The predict time for this model varies significantly based on the inputs.

Runs of chenxwh video-retalking on replicate.com

28.9K
Total runs
0
24-hour runs
0
3-day runs
0
7-day runs
0
30-day runs

More Information About video-retalking replicate.com Model

video-retalking replicate.com

video-retalking replicate.com is an AI model on replicate.com that provides video-retalking's model effect (Audio-based Lip Synchronization for Talking Head Video), which can be used instantly with this chenxwh video-retalking model. replicate.com supports a free trial of the video-retalking model, and also provides paid use of the video-retalking. Support call video-retalking model through api, including Node.js, Python, http.

video-retalking replicate.com Url

https://replicate.com/chenxwh/video-retalking

chenxwh video-retalking online free

video-retalking replicate.com is an online trial and call api platform, which integrates video-retalking's modeling effects, including api services, and provides a free online trial of video-retalking, you can try video-retalking online for free by clicking the link below.

chenxwh video-retalking online free url in replicate.com:

https://replicate.com/chenxwh/video-retalking

video-retalking install

video-retalking is an open source model from GitHub that offers a free installation service, and any user can find video-retalking on GitHub to install. At the same time, replicate.com provides the effect of video-retalking install, users can directly use video-retalking installed effect in replicate.com for debugging and trial. It also supports api for free installation.

video-retalking install url in replicate.com:

https://replicate.com/chenxwh/video-retalking

video-retalking install url in github:

https://github.com/chenxwh/video-retalking

Url of video-retalking

video-retalking replicate.com Url

video-retalking Owner Github

Provider of video-retalking replicate.com

Other API from chenxwh

replicate

Fast sdxl with higher quality

Total runs: 729.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:May 27 2024
replicate

CogVLM2: Visual Language Models for Image and Video Understanding

Total runs: 650.6K
Run Growth: 0
Growth Rate: 0.00%
Updated:September 25 2024
replicate

Depth estimation with faster inference speed, fewer parameters, and higher depth accuracy.

Total runs: 194.7K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 30 2024
replicate

Updated to OpenVoice v2: Versatile Instant Voice Cloning

Total runs: 55.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:May 18 2024
replicate

Fast and High-Quality Text-to-video Generation

Total runs: 4.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 01 2024
replicate

OmniGen: Unified Image Generation

Total runs: 4.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 04 2024
replicate

Scalable Streaming Speech Synthesis with Large Language Models

Total runs: 3.0K
Run Growth: 0
Growth Rate: 0.00%
Updated:December 26 2024
replicate

DiT-based video generation model for generating high-quality videos in real-time

Total runs: 2.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:November 24 2024
replicate

Convert LLM's coding to image generation

Total runs: 1.9K
Run Growth: 0
Growth Rate: 0.00%
Updated:June 03 2024
replicate

Sharp Monocular Metric Depth in Less Than a Second

Total runs: 1.2K
Run Growth: 0
Growth Rate: 0.00%
Updated:October 13 2024
replicate

Minimal and Universal Control for Diffusion Transformer - demo for Subject-driven generation

Total runs: 1.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:January 01 2025
replicate

Mixture-of-Experts Vision-Language Models for Advanced Multimodal Understanding

Total runs: 1.1K
Run Growth: 0
Growth Rate: 0.00%
Updated:December 29 2024
replicate

CogVLM2: Visual Language Models for Image and Video Understanding

Total runs: 573
Run Growth: 0
Growth Rate: 0.00%
Updated:September 25 2024
replicate

Efficient High-Resolution Image Synthesis with Linear Diffusion Transformer

Total runs: 358
Run Growth: 0
Growth Rate: 0.00%
Updated:November 24 2024
replicate

A Powerful Multi-Resolution Diffusion Transformer with Fine-Grained Chinese Understanding

Total runs: 333
Run Growth: 0
Growth Rate: 0.00%
Updated:May 24 2024
replicate

Extended video synthesis model that generates 128 frames

Total runs: 203
Run Growth: 0
Growth Rate: 0.00%
Updated:July 01 2024
replicate

Depth Any Video with Scalable Synthetic Data

Total runs: 150
Run Growth: 0
Growth Rate: 0.00%
Updated:October 20 2024
replicate

High-Fidelity Single-Step Diffusion through Dynamic Adversarial Training

Total runs: 147
Run Growth: 0
Growth Rate: 0.00%
Updated:December 07 2024
replicate

Generating Consistent Long Depth Sequences for Open-world Videos

Total runs: 141
Run Growth: 0
Growth Rate: 0.00%
Updated:October 01 2024
replicate

One Diffusion to Generate Them All

Total runs: 135
Run Growth: 0
Growth Rate: 0.00%
Updated:December 31 2024
replicate

Diffusion-based Visual Foundation Model for High-quality Dense Prediction

Total runs: 131
Run Growth: 0
Growth Rate: 0.00%
Updated:October 07 2024
replicate

Efficient Visual Generation with Hybrid Autoregressive Transformer

Total runs: 121
Run Growth: 0
Growth Rate: 0.00%
Updated:October 19 2024
replicate

Minimal and Universal Control for Diffusion Transformer - demo for Spatially aligned control

Total runs: 96
Run Growth: 0
Growth Rate: 0.00%
Updated:January 01 2025
replicate

Image-to-Video Diffusion Models with An Expert Transformer

Total runs: 74
Run Growth: 0
Growth Rate: 0.00%
Updated:September 22 2024
replicate

Finer and Faster Text-to-Image Generation via Relay Diffusion

Total runs: 44
Run Growth: 0
Growth Rate: 0.00%
Updated:October 15 2024
replicate

Text-to-Video Diffusion Models with An Expert Transformer

Total runs: 42
Run Growth: 0
Growth Rate: 0.00%
Updated:September 21 2024
replicate

Revitalizing Masked Generative Transformers for Efficient High-Resolution Text-to-Image Synthesis

Total runs: 36
Run Growth: 0
Growth Rate: 0.00%
Updated:October 21 2024
replicate

Autoregressive Video Generation without Vector Quantization

Total runs: 32
Run Growth: 0
Growth Rate: 0.00%
Updated:December 27 2024
replicate

Emu3-Gen for image generation

Total runs: 27
Run Growth: 0
Growth Rate: 0.00%
Updated:September 30 2024
replicate

Temporal-Consistent Diffusion Model for Real-World Video Super-Resolution

Total runs: 20
Run Growth: 0
Growth Rate: 0.00%
Updated:September 22 2024
replicate

Emu3-Chat for vision-language understanding

Total runs: 18
Run Growth: 0
Growth Rate: 0.00%
Updated:September 30 2024
replicate

Autoregressive Image Generation without Vector Quantization

Total runs: 14
Run Growth: 0
Growth Rate: 0.00%
Updated:December 27 2024
replicate

Let Vision Language Models Reason Step-by-Step

Total runs: 13
Run Growth: 0
Growth Rate: 0.00%
Updated:December 02 2024
replicate

Enhancing Video Model Post-Training through Data, Reward, and Conditional Guidance Design

Total runs: 10
Run Growth: 0
Growth Rate: 0.00%
Updated:October 14 2024
replicate

Text-to-Video Diffusion Models with An Expert Transformer

Total runs: 4
Run Growth: 0
Growth Rate: 0.00%
Updated:September 21 2024