



Total runs:
213.5K
Run Growth:
125.2K
Growth Rate:
58.61%




MOSS‑TTS Family is an open‑source speech and sound generation model family from MOSI.AI and the OpenMOSS team . It is designed for high‑fidelity , high‑expressiveness , and complex real‑world scenarios , covering stable long‑form speech, multi‑speaker dialogue, voice/character design, environmental sound effects, and real‑time streaming TTS.
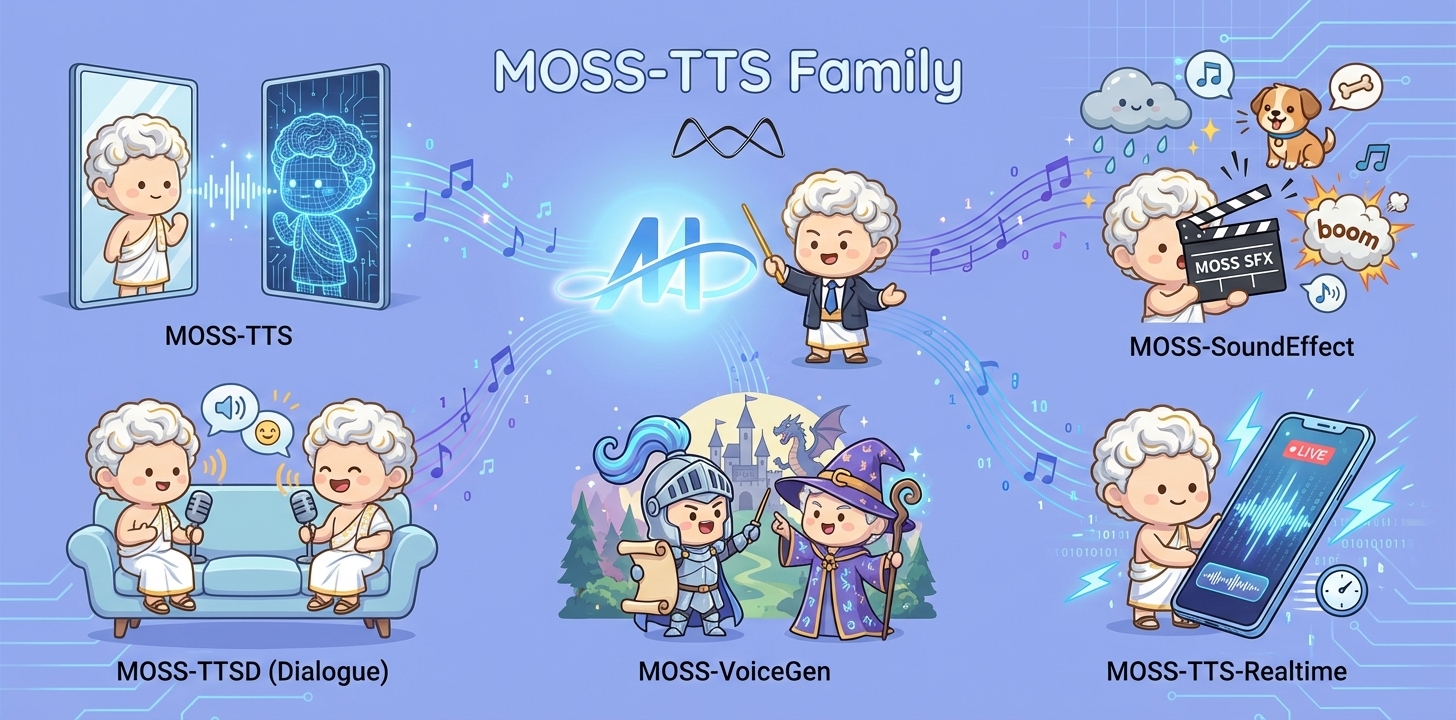
When a single piece of audio needs to sound like a real person , pronounce every word accurately , switch speaking styles across content , remain stable over tens of minutes , and support dialogue, role‑play, and real‑time interaction , a single TTS model is often not enough. The MOSS‑TTS Family breaks the workflow into five production‑ready models that can be used independently or composed into a complete pipeline.
| Model | Architecture | Size | Model Card | Hugging Face |
|---|---|---|---|---|
| MOSS-TTS | MossTTSDelay | 8B | moss_tts_model_card.md | 🤗 Huggingface |
| MossTTSLocal | 1.7B | moss_tts_model_card.md | 🤗 Huggingface | |
| MOSS‑TTSD‑V1.0 | MossTTSDelay | 8B | moss_ttsd_model_card.md | 🤗 Huggingface |
| MOSS‑VoiceGenerator | MossTTSDelay | 1.7B | moss_voice_generator_model_card.md | 🤗 Huggingface |
| MOSS‑SoundEffect | MossTTSDelay | 8B | moss_sound_effect_model_card.md | 🤗 Huggingface |
| MOSS‑TTS‑Realtime | MossTTSRealtime | 1.7B | moss_tts_realtime_model_card.md | 🤗 Huggingface |
MOSS-TTS is the flagship base model in our open-source TTS Family . It is designed as a production-ready synthesis backbone that can serve as the primary high-quality engine for scalable voice applications, and as a strong research baseline for controllable TTS and discrete audio token modeling.
Design goals
MOSS-TTS delivers state-of-the-art quality while providing the fine-grained controllability and long-form stability required for production-grade voice applications, from zero-shot cloning and hour-long narration to token- and phoneme-level control across multilingual and code-switched speech.
State-of-the-art evaluation performance — top-tier objective and subjective results across standard TTS benchmarks and in-house human preference testing, validating both fidelity and naturalness.
Zero-shot Voice Cloning (Voice Clone) — clone a target speaker’s timbre (and part of speaking style) from short reference audio, without speaker-specific fine-tuning.
Ultra-long Speech Generation (up to 1 hour) — support continuous long-form speech generation for up to one hour in a single run, designed for extended narration and long-session content creation.
Token-level Duration Control — control pacing, rhythm, pauses, and speaking rate at token resolution for precise alignment and expressive delivery.
Phoneme-level Pronunciation Control — supports:
Multilingual support — high-quality multilingual synthesis with robust generalization across languages and accents.
Code-switching — natural mixed-language generation within a single utterance (e.g., Chinese–English), with smooth transitions, consistent speaker identity, and pronunciation-aware rendering on both sides of the switch.
MOSS-TTS includes two complementary architectures , both trained and released to explore different performance/latency tradeoffs and to support downstream research.
Architecture A: Delay Pattern (MossTTSDelay)
Architecture B: Global Latent + Local Transformer (MossTTSLocal)
Why train both?
For full details, see:
| Model | Description |
|---|---|
| MossTTSDelay-8B | Recommended for production . Faster inference, stronger long-context stability, and robust voice cloning quality. Best for large-scale deployment and long-form narration. |
| MossTTSLocal-1.7B | Recommended for evaluation and research . Smaller model size with SOTA objective metrics. Great for quick experiments, ablations, and academic studies. |
Recommended decoding hyperparameters (per model)
| Model | audio_temperature | audio_top_p | audio_top_k | audio_repetition_penalty |
|---|---|---|---|---|
| MOSS-TTSDelay-8B | 1.7 | 0.8 | 25 | 1.0 |
| MOSS-TTSLocal-1.7B | 1.0 | 0.95 | 50 | 1.1 |
Note:
max_new_tokenscontrols duration. At 12.5 tokens per second, 1s ≈ 12.5 tokens .
We recommend a clean, isolated Python environment with Transformers 5.0.0 to avoid dependency conflicts.
conda create -n moss-tts python=3.12 -y
conda activate moss-tts
Install all required dependencies:
git clone https://github.com/OpenMOSS/MOSS-TTS.git
cd MOSS-TTS
pip install --extra-index-url https://download.pytorch.org/whl/cu128 -e .
For better speed and lower GPU memory usage, you can install FlashAttention 2 if your hardware supports it.
pip install --extra-index-url https://download.pytorch.org/whl/cu128 -e ".[flash-attn]"
If your machine has limited RAM and many CPU cores, you can cap build parallelism:
MAX_JOBS=4 pip install --extra-index-url https://download.pytorch.org/whl/cu128 -e ".[flash-attn]"
Notes:
pyproject.toml
, which currently pins
torch==2.9.1+cu128
and
torchaudio==2.9.1+cu128
.
torch.float16
or
torch.bfloat16
.
Tip: For evaluation and research purposes, we recommend using MOSS-TTSLocal-1.7B .
MOSS-TTS provides a convenient
generate
interface for rapid usage. The examples below cover:
import importlib.util
from pathlib import Path
import torch
import torchaudio
from transformers import AutoModel, AutoProcessor, GenerationConfig
# Disable the broken cuDNN SDPA backend
torch.backends.cuda.enable_cudnn_sdp(False)
# Keep these enabled as fallbacks
torch.backends.cuda.enable_flash_sdp(True)
torch.backends.cuda.enable_mem_efficient_sdp(True)
torch.backends.cuda.enable_math_sdp(True)

class DelayGenerationConfig(GenerationConfig):
    def __init__(self, **kwargs):
        super().__init__(**kwargs)
        self.layers = kwargs.get("layers", [{} for _ in range(32)])
        self.do_samples = kwargs.get("do_samples", None)
        self.n_vq_for_inference = 32

def initial_config(tokenizer, model_name_or_path):
    generation_config = DelayGenerationConfig.from_pretrained(model_name_or_path)
    generation_config.pad_token_id = tokenizer.pad_token_id
    generation_config.eos_token_id = 151653
    generation_config.max_new_tokens = 1000000
    generation_config.temperature = 1.0
    generation_config.top_p = 0.95
    generation_config.top_k = 100
    generation_config.repetition_penalty = 1.1
    generation_config.use_cache = True
    generation_config.do_sample = False
    return generation_config


pretrained_model_name_or_path = "OpenMOSS-Team/MOSS-TTS-Local-Transformer"
device = "cuda" if torch.cuda.is_available() else "cpu"
dtype = torch.bfloat16 if device == "cuda" else torch.float32

def resolve_attn_implementation() -> str:
    # Prefer FlashAttention 2 when package + device conditions are met.
    if (
        device == "cuda"
        and importlib.util.find_spec("flash_attn") is not None
        and dtype in {torch.float16, torch.bfloat16}
    ):
        major, _ = torch.cuda.get_device_capability()
        if major >= 8:
            return "flash_attention_2"

    # CUDA fallback: use PyTorch SDPA kernels.
    if device == "cuda":
        return "sdpa"

    # CPU fallback.
    return "eager"


attn_implementation = resolve_attn_implementation()
print(f"[INFO] Using attn_implementation={attn_implementation}")

processor = AutoProcessor.from_pretrained(
    pretrained_model_name_or_path,
    trust_remote_code=True,
)
processor.audio_tokenizer = processor.audio_tokenizer.to(device)

text_1 = """亲爱的你,
你好呀。

今天,我想用最认真、最温柔的声音,对你说一些重要的话。
这些话,像一颗小小的星星,希望能在你的心里慢慢发光。

首先,我想祝你——
每天都能平平安安、快快乐乐。

希望你早上醒来的时候,
窗外有光,屋子里很安静,
你的心是轻轻的,没有着急,也没有害怕。
"""
text_2 = """We stand on the threshold of the AI era.
Artificial intelligence is no longer just a concept in laboratories, but is entering every industry, every creative endeavor, and every decision. It has learned to see, hear, speak, and think, and is beginning to become an extension of human capabilities. AI is not about replacing humans, but about amplifying human creativity, making knowledge more equitable, more efficient, and allowing imagination to reach further. A new era, jointly shaped by humans and intelligent systems, has arrived."""
text_3 = "nin2 hao3,qing3 wen4 nin2 lai2 zi4 na3 zuo4 cheng2 shi4?"
text_4 = "nin2 hao3,qing4 wen3 nin2 lai2 zi4 na4 zuo3 cheng4 shi3?"
text_5 = "您好,请问您来自哪 zuo4 cheng2 shi4?"
text_6 = "/həloʊ, meɪ aɪ æsk wɪtʃ sɪti juː ɑːr frʌm?/"

ref_audio_1 = "https://speech-demo.oss-cn-shanghai.aliyuncs.com/moss_tts_demo/tts_readme_demo/reference_zh.wav"
ref_audio_2 = "https://speech-demo.oss-cn-shanghai.aliyuncs.com/moss_tts_demo/tts_readme_demo/reference_en.m4a"

conversations = [
    # Direct TTS (no reference)
    [
        processor.build_user_message(text=text_1)
    ],
    [
        processor.build_user_message(text=text_2)
    ],
    # Pinyin or IPA input
    [
        processor.build_user_message(text=text_3)
    ],
    [
        processor.build_user_message(text=text_4)
    ],
    [
        processor.build_user_message(text=text_5)
    ],
    [
        processor.build_user_message(text=text_6)
    ],
    # Voice cloning (with reference)
    [
        processor.build_user_message(text=text_1, reference=[ref_audio_1])
    ],
    [
        processor.build_user_message(text=text_2, reference=[ref_audio_2])
    ],
]

model = AutoModel.from_pretrained(
    pretrained_model_name_or_path,
    trust_remote_code=True,
    attn_implementation=attn_implementation,
    torch_dtype=dtype,
).to(device)
model.eval()

generation_config = initial_config(processor.tokenizer, pretrained_model_name_or_path)
generation_config.n_vq_for_inference = model.channels - 1
generation_config.do_samples = [True] * model.channels
generation_config.layers = [
    {
        "repetition_penalty": 1.0,
        "temperature": 1.5,
        "top_p": 1.0,
        "top_k": 50
    }
] + [
    {
        "repetition_penalty": 1.1,
        "temperature": 1.0,
        "top_p": 0.95,
        "top_k": 50
    }
] * (model.channels - 1)

batch_size = 1

save_dir = Path(f"inference_root_moss_tts_local_transformer_generation")
save_dir.mkdir(exist_ok=True, parents=True)
sample_idx = 0
with torch.no_grad():
    for start in range(0, len(conversations), batch_size):
        batch_conversations = conversations[start : start + batch_size]
        batch = processor(batch_conversations, mode="generation")
        input_ids = batch["input_ids"].to(device)
        attention_mask = batch["attention_mask"].to(device)

        outputs = model.generate(
            input_ids=input_ids,
            attention_mask=attention_mask,
            generation_config=generation_config
        )

        for message in processor.decode(outputs):
            audio = message.audio_codes_list[0]
            out_path = save_dir / f"sample{sample_idx}.wav"
            sample_idx += 1
            torchaudio.save(out_path, audio.unsqueeze(0), processor.model_config.sampling_rate)
MOSS-TTS supports continuation-based cloning: provide a prefix audio clip in the assistant message, and make sure the prefix transcript is included in the text. The model continues in the same speaker identity and style.
import importlib.util
from pathlib import Path
import torch
import torchaudio
from transformers import AutoModel, AutoProcessor, GenerationConfig
# Disable the broken cuDNN SDPA backend
torch.backends.cuda.enable_cudnn_sdp(False)
# Keep these enabled as fallbacks
torch.backends.cuda.enable_flash_sdp(True)
torch.backends.cuda.enable_mem_efficient_sdp(True)
torch.backends.cuda.enable_math_sdp(True)

class DelayGenerationConfig(GenerationConfig):
    def __init__(self, **kwargs):
        super().__init__(**kwargs)
        self.layers = kwargs.get("layers", [{} for _ in range(32)])
        self.do_samples = kwargs.get("do_samples", None)
        self.n_vq_for_inference = 32

def initial_config(tokenizer, model_name_or_path):
    generation_config = DelayGenerationConfig.from_pretrained(model_name_or_path)
    generation_config.pad_token_id = tokenizer.pad_token_id
    generation_config.eos_token_id = 151653
    generation_config.max_new_tokens = 1000000
    generation_config.temperature = 1.0
    generation_config.top_p = 0.95
    generation_config.top_k = 100
    generation_config.repetition_penalty = 1.1
    generation_config.use_cache = True
    generation_config.do_sample = False
    return generation_config


pretrained_model_name_or_path = "OpenMOSS-Team/MOSS-TTS-Local-Transformer"
device = "cuda" if torch.cuda.is_available() else "cpu"
dtype = torch.bfloat16 if device == "cuda" else torch.float32

def resolve_attn_implementation() -> str:
    # Prefer FlashAttention 2 when package + device conditions are met.
    if (
        device == "cuda"
        and importlib.util.find_spec("flash_attn") is not None
        and dtype in {torch.float16, torch.bfloat16}
    ):
        major, _ = torch.cuda.get_device_capability()
        if major >= 8:
            return "flash_attention_2"

    # CUDA fallback: use PyTorch SDPA kernels.
    if device == "cuda":
        return "sdpa"

    # CPU fallback.
    return "eager"


attn_implementation = resolve_attn_implementation()
print(f"[INFO] Using attn_implementation={attn_implementation}")

processor = AutoProcessor.from_pretrained(
    pretrained_model_name_or_path,
    trust_remote_code=True,
)
processor.audio_tokenizer = processor.audio_tokenizer.to(device)

text_1 = """亲爱的你,
你好呀。

今天,我想用最认真、最温柔的声音,对你说一些重要的话。
这些话,像一颗小小的星星,希望能在你的心里慢慢发光。

首先,我想祝你——
每天都能平平安安、快快乐乐。

希望你早上醒来的时候,
窗外有光,屋子里很安静,
你的心是轻轻的,没有着急,也没有害怕。
"""

ref_text_1 = "太阳系八大行星之一。"
ref_audio_1 = "https://speech-demo.oss-cn-shanghai.aliyuncs.com/moss_tts_demo/tts_readme_demo/reference_zh.wav"

conversations = [
    # Continuatoin only
    [
        processor.build_user_message(text=ref_text_1 + text_1),
        processor.build_assistant_message(audio_codes_list=[ref_audio_1])
    ],
]

model = AutoModel.from_pretrained(
    pretrained_model_name_or_path,
    trust_remote_code=True,
    attn_implementation=attn_implementation,
    torch_dtype=dtype,
).to(device)
model.eval()

generation_config = initial_config(processor.tokenizer, pretrained_model_name_or_path)
generation_config.n_vq_for_inference = model.channels - 1
generation_config.do_samples = [True] * model.channels
generation_config.layers = [
    {
        "repetition_penalty": 1.0,
        "temperature": 1.5,
        "top_p": 1.0,
        "top_k": 50
    }
] + [
    {
        "repetition_penalty": 1.1,
        "temperature": 1.0,
        "top_p": 0.95,
        "top_k": 50
    }
] * (model.channels - 1)

batch_size = 1

save_dir = Path("inference_root_moss_tts_local_transformer_continuation")
save_dir.mkdir(exist_ok=True, parents=True)
sample_idx = 0
with torch.no_grad():
    for start in range(0, len(conversations), batch_size):
        batch_conversations = conversations[start : start + batch_size]
        batch = processor(batch_conversations, mode="continuation")
        input_ids = batch["input_ids"].to(device)
        attention_mask = batch["attention_mask"].to(device)

        outputs = model.generate(
            input_ids=input_ids,
            attention_mask=attention_mask,
            generation_config=generation_config
        )

        for message in processor.decode(outputs):
            audio = message.audio_codes_list[0]
            out_path = save_dir / f"sample{sample_idx}.wav"
            sample_idx += 1
            torchaudio.save(out_path, audio.unsqueeze(0), processor.model_config.sampling_rate)
UserMessage
| Field | Type | Required | Description |
|---|---|---|---|
text
|
str
|
Yes | Text to synthesize. Supports Chinese, English, German, French, Spanish, Japanese, Korean, etc. Can mix raw text with Pinyin or IPA for pronunciation control. |
reference
|
List[str]
|
No | Reference audio for voice cloning. For current MOSS-TTS, one audio is expected in the list. |
tokens
|
int
|
No | Expected number of audio tokens. 1s ≈ 12.5 tokens . |
AssistantMessage
| Field | Type | Required | Description |
|---|---|---|---|
audio_codes_list
|
List[str]
|
Only for continuation | Prefix audio for continuation-based cloning. Use audio file paths or URLs. |
MOSS-TTSLocal utilizes
DelayGenerationConfig
to manage hierarchical sampling. Due to the
Progressive Sequence Dropout
training mechanism, the model supports variable bitrate inference by adjusting the RVQ depth.
| Parameter | Type | Recommended (Audio Layers) | Description |
|---|---|---|---|
max_new_tokens
|
int
|
— | Controls total generated audio tokens. 1s ≈ 12.5 tokens . |
n_vq_for_inference
|
int
|
32 | RVQ Inference Depth : Controls the number of codebook layers generated. Higher values (max 32) improve audio fidelity but slow down inference; lower values speed up inference but reduce audio quality. |
audio_temperature
|
float
|
1.0 | Temperature for audio token layers (Layer 1+). Lower values ensure more stable and consistent acoustic reconstruction. |
audio_top_p
|
float
|
0.95 | Nucleus sampling cutoff for audio layers. |
audio_top_k
|
int
|
50 | Top-K sampling filter for audio layers. |
audio_repetition_penalty
|
float
|
1.1 | Discourages repeating acoustic patterns. Values > 1.0 help prevent artifacts in long-form synthesis. |
Use tone-numbered Pinyin such as
ni3 hao3 wo3 men1
. You can convert Chinese text with
pypinyin
, then adjust tones for pronunciation control.
import re
from pypinyin import pinyin, Style

CN_PUNCT = r",。!?;:、()“”‘’"


def fix_punctuation_spacing(s: str) -> str:
    s = re.sub(rf"\s+([{CN_PUNCT}])", r"\1", s)
    s = re.sub(rf"([{CN_PUNCT}])\s+", r"\1", s)
    return s


def zh_to_pinyin_tone3(text: str, strict: bool = True) -> str:
    result = pinyin(
        text,
        style=Style.TONE3,
        heteronym=False,
        strict=strict,
        errors="default",
    )

    s = " ".join(item[0] for item in result)
    return fix_punctuation_spacing(s)

text = zh_to_pinyin_tone3("您好,请问您来自哪座城市?")
print(text)

# Expected: nin2 hao3,qing3 wen4 nin2 lai2 zi4 na3 zuo4 cheng2 shi4?
# Try: nin2 hao3,qing4 wen3 nin2 lai2 zi4 na4 zuo3 cheng4 shi3?
Use
/.../
to wrap IPA sequences so they are distinct from normal text. You can use
DeepPhonemizer
to convert English paragraphs or words into IPA sequences.
from dp.phonemizer import Phonemizer

# Download a phonemizer checkpoint from https://public-asai-dl-models.s3.eu-central-1.amazonaws.com/DeepPhonemizer/en_us_cmudict_ipa_forward.pt
model_path = "<path-to-phonemizer-checkpoint>"
phonemizer = Phonemizer.from_checkpoint(model_path)

english_texts = "Hello, may I ask which city you are from?"
phoneme_outputs = phonemizer(
    english_texts,
    lang="en_us",
    batch_size=8
)
model_input_text = f"/{phoneme_outputs}/"
print(model_input_text)

# Expected: /həloʊ, meɪ aɪ æsk wɪtʃ sɪti juː ɑːr frʌm?/
MOSS-TTS achieved state-of-the-art results on the open-source zero-shot TTS benchmark Seed-TTS-eval, not only surpassing all open-source models but also rivaling the most powerful closed-source models.
| Model | Params | Open-source | EN WER (%) ↓ | EN SIM (%) ↑ | ZH CER (%) ↓ | ZH SIM (%) ↑ |
|---|---|---|---|---|---|---|
| DiTAR | 0.6B | ❌ | 1.69 | 73.5 | 1.02 | 75.3 |
| FishAudio-S1 | 4B | ❌ | 1.72 | 62.57 | 1.22 | 72.1 |
| Seed-TTS | ❌ | 2.25 | 76.2 | 1.12 | 79.6 | |
| MiniMax-Speech | ❌ | 1.65 | 69.2 | 0.83 | 78.3 | |
| CosyVoice | 0.3B | ✅ | 4.29 | 60.9 | 3.63 | 72.3 |
| CosyVoice2 | 0.5B | ✅ | 3.09 | 65.9 | 1.38 | 75.7 |
| CosyVoice3 | 0.5B | ✅ | 2.02 | 71.8 | 1.16 | 78 |
| CosyVoice3 | 1.5B | ✅ | 2.22 | 72 | 1.12 | 78.1 |
| F5-TTS | 0.3B | ✅ | 2 | 67 | 1.53 | 76 |
| SparkTTS | 0.5B | ✅ | 3.14 | 57.3 | 1.54 | 66 |
| FireRedTTS | 0.5B | ✅ | 3.82 | 46 | 1.51 | 63.5 |
| FireRedTTS-2 | 1.5B | ✅ | 1.95 | 66.5 | 1.14 | 73.6 |
| Qwen2.5-Omni | 7B | ✅ | 2.72 | 63.2 | 1.7 | 75.2 |
| FishAudio-S1-mini | 0.5B | ✅ | 1.94 | 55 | 1.18 | 68.5 |
| IndexTTS2 | 1.5B | ✅ | 2.23 | 70.6 | 1.03 | 76.5 |
| VibeVoice | 1.5B | ✅ | 3.04 | 68.9 | 1.16 | 74.4 |
| HiggsAudio-v2 | 3B | ✅ | 2.44 | 67.7 | 1.5 | 74 |
| VoxCPM | 0.5B | ✅ | 1.85 | 72.9 | 0.93 | 77.2 |
| Qwen3-TTS | 0.6B | ✅ | 1.68 | 70.39 | 1.23 | 76.4 |
| Qwen3-TTS | 1.7B | ✅ | 1.5 | 71.45 | 1.33 | 76.72 |
| MossTTSDelay | 8B | ✅ | 1.79 | 71.46 | 1.32 | 77.05 |
| MossTTSLocal | 1.7B | ✅ | 1.85 | 73.42 | 1.2 | 78.82 |