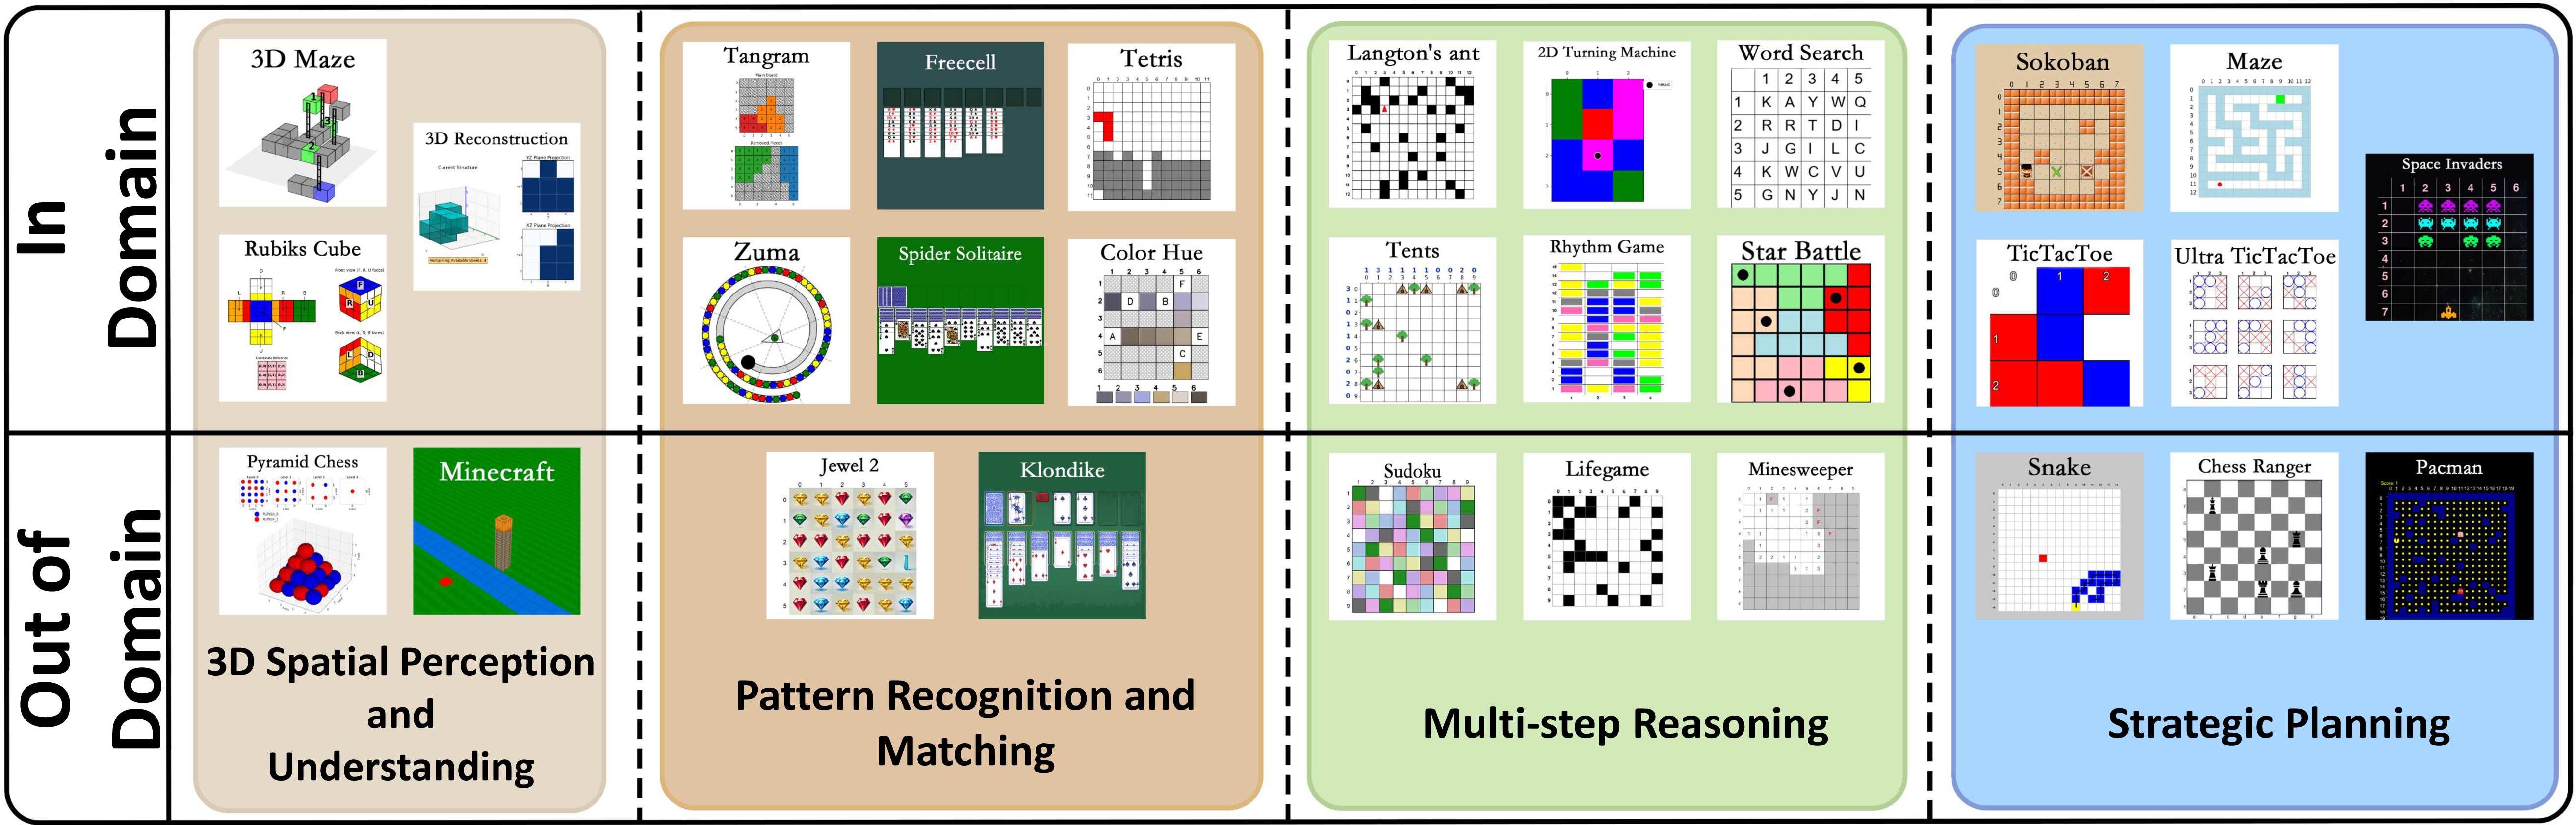
This model (GameQA-InternVL3-8B) results from training InternVL3-8B with GRPO solely on our
GameQA-5K
(sampled from the full
GameQA-140K
dataset).
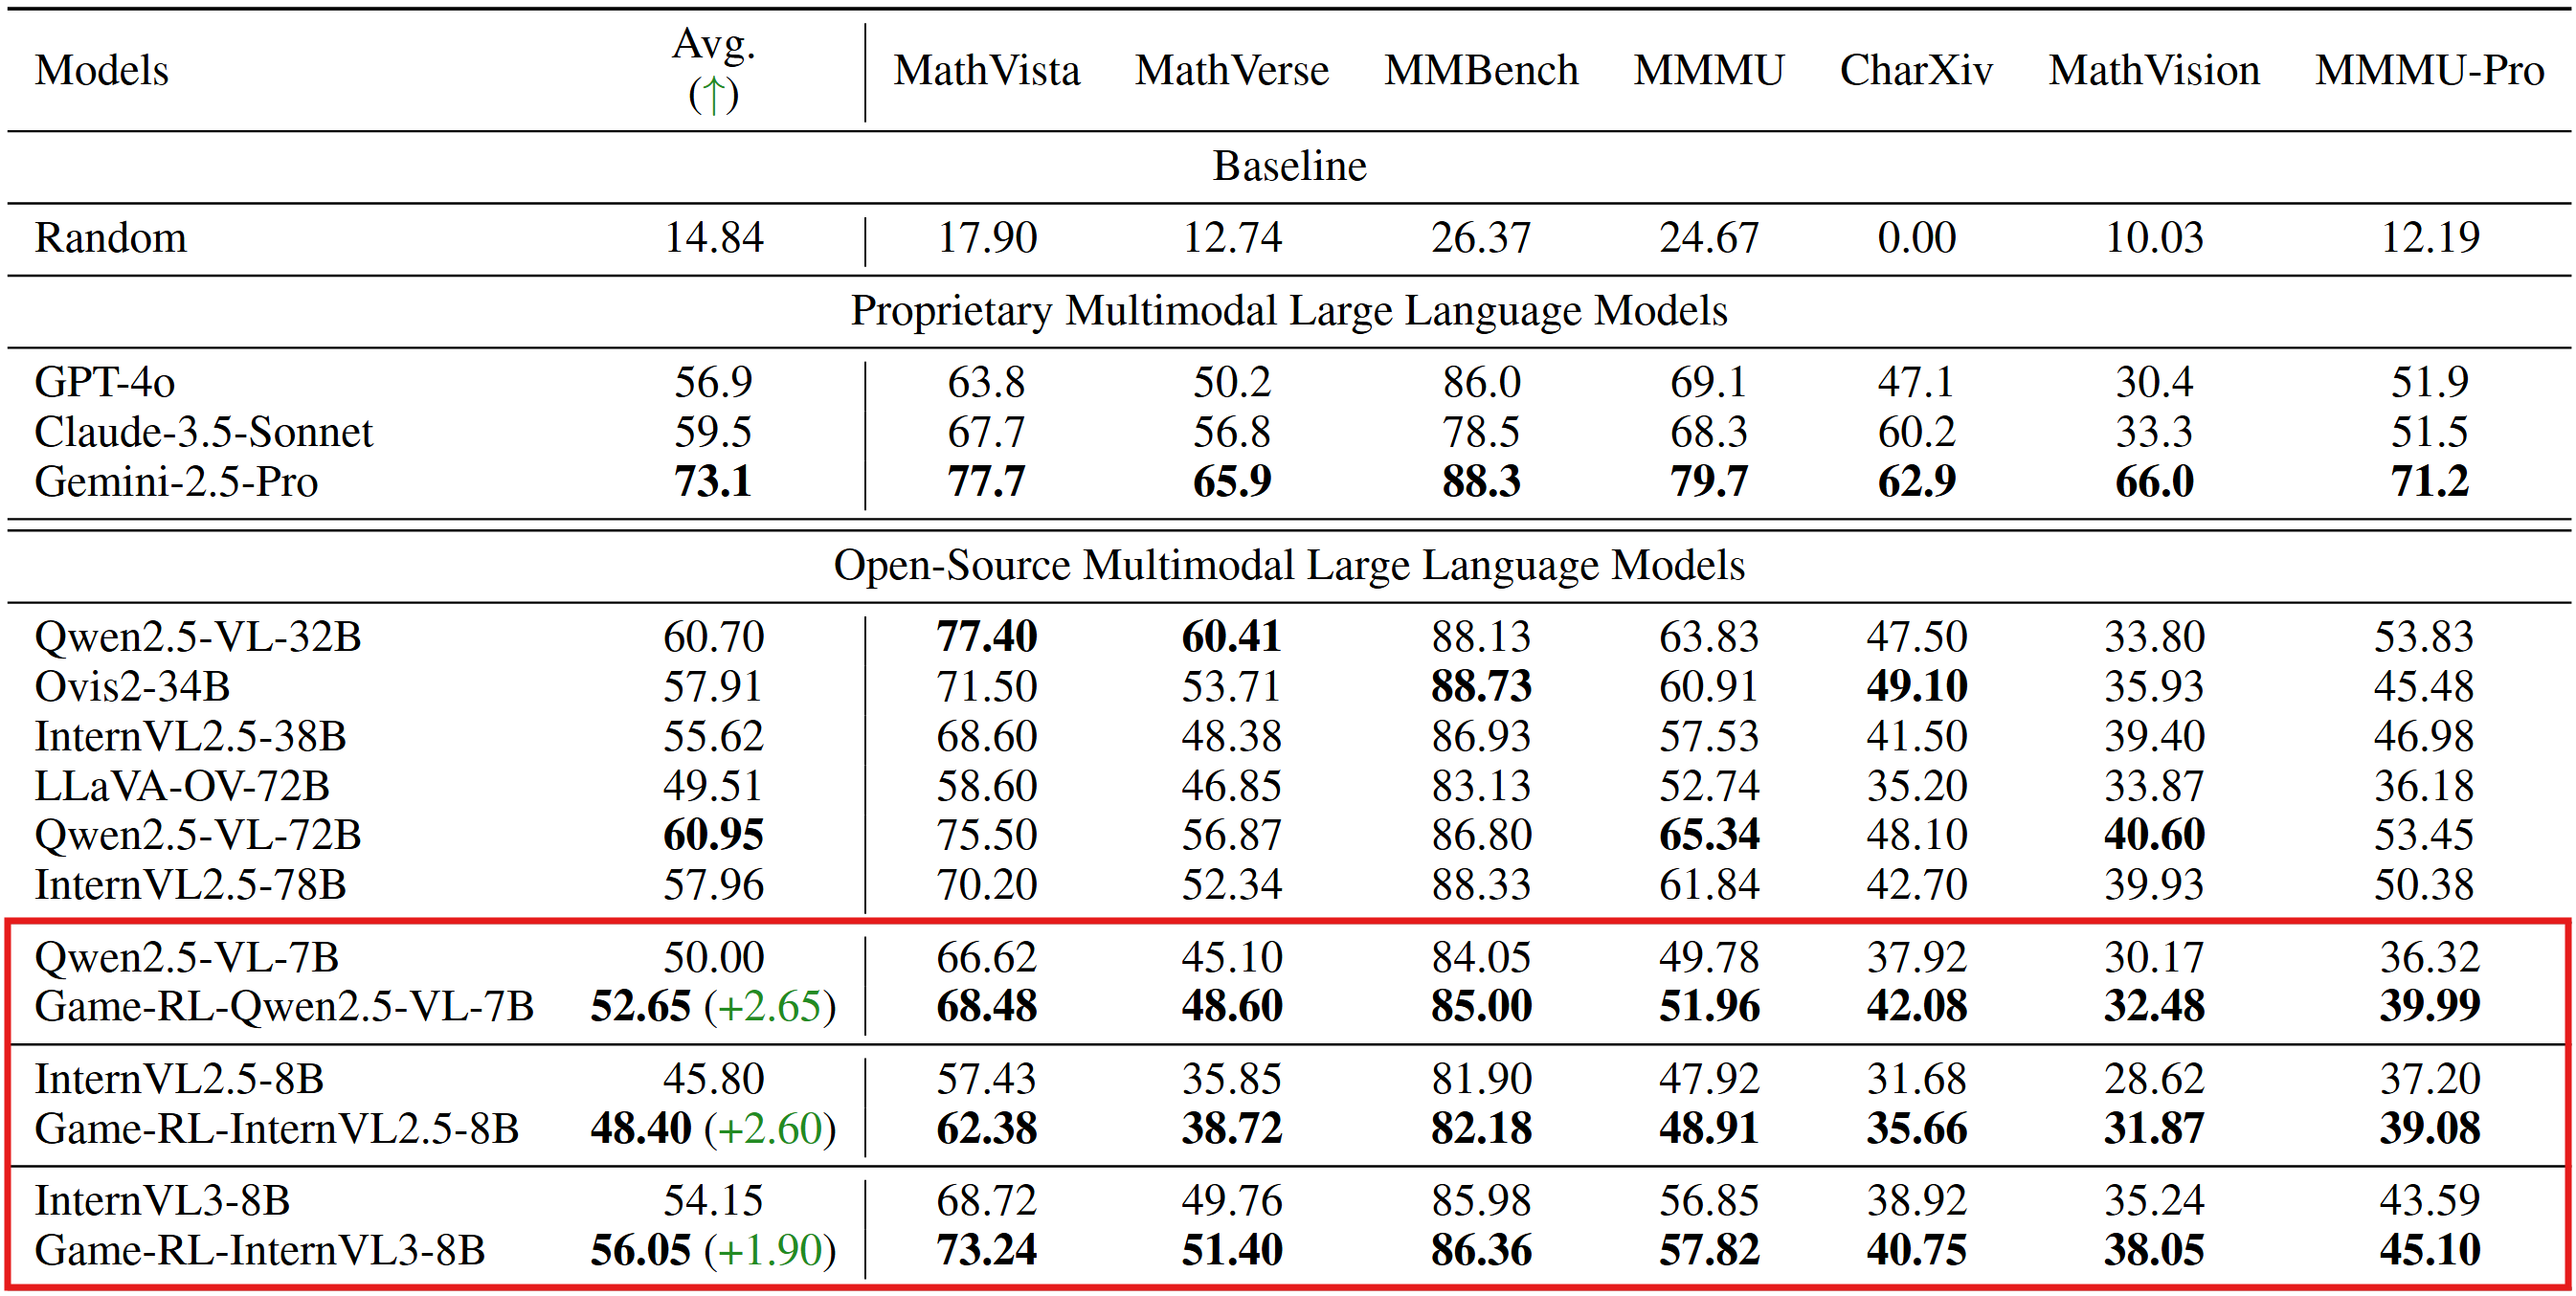
Evaluation Results on General Vision BenchMarks
(The inference and evaluation configurations were unified across both the original open-source models and our trained models.)
Code2Logic: Game-Code-Driven Data Synthesis for Enhancing VLMs General Reasoning
This is the first work, to the best of our knowledge, that leverages
game code
to synthesize multimodal reasoning data for
training
VLMs. Furthermore, when trained with a GRPO strategy solely on
GameQA
(synthesized via our proposed
Code2Logic
approach), multiple cutting-edge open-source models exhibit significantly enhanced out-of-domain generalization.
Game-RL-InternVL3-8B huggingface.co is an AI model on huggingface.co that provides Game-RL-InternVL3-8B's model effect (), which can be used instantly with this OpenMOSS-Team Game-RL-InternVL3-8B model. huggingface.co supports a free trial of the Game-RL-InternVL3-8B model, and also provides paid use of the Game-RL-InternVL3-8B. Support call Game-RL-InternVL3-8B model through api, including Node.js, Python, http.
Game-RL-InternVL3-8B huggingface.co is an online trial and call api platform, which integrates Game-RL-InternVL3-8B's modeling effects, including api services, and provides a free online trial of Game-RL-InternVL3-8B, you can try Game-RL-InternVL3-8B online for free by clicking the link below.
OpenMOSS-Team Game-RL-InternVL3-8B online free url in huggingface.co:
Game-RL-InternVL3-8B is an open source model from GitHub that offers a free installation service, and any user can find Game-RL-InternVL3-8B on GitHub to install. At the same time, huggingface.co provides the effect of Game-RL-InternVL3-8B install, users can directly use Game-RL-InternVL3-8B installed effect in huggingface.co for debugging and trial. It also supports api for free installation.
Game-RL-InternVL3-8B install url in huggingface.co: