



Total runs:
213.5K
Run Growth:
125.2K
Growth Rate:
58.61%




MOSS‑TTS Family is an open‑source speech and sound generation model family from MOSI.AI and the OpenMOSS team . It is designed for high‑fidelity , high‑expressiveness , and complex real‑world scenarios , covering stable long‑form speech, multi‑speaker dialogue, voice/character design, environmental sound effects, and real‑time streaming TTS.
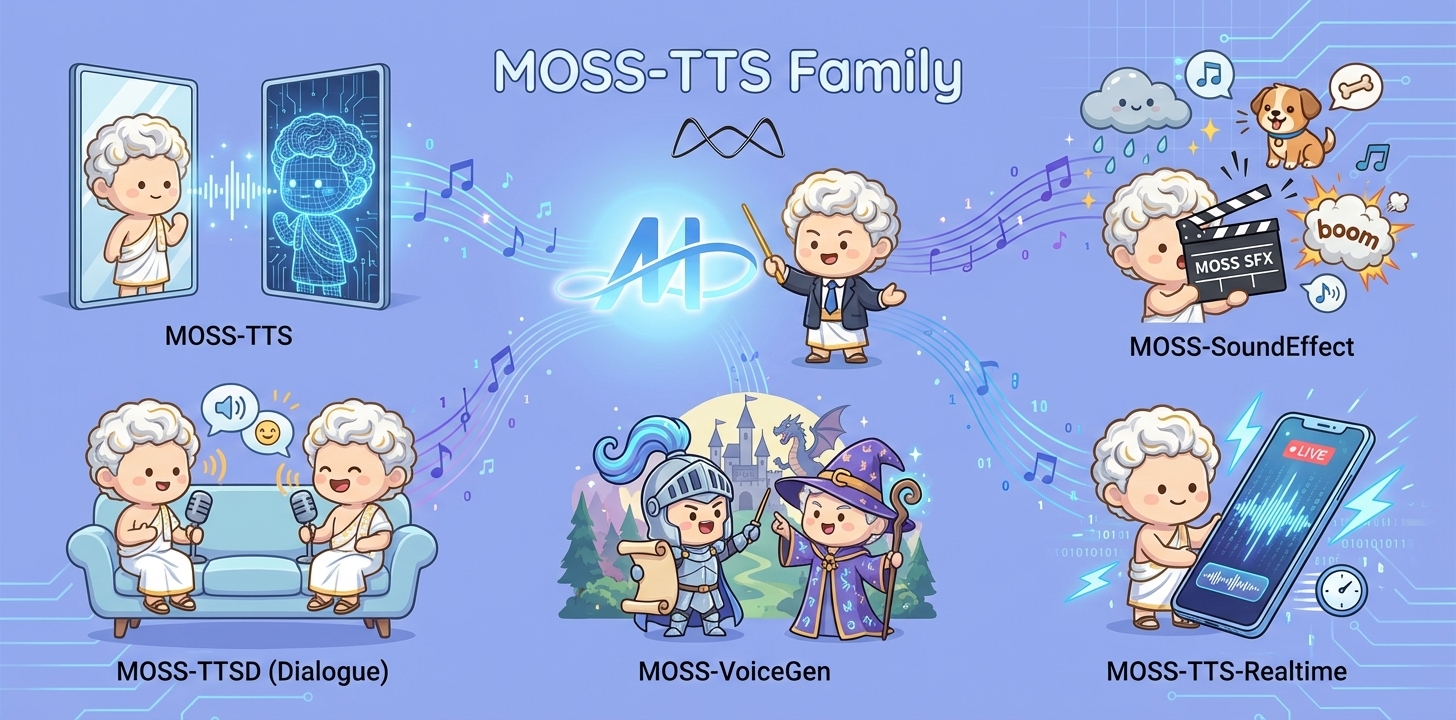
When a single piece of audio needs to sound like a real person , pronounce every word accurately , switch speaking styles across content , remain stable over tens of minutes , and support dialogue, role‑play, and real‑time interaction , a single TTS model is often not enough. The MOSS‑TTS Family breaks the workflow into five production‑ready models that can be used independently or composed into a complete pipeline.
| Model | Architecture | Size | Model Card | Hugging Face |
|---|---|---|---|---|
| MOSS-TTS | MossTTSDelay | 8B | moss_tts_model_card.md | 🤗 Huggingface |
| MossTTSLocal | 1.7B | moss_tts_model_card.md | 🤗 Huggingface | |
| MOSS‑TTSD‑V1.0 | MossTTSDelay | 8B | moss_ttsd_model_card.md | 🤗 Huggingface |
| MOSS‑VoiceGenerator | MossTTSDelay | 1.7B | moss_voice_generator_model_card.md | 🤗 Huggingface |
| MOSS‑SoundEffect | MossTTSDelay | 8B | moss_sound_effect_model_card.md | 🤗 Huggingface |
| MOSS‑TTS‑Realtime | MossTTSRealtime | 1.7B | moss_tts_realtime_model_card.md | 🤗 Huggingface |
MOSS-TTS-Realtime is a high-performance, real-time speech synthesis model within the broader MOSS TTS Family. It is designed for interactive voice agents that require low-latency, continuous speech generation across multi-turn conversations. Unlike conventional streaming TTS systems that synthesize each response in isolation, MOSS-TTS-Realtime natively models dialogue context by conditioning speech generation on both textual and acoustic information from previous turns. By tightly integrating multi-turn context awareness with incremental streaming synthesis, it produces natural, coherent, and voice-consistent audio responses, enabling fluid and human-like spoken interactions for real-time applications.
Key Capabilities
Context-Aware & Expressive Speech Generation : Generates expressive and coherent speech by modeling both textual and acoustic context across multiple dialogue turns.
High-Fidelity Voice Cloning with Multi-Turn Consistency : Achieves exceptionally high voice similarity while maintaining strong speaker identity consistency across multiple dialogue turns.
Long-Context : Supports long-range context with a maximum context length of 32K (about 40 minutes), enabling stable and consistent speech generation in extended conversations.
Highly Human-Like Speech with Natural Prosody : Trained on over 2.5 million hours of single-speaker speech and more than 1 million hours of two-speaker and multi-speaker conversational data, resulting in highly natural prosody and strong human-like expressiveness.
Multilingual Speech Support : Supports over 10 languages beyond Chinese and English, including Korean, Japanese, German, and French, enabling consistent and expressive speech across languages.
We recommend a clean, isolated Python environment with Transformers 5.0.0 to avoid dependency conflicts.
conda create -n moss-tts python=3.12 -y
conda activate moss-tts
Install all required dependencies:
git clone https://github.com/OpenMOSS/MOSS-TTS.git
cd MOSS-TTS
pip install --extra-index-url https://download.pytorch.org/whl/cu128 -e .
Please refer to the following GitHub repository for detailed usage instructions and examples:
👉
Usage Guide
:
https://github.com/OpenMOSS/MOSS-TTS/blob/main/docs/moss_tts_realtime_model_card.md